HanLP 2.1: A Production-Oriented Multilingual NLP Toolkit with a Dual-Engine Architecture
Natural language processing toolkit: Chinese word segmentation, part-of-speech tagging, named entity recognition, dependency parsing, constituency parsing, semantic dependency parsing, semantic role labeling, coreference resolution, style transfer, semantic similarity, new-word discovery, keyword/phrase extraction, automatic summarization, text classification/clustering, and pinyin/simplified-traditional conversion.
At a glance
- What is it?
- HanLP is a Python NLP toolkit covering tokenization, POS tagging, NER, parsing, and more across 130 languages. Its dual PyTorch and TensorFlow 2.x engines and RESTful API make it a strong candidate for production pipelines, but the breadth comes with complexity.
- Who is it for?
- Adopt HanLP if you need a single Python library for multiple Chinese and multilingual NLP tasks, especially if you value a RESTful API and a dual-engine design that lets you choose PyTorch or TensorFlow 2.x. Do not use it if you require a lightweight, single-task tool with minimal dependencies, or if you cannot afford the memory and disk footprint of loading large pretrained models.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 8 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
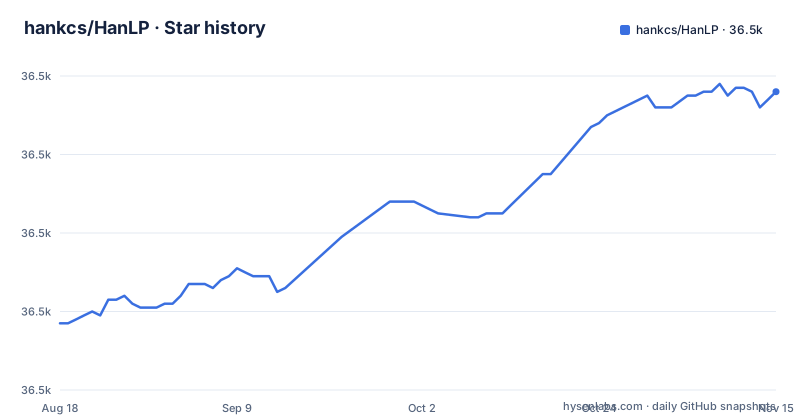
Star history
- hankcs/HanLP36,536 ★ · +59
| Repository | 2026-08-18 | 2026-11-15 |
|---|---|---|
| hankcs/HanLP | 36.5k | 36.5k |
59 Stars in the last 89 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What HanLP Solves and Who It Targets
HanLP is a multilingual natural language processing toolkit aimed at production environments. The README describes it as covering 130 languages, including simplified and traditional Chinese, English, Japanese, Russian, French, and German. It offers ten joint tasks and several single tasks, ranging from tokenization and part-of-speech tagging to named entity recognition, dependency parsing, constituency parsing, semantic dependency parsing, semantic role labeling, coreference resolution, and abstract meaning representation. The target user is an engineer or data scientist who needs a broad NLP pipeline in one package, rather than stitching together separate libraries for each task. The emphasis on production is explicit in the description, which mentions features like completeness, accuracy, performance, and customizability. This is not a research-only toolkit; it is designed to be dropped into real applications.
Dual Engine Architecture: PyTorch and TensorFlow 2.x
HanLP is built on two deep learning frameworks: PyTorch and TensorFlow 2.x. This dual-engine design is unusual. Most NLP libraries commit to one framework. The benefit is flexibility: you can choose the engine that fits your existing stack or your team's expertise. The cost is complexity. You must understand which models are implemented in which engine, and the installation and deployment requirements differ. Check the model documentation on the official site to see which tasks use which engine. This is a trade-off. If you are already standardized on one framework, the other engine becomes dead weight. But if you are migrating between frameworks or serving multiple teams, the choice is useful. The dual-engine approach also suggests that the codebase is more complex to maintain, which could affect upgrade cycles.
Setup and Basic Usage: From pip to RESTful API
Getting HanLP running starts with installing the Python package from PyPI. The README links to the PyPI page, so the standard command is pip install hanlp. After installation, you load a pretrained model by name. For example, the documentation shows models for tokenization, POS, NER, and parsing, each with a specific identifier. The README provides tutorial notebooks for each task, both for local use and for the RESTful API. The RESTful approach is a significant feature: it lets you call HanLP over HTTP instead of loading models in your own process. The tutorials are organized by task and by mode (RESTful, multi-task, single-task), so you can follow the exact steps.
The Multi-Task and Single-Task Model Landscape
HanLP distinguishes between multi-task and single-task models. Multi-task models handle several tasks jointly, which can be more efficient because they share representations. Single-task models are specialized for one task, often with higher accuracy for that task. The README lists a table with columns for each task, showing RESTful, multi-task, and single-task tutorials, plus links to model pages. For example, tokenization has separate tutorials for RESTful, multi-task, and single-task, and the annotation standards include coarse-grained and fine-grained segmentation. This separation is important because it affects performance and ease of use. A multi-task model might be easier to deploy for a pipeline, but a single-task model might be better if you only need one function. The annotation standards also vary: POS uses CTB, PKU, or 863; NER uses PKU, MSRA, or OntoNotes. You must pick the standard that matches your data or your downstream needs. This is a decision point that is often overlooked.
Language Coverage and the 130-Language Claim
The README claims support for 130 languages, which is a broad claim. It says HanLP uses the world's largest multilingual corpus. The supported languages include simplified and traditional Chinese, English, Japanese, Russian, French, and German. This is a crucial limitation to verify before adoption. If your application needs, say, dependency parsing for Swahili, you cannot assume it exists just because the language count is high. The documentation links to a pretrained model page that lists the exact models, so you can check.
RESTful API and Production Deployment
The RESTful API is a standout feature for production use. Instead of loading models in your application process, you can send HTTP requests to HanLP through its RESTful interface. The README provides tutorial notebooks for each task in RESTful mode. You can use HanLP from any language that can make HTTP calls, at the cost of network latency and dependence on the service being available. The RESTful tutorials are the place to look for endpoint and authentication specifics.
Maintenance, Licensing, and the Recent Release Trajectory
HanLP is licensed under Apache-2.0, which is permissive for commercial use. The repository is not archived, and the last push was on 2026-10-25. The recent releases show a pattern: v2.1.1 added Ancient Chinese support, v2.1.0 added English support, and v1.8.6 was a regular maintenance release. This indicates active development, with major features being added in point releases. The dual-engine architecture and the large model zoo mean that upgrades can be disruptive. When a new version changes a model format or a dependency, your existing pipeline might break. You should pin the version in your requirements and test before upgrading. Check the release notes before upgrading. The Apache-2.0 license gives you freedom to modify and redistribute, but you must retain the license notice. This is a low-risk license for most companies.
Limitations and When HanLP Is the Wrong Tool
HanLP's biggest limitation is its size and complexity. Its pretrained model collection is large, with dozens of models across more than ten tasks. For a simple tokenization task, a lighter library like jieba would be faster and simpler. HanLP is also not ideal for edge devices or real-time applications with strict latency budgets, because the models are deep learning based. Another limitation is the annotation standards. If your data uses a different standard than the ones HanLP supports, you might need to convert or retrain models. The README lists standards like CTB, PKU, and OntoNotes, but not all standards are covered. For example, if you need a specific NER tagset, you may have to adapt. Finally, verify that the task you need is available in the mode you want, since the README's task table shows no multi-task option for AMR and coreference resolution.
Alternative: Comparing with spaCy and Stanza
A real alternative to HanLP is spaCy, which is a production-oriented NLP library with a unified pipeline for tokenization, POS, NER, and dependency parsing. spaCy's approach is different: it uses a single, efficient engine (now with a transformer-based option) and focuses on a smaller set of languages, with strong support for English and several others. spaCy models are smaller and faster to load, making it easier to deploy in microservices. Another alternative is Stanza, which is built on PyTorch and offers a similar range of tasks, but with a stronger focus on research and a simpler API. Stanza also supports multiple languages, but its model zoo is smaller than HanLP's. The key difference is that HanLP emphasizes a dual-engine design and a RESTful service, while spaCy and Stanza are more traditional libraries. If you need a lightweight, single-framework solution, spaCy or Stanza might be a better fit. But if you need the breadth of tasks and languages that HanLP claims, it is a stronger candidate.
Editorial conclusion
Adopt HanLP if you need a single Python library for multiple Chinese and multilingual NLP tasks, especially if you value a RESTful API and a dual-engine design that lets you choose PyTorch or TensorFlow 2.x. Do not use it if you require a lightweight, single-task tool with minimal dependencies, or if you cannot afford the memory and disk footprint of loading large pretrained models. Before committing, verify that the specific task models you need (e.g., SRL or AMR) are available for your target language and that the annotation standards match your downstream requirements, since the documentation lists separate standards per task.
Frequently asked questions
What is NLP used for in HanLP?
HanLP's own task list runs from word segmentation, part-of-speech tagging and named entity recognition through dependency and constituency parsing, semantic role labeling and coreference resolution. It also covers style transfer, semantic similarity, new word discovery, keyword and phrase extraction, summarization, text classification and clustering, and simplified to traditional Chinese conversion.
What are the four types of NLP in HanLP?
The README for HanLP 2.1 states support for 130 languages including simplified and traditional Chinese, English, Japanese, Russian, French and German, across ten joint tasks plus a range of single tasks.
What are the 5 stages of NLP in HanLP?
HanLP organizes its capabilities as joint multitask models and single-task models, each reachable through a RESTful tutorial, a multitask tutorial or a single-task tutorial, with a pretrained model page and an annotation standard named for every task.
What is multilingual NLP and how does HanLP do it?
HanLP 2.1 covers 130 languages on a multilingual corpus and offers multitask models that handle ten joint tasks at once, alongside dedicated single-task models. Each task links to its own pretrained model page, and the default branch of the repository is doc-zh, where the zh tutorial notebooks live.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/hankcs-hanlp)Star history chart for your README
[](https://hysenlabs.com/projects/hankcs-hanlp)Was this useful?