speech-to-speech: A Modular Voice Agent Pipeline That Speaks OpenAI Realtime
GitHub describes it as Build local voice agents with open-source models. The repository metadata lists Python as its primary language. The metadata lists the Apache-2.0 license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- Hugging Face's speech-to-speech builds local voice agents from a VAD-STT-LLM-TTS cascade and exposes them through the OpenAI Realtime event set. The modular design is its strength, but the dependency matrix and CUDA versioning are where you will spend your time.
- Who is it for?
- Adopt speech-to-speech if you want a local or hybrid voice agent that speaks the OpenAI Realtime protocol and you are comfortable swapping components via CLI flags. Skip it if you need a single-command production deployment with no dependency tuning, because on Linux systems other than CUDA 12.8 and Ubuntu 24.04 the Qwen3-TTS backend needs a matching wheel.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
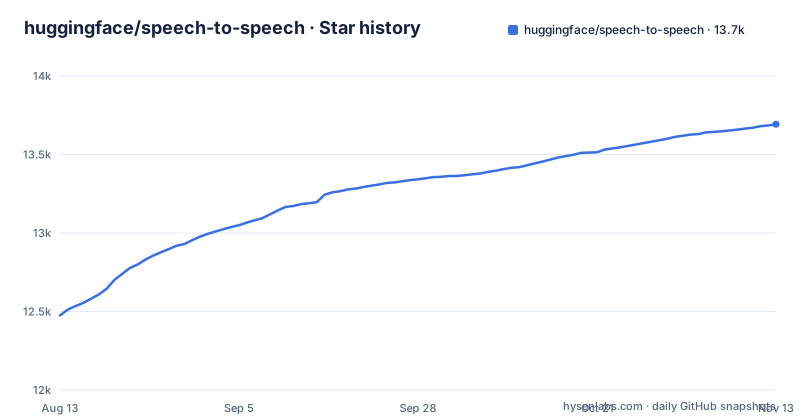
- huggingface/speech-to-speech13,693 ★ · +1,218
| Repository | 2026-08-13 | 2026-11-13 |
|---|---|---|
| huggingface/speech-to-speech | 12.5k | 13.7k |
1,218 Stars in the last 92 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A Voice Agent Pipeline That Speaks the OpenAI Realtime Protocol
The project solves a specific integration problem: building a voice agent that can drop into existing OpenAI Realtime clients without rewriting them. It exposes a server at ws://localhost:8765/v1/realtime that implements the core OpenAI Realtime GA event set over WebSocket and WebRTC. That means clients written against OpenAI's Realtime API, including the official OpenAI Agents SDK, can connect to a local stack where every stage is an open-source model. The intended user is an engineer who wants a voice agent on their own hardware or with a hybrid setup, using a hosted LLM but local speech recognition and synthesis. The README states the pipeline runs in production as the conversation backend for thousands of Reachy Mini robots, which gives some confidence in its real-world use, though you should verify that claim against the Reachy Mini blog post if it matters to you.
Four Threads, Four Queues, One Swappable Cascade
The architecture is a cascade of four components, each running in its own thread and connected by queues. VAD uses Silero VAD to detect speech boundaries and manage turn-taking. STT transcribes the user's turn, with optional live partial transcripts. The LLM generates the response, streaming text and tool calls. TTS synthesizes audio and streams it back. Every stage has multiple interchangeable backends, selected via CLI flags. The design is deliberately simple: queues between threads mean you can replace any stage without touching the others. The README emphasizes that the code is designed for easy modification, with a focus on models available through Transformers and the Hugging Face Hub. This is not a monolithic black box; it is a skeleton you are meant to reconfigure.
Getting It Running: Commands and Configuration Keys
The quickstart is short: pip install speech-to-speech, then speech-to-speech local, with no API key; the default pipeline is Silero VAD, Parakeet TDT, Qwen3.5-4B and Qwen3-TTS, all on your machine. To run only the server, use speech-to-speech serve. You can talk to it from a second terminal with speech-to-speech talk --url ws://127.0.0.1:8765/v1/realtime. The local command runs the server and a microphone client in one process. To keep the LLM local, the README shows serving Gemma 4 with llama.cpp using llama-server -hf ggml-org/gemma-4-E4B-it-GGUF -np 2 -c 65536 -fa on --swa-full, then pointing the backend at it with --model_name, --responses_api_base_url, and --responses_api_api_key. The API key flag is set to an empty string for local servers, which is a small detail that will trip you up if you leave the default key in place.
The CUDA and glibc Trap in Qwen3-TTS
The default TTS backend on Linux is Qwen3-TTS through the GGML implementation, and its PyPI wheel targets CUDA 12.8 and manylinux_2_39, which means Ubuntu 24.04 or newer. If your CUDA runtime or glibc is older, the README directs you to install a matching wheel from the Hugging Face wheelhouse before installing speech-to-speech. That is an extra step. The README lists specific wheel versions for CUDA 13.x, CUDA 12.4, and a CPU-only fallback. You must know your exact CUDA version before you start. This is not a plug-and-play experience on Linux; it is a dependency puzzle that you solve once and then forget, but the first hour is fiddly.
Platform Markers and the DeepFilterNet Conflict
macOS and non-macOS dependencies are resolved automatically via platform markers in pyproject.toml, so Apple Silicon users get mlx-audio for TTS and different STT backends. The optional extras cover a wide range: kokoro, pocket, chattts, omnivoice, faster-whisper, whisper-mlx, paraformer, and mlx-lm. But there is a documented conflict: DeepFilterNet, used for optional audio enhancement in VAD, requires numpy<2, while Pocket TTS requires numpy>=2. The README tells you to install DeepFilterNet manually only in environments where you are not using Pocket TTS. That is a brittle coexistence. If you want both audio enhancement and Pocket TTS, you are out of luck without custom dependency management. This is a concrete limitation you should weigh before committing.
Backend Choices and the Archive Trap
The component table lists VAD as built-in, STT with Parakeet TDT as default and Whisper, Faster Whisper, Lightning Whisper MLX, MLX Audio Whisper, and Paraformer as options. TTS has Qwen3-TTS, Kokoro, ChatTTS, OmniVoice, and Pocket TTS. The README notes that deprecated implementations, including MeloTTS, live in archive/ and are no longer wired into the CLI. That is a useful signal for maintainers: if you see an old blog post recommending MeloTTS, it will not work through the current CLI. The archive directory is a graveyard, not a supported path. For new projects, stick to the components listed in the table and the extras.
Alternatives: What You Are Trading Away
The obvious alternative is the official OpenAI Realtime API itself, which gives you a managed pipeline with no local models and no dependency management. You trade away privacy, latency control, and the ability to run fully offline. Another alternative is a DIY pipeline using something like faster-whisper plus a local LLM server plus a TTS engine like Kokoro, glued together with your own WebSocket code. That gives you full control but requires you to implement the Realtime event protocol yourself, which is exactly the work speech-to-speech saves you. The difference in approach is that speech-to-speech gives you a tested event surface and a working client, while a DIY stack leaves protocol compatibility to you. If you need the OpenAI Realtime wire protocol, this project is the shortcut; if you just need any voice agent, a custom glue might be simpler.
Maintenance and Upgrade Cost
The project is actively maintained, with releases v0.2.12, v1.0.0 and v1.1.0 published between August and October 2026. That cadence suggests ongoing work, but it also means you should expect frequent updates and potential breaking changes in CLI flags or backend defaults. The license is Apache-2.0, which permits commercial use, modification, and redistribution without copyleft obligations, though you should read the license text for exact terms. The upgrade cost is moderate: because components are swappable, you can pin versions of the core package and the qwentts-cpp-python wheel separately. The main risk is that a new release changes the default model or the event set, which could break your client. Verify the changelog before upgrading, and test the OpenAI Agents SDK against the new version.
Editorial conclusion
Adopt speech-to-speech if you want a local or hybrid voice agent that speaks the OpenAI Realtime protocol and you are comfortable swapping components via CLI flags. Skip it if you need a single-command production deployment with no dependency tuning, because on Linux systems other than CUDA 12.8 and Ubuntu 24.04 the Qwen3-TTS backend needs a matching wheel. Before adopting, verify your exact CUDA runtime and glibc version against the qwentts-cpp-python wheelhouse, and test the OpenAI Agents SDK against the implemented event set on your chosen transport, since the README only confirms that SDK over the stock WebSocket and WebRTC paths.
Frequently asked questions
What is speech to speech?
In this project it is a four-stage pipeline, VAD then STT then LLM then TTS, exposed through the core OpenAI Realtime GA event set over WebSocket and WebRTC. Parakeet TDT for recognition and Qwen3-TTS for output are the defaults, and every stage is swappable.
How do you build a speech to speech pipeline with this project?
Install the package and run one command: `speech-to-speech local` picks local models for your platform, Qwen3.5-4B 4-bit via MLX LM on Apple Silicon, and the first run downloads the models.
Which STT model does speech-to-speech use?
Parakeet TDT is the default speech recognition model and runs locally; like every stage, STT has interchangeable backends selected via CLI flags.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/huggingface-speech-to-speech)Star history chart for your README
[](https://hysenlabs.com/projects/huggingface-speech-to-speech)Was this useful?