Scira's 17 search modes, 28 tools, and the pnpm against bun build gap
Scira (Formerly MiniPerplx) is a minimalistic AI-powered search engine that helps you find information on the internet and cites it too. Powered by Vercel AI SDK!
At a glance
- What is it?
- Scira, formerly MiniPerplx, is a minimalistic AI search engine in TypeScript that plans, retrieves, and cites, released under AGPL-3.0. Its self-hosting story is where the real detail sits: a Dockerfile that installs with pnpm against a repository shipping a bun.lock, a build stage that copies .env, and 28 tools, most of which wrap third-party services.
- Who is it for?
- Scira is worth reading if you want a citation-first search agent whose retrieval layer you can swap per query, since web search fans out across four providers and self-hosting is explicitly supported under AGPL-3.0. It is a poor fit if you need a turnkey container today: the build assumes a pnpm lockfile the repository does not ship, it requires a .env file inside the build context, and every mode depends on a vendor key you must supply yourself.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 94 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
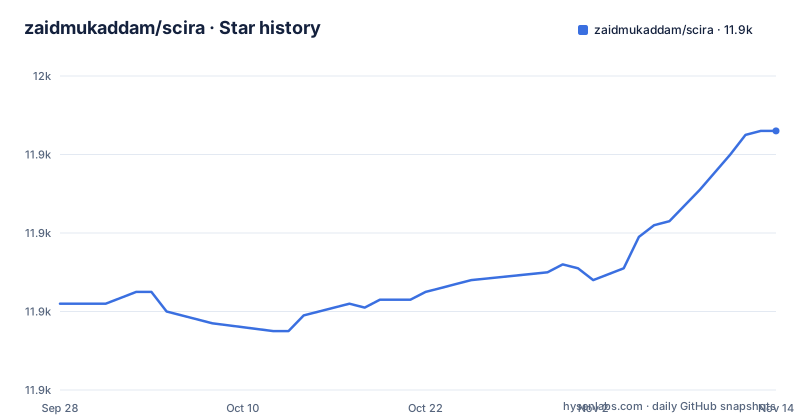
- zaidmukaddam/scira11,946 ★ · +44
| Repository | 2026-09-28 | 2026-11-14 |
|---|---|---|
| zaidmukaddam/scira | 11.9k | 11.9k |
44 Stars in the last 47 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Dockerfile installs with pnpm, and the repository ships a bun.lock
The container build names a package manager that the repository root does not back up. The dependency stage enables pnpm through corepack and installs from a lockfile it copies conditionally:
WORKDIR /app

# Copy package files and install dependencies using pnpm
# pnpm is used for faster and more efficient package management
COPY package.json pnpm-lock.yaml* ./
RUN corepack enable pnpm && pnpm i;
The top level of the repository contains bun.lock, and no pnpm-lock.yaml appears alongside it. The glob makes the copy tolerant of a missing file, so the build proceeds and resolves the dependency tree without a lockfile rather than failing loudly on the mismatch. The consequence is that the dependency versions you get from a self-hosted build are not pinned the way the source tree pins them, and the divergence grows with every release until someone regenerates the lockfile the Dockerfile expects.
The build stage copies .env, so secrets enter the image by design
The builder stage takes the whole context and then adds the environment file explicitly, copying .env into the application directory before running the build. That step means a .env file has to exist for the build to succeed, which is a reasonable requirement in Next.js projects that inline configuration at build time, but it also means the file lands in a build layer. The consequence for a self-hoster is that secrets are handled as a build input rather than as a runtime injection, and the image produced by docker-compose.yml is a production image with those values compiled in. The compose service sets NODE_ENV=production, PORT=3000, and HOSTNAME=0.0.0.0, maps port 3000, and restarts unless stopped.
Self-hosting runs on node:22-alpine as a non-root user
The runtime image is deliberately narrow. It starts from node:22-alpine, installs libc6-compat in the dependency stage because some npm packages carry native dependencies, and ends in a runner stage that creates a nodejs group at id 1001 and a nextjs user at id 1001 before switching to it with USER nextjs. Three paths are carried forward: the public directory, the standalone build output at /app/.next/standalone, and .next/static. The standalone output and static files are copied with chown to nextjs:nodejs; the public directory is copied without it. Port 3000 is exposed. The consequence is a small image with a real non-root default, but also a narrow one. Anything the standalone output does not trace is absent from the final stage, so a self-hoster who relies on a file the standalone trace missed will not find it in the final image.
Four of the seventeen search modes are marked Pro
The mode table carries a split that is easy to miss when reading feature lists. Connectors, which searches Google Drive, Notion, and OneDrive, is labelled Pro. Memory, described as a personal memory companion, is Pro. Voice, conversational AI with real-time voice, is Pro. XQL, an advanced X query language for tweet analysis, is Pro. The remaining modes carry no such marker, including Web for searching the entire web, Chat for talking to the model directly with no search, X for real-time posts and trends, Stocks, Code, Academic, Extreme for deep research with multiple sources, Reddit, GitHub, Crypto powered by CoinGecko, Prediction drawing on Polymarket and Kalshi, YouTube, and Spotify.
Every tool is a vendor API key, so the real dependency list is .env.example
The 28 tools are mostly thin wrappers over other companies' services, which means self-hosting moves the cost from Scira to your own account. Web search fans out across Exa, Firecrawl, Parallel, and Tavily with deduplication. Academic search uses Exa and Firecrawl. Reddit search uses Parallel, X search uses xAI Grok, YouTube search uses Supadata, GitHub search uses Firecrawl, and Spotify search uses the Spotify Web API. Stock charts, currency conversion, and Polymarket and Kalshi prediction market queries use Valyu, with Cohere reranking on prediction markets. Weather uses OpenWeatherMap and Open-Meteo, maps use the Google Maps API, and movie and TV tools use TMDB. .env.example lists keys for services such as Tavily, Exa, Firecrawl, TMDB, Spotify, Google Maps and OpenWeather, plus XAI, OpenAI, Anthropic, Groq, Inception, and Google Generative AI keys, DAYTONA_API_KEY, DATABASE_URL, REDIS_URL, BLOB_READ_WRITE_TOKEN, and BETTER_AUTH_SECRET.
Agentic planning means the model chooses the tools, so your key set has to be ahead of the query
The workflow is described in three steps: ask anything by typing a question, uploading a PDF, or pasting a URL, with an option to pick a mode or let Scira decide; the agent then breaks the question into sub-tasks, searches live sources, and cross-checks the evidence; and the answer arrives with inline citations you can click to verify. Agentic planning is stated more precisely elsewhere, as breaking complex questions into steps, selecting the right models and tools, and executing multi-step workflows end to end. The consequence is that the tool and key set an operator configures has to cover questions they have not seen yet.
Drizzle and two raw SQL files sit side by side in the schema story
The repository manages its database through two mechanisms that do not obviously belong together. TypeScript side, drizzle/ and drizzle.config.ts hold the Drizzle configuration and migrations, with DATABASE_URL supplied through the environment. SQL side, create_indexes.sql and reindex_tables.sql sit at the repository root as standalone files.
Version 0.1.0, private, and no releases, so upgrades come from the source tree
The packaging metadata says what kind of artifact this is. package.json names the project scira at version 0.1.0 with private set to true and type module, and the repository has no GitHub releases at all. What is published instead is a hosted app at scira.ai and a deploy path through the Vercel CLI, where deploy runs vc --prod and deploy:preview runs vc. Day to day work goes through next dev, next build, next start, eslint for lint, tsgo --noEmit for typecheck in both one-shot and watch forms, prettier for fix, knip for unused code, and an email:dev script pointing at ./components/emails. The consequence is that there is no upgrade path to follow and no changelog to read. A self-hoster is tracking a branch whose last push was 2026-08-12, and the only way to learn what changed is to read the diff yourself.
Editorial conclusion
Scira is worth reading if you want a citation-first search agent whose retrieval layer you can swap per query, since web search fans out across four providers and self-hosting is explicitly supported under AGPL-3.0. It is a poor fit if you need a turnkey container today: the build assumes a pnpm lockfile the repository does not ship, it requires a .env file inside the build context, and every mode depends on a vendor key you must supply yourself. Before deploying, copy .env.example and fill in only the keys for the modes you intend to use, decide whether the code interpreter keeps a Daytona dependency or gets replaced, and expect the image build to resolve dependencies without a lockfile unless you fix the package manager step.
Frequently asked questions
is scira ai free
The code is AGPL-3.0 licensed and the README lists self-hosting, bringing your own models, and connecting custom tools as features, so running it yourself is not gated. The hosted app is offered at scira.ai and the repository does not state its pricing, so whether the hosted version is free has to be checked there. Four modes carry a Pro label: Connectors, Memory, Voice, and XQL.
what is scira ai
Scira is a minimalistic AI-powered search engine, formerly named MiniPerplx, that plans, retrieves, and cites. It takes a typed question, an uploaded PDF, or a pasted URL, works across 17 search modes with 28 tools, and returns answers with inline citations you can click to audit. It is built on the Vercel AI SDK and released under AGPL-3.0.
scira vs perplexity
The README describes Scira as an agentic research platform with 17 search modes and 28 tools, inline citations on every answer, a code interpreter that executes Python in a sandboxed Daytona environment, and AGPL-3.0 self-hosting with a Dockerfile and docker-compose.yml.
scira ai vs perplexity
The README highlights grounded retrieval with clickable inline citations, agentic planning that selects models and tools per sub-task, and Lookouts, which schedule recurring research agents that monitor topics and email updates.
scira ai alternative
Within Scira, Chat mode talks to the model directly with no search, while Web mode searches the entire web with AI-powered analysis across Exa, Firecrawl, Parallel, and Tavily with deduplication.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zaidmukaddam-scira)Star history chart for your README
[](https://hysenlabs.com/projects/zaidmukaddam-scira)Was this useful?