HydraDB: a graph database whose only durable copy lives in object storage
HydraDB - fast graph database on object storage
At a glance
- What is it?
- HydraDB is an object-store-native graph database in Rust, with OpenCypher, Bolt, and separate data-node and indexer roles. The design is coherent, but the README leaves operational details thin.
- Who is it for?
- Adopt HydraDB if you already run S3-compatible object storage, want graph queries without provisioning local disks for durability, and can accept AGPL-3.0. Do not adopt it if you need a single-binary embedded graph, or if you cannot operate two separate process roles.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
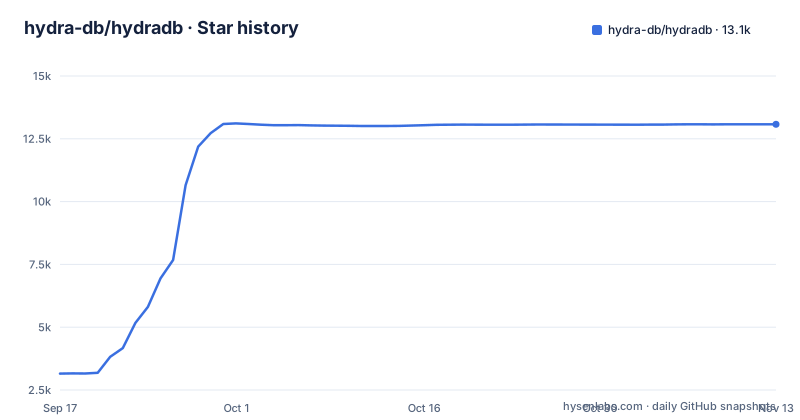
- hydra-db/hydradb13,076 ★ · +9,923
| Repository | 2026-09-17 | 2026-11-13 |
|---|---|---|
| hydra-db/hydradb | 3.2k | 13.1k |
9,923 Stars in the last 57 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem HydraDB targets: durable graphs without durable local disks
Most graph databases keep their authoritative copy on local disks attached to the machines running the query engine. That ties durability to those machines. Replacing a node means moving data; scaling reads means copying it. HydraDB inverts this. According to the README, "S3-compatible object storage is the durable source of truth," and both compute roles keep "only disposable state in memory and on local SSD or NVMe."
The audience is therefore narrow and specific: teams that already treat an object store as their system of record and want graph queries over it. If your data already sits in S3 and you are bolting on a graph layer, the storage model is a fit. If you want a graph library inside one process, it is not.
The README frames the benefit as compute that "can be replaced or scaled without moving the graph itself." That is the whole pitch, and it is a real one. It is also the source of every operational constraint below.
Two roles, one object store: how graph-node and graph-indexer divide the work
The architecture is a split between serving and indexing. Query nodes, the graph-node binary, "serve reads and canonical graph mutations." Indexer workers, the graph-indexer binary, "build immutable CSC generations asynchronously." Both talk to the same object store and neither holds a durable local copy.
Reads are snapshot-based. The README states that "every query runs against one pinned SlateDB snapshot," and that indexed traversal "combines a compiled CSC generation with its visible WAL overlay." That second sentence is the interesting one. A CSC generation is a compressed sparse column structure, the immutable artifact an indexer publishes "through atomic object-store pointers." The WAL overlay is the tail of writes that the index has not yet absorbed. Because the reader merges the two, "readers remain correct when an index is absent or behind." An indexer that has crashed, or that is simply lagging, costs you speed rather than correctness.
Writes are serialized per cell. The README describes "object-store CAS leases" selecting "the active writer for each cell," with "SlateDB writer epochs" fencing stale writers. The cell is the unit of coordination: GRAPH_CELL_ID and GRAPH_CELLS appear in the local server example. The README does not spell out how cells map to nodes or how many cells a single deployment should use, so that is something to settle from architecture.md before designing a topology.
Execution is graph-native rather than a translation layer: the planner uses "property indexes, reverse adjacency, sparse traversal, and SuiteSparse GraphBLAS where appropriate." Clients reach it two ways, Neo4j drivers over Bolt 5.x or the typed JSON and streaming NDJSON HTTP API.
Running a local HydraDB node with Docker and verifying it
The README's Getting Started path builds from source. It requires Rust 1.91 or newer, a C/C++ toolchain, libcypher-parser and SuiteSparse GraphBLAS, and `just` is the supported command runner. Then clone and verify:
git clone https://github.com/hydra-db/hydradb.git
cd hydradb

just native-check
just smoke
The smoke example creates a local graph, writes and deletes edges, runs a sparse traversal, closes the database, reopens it, and verifies the durable result. `just minio-smoke` exercises the same flow against an ephemeral MinIO instance.
To run a single plaintext development node backed by a local directory, the README creates a store directory, a cache directory and a token file, then exports the node's settings, including CLOUD_PROVIDER=local, LOCAL_PATH, GRAPH_CELL_ID=cell-0, GRAPH_CELLS=cell-0 and GRAPH_DATA_CACHE_DIR. TLS is required by default in deployed environments, and plaintext must be enabled explicitly. The node runs in the foreground and listens on 7687 for Bolt, 8443 for the JSON and NDJSON HTTP query API, and 9090 for readiness and Prometheus metrics. CLOUD_PROVIDER=local with LOCAL_PATH points the storage layer at a local directory instead of S3, which is what makes this a single-machine setup.
From a second shell, the README checks the node by writing and reading a small graph through the HTTP query API on port 8443. For source builds, the repository expects Rust 1.91 or newer, and the Dockerfile installs libcypher-parser-dev and libgraphblas-dev, so those native dependencies are not optional. The justfile exists to set the environment those builds need, including RUST_MIN_STACK=33554432, which the justfile explains is because "OpenCypher's async query futures exceed the 2 MiB default thread stack."
Where HydraDB is the wrong tool
The two-role split is the design, and it is also the tax. A single-node deployment still involves deciding what to do about indexing. If you run only graph-node, queries remain correct but traversal falls back to whatever the planner can do without a published CSC generation. The README does not quantify that penalty, and it would be wrong to guess at it. What it does say is that readers stay correct, which is a correctness guarantee, not a performance one.
The object store is a hard dependency in any real deployment. CLOUD_PROVIDER=local with a host directory is a development convenience, not a production topology, and the repository carries a charts/ directory for deployments. If you have no S3-compatible storage and no intention of running one, the architecture offers you nothing over a conventional graph database.
AGPL-3.0 is the other boundary. The licence badge and LICENSE file are unambiguous. For a database that a service links against, that is a decision for your legal team, not a footnote.
Finally, the README's local server example is a plaintext development node backed by a local directory. The README's opening sections do not describe backup, restore, or rollback procedures, which matters more for a system whose durability story rests entirely on objects you do not control.
How HydraDB differs from Neo4j and from embedded graph engines
The nearest comparison is Neo4j, and the README invites it by supporting Bolt 5.x, which means existing Neo4j drivers work unchanged. The difference is where the data lives. A Neo4j deployment keeps its store on the machines in the cluster; HydraDB keeps records, WALs, manifests, and traversal indexes in object storage and treats local disks as cache. That changes failure handling: losing a HydraDB compute node loses cache, not data.
Against an embedded graph engine, the difference runs the other way. An embedded engine is a library in your process, with no server, no ports, no token file, and no indexer. HydraDB is a server with a query engine, a Bolt endpoint, an HTTPS API on 8443, metrics on 9090, and a background indexing tier. If your graph fits in memory and your process is the only reader, that is a great deal of machinery to adopt.
The repository also ships examples/falkor_import.rs and workspace crates falkordb-rdb and falkor-dump-import, which suggests the maintainers have looked at importing from FalkorDB. The README does not describe what that example covers in detail, so anyone migrating from FalkorDB should read the example rather than assume a supported migration path.
Maintenance, upgrades and what AGPL-3.0 means in practice
The repository is not archived, and the last push was on 2026-10-28. It has published GitHub releases v0.2.0 (2026-09-30) and v0.3.0 (2026-10-25), and CHANGELOG.md sits at the top level, so that is where to read upgrade notes.
Upgrade cost has one structural component worth naming. Because indexers publish immutable CSC generations through atomic object-store pointers, an index format change would mean rebuilding indexes rather than migrating a store in place. The README does not state a compatibility policy for index generations, so that is a question to answer before you depend on a long-lived deployment.
On licensing: AGPL-3.0 is a strong copyleft licence with a network-use clause. The repository is the source of truth for what that means for your use, and this article is not legal advice.
Editorial conclusion
Adopt HydraDB if you already run S3-compatible object storage, want graph queries without provisioning local disks for durability, and can accept AGPL-3.0. Do not adopt it if you need a single-binary embedded graph, or if you cannot operate two separate process roles. Before committing, confirm the indexer role is running so traversal indexes are built, and read architecture.md for the failure semantics the README leaves out.
Frequently asked questions
What is HydraDB?
It is an object-store-native distributed graph database written in Rust. It combines durable graph storage on SlateDB with snapshot-consistent OpenCypher queries, GraphBLAS traversal, Neo4j-compatible Bolt connectivity, and an HTTPS query API.
Is HydraDB open source?
Yes. The repository carries an AGPL-3.0 licence, shown by the licence badge in the README and the LICENSE file at the top level of the repository.
What is a HydraDB alternative if I do not want object storage?
HydraDB's defining choice is that S3-compatible object storage is the durable source of truth, with compute keeping only disposable state. If you want the graph on the machines running the engine, a conventional graph database such as Neo4j is the different approach, and HydraDB still speaks Bolt 5.x so Neo4j drivers work against it.
What is Hydra in AI?
HydraDB is not an AI system; its README describes it as an object-store-native distributed graph database written in Rust.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/hydra-db-hydradb)
[](https://hysenlabs.com/projects/hydra-db-hydradb)Star history chart for your README
[](https://hysenlabs.com/projects/hydra-db-hydradb)Was this useful?