Jackett: one scraper for the torrent trackers your media apps cannot keep up with
API Support for your favorite torrent trackers
At a glance
- What is it?
- A C# proxy that translates Torznab queries into site-specific scrapes, maintained as a long list of one-off fixes to trackers that change their HTML on a schedule.
- Who is it for?
- Jackett is the right tool for a specific shape of problem: you run one of the supported applications, you want results from trackers that application has no integration for, and you would rather not maintain a fork of that application. It does that job and it does it in one place, which is why the release notes look the way they do.
- Can I use it commercially?
- Yes, with conditions. GPL-2.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C#, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 22, 2026, and from our analysis. They are not legal advice.
Star history
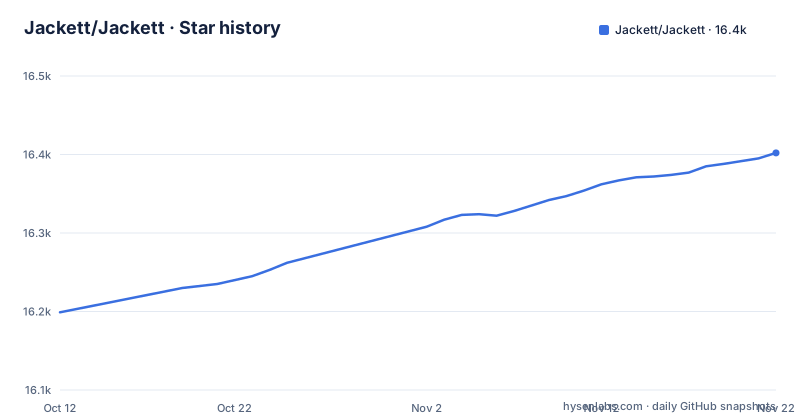
- Jackett/Jackett16,402 ★ · +203
| Repository | 2026-10-12 | 2026-11-22 |
|---|---|---|
| Jackett/Jackett | 16.2k | 16.4k |
203 Stars in the last 41 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A translation layer between your apps and the trackers
Jackett's own description of what it does is precise: it works as a proxy server that translates queries from applications such as Sonarr, Radarr, SickRage, CouchPotato, Mylar3, Lidarr, DuckieTV, qBittorrent, Nefarious and NZBHydra2 into tracker-site-specific HTTP queries, parses the HTML or JSON response, and sends results back.
Read that sentence as a pipeline and the architecture becomes obvious. The input is a standard API call, the middle is per-site scraping logic, and the output is the same standard API. What Jackett provides is a single repository of maintained indexer scraping and translation logic, which removes the tracker integration burden from every other application. It also gives you recent uploads in the manner of RSS feeds, searches across multiple trackers at once, and results in a standardized Torznab or TorrentPotato format.
The Torznab specification is the important detail. Because the output is Torznab rather than a proprietary shape, an application that already speaks Torznab can consume Jackett without knowing anything about the trackers behind it. That is the whole reason the project exists at this scale, and it is why the README links the Torznab 1.3 draft alongside the older TorrentPotato provider page for CouchPotato.
Public, semi-private and private trackers are all supported, which is the distinction that matters in practice.
The tracker list is a snapshot, not a contract
The README's supported trackers section is the longest part of the document, split into three collapsed lists. The public list runs to 96 entries and includes the sites you would expect, Nyaa.si and its sukebei variant, The Pirate Bay and TheRARBG among the older names, plus language-specific and niche sites such as AniLibria, Anime Tosho, E-Hentai and LinuxTracker. The semi-private list adds the ones needing credentials, and the private list is the credentialed tier proper.
Treat those lists as a snapshot of one moment. The release list shows why: v0.24.2985, v0.24.2994 and v0.24.3003 were published on 2026-11-01, 2026-11-02 and 2026-11-03.
That is a maintenance pattern you should factor into your decision. Every entry needs its own scraper, and every entry breaks when the site changes a domain, a category taxonomy or a page template. The build badge points at Azure Pipelines, and the project ships roughly daily patch releases within a fixed 0.24 major version. The work is continuous and it is maintenance rather than feature work.
One more README note worth repeating back to yourself before installing: the Discord server is no longer maintained, and the project asks for problems to be filed as GitHub issues. With 212 open issues and 1,565 forks, that tracker is where the community actually is.
Supported systems and what 0.24 pins
The supported version is stated as 0.24 and up, and prior versions are explicitly no longer supported. That version number is tied to a set of operating system floors, because it runs on the .NET runtime:
Windows 10 Version 1607 or greater, various Linux distributions, and macOS 13.0 or later. The README links the .NET supported-OS lists rather than restating them, which is the honest thing to do since those pages change with runtime releases.
The repository tree explains the shape of the deliverable. There is `src/` for the C# code, `Installer.iss` for the Windows installer script, and a set of platform service scripts sitting at the top level: `install_service_systemd.sh`, `install_service_systemd_mono.sh`, `install_service_macos` and matching uninstallers, plus `jackett_launcher.sh` and `jackett_launcher.bat`. `Upstart.config` suggests the older process supervisors were supported as well. There is also `azure-pipelines.yml` for CI and `yamllint.yml`, which is a small hint that YAML configuration files are linted in this project.
A C# codebase of this size is not something you would patch casually, and the README says so by asking for development help and pointing contributors at CONTRIBUTING.md. A third-party Go SDK exists at webtor-io/go-jackett if you want to drive Jackett from Go rather than curl it.
Caches, Cloudflare challenges and the OMDb lookup
The configuration section is where the project is most honest about how scraping fails in the real world. Two separate caches exist, a search cache and a Torznab cache.
FlareSolverr configuration has its own section, and its existence explains a category of problem you will hit otherwise. Sites behind Cloudflare challenge pages return HTML that looks valid and contains no results. FlareSolverr is a companion service that solves the challenge in a browser and hands back a cookie, and Jackett can use that cookie to get past the gate. FlareSolverr is not required for trackers that do not use it.
OMDb configuration is listed too, which is metadata rather than search.
Running behind a reverse proxy is also documented, which matters because Jackett hands out Torznab URLs pointing at itself and those URLs have to reach the client application from wherever that runs.
Search modes, filters and aggregate indexers
The API usage section is structured around three ideas: the Torznab query syntax itself, the search modes and parameters Jackett adds on top, and the two kinds of indexer grouping.
Filter indexers restrict what Jackett searches.
Aggregate indexers are the other half and they work the other direction. Instead of restricting, an aggregate groups several configured indexers behind one endpoint, so a client configured against that aggregate sees a single tracker that fans out across the group.
The practical reading is that the two features are complementary. Filters narrow what is searched, and aggregates save you from configuring each site individually in every application.
Editorial conclusion
Jackett is the right tool for a specific shape of problem: you run one of the supported applications, you want results from trackers that application has no integration for, and you would rather not maintain a fork of that application. It does that job and it does it in one place, which is why the release notes look the way they do. The cost is that you are running a scraper whose subject matter moves underneath it, and the domain list in the README is a snapshot rather than a contract. The version line, 0.24, moves daily and pins the operating system floor at Windows 10 Version 1607 and macOS 13, so treat the version string as the thing to watch rather than the star count. If you want a maintained indexer layer instead of a maintained scraper collection, Prowlarr is the project to compare against first.
Frequently asked questions
What is a jackett?
In the software sense, Jackett is a proxy server that translates queries from media applications such as Sonarr and Radarr into tracker-specific HTTP requests, parses the responses, and returns results in a standardized Torznab or TorrentPotato format. It maintains the scraper and translation logic for each tracker in one place instead of in every application.
How do I use Jackett?
Install it, add a tracker or indexer for the sites you want, then point your application at the Torznab URL Jackett gives that indexer. Jackett searches across every configured indexer and returns normalized results, so the application never needs a per-site integration. Filters and aggregate indexers let you narrow or group sites at the Jackett layer instead of in each client.
Is Jackett better than Prowlarr?
The README does not position Jackett against Prowlarr. What it describes is a single repository of maintained indexer scraping and translation logic covering public, semi-private and private trackers, returning results in Torznab or TorrentPotato format.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/jackett-jackett)Star history chart for your README
[](https://hysenlabs.com/projects/jackett-jackett)Was this useful?