MiniMind: A 64M-Parameter LLM You Can Train from Scratch on One GPU
🧠 Train a 64M-parameter LLM from scratch in just 2h!
At a glance
- What is it?
- MiniMind is an open-source project that walks you through training a 64M-parameter language model from scratch on a single GPU, with about two hours for one SFT epoch on an NVIDIA 3090, and all core algorithms implemented in raw PyTorch.
- Who is it for?
- Adopt MiniMind if you are a student, researcher, or hobbyist who wants to understand the inner workings of LLMs by writing and running every training stage yourself, and if you have a single modern GPU like a 3090. Do not adopt it if you need a production-ready model with state-of-the-art quality, or if you prefer high-level abstractions like transformers Trainer.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 19 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
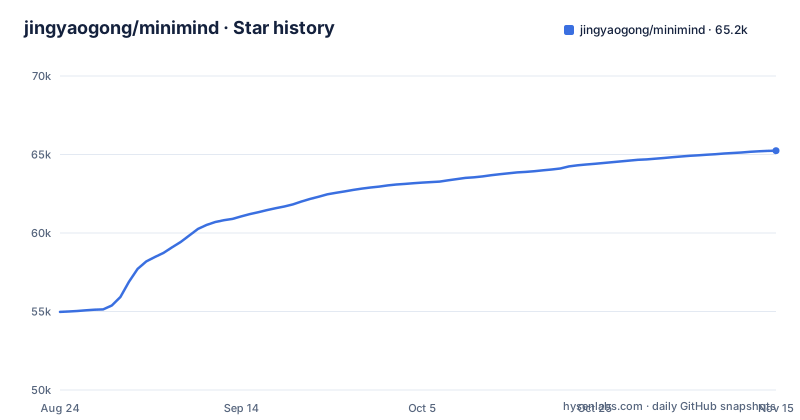
- jingyaogong/minimind65,243 ★ · +10,271
| Repository | 2026-08-24 | 2026-11-15 |
|---|---|---|
| jingyaogong/minimind | 55k | 65.2k |
10,271 Stars in the last 83 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What MiniMind Actually Solves
Most LLM tutorials stop at fine-tuning a pretrained model with LoRA. MiniMind targets the gap between that and understanding how a transformer is built and trained from zero. The project's stated goal is to let anyone with a personal GPU train a 64M-parameter model in about two hours on a single NVIDIA 3090, at a GPU rental cost of roughly 3 yuan. That claim is specific to the SFT stage running one epoch on that hardware, not the full pipeline. The intended audience is people who want to read and modify every line of a training loop, not those who just want to deploy a chatbot. The README is explicit about this: it criticizes frameworks like transformers, trl, and peft for hiding the underlying implementation behind high-level interfaces. MiniMind is a teaching tool first, a model second.
Architecture: Dense and MoE Aligned with Qwen3
The current mainline structure aligns with the Qwen3 and Qwen3-MoE ecosystem. The dense model has about 64M parameters, and the MoE variant has 198M total with 64M active parameters. The MoE design removes the shared expert, which is a notable divergence from some other MoE implementations. The tokenizer is a custom BPE + ByteLevel tokenizer, trained as part of the project, and it includes special tokens for tool calls and reasoning, like <tool_call> and <tool_response>. There is also a thinking tag, which the model can use to emit reasoning before answering. The project includes code for tokenizer training, which is rare in educational repos. The architecture is deliberately small: the README notes the mainline model is roughly 1/2700 the size of GPT-3, which makes it feasible to train on a single consumer GPU.
The Full Training Pipeline, All from Scratch
MiniMind covers the entire training lifecycle: pretraining, supervised fine-tuning (SFT), LoRA, RLHF via DPO, and RLAIF via PPO, GRPO, and CISPO. There is also support for tool use, agentic RL, adaptive thinking, and model distillation. The key point is that all core algorithms are implemented natively in PyTorch, not wrapped from third-party libraries. For example, LoRA is implemented from zero, and DPO is also implemented from zero. This is a deliberate design choice. It means you can step through the code to see exactly how gradient updates happen during LoRA, or how the DPO loss is computed. The trade-off is that you do not get the battle-tested optimizations of libraries like peft or trl. The project does claim compatibility with those frameworks for loading and inference, but the training code itself is self-contained.
Getting It Running: Commands and Config
The repository is structured with scripts for each stage. The README mentions several specific files: train_agent.py for agentic RL, serve_openai_api.py for an OpenAI-compatible server, web_demo.py for a Streamlit chat UI, and scripts/chat_api.py for inference examples. To train, you would clone the repo, install PyTorch and any dependencies, and then run the appropriate Python script for the stage you want. The project uses jsonl data files like pretrain_t2t_mini.jsonl and sft_t2t_mini.jsonl, which are provided as part of the open-source data. For LoRA weight merging, there is a script scripts/convert_model.py that combines a base model with LoRA weights into a full model. The repository's requirements.txt pins the Python dependencies, with torch itself commented out.
Limitations and Wrong Use Cases
The most obvious limitation is model quality. A 64M-parameter model is not going to compete with models like Qwen or DeepSeek on complex reasoning or broad knowledge. The README does not claim otherwise; it positions MiniMind as a learning tool. A second limitation is the hardware requirement. While the SFT stage runs in 2 hours on a 3090, pretraining and RLHF stages will take longer, and the total cost will exceed 3 yuan. The project also has a history of breaking changes. The 2025-04-26 update renamed all model parameters to align with Transformers, and as a result old models from before that date cannot be loaded directly. The update notes that the minimind-v1 series is no longer maintained. This means you cannot assume that code from a tutorial written six months ago will work with the current master branch. For production use, this is the wrong tool. For a quick experiment with a real chatbot, you would be better served by a small pretrained model from Hugging Face.
Alternatives: What Else Is Out There
The closest alternative in spirit is nanoGPT, Andrej Karpathy's educational GPT implementation. nanoGPT also trains a small GPT from scratch in PyTorch, but it focuses only on pretraining and does not cover SFT, RLHF, or tool use. MiniMind goes further along the full training pipeline. Another alternative is TinyLlama, which trains a 1.1B model, but it requires multiple GPUs and far more compute, so it is not a realistic personal project. A more modern alternative is the Hugging Face transformers library with a small model like GPT-2, but that hides the implementation details that MiniMind exposes. The difference is the level of abstraction: transformers gives you a Trainer class that handles everything, while MiniMind forces you to write the training loop yourself. If you want to learn, that is the point. If you want to ship a model, that is the cost.
Maintenance and Upgrade Costs
The project is actively maintained, with a v2 release in October 2025, minimind-3 models released on 2026-04-01 and a last push on 2026-10-27. That activity is a double-edged sword. The 2025-04-26 update introduced breaking changes that made old models incompatible. The README explicitly states that the project will no longer maintain the minimind-v1 series. If you build on MiniMind, you must track the changelog and be prepared to migrate your code and weights. The project uses an Apache-2.0 license, which means you can use, modify, and distribute it freely, including for commercial purposes, as long as you preserve the license notice. For a learning project, this is a low-risk license. For a product, you need to check the license of the datasets you use, since the project provides open-source data.
What to Verify Before You Start
Before you invest time in MiniMind, verify three things. First, check that your GPU has enough VRAM. The README mentions a 3090, which has 24GB, for the 2-hour SFT run. A smaller GPU may still work but will likely take longer. Second, confirm that the current master branch matches the tutorial you are following. The project has changed data formats, tokenizer, and model naming over time, so an older blog post may not work. Third, look at the project documentation at https://jingyaogong.github.io/minimind, the homepage listed for the repository. If you are coming from a transformers background, expect to spend time reading Python code rather than writing config files.
Editorial conclusion
Adopt MiniMind if you are a student, researcher, or hobbyist who wants to understand the inner workings of LLMs by writing and running every training stage yourself, and if you have a single modern GPU like a 3090. Do not adopt it if you need a production-ready model with state-of-the-art quality, or if you prefer high-level abstractions like transformers Trainer. Before you start, verify that your GPU is comparable to the NVIDIA 3090 the README's two-hour SFT timing was measured on, and check the release notes for breaking changes between versions, since the project has already dropped support for older model series.
Frequently asked questions
What is a MiniMind?
MiniMind is a set of open source model structures and training code for very small language models, the main line being a model of roughly 64M parameters trained from scratch rather than fine-tuned. The repository covers the whole pipeline: pretraining, SFT, LoRA, RLHF-DPO, RLAIF with PPO, GRPO and CISPO, tool use and agentic RL.
What type of AI model is MiniMind?
The main line is an autoregressive language model, published as a Dense version of about 64M parameters and a Mixture of Experts version at 198M-A64M, both aligned with the Qwen3 and Qwen3-MoE ecosystem. Vision, omni, discrete diffusion and linear attention variants are developed as separate projects.
Is MiniMind safe and secure?
The repository is Apache 2.0 licensed training code with a pinned requirements.txt, and the README links an online demo on ModelScope. The top level holds no security policy file, only CODE_OF_CONDUCT.md and LICENSE, so what you run is your own PyTorch installation and your own copy of the datasets.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/jingyaogong-minimind)Star history chart for your README
[](https://hysenlabs.com/projects/jingyaogong-minimind)Was this useful?