Autoresearch: Karpathy's Overnight LLM Optimization Loop for One GPU
GitHub describes it as AI agents running research on single-GPU nanochat training automatically. The repository metadata lists Python as its primary language. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- A small repo that turns a single NVIDIA GPU into an autonomous research lab, where an AI agent edits train.py, trains for exactly five minutes, and keeps or discards the change. The core judgment: it is a clever idea with a deliberately narrow scope, and its value depends on how well the agent can navigate a single-file codebase.
- Who is it for?
- Use autoresearch if you have a single NVIDIA GPU, a Python 3.10+ environment with uv, and you want to experiment with automated hyperparameter and architecture search without writing your own orchestration. Do not use it if you need multi-GPU training, non-NVIDIA hardware, or reproducible results across different platforms, because the fixed 5-minute budget makes runs incomparable across machines.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
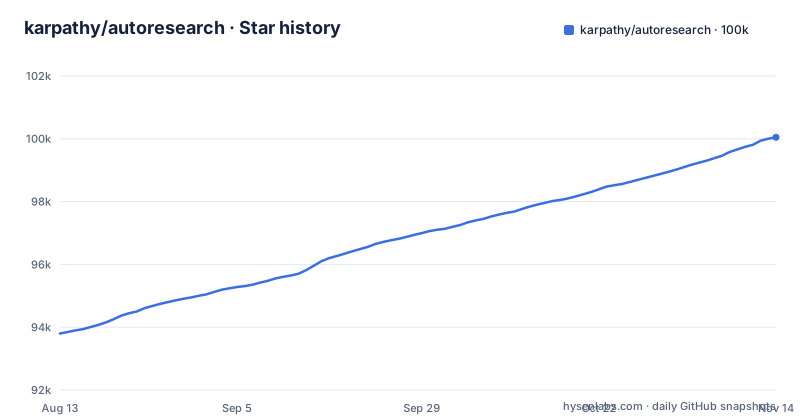
- karpathy/autoresearch100,047 ★ · +6,248
| Repository | 2026-08-13 | 2026-11-14 |
|---|---|---|
| karpathy/autoresearch | 93.8k | 100k |
6,248 Stars in the last 93 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Problem This Solves
The problem is the human bottleneck in iterative LLM training experiments. A researcher normally edits a training script, launches a run, waits, inspects the loss curve, and repeats. That cycle is slow and occupies the researcher's attention. Autoresearch hands the loop to an AI agent. The agent modifies the training code, runs a fixed 5-minute training session, checks the validation bits per byte (val_bpb), and keeps or discards the change. The intended user is someone who has a single NVIDIA GPU, knows how to run a Python script, and wants to wake up to a log of experiments and a possibly better model. The README frames it as a story about autonomous research swarms, but the practical target is a solo engineer or researcher who wants to offload the tedious part of tuning a small language model.
The Three-File Architecture
The repository is deliberately small. Three files matter. prepare.py holds fixed constants, one-time data preparation (downloading data and training a BPE tokenizer), and runtime utilities like the dataloader and evaluation. It is not meant to be modified. train.py is the single file the agent edits. It contains the full GPT model, the optimizer (Muon and AdamW), and the training loop. The README says everything is fair game: architecture, hyperparameters, optimizer, batch size. program.md is the human's input. It contains instructions for the agent, and the human edits it to shape the research process. The agent never touches prepare.py or program.md. That separation keeps the diffs reviewable and the experiment scope manageable. The human programs the research organization by editing program.md, not by editing Python. That is the core design bet: the agent is the worker, and the human is the manager who writes the brief.
The Fixed 5-Minute Time Budget and the val_bpb Metric
The most distinctive mechanism is the fixed time budget. Training always runs for exactly 5 minutes of wall clock, excluding startup and compilation. This design has two stated upsides. First, experiments are directly comparable regardless of what the agent changes: a larger model, a different batch size, or a new optimizer all compete for the same wall-clock time. Second, the search finds the best model for your specific platform within that budget. The downside is explicit in the README: your results are not comparable to someone else running on different hardware. The metric is val_bpb, validation bits per byte, which is lower better. The README claims it is vocab-size-independent, so architectural changes that alter the tokenizer or vocab size can still be compared. That is a sound choice for a search over architecture, but it also means the agent is optimizing for a single number, not for downstream task performance. A model that achieves a lower val_bpb might still be worse at a specific task, but the repo does not address that.
Getting It Running: Commands and Configuration
The quick start is explicit. You need a single NVIDIA GPU (tested on H100), Python 3.10 or later, and the uv package manager. The commands are: curl -LsSf https://astral.sh/uv/install.sh | sh to install uv, then uv sync to install dependencies, then uv run prepare.py for one-time data prep (the README says this takes about 2 minutes), and finally uv run train.py to run a single training experiment, which takes about 5 minutes. After that, you can go into autonomous mode by launching an AI agent like Claude or Codex in the repo, disabling permissions, and prompting it to look at program.md and kick off an experiment. The README gives an example prompt. The configuration lives in program.md for the agent's instructions, and in constants inside prepare.py and train.py. For smaller platforms, the README suggests tuning: lower MAX_SEQ_LEN in prepare.py, possibly down to 256; reduce vocab_size from 8192 to 4096 or lower, or even use a byte-level tokenizer with 256 bytes; decrease EVAL_TOKENS; and adjust DEVICE_BATCH_SIZE in train.py. These are real knobs, but they require editing the Python files, which contradicts the clean separation for the human, but that is only for forks, not for the main flow.
Running the Agent: What Actually Happens
The README does not provide a full trace of the agent's decision loop, but it describes the intended flow. You launch an agent in the repo with permissions disabled, and you prompt it to look at program.md and start an experiment. The agent reads program.md, which contains baseline instructions, then edits train.py, runs the training for 5 minutes, evaluates val_bpb, and decides to keep or discard the change. The README says the agent modifies train.py and iterates. The mechanism is clear in principle: the agent is a loop that edits, trains, evaluates, and keeps or reverts. But the repo does not include a script that automates this loop. The agent is external, like Claude or Codex, and the repo only provides the context via program.md. That means the reproducibility of the research depends entirely on the agent's behavior, which is not pinned to a specific version. If you use a different agent or a different model, the results will vary.
Limitations and Failure Modes
The most obvious limitation is hardware. The code requires a single NVIDIA GPU, and the README explicitly says it is tested on an H100. Running on a Macbook or a CPU is not supported out of the box, and the README points to forks for that. Even with a GPU, the 5-minute budget is a hard constraint. If your GPU is slower, the model will not train as much, and the search will favor smaller models. That is by design, but it means the results are only meaningful for your specific hardware. Another failure mode is the agent's edits to train.py. The agent can change anything, and a bad edit could break the training loop entirely. If the agent makes a change that causes an exception, the run might fail, and the agent might not recover. The README also notes that the default program.md is a bare bones baseline, so the quality of the research depends on how well the human writes that file. A poorly written program.md could lead the agent to waste time on pointless experiments. Finally, the metric val_bpb is not a proxy for model quality on real tasks. A lower val_bpb does not guarantee a better chatbot or better downstream performance.
Alternatives: Manual Tuning and Automated Search Libraries
The most direct alternative is doing the experiments yourself. Instead of letting an agent edit train.py, you edit it manually and run train.py repeatedly. That gives you full control and a clear understanding of each change, but it is slower and requires you to be present. The README's fixed 5-minute budget is actually an advantage here: you can run many experiments in an hour without a complex scheduler. Another alternative is to use a general-purpose hyperparameter optimization library like Optuna or Ray Tune. Those tools automate the search over hyperparameters, but they do not modify the architecture or the optimizer code. They typically sample from a predefined search space and use a trial-based mechanism. Autoresearch is different because the agent can rewrite the training code itself, which allows for architectural changes that a hyperparameter search cannot do. However, that freedom also makes the search less controlled. A library like Optuna gives you a structured search with a clear objective and a history of trials, while autoresearch gives an open-ended, agent-driven exploration. The choice depends on whether you want to explore code-level changes or just tune numeric hyperparameters.
Maintenance, Upgrade Cost, and Licensing
The repository is a small, self-contained project with no recent releases listed and no license specified. The absence of a license is a practical concern if you plan to fork or redistribute the code. You cannot assume it is open source without an explicit license, so you should contact the author or check the repository for a license file before using it in a commercial project. Maintenance is minimal because there are few dependencies: the README says no external dependencies beyond PyTorch and a few small packages. That reduces the upgrade burden. However, the project depends on the external agent (Claude, Codex, etc.), and those agents change over time. The behavior of the agent is not pinned, so upgrading your agent tool could change the quality of the research. The repo itself is unlikely to change much because it is a small experiment, but the README mentions that the author is open to linking forks for other platforms. If you need CPU or MPS support, you will have to maintain a fork yourself. The 5-minute budget is a fixed constant, but if you change it, the comparability of experiments breaks, so you should treat it as a hard invariant.
Editorial conclusion
Use autoresearch if you have a single NVIDIA GPU, a Python 3.10+ environment with uv, and you want to experiment with automated hyperparameter and architecture search without writing your own orchestration. Do not use it if you need multi-GPU training, non-NVIDIA hardware, or reproducible results across different platforms, because the fixed 5-minute budget makes runs incomparable across machines. Before adopting, verify that your GPU can run the default train.py within the 5-minute budget, and check whether you are comfortable with the agent's edits to train.py. Also confirm the license, as the repository does not specify one, which may affect redistribution.
Frequently asked questions
What is autoresearch?
autoresearch is a small Python LLM training setup in which an AI agent modifies one file, trains for a fixed five minutes, checks whether validation bits per byte improved, then keeps or discards the change and repeats. The training code is a simplified single-GPU implementation of nanochat.
How do I install autoresearch?
You need a single NVIDIA GPU, Python 3.10 or newer, and uv. Install uv, run uv sync to install dependencies, then run uv run prepare.py once to download training data and train a BPE tokenizer, which takes about two minutes. Dependencies resolve torch 2.9.1 from an explicit CUDA 12.8 index.
How do I use autoresearch with Claude Code?
Point the agent at program.md inside the repository with permissions disabled and ask it to start an experiment. The project's own suggestion is to spin up Claude or Codex in the repo, disable all permissions, and prompt it to look at program.md and kick off a new experiment.
How does autoresearch work?
Three files carry the project. prepare.py holds fixed constants, one-time data prep and runtime utilities and is not modified, train.py holds the model, the Muon and AdamW optimizer and the training loop and is the file the agent edits, and program.md holds the instructions that a human edits and the agent reads.
What is karpathy's autoresearch?
It is described as giving an AI agent a small but real LLM training setup to experiment with autonomously overnight, where the human programs the program.md Markdown rather than the Python files, iterating on it to find the research org code that makes the fastest progress. The last push was on 2026-03-26 and the repository has no GitHub releases.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/karpathy-autoresearch)Star history chart for your README
[](https://hysenlabs.com/projects/karpathy-autoresearch)Was this useful?