Knockout: MVVM data binding for plain HTML and JavaScript
Knockout makes it easier to create rich, responsive UIs with JavaScript
At a glance
- What is it?
- Knockout is an MVVM library that keeps a JavaScript view model and the DOM in sync through observables and declarative bindings. It installs from npm or a released script file, and is MIT-licensed.
- Who is it for?
- Adopt Knockout when you have server-rendered HTML and want a view model to drive it without a build step, and when the binding surface in the documentation covers what you need. Do not adopt it if you want a component framework with routing and state management built in, or if you cannot audit the bindings your templates already use.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
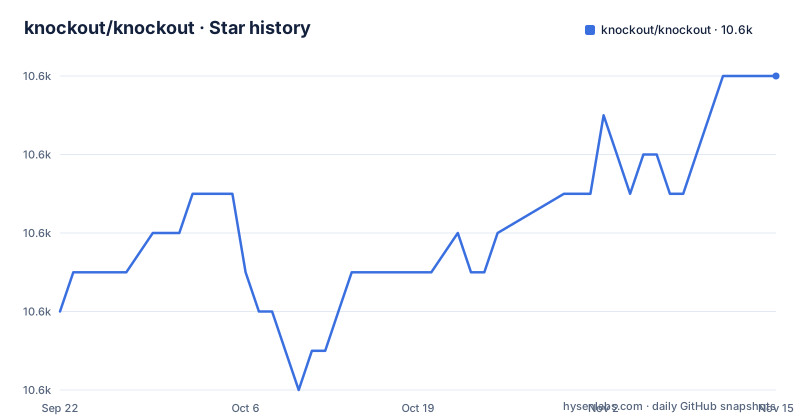
- knockout/knockout10,566 ★ · +6
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| knockout/knockout | 10.6k | 10.6k |
6 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Knockout solves, and which codebases it fits
The README describes Knockout as a JavaScript MVVM library that uses observers to keep a UI in sync with an underlying data model, plus a set of declarative bindings. That is a narrow promise, and it is worth taking literally. Knockout does not own your application structure, your routing or your data fetching. It owns the link between a view model object and the DOM nodes that display it.
The fit is a page that already has HTML and needs that HTML to react to changes in JavaScript state without hand-written DOM updates. A form with dependent fields, a list that filters as you type, a table whose rows recompute when a filter changes: these are the cases the library targets.
It is a poor fit when the whole application is being written from scratch in a component model. Knockout gives you bindings, not a component tree, a router or a store. Teams that want those pieces in one package will spend time assembling them.
One more boundary: Knockout is a browser library. The README states plainly that once built, Knockout has no dependency on Node.js or Java, and that it works with any server technology or none. Node.js and Java appear only as build prerequisites.
Observables, bindings and the data flow between model and DOM
The mechanism the README names is observers. A view model holds observable values; the markup declares bindings that read those values; when an observable changes, the bound DOM updates. The direction of travel matters. You do not query the DOM to find out what the user typed. You read the observable.
Bindings are declared in HTML attributes rather than assembled in JavaScript. That is the design decision that separates Knockout from a virtual DOM library: the template is the existing markup, annotated, and the browser parses it as it always would. There is no compile step required to make a page work, which is why the library can be dropped into a server-rendered page.
The repository layout reflects a single-library distribution rather than a framework. The top level holds src/, spec/, build/, Gruntfile.js, package.json, bower.json and LICENSE. The package entry point is build/output/knockout-latest.js, with type definitions at build/types/knockout.d.ts. That means the published artifact is a built file, and the source tree is not what consumers load.
Because bindings are extensible, the practical surface of a Knockout application is whatever bindings the team has written or pulled in, not just the built-in set. The README calls the binding set powerful and extensible; it does not enumerate them, and the documentation on the project website is where that list lives.
Installing Knockout and wiring a first observable
The README gives two routes. Released versions are downloadable from the project website, and Node.js developers can install from npm with a single command. The npm route is the one that fits a project with a package.json.
npm install knockoutAfter that, the package's main entry is build/output/knockout-latest.js, so a bundler that resolves the package main field will pick up the built library. The package also declares types at build/types/knockout.d.ts, which is what a TypeScript project will read.
If you would rather build the library from source, the README lists the steps. Node.js and Java must be installed on the workstation for the build only.
git clone https://github.com/knockout/knockout.git
cd knockout
npm install
npm run grunt
The README states that the built files then appear in build/output/. To run a single task, the README shows passing it after a double dash.
npm run grunt -- build:debugFor a first real use, the README points new users at the online interactive tutorials at learn.knockoutjs.com and at the examples on the project website. Those are the places to see a view model and its bindings together; the README itself does not include a worked binding example.
Testing and building: what the scripts actually run
The package.json scripts are concrete and worth reading before you adopt the library into a pipeline. The test script chains two others, so the default test run is not a single process.
npm test              # All tests (Node.js + headless Chrome)
npm run test:node     # Node.js non-DOM specs only
npm run test:browser  # Headless Chrome specs only
The comments above are the README's own. The node run executes spec/runner.node.js with a --source flag. The browser run executes spec/runner.puppeteer.js against spec/runner.html, which is why puppeteer is a devDependency. For interactive debugging, the README says to open spec/runner.html in a browser directly.
Note the split: non-DOM specs run under Node, DOM specs run in headless Chrome. If you are extending Knockout with a custom binding, that split tells you where a test belongs. A binding that touches the document cannot be exercised by the node runner.
The build is driven by Grunt, and the devDependencies include grunt, grunt-cli, closure-compiler, puppeteer and typescript. A prepublishOnly script runs grunt, so publishing from the repository rebuilds the output rather than shipping whatever is on disk. That is a small but real safeguard against a stale build/output/ directory reaching npm.
Where Knockout is the wrong tool
The clearest limitation is scope. Knockout binds a view model to markup. It does not give you a router, a component registry, a state container or server-side rendering. A team that needs those will build or import them separately, and the seams between those pieces are theirs to maintain.
The second limitation is that bindings live in HTML attributes. This is the same property that makes Knockout easy to adopt, and it is also the reason a large template becomes hard to reason about. Binding expressions sit in the markup, so the logic that decides what a page shows is spread across files that a JavaScript-only reader will not see. There is no single module you can open to understand a screen.
The build prerequisites are a smaller friction point. Building from source requires Node.js and Java on the workstation, per the README. That is a heavier toolchain than the library itself needs at runtime, and it is only relevant if you build rather than install.
Finally, the repository files do not document a migration path between major versions, and the README does not document rollback. If you are upgrading an application that leans on bindings heavily, the release notes are the source to check, not this page.
Alternatives and the difference in approach
The obvious comparison is with a virtual DOM library such as React. The difference is where the template lives and who owns the DOM. React builds a component tree in JavaScript, renders it to a virtual representation, and diffs that against the previous render to decide which DOM operations to apply. Knockout leaves the DOM where it is and attaches observers to the values the markup reads. In React you describe a tree; in Knockout you annotate existing markup and let observables drive it.
A second comparison is with the two-way binding in Angular. Angular is a full framework: it brings dependency injection, routing, a module system and its own template compiler. Knockout is a library you can add to a page that already exists. If you want the framework, Angular gives you more and asks for more. If you want to keep a server-rendered page and add reactivity, Knockout asks for less.
A third option is to write the DOM updates yourself. For a page with a handful of interactive elements, direct event handlers and text updates are simpler than learning a binding syntax. Knockout starts paying off when the number of interdependent values grows, because the bookkeeping of which node depends on which value is the part you stop writing by hand.
The honest summary: Knockout's approach is markup-first and incremental. Virtual DOM libraries are component-first and total. Neither is better in the abstract; they suit different starting points.
Licence, maintenance and the cost of staying current
The package.json declares the license as MIT, and the README repeats it with a link to the Open Source Initiative page. The repository's LICENSE file is at the top level. MIT is permissive, which in practice means the obligations are attribution and inclusion of the licence text; the specifics depend on how you distribute the software, and that is a question for your own counsel rather than for this article.
On maintenance, the last push to the default branch was on 2026-03-25, and the most recent release listed is v3.5.3 on the same date. The release before that, v3.5.2, is dated 2026-03-09, and v3.5.1 is dated 2019-11-05. That gap between v3.5.1 and v3.5.2 is the number that should shape your upgrade expectations: this is not a library that ships on a frequent cadence, so a fix you are waiting on may sit for a while.
The version in package.json is 3.5.4-pre, which means the repository is ahead of the last tagged release. If you install from npm you get the released version; if you build from source you get something the tags do not describe.
The upgrade cost itself is low in one respect: the runtime has no dependencies, so there is no transitive tree to audit. It is higher in another: because bindings are spread through markup, an upgrade that changes binding behaviour can only be checked by exercising the pages that use them. The test scripts in package.json test the library, not your templates.
Editorial conclusion
Adopt Knockout when you have server-rendered HTML and want a view model to drive it without a build step, and when the binding surface in the documentation covers what you need. Do not adopt it if you want a component framework with routing and state management built in, or if you cannot audit the bindings your templates already use. Before committing, verify the released version you depend on and read the binding documentation for the specific bindings your templates rely on.
Frequently asked questions
What is Knockout in JavaScript?
It is an MVVM library that uses observers to keep a UI in sync with an underlying data model, together with a set of declarative bindings. It is aimed at creating rich, desktop-like interfaces with JavaScript and HTML.
How do I install Knockout?
Released versions can be downloaded from the project website, and Node.js developers can install it from npm with npm install knockout. The package main entry is build/output/knockout-latest.js.
Does Knockout need Node.js or Java at runtime?
No. The README states that Knockout itself has no dependency on Node.js or Java once it is built, and that it works with any server technology or none. Those tools are only needed to build the library from source.
How do I run the Knockout test suite?
The README lists npm test for all tests, npm run test:node for the Node.js non-DOM specs, and npm run test:browser for the headless Chrome specs. For interactive debugging, open spec/runner.html in a browser.
What licence does Knockout use?
The package.json declares the license as MIT, and the README repeats that with a link to the MIT licence page. The LICENSE file sits at the top level of the repository.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/knockout-knockout)Star history chart for your README
[](https://hysenlabs.com/projects/knockout-knockout)Was this useful?