Antidoom: FTPO Training Against Repetition Loops in Reasoning Models
Antidoom generates and trains targeted preference data for reducing model repetition loops (doom loops).
At a glance
- What is it?
- Antidoom is a narrow Python tool from Liquid4All that samples model completions, finds where a repeated span starts, marks the first looping token as rejected, and trains a LoRA adapter with Final Token Preference Optimization. It requires a CUDA or ROCm GPU runtime and a prompt-only dataset.
- Who is it for?
- Antidoom is for teams fine-tuning a reasoning checkpoint that reliably falls into repetition loops and who can supply at least 15k prompts plus a CUDA or ROCm GPU. It is not for general instruction tuning, alignment work, or anyone without the hardware: vLLM and PyTorch are hard dependencies, and the README states the pinned uv.lock is CUDA-only.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 19, 2026, and from our analysis. They are not legal advice.
Star history
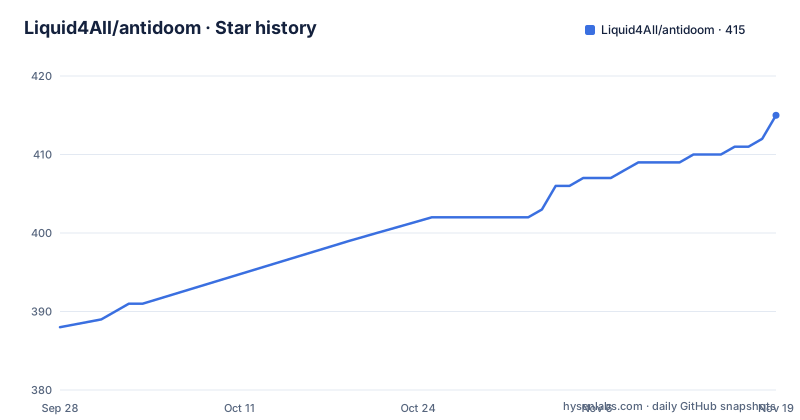
- Liquid4All/antidoom415 ★ · +27
| Repository | 2026-09-28 | 2026-11-19 |
|---|---|---|
| Liquid4All/antidoom | 388 | 415 |
27 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Antidoom Actually Fixes
Antidoom targets one failure mode: runaway repetition during reasoning. The README describes doom loops as the product of three forces lining up. Overtrained tokens such as Wait, So, But and Alternatively become unusually attractive after heavy synthetic reasoning training, so when the model is uncertain they dominate the next-token distribution without advancing the reasoning. Once a short sequence appears, the prior context makes that sequence more likely to appear again, and across repeated turns the probability of each token can climb toward certainty. Low-temperature sampling removes the escape route, because the model keeps picking the highest-probability continuation.
The audience is correspondingly narrow. This is a tool for someone who already has a checkpoint that loops, a GPU runtime that can host vLLM, and a supply of prompts. It is not an alignment toolkit and not a general fine-tuning framework. The README is explicit that the default dataset excludes gold answers, rationales, hidden tests, verifier targets and answer labels, which tells you the training signal is local rather than answer-level. If your problem is that the model reasons badly, Antidoom has nothing to say about it.
The FTPO Pair Pipeline, Step by Step
The mechanism adapts the single-token preference idea from Antislop and its auto-antislop implementation to repetition specifically. For each prompt, Antidoom generates a completion and scans it for inner repetition. When a loop is found, it refines the boundary in token space so the rejected token is the first readable token of the repeated segment.
Each FTPO row then holds four things: a prompt/context prefix ending immediately before the rejected token, one rejected token (the loop starter), one or more chosen tokens sampled from filtered alternatives at that same position, and metadata about the source prompt, generated completion and detected loop. The training step regularises overrepresented rejected and chosen tokens so the adapter learns a broad anti-loop preference instead of simply suppressing one word.
That last point is the design choice worth noticing. A naive version of this would teach the model never to emit the token Wait. Antidoom instead tries to spread the correction across the rejected-token distribution, which is why rejected_regularisation_strength exists as a knob and why the README warns that an unbalanced generated set can produce poor training outcomes. The prefix ends before the rejected token, so the model never sees the loop it is being taught to avoid. It only sees the position where the loop began.
Installing Antidoom and Running a First Job
The README's prerequisites are a supported GPU runtime for PyTorch and vLLM. NVIDIA/CUDA is the default path and uses the pinned uv.lock with configs/default.yaml. AMD/ROCm users on Instinct MI-series cards must not use the default uv.lock, because the README states it is CUDA-only; they create a separate ROCm environment and run with configs/default_amd.yaml, which adds attention_backend: TRITON_ATTN and optim: adamw_torch overrides.
The clone and dependency step is three commands. uv sync resolves the lock file, so expect a large download of torch and vllm rather than a quick install.
git clone https://github.com/Liquid4All/antidoom
cd antidoom
uv sync
After that, edit configs/default.yaml and set model_name to the checkpoint you want to antidoom. The default config reads prompts from LiquidAI/antidoom-mix-v1.0, generates FTPO pairs, trains a LoRA adapter, and merges it. The full generate-and-train flow is one invocation; the README's example passes a run directory, a temperature of 0.01, and an explicit model name.
uv run antidoom -c configs/default.yaml -r runs/antidoom1 \
  --temp 0.01 \
  --model-name LiquidAI/LFM2.5-1.2B-Base
According to the README, this writes generated completions and FTPO pairs to runs/antidoom1/, trains on the pair file, and writes the adapter plus merged model under the same run directory. The package also installs a second console script, doomloop, which points at the same antidoom.cli:main entry point.
What to Change Before You Train
The most common fields are listed in the README: model_name, generation.hf_dataset or generation.input_jsonl, generation.prompt_field, generation.target_pairs, generation.temperature or generation.temperatures, train.max_train_examples, train.output_dir and train.merged_output_dir. One parsing rule deserves attention because it is easy to get wrong. prompt_field is authoritative: generation reads that column and parses the value by shape. A string is a plain user prompt, an OpenAI-style list of role/content objects is used as chat messages, and a ShareGPT-style list of from/value objects is converted to chat messages. The parser does not infer prompt format from the column name, so a column called messages containing plain strings will be treated as a plain prompt.
The hyperparameter guidance is unusually specific, and it is where most of the practical risk sits. max_train_examples should be set below the number of generated preference rows; the README suggests roughly 12k rows from a 15k-20k generated set and states a usage hint of at most 70% of the actual preference row count. Learning rate has a starting range of 0.00001 to 0.00002 when training on about 12k samples. The README warns plainly that the trainer can undertrain or overtrain, and that an overtrained model can degrade and produce more doom loops. early_stopping_chosen_win stops training when chosen_win, the share of samples where the chosen token beats the rejected one, exceeds the configured value; the README suggests trying 0.4, notes that 0.15-0.3 usually shows a strong reduction in doom looping, and says training past 0.5 may be overtraining while adding that more ablations are needed. Treat that last clause as the authors marking their own uncertainty.
Where Antidoom Is the Wrong Tool
The clearest limitation is hardware. PyTorch and vLLM are declared dependencies in pyproject.toml, and the README frames a supported GPU runtime as a prerequisite rather than a recommendation. There is no documented CPU path, and the AMD route is not a flag flip: it requires a separate environment because the pinned lock file is CUDA-only.
The second limitation is data volume. The README's rule of thumb starts at 15k prompts to reach roughly 15k-20k preference rows, and the number of samples you actually get depends on how many prompts you have, how many temperature passes you run, and how doom-loopy the checkpoint is. A model that rarely loops will not yield enough pairs. That is a chicken-and-egg problem: you need a looping model to build the dataset that stops the looping.
The third is scope. Because training is on a single-token local preference, Antidoom does nothing for a model that is verbose, factually wrong, or poorly formatted but does not repeat. The repository has no published GitHub releases, so there is no published version history to fall back on. The last push to the repository was on 2026-07-07.
How Antidoom Differs from Auto-Antislop
The README positions Antidoom as an adaptation of Antislop and the auto-antislop implementation, so the honest comparison is with its own ancestor. Auto-antislop applies single-token preference training to slop broadly, meaning the filler and stock phrasing that models overproduce. Antidoom keeps the training machinery and narrows the target to runaway repetition during reasoning.
That narrowing changes the data collection. Antidoom has to elicit loops before it can label them, which is why generation.target_pairs and generation.temperatures exist as separate controls and why the README describes the generation stage as an attempt to elicit doom loops. A slop-reduction pipeline can harvest its negatives from ordinary output; a loop-reduction pipeline has to provoke the failure first. The boundary refinement in token space is also specific to this problem, since the rejected token must be the first readable token of the repeated segment rather than any disfavoured word. If your complaint is stylistic rather than structural repetition, the broader Antislop approach maps to the problem better.
Licence, Maintenance and Upgrade Cost
The repository is Apache-2.0, and the README notes that dataset build scripts and license notes live in datasets/, which means the prompt mixture carries its own terms separate from the code licence. Apache-2.0 covers the source; it says nothing about the LiquidAI/antidoom-mix-v1.0 dataset or about any base checkpoint you point model_name at. Check those separately before shipping a merged model.
On maintenance, the repository is not archived and the last push was on 2026-07-07. The repository has no published GitHub releases, so there is no tagged version to pin beyond the version field of 0.1.0 in pyproject.toml. Upgrading is a real cost here: the project pins uv.lock and depends on vllm, torch, transformers, trl and peft, all of which move quickly. The AMD instructions show what that costs in practice, because the CUDA-only lock file forces a parallel environment rather than a configuration change. Budget for re-validating generation output after any dependency bump, since a change in sampling behaviour changes which loops get detected.
Editorial conclusion
Antidoom is for teams fine-tuning a reasoning checkpoint that reliably falls into repetition loops and who can supply at least 15k prompts plus a CUDA or ROCm GPU. It is not for general instruction tuning, alignment work, or anyone without the hardware: vLLM and PyTorch are hard dependencies, and the README states the pinned uv.lock is CUDA-only. Before committing, verify three things on your own checkpoint: that the default dataset LiquidAI/antidoom-mix-v1.0 matches your domain, that your chosen model_name actually loops at the generation temperature you configure, and that max_train_examples lands at or below 70% of the preference rows your run produces, since the README ties rejected_regularisation_strength to that ratio.
Frequently asked questions
What is an example of a doom loop?
The README describes a doom loop as a short sequence that, once it appears, becomes more likely to appear again because of the prior context, with each token's probability climbing toward certainty across repeated turns. It names common reasoning tokens such as Wait, So, But and Alternatively as the ones that tend to start these loops after heavy synthetic reasoning training.
What is a doom loop economy?
The repository does not address this. Antidoom is a training tool for repetition loops in language models, and the README uses the term only in that technical sense.
How do I install Antidoom?
Clone the repository, change into the directory and run uv sync. The README states that a supported GPU runtime for PyTorch and vLLM is required, with NVIDIA/CUDA as the default path using the pinned uv.lock; AMD/ROCm users must build a separate environment and use configs/default_amd.yaml instead.
How many preference rows does Antidoom need before training?
The README suggests starting with at least 15k prompts and aiming to produce roughly 15k-20k preference rows, then setting max_train_examples below that count, for example 12k rows. It gives a usage hint of at most 70% of the actual number of preference rows, so that rejected_regularisation_strength has room to shave off overrepresented rejected tokens.
What learning rate should I use with Antidoom?
The README gives a starting range of 0.00001 to 0.00002 when training on about 12k samples. It warns that the trainer can undertrain or overtrain, that an overtrained model can degrade and produce more doom loops, and that early stopping is useful to avoid overtraining.
Which dataset does Antidoom train on by default?
The default config reads prompts from LiquidAI/antidoom-mix-v1.0, described in the README as a prompt-only ShareGPT mixture built for this pipeline. It intentionally excludes gold answers, rationales, hidden tests, verifier targets and answer labels.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/liquid4all-antidoom)Star history chart for your README
[](https://hysenlabs.com/projects/liquid4all-antidoom)Was this useful?