Mesh LLM: pooling GPUs across machines behind one OpenAI-compatible API
Distributed AI/LLM for the people. Share compute privately or publicly to power your agents and chat.
At a glance
- What is it?
- Mesh LLM is a Rust-based distributed inference system that turns a group of machines into a single OpenAI-compatible endpoint. Its Skippy stage-splitting approach for oversized models and its invite-token private meshes are the features most worth evaluating.
- Who is it for?
- Adopt Mesh LLM if you have several machines with idle GPUs and want to serve models larger than any single box can hold, or if you need a private, invite-token mesh for agent workloads. Skip it if you require stable semantics for the experimental model:"mesh" fan-out, or if you cannot tolerate the risk of a young project with release candidates as the latest tags.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
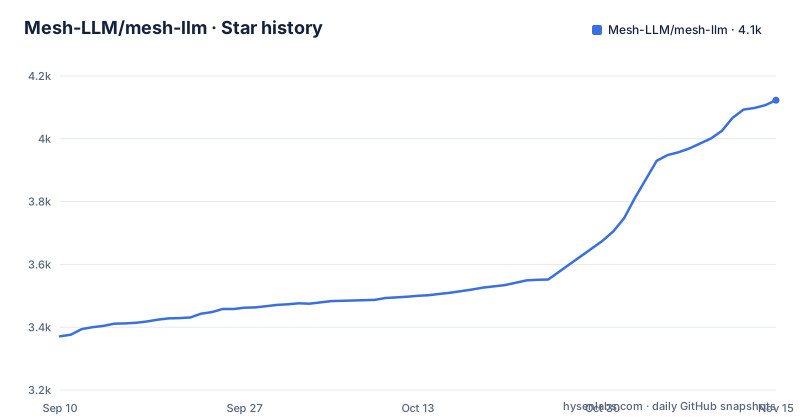
- Mesh-LLM/mesh-llm4,123 ★ · +752
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| Mesh-LLM/mesh-llm | 3.4k | 4.1k |
752 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Mesh LLM actually does
The project is written in Rust, which matters for the transport layer. It uses QUIC for end-to-end encryption between nodes, including inference requests, responses, and split-model activations. Iroh relays forward encrypted packets without reading their payload. That design choice means the public mesh can route traffic through relays that cannot inspect the content, which is a meaningful privacy property for a public network.
The mesh routing mechanism
Public discovery uses Nostr, a decentralized protocol, to advertise published meshes. Private meshes, by contrast, are invite-token based. That distinction is important for security: a public mesh is discoverable, but a private one requires an explicit token to join. The README does not detail how tokens are issued or rotated, so an operator considering a private mesh should look at docs/MESHES.md before trusting it for sensitive workloads.
Skippy stage splits for oversized models
This is a real departure from naive sharding. Instead of splitting layers arbitrarily across machines and hoping the network keeps up, the coordinator plans contiguous ranges and stages the startup sequence. The README warns that the complete model must fit within detected local capacity in --local-model-only mode, and it never falls back to distributed serving. That means if you point it at a model that does not fit, startup fails rather than silently degrading. That is a clean failure mode, but it also means you need to know your hardware capacity before you run.
Getting it running: commands and config
Server deployments can add --headless to hide the web UI while keeping the management API on the --console port. There is also a client-only mode: mesh-llm client --auto runs an API-only client. The CLI surface is broad, and the README points to docs/CLI.md for every command and switch.
The experimental mixture-of-agents gateway
This is a useful capability for comparing model outputs, but the warning is warranted. If you need stable semantics for an agent workflow, using a specific model id is the safer path. The fan-out approach also multiplies cost and latency, since every model in the mesh processes every request. The README does not state how many models are typically in a public mesh, so the practical latency impact is unknown. Treat this as a preview, not a production feature.
Limitations and wrong-tool cases
The project is also wrong for users who need a managed API. There is no cloud offering mentioned; you run the nodes yourself. The public mesh exists, but joining it means your requests traverse relays you do not control. Even with QUIC encryption, you are trusting the mesh operators to not drop or delay traffic. For a private mesh, you must handle the invite tokens and node maintenance yourself.
Alternatives and how they differ
Another alternative is llama.cpp's RPC mode, which can offload layers to remote machines over TCP. That is a simpler approach: you manually assign layer ranges to specific servers. Mesh LLM automates the planning and routing, and it adds the OpenAI-compatible API layer plus the mesh discovery. The trade-off is complexity: Mesh LLM has a control plane, discovery, and a web console, whereas llama.cpp RPC is a lower-level tool you script yourself. If you want a quick way to spread a model across two known machines, llama.cpp RPC may be simpler. If you want a self-organizing pool with a unified API, Mesh LLM is the more complete package.
Maintenance, licensing, and upgrade cost
Upgrade cost is not documented in the README beyond the install and uninstall commands. There is no migration guide mentioned for moving between versions. The presence of a mesh-llm-control/1 lane with explicit endpoint bootstrap suggests the developers are thinking about version compatibility, but the README does not promise that a node running v0.76.0-rc9 can talk to a node running v0.75.0. If you run a private mesh with multiple nodes, you will need to coordinate upgrades across all of them. The uninstall command preserving ~/.mesh-llm is a plus, but it also means stale config could linger if you change identity or mesh settings. Before adopting, read docs/USAGE.md and docs/CLI.md to understand the full operational surface, because the README only scratches the surface.
Editorial conclusion
Adopt Mesh LLM if you have several machines with idle GPUs and want to serve models larger than any single box can hold, or if you need a private, invite-token mesh for agent workloads. Skip it if you require stable semantics for the experimental model:"mesh" fan-out, or if you cannot tolerate the risk of a young project with release candidates as the latest tags. Before deploying, verify that your GGUF files are not symlinks in --local-model-only mode, confirm that your model fits within --max-vram if you set it, and test the QUIC transport on your network, since the README does not specify how it behaves under NAT or firewall restrictions.
Frequently asked questions
what is mesh llm
A Rust workspace that pools GPUs and memory across machines and exposes the result as one OpenAI-compatible API at http://localhost:9337/v1. Start one node and add more later, and the mesh decides whether a model runs locally, routes to a peer, or uses Skippy stage splits for models too large for one machine.
What is an LLM mesh?
In this project, a set of machines that each expose the same `/v1` API and route requests by the `model` field to whichever peer can serve that model. Peer traffic is QUIC with end-to-end encryption, Iroh relays forward encrypted packets without reading them, published meshes advertise through Nostr, and private meshes use invite tokens.
Does mesh-llm join the public mesh by default?
Yes, if you run `mesh-llm serve --auto`, which chooses a backend flavor, downloads a suitable model if needed, joins the best discovered public mesh, starts the API on port 9337 and the console on 3131. For a private mesh you pass an explicit model, or an invite token with `--join`.
What ports does mesh-llm use?
Port 9337 for the OpenAI-compatible API and port 3131 for the web console. The API defaults to 127.0.0.1:9337, with `--port` and `--listen-all` changing that, and `--headless` hides the web UI while keeping the management API on the console port.
Is --local-model-only suitable for production?
The README says it is not. It labels the flag a debugging and development endpoint that bypasses mesh networking entirely, and states that the supported production path for OpenAI clients, including tool calls, is the regular mesh inference port with its host-runtime normalizer.
How do I uninstall mesh-llm?
With a two-step form: `mesh-llm uninstall --dry-run` previews the cleanup, and `--yes` carries it out. Uninstall preserves the `~/.mesh-llm` configuration and identity data unless you explicitly pass `--purge-config`.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mesh-llm-mesh-llm)Star history chart for your README
[](https://hysenlabs.com/projects/mesh-llm-mesh-llm)Was this useful?