VibeVoice: Microsoft's 7.5 Hz Tokenizer Family for Long-Form Speech
GitHub describes it as Open-Source Frontier Voice AI. The repository metadata lists Python as its primary language. The metadata lists the MIT license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- VibeVoice is a family of open-source TTS and ASR models built around continuous speech tokenizers at 7.5 Hz. The ASR model handles 60-minute audio in one pass; the original long-form VibeVoice-TTS code was removed after misuse, while a separate real-time TTS model is available.
- Who is it for?
- Adopt VibeVoice if you need long-form ASR with speaker labels and timestamps in a single pass, or real-time TTS with streaming input, and you can work with Python and Hugging Face tooling. Do not adopt it if you need the original VibeVoice-TTS multi-speaker synthesis, because that code has been removed from the repository.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 37 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
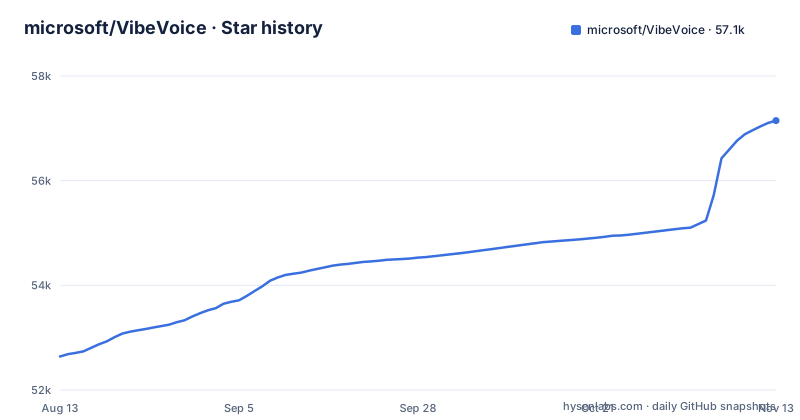
- microsoft/VibeVoice57,147 ★ · +4,507
| Repository | 2026-08-13 | 2026-11-13 |
|---|---|---|
| microsoft/VibeVoice | 52.6k | 57.1k |
4,507 Stars in the last 92 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What VibeVoice Actually Solves
VibeVoice targets two pain points in speech AI. For transcription, conventional ASR systems slice audio into short chunks, which loses global context and makes speaker tracking inconsistent across a long recording. VibeVoice-ASR accepts up to 60 minutes of continuous audio in a single pass within a 64K token length, producing structured output with who spoke, when, and what was said. For synthesis, VibeVoice-Realtime-0.5B provides streaming text-to-speech, which matters for live applications where you cannot wait for a full paragraph before hearing audio. The intended users are researchers and engineers building voice applications that need long-context understanding or low-latency generation. The README positions it as a research framework, not a polished product, so expect rough edges.
The 7.5 Hz Tokenizer and Next-Token Diffusion
The core mechanism is a continuous speech tokenizer that operates at an ultra-low frame rate of 7.5 Hz. This is far lower than typical speech tokenizers, which often run at 50 Hz or higher. The low frame rate is what allows the model to process 60 minutes of audio within a 64K token window, because fewer tokens per second means more seconds fit in the context. The README explains that VibeVoice uses a next-token diffusion framework: an LLM understands the textual context and dialogue flow, then a diffusion head generates high-fidelity acoustic details. This is a two-stage design, where the language model handles semantics and the diffusion head handles acoustics. The trade-off is that the tokenizer must preserve enough audio fidelity at 7.5 Hz to make the diffusion head's job feasible. The documentation claims this boosts computational efficiency for long sequences, which is plausible given the reduced token count.
VibeVoice-ASR: Long-Form Transcription with Hotwords
The ASR model is the most developed component. It handles 60-minute audio in a single pass, which is a specific design choice to maintain speaker and semantic coherence across the entire hour. It jointly performs ASR, diarization, and timestamping, so you get a structured transcript with speaker labels and timecodes. A notable feature is customized hotwords: you can provide domain-specific terms, names, or background info to guide recognition. This is useful for technical jargon or rare proper nouns that generic models often mangle. The model is natively multilingual, supporting over 50 languages, and is integrated into Hugging Face Transformers and Azure AI Foundry Labs. For faster inference, vLLM is supported. The finetuning code is available in the repository, which suggests you can adapt the model to your domain.
VibeVoice-Realtime-0.5B and the Missing TTS
The real-time TTS model is a 0.5B parameter model that supports streaming text input and long-form speech generation. It also includes experimental speakers: multilingual voices in nine languages (German, French, Italian, Japanese, Korean, Dutch, Polish, Portuguese, Spanish) and 11 distinct English style voices. The README notes these are experimental and more will be added. However, the original VibeVoice-TTS, a long-form multi-speaker model that could synthesize up to 90 minutes with four speakers, has been removed from the repository. The news entry from September 2025 states that after release, instances of misuse were discovered, and Microsoft removed the code. The project still documents the long-form model and links its 1.5B weights, but its installation and usage instructions are disabled. Verify availability and terms before planning around that model. The real-time model remains, but it is a different, smaller offering. This removal shapes the project's identity: it is not a complete TTS suite, but a curated set of models with guardrails.
Getting It Running: Commands and Config
The README points to Colab notebooks for both real-time TTS and ASR, which is the fastest way to try the models without local setup. For local use, the ASR model is available through Hugging Face Transformers, so you can load it with standard Python code. The repository includes documentation files, such as docs/vibevoice-asr.md and docs/vibevoice-realtime-0.5b.md, which likely contain installation instructions and API usage. For ASR, vLLM inference is supported. For the edge CPU version, there is a separate repository, VibeASR.cpp, which uses heterogeneous quantization (I8_S + I2_S) to compress the model from 4.62 GB to 1.58 GB and runs real-time on 3+ CPU threads without a GPU.
Limitations and Failure Modes
The most obvious limitation is the removal of VibeVoice-TTS. If you need multi-speaker synthesis for long-form content, this project cannot provide it. Another limitation is the 64K token context for ASR: while it handles 60 minutes, that is the upper bound, and longer audio would require chunking, which defeats the purpose. The real-time TTS model is only 0.5B, so the voice quality may be lower than larger models, and the experimental speakers are explicitly marked as exploratory, meaning they may not be production-ready. The ASR model is 7B, which is large and may require significant GPU memory for inference or finetuning. Finally, the project is research-oriented, so the code may not be as polished or stable as a commercial product. The news entries show rapid changes, including the TTS removal, so the API may shift.
Alternatives and Approach Differences
For long-form ASR, a common alternative is to use a chunked pipeline with a separate diarization model, such as Whisper for transcription and pyannote for speaker labels. The difference in approach is that VibeVoice does everything in one pass, preserving global context, while a chunked pipeline loses that context and may introduce errors at chunk boundaries. Whisper is a strong general-purpose ASR, but it does not natively produce speaker labels or handle 60-minute audio in a single pass. For TTS, alternatives like Coqui TTS or Piper offer lightweight, on-device synthesis. VibeVoice's real-time model is designed for streaming, which is a specific use case. The choice depends on whether you need the integrated diarization and hotwords, or if you can accept the complexity of a multi-model pipeline.
Maintenance, Licensing, and Upgrade Cost
The project is under the MIT license, which is permissive and allows commercial use with attribution. The repository is not archived, and the news entries show active development, including a release in July 2026 for the edge ASR engine. However, the repository publishes no formal releases, so the release cadence is unclear. The removal of TTS code is a maintenance signal: the project may change direction or remove features without notice. Upgrade cost is moderate: if you adopt VibeVoice-ASR, you will need to track changes to the model on Hugging Face, as the Transformers integration may change. The VibeASR.cpp engine is a separate repository, so you would need to maintain that dependency separately. The finetuning code is available, but upgrading a finetuned model to a new base model would require re-running finetuning. Given the research nature, expect to invest time in reading docs and adapting to API changes.
Editorial conclusion
Adopt VibeVoice if you need long-form ASR with speaker labels and timestamps in a single pass, or real-time TTS with streaming input, and you can work with Python and Hugging Face tooling. Do not adopt it if you need the original VibeVoice-TTS multi-speaker synthesis, because that code has been removed from the repository. Before committing, verify the exact model card on Hugging Face for the ASR language list and the real-time TTS speaker set, and check the finetuning script for your hardware, since the 7B ASR model likely requires substantial GPU memory. The project is research-grade, under MIT license, but the removal of TTS code is a clear signal that the maintainers prioritize responsible use over feature completeness.
Frequently asked questions
Is Vibe voice free?
The repository is MIT licensed and every model in the table has a Hugging Face weight link. Trying the models goes through a Playground for VibeVoice-ASR, a Colab notebook for VibeVoice-Realtime-0.5B, and a demo folder of Python scripts, so the cost of trying it is hardware and setup rather than a license.
What is the Microsoft Vibe voice model?
VibeVoice is a family of open-source voice AI models covering both text-to-speech and automatic speech recognition. It uses continuous acoustic and semantic speech tokenizers at a 7.5 Hz frame rate and a next-token diffusion framework in which a Large Language Model handles textual context and dialogue flow while a diffusion head generates the acoustic detail.
how to install vibevoice locally
Concrete starting points are pyproject.toml, which declares the package name vibevoice at version 1.0.0 with requires-python >=3.10, and the docs/ files for the model you want. Weights are fetched separately through the Hugging Face links in the model table, and the runnable examples are demo/vibevoice_asr_inference_from_file.py and demo/vibevoice_realtime_colab.ipynb.
how to use vibevoice asr
VibeVoice-ASR handles 60-minute long-form audio in a single pass and returns structured transcriptions containing Who (Speaker), When (Timestamps), and What (Content), with support for User-Customized Context. The project documents a vLLM path in docs/vibevoice-vllm-asr.md, a finetuning recipe in finetuning-asr/README.md, and a streaming variant that emits text once per chunk in docs/vibevoice-asr-streaming.md.
how to use vibevoice in comfyui
No ComfyUI integration is listed among the repository's top-level entries: .gitignore, CONTRIBUTING.md, Figures/, LICENSE, README.md, SECURITY.md, demo/, docs/, finetuning-asr/, pyproject.toml, tests/, vibevoice/, and vllm_plugin/. The demo directory holds Python inference scripts, a Gradio demo, a FastAPI streaming demo, a Colab notebook, voice files, and a web directory rather than node definitions.
how to use vibevoice 7b
VibeVoice-ASR-7B is the long-form recognition checkpoint, listed in the model table with a Hugging Face link and a Playground as its quick try. It is the checkpoint that carries the more than 50 language claim, while the streaming model released 2026-09-03 names 10, so language coverage is the deciding difference between them.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/microsoft-vibevoice)Star history chart for your README
[](https://hysenlabs.com/projects/microsoft-vibevoice)Was this useful?