mihang123/mom-index: a sentiment framework for Chinese retail investor chatter
Mom Index: a contrarian indicator tracking the investment sentiment of novice and stay-at-home-mom investors. When aunties at the vegetable market are all talking about stocks, it's time to exit.
At a glance
- What is it?
- Mom Index (宝妈指数) is a Python pipeline that scores Chinese social platform discussion for novice-investor heat and emotion extremes. The public repository is a framework release: real data flow, demo data, v0.1 rules.
- Who is it for?
- Adopt it if you want a readable, MIT-licensed skeleton for a behavioural-finance sentiment pipeline and you already have a lawful data source and your own calibration. Do not adopt it if you need a working live index or a validated trading signal: the README states the weights are a v0.1 baseline, the data is synthetic, and the private strategy, prompts and calibration are not in the repository.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 85 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
Star history
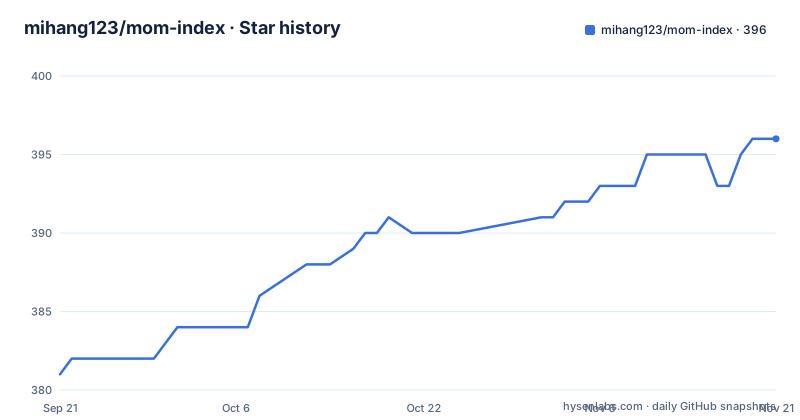
- mihang123/mom-index396 ★ · +15
| Repository | 2026-09-21 | 2026-11-21 |
|---|---|---|
| mihang123/mom-index | 381 | 396 |
15 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem: separating novice chatter from informed discussion
Retail sentiment tools usually assume every post carries the same weight. Mom Index starts from a narrower premise, stated in its own description: when people with no investing background start talking about stocks, that crowd behaviour is itself the signal. The README frames the output as a research observation metric, not a trading instruction, and the index rises when discussion concentrates and emotion becomes extreme.
The target user is not a discretionary trader. It is someone doing behavioural-finance research or building a demo who needs a Chinese-language text pipeline with visible rules. The README says the rules, weights and sample data are for demonstration, and that real use should combine your own research goal, data quality and backtest results. That framing matters: the repository is honest about being a starting point.
How the pipeline scores text: four signal classes and a fixed-weight index
The data flow is collection, analysis, index, output. pipeline.py drives it. Collectors produce posts with a unified field set; analyzer/llm_analyzer.py classifies text; analyzer/index_calculator.py turns the classifications into a number; the frontend reads the result.
The classifier sorts signals into four groups. Identity and knowledge-seeking signals, meaning posts from people who present as newcomers asking for help. Chase, panic and decision-dependency signals. Buy, sell and wait intent. And reverse signals such as professional terminology, risk awareness and a long-term view, which push the index down.
The README gives the v0.1 formula as novice discussion share at 40 percent, novice signal strength at 25 percent, emotion extremity at 20 percent and signal purity at 15 percent. The name llm_analyzer.py is historical: the README calls the shipped component a v0.1 rule-based analyser, so no model call is described for the public version. The README also states the weights are a readable baseline and suggests adding semantic models, confidence estimation, debiasing, time decay and historical backtesting.
Installing Mom Index and running the demo pipeline
The README gives a PowerShell quick start on Windows. Create a virtual environment, activate it, install the two pinned dependencies, run the pipeline, then start the local dashboard server on port 8765.
py -3 -m venv .venv
.\.venv\Scripts\Activate.ps1
pip install -r requirements.txt

# 运行示例流程
py -3 pipeline.py

# 启动看板
py -3 frontend/server.py 8765
requirements.txt pins requests to the 2.31 line and playwright to the 1.40 line, both below the next major version. Playwright normally needs a browser download step, and the README does not document one, so expect to check that yourself if the collector path is exercised.
After the pipeline writes output, the dashboard is served locally. The README says to open http://localhost:8765/dashboard.html. The frontend directory ships chart.umd.min.js locally, and the README explains this is to avoid CDN fluctuation, so the page should render without network access to a chart CDN.
Credentials are optional and live in .env.example, which lists XHS_API_KEY and XHS_API_URL with empty values. That file corresponds to collectors/xhs_collector.py, described as an optional data source interface. The README warns not to commit cookies, login state, browser profiles, API keys, tokens, .env files, unauthorised raw posts or user IDs.
What the public release deliberately leaves out
The README has a section explaining why the framework is what is public. It states the release shows the full data flow and extension interfaces but excludes the maintainer's private strategy, model prompts, production calibration logic and raw social platform data. The data directory holds desensitised synthetic samples that do not correspond to real users. Collectors are interfaces plus example implementations, and the README puts the burden on the user to confirm platform terms and data authorisation.
That is an unusual amount of disclosure about what is missing, and it should shape expectations. You cannot reproduce a published index value from this repository, because no published value is tied to this code. The index formula is described as a research starting point, not the private version, with no guarantee of investment validity.
The collectors directory also contains anti_detection.py, described in the structure listing as historical experiment code. Nothing in the README suggests it is maintained or that it should be used. Treat it as a leftover rather than a feature, and check the terms of any platform before writing a collector against it.
Where this framework is the wrong tool
The first failure mode is expecting a live signal. The shipped data is synthetic, the analyser is rule-based, and the weights are fixed. An index computed from demo samples tells you the code path runs, nothing about a market.
The second is language and platform scope. The signals are defined for Chinese-language posts from retail and novice investors on Chinese social platforms. The keyword rules in the public analyser will not transfer to English-language discussion without rewriting the classifier, and the README suggests exactly that as an extension path: replace analyzer/llm_analyzer.py with your own rules or model.
The third is legal and ethical. The README tells users to confirm platform terms and data authorisation themselves, and warns against committing unauthorised raw posts, comments or user IDs. A sentiment pipeline that scrapes login-gated content is a compliance problem before it is an engineering one, and the repository provides no authorisation mechanism.
Finally, the index is a single scalar built from four weighted components. It cannot tell you which component moved, so diagnosing a spike means reading the intermediate classifications, which the README does not describe as an exposed output.
Dad Index and the difference in approach
The README links one related project: 宝爸指数, Dad Index, at github.com/mihang123/dad-index. The README describes it as a companion framework aimed at experienced-investor discussion.
That is the meaningful contrast. Mom Index scores novice and knowledge-seeking signals and treats professional terminology, risk awareness and long-term perspective as reverse signals that lower the index. Dad Index is oriented toward experienced investors, so the same phrases that suppress the Mom Index would plausibly be the subject of interest rather than noise. If your research question is about informed commentary, the novice-weighted formula is the wrong instrument, and the sibling project is the one the repository points at.
If neither fits, the alternative is to build the classifier yourself on the same skeleton. The README's extension list is the honest path: new collectors emitting unified post fields, a replacement analyser, calibration and decay in index_calculator.py, and an offline backtest with error evaluation.
Maintenance, licence and upgrade cost
The repository is not archived, and the last push was on 2026-08-29. The repository has no published GitHub releases, so there is no versioned artefact to pin against; the default branch is master and the README labels the code Framework v0.1.
The licence is MIT, which permits commercial and private use with the copyright notice and permission notice retained. This is not legal advice, and the more consequential question is data, not code: the MIT grant covers the repository, not any social platform content you feed into it.
Upgrade cost is concentrated in the analyser. Because the public analyser is rule-based and the weights are hard-coded in index_calculator.py, any change in signal definition means editing code rather than configuration. The dependency range is narrow, requests below 3 and playwright below 2, which limits breakage but also means a future major release of either package will require a deliberate bump. There is no migration guide in the README, and the repository has no published GitHub releases.
Editorial conclusion
Adopt it if you want a readable, MIT-licensed skeleton for a behavioural-finance sentiment pipeline and you already have a lawful data source and your own calibration. Do not adopt it if you need a working live index or a validated trading signal: the README states the weights are a v0.1 baseline, the data is synthetic, and the private strategy, prompts and calibration are not in the repository. Before building on it, check index_calculator.py against the four signal categories in the README, confirm that collectors/guba_collector.py matches the platform terms you plan to operate under, and read .env.example to see which credentials the optional collector expects.
Frequently asked questions
What is the Mom Index (宝妈指数)?
It is a behavioural-finance observation metric for Chinese social platform discussion, built to track retail and novice investor heat, emotion extremes and buy or sell intent. The README states a higher index means discussion is more concentrated and emotion more extreme, and that it is a research metric rather than a trading instruction.
Is there a type D mom in the Mom Index?
The repository does not define mom types or any A to D classification. Its four categories are text signal classes: identity and knowledge-seeking signals, chase and panic signals, buy and sell intent, and reverse signals such as professional terminology and risk awareness.
What are MoM metrics in the Mom Index?
The README does not use month-over-month metrics. The index is a weighted composite of novice discussion share at 40 percent, novice signal strength at 25 percent, emotion extremity at 20 percent and signal purity at 15 percent, and the README says those v0.1 weights are a baseline to replace.
What is a .mom website?
The repository does not describe a .mom website or any hosted service. Mom Index is a local Python project: pipeline.py produces output and frontend/server.py serves dashboard.html on port 8765 from your own machine.
What are the best websites for mothers?
This repository does not list or review websites for mothers. It is a behavioural-finance analysis framework that processes Chinese social platform posts about investing, and the README states it is for research, software demonstration and science communication, not consumer recommendations.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mihang123-mom-index)Star history chart for your README
[](https://hysenlabs.com/projects/mihang123-mom-index)Was this useful?