laya-mlx: typed decisions on Apple Silicon without a token decoder
Native MLX runtime for Laya typed decision models — 7–14 ms short decisions on M3 Max. No text generation, PyTorch, or cloud API.
At a glance
- What is it?
- An independent MLX port of the Laya decision models that returns probabilities over options, rubric levels or a truth value instead of generating text. It runs on Apple Silicon only, and the README's latency figures come from a one-question API benchmark rather than the Snake demo loop.
- Who is it for?
- Adopt laya-mlx if you need a bounded decision (a department, a rubric level, a yes/no probability) on an Apple Silicon machine and you want it local, without a PyTorch or Transformers runtime. Skip it if you need generated text, if you are not on arm64 macOS, or if you need to fine-tune: the README states that RLCD training and fine-tuning remain in the upstream project, and the port covers inference and conversion only.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 17 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
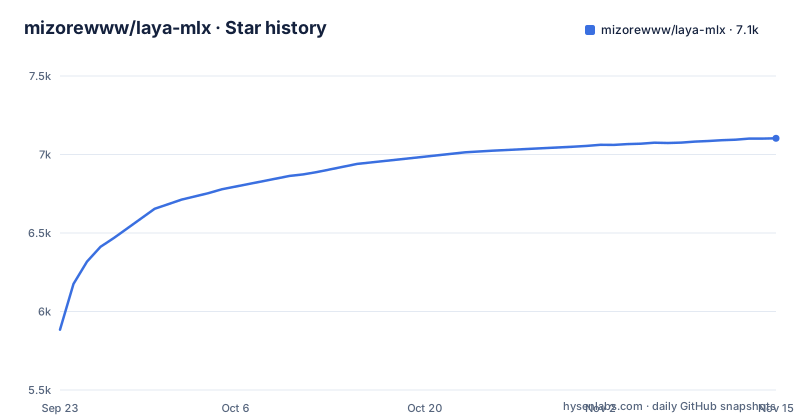
- mizorewww/laya-mlx7,103 ★ · +1,219
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| mizorewww/laya-mlx | 5.9k | 7.1k |
1,219 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem laya-mlx solves: a choice, not a paragraph
Most local model stacks are built to produce text. A routing rule, a rubric score or a yes/no gate does not need text. It needs a distribution over a small set of named outcomes, and it needs that distribution fast enough to sit inside a request handler. laya-mlx targets exactly that gap. The README says Laya answers constrained questions with calibrated probabilities from one bidirectional forward pass, and that it generates no tokens and returns no JSON to parse.
The audience is narrow on purpose. You need an Apple Silicon Mac, Python 3.11 or newer, and macOS 14 or newer. If your deployment target is a Linux container, this project is not for you, and the dependency list says so directly: the mlx requirement is marked with sys_platform == 'darwin' and platform_machine == 'arm64'. That is not a soft preference. It is the runtime.
How the bidirectional encoder and decision heads fit together
The pipeline the README gives is short: state plus typed question goes into a bidirectional encoder, then decision heads, then probabilities. There is no autoregressive loop, so there is no decoding step to tune and no JSON to parse out of a string.
Three question types are exposed. choice returns probabilities over named options. score returns probabilities over ordered rubric levels plus their expected score. noul returns P(true) for a proposition. The encoder and decision heads are reimplemented in MLX, and the tokenizers package is a dependency.
For batches, the README says predict_batch shares forward passes across identical question schemas.
Three checkpoints are supported. convaiinnovations/laya has 421M parameters and a 512-token context, for English. convaiinnovations/laya-multilingual has 322M parameters and a 1,024-token context. convaiinnovations/laya-typed-decisions has 421M parameters and a 1,024-token context, aimed at upstream typed-decisions workflows. Context covers instructions, options and state together, so a long state string eats into the room left for the question.
Installing laya-mlx and running a first typed decision
The package is on PyPI. The README's quick start is a single pip install, and the first load pulls the checkpoint from Hugging Face; after that, inference is local.
pip install laya-mlxThe example below asks a support message to be routed. It loads the pre-converted FP16 checkpoint aac6fef/laya-mlx, then calls predict with the state string and a dictionary describing one choice question with three criteria.
import laya_mlx as laya

agent = laya.load("aac6fef/laya-mlx")
result = agent.predict(
    "I was billed twice. Please refund the duplicate.",
    {
        "department": {
            "type": "choice",
            "instructions": "Which department should handle this request?",
            "criteria": ["billing", "technical", "sales"],
        }
    },
)
For a terminal demo, the README installs the demo extra, downloads the multilingual checkpoint in advance, and runs the Snake CLI. The download step matters because the demo is meant to run offline afterwards.
pip install 'laya-mlx[demo]'
hf download aac6fef/laya-multilingual-mlx
laya-snake
Use a terminal of at least 104 x 35 cells. Space pauses, the up and down arrows change speed, R resets and Q quits. The README also documents laya-snake --max-speed, which removes pacing, and laya-snake --optimize --max-speed. The package also exposes a laya-mlx console script entry point.
Latency numbers and what they do not cover
The headline figures are 13.42 ms P50 for one short question on the 421M model and 7.39 ms for the 322M multilingual model, both FP16 end to end on an M3 Max with 40 GPU cores and 128 GiB of memory. P95 is 13.92 ms and 7.79 ms respectively. Throughput at 50 questions is 146.8 q/s and 395.0 q/s. Peak MLX allocation for a single short question is 943.6 MiB and 687.6 MiB.
Read the fine print. Timing includes prompt preparation, tokenization, inference, calibration and formatting, but excludes model loading. The 50-question measurement uses batch_size=64 while the API defaults to 16, so the throughput row is not what a default caller gets. And the latency row measures one short question, while each Snake move asks three questions. Quoting 13.4 ms as your per-decision budget in a multi-question loop would be a misreading of the source.
On correctness, the README reports that all three checkpoints matched the upstream selected answer on 63/63 validation questions in both FP32 and FP16, 378 comparisons in total, and that calls were deterministic on repetition with no measured memory growth. The README itself scopes this: it measures fidelity on those fixtures, not accuracy on every possible question. Treat it as a port-fidelity claim, not a quality claim.
Where laya-mlx is the wrong tool
The clearest boundary is platform. CUDA is out of scope. The mlx dependency is conditioned on darwin and arm64, so a pip install on anything else does not give you a working runtime.
The second boundary is task shape. This is not a text generator. If your output is a summary, a reply draft or a tool call in JSON, you are outside the three question types and outside the project's stated purpose. The README's own framing, that it generates no tokens, is a feature for routing and a disqualifier for generation.
The third is training. The README states that the repository provides inference and conversion, and that RLCD training and fine-tuning remain in the upstream project. The published checkpoints carry pinned revisions and hashes in hub-publication.json.
Finally, the project is an independent port and says so: it is not an official Convai Innovations release. If you need vendor support, that is a real consideration.
laya-mlx versus keeping the PyTorch reference stack
The natural alternative is the upstream Laya project with its PyTorch and Transformers reference path. The pyproject.toml makes the split concrete: there is a reference extra pulling torch>=2.14,<3, transformers>=5.17,<6 and safetensors>=0.6, and it is optional. The default dependency set is mlx, numpy, huggingface-hub and tokenizers.
The difference is not accuracy on the fixtures, since the port matched upstream on all 63 validation questions in both precisions. The difference is the runtime. The reference stack gives you the training and fine-tuning workflows that this repository explicitly leaves upstream, plus portability off Apple Silicon. laya-mlx gives you a smaller dependency surface on a Mac and a path that the README measures in single-digit to low-double-digit milliseconds per short question.
If you are prototyping on a Mac and will later train or fine-tune, the reference extra is the more honest starting point, because you will not have to switch stacks when you reach the part this port does not cover. If you only ever call the model for inference on Apple hardware, the MLX path removes an entire framework from your install.
Licence, maintenance and what an upgrade costs you
The project is Apache-2.0, declared both in the repository metadata and in pyproject.toml, with a LICENSE and a NOTICE file at the top level. Apache-2.0 includes an explicit patent grant and requires that you preserve the NOTICE file and state changes you make. That is a description of the licence text, not legal advice; if you are redistributing the package or the converted weights, have someone check your obligations.
The licence of the package is one question. The licence of the model weights is another. The README says each published checkpoint includes its model card, validation results, provenance and checksums, so read the model card for the checkpoint you actually deploy. The README also states the port is independent and not an official Convai Innovations release.
On cadence: the last push to the repository was on 2026-10-29. Version 0.6.0 is classified as Development Status 4 - Beta, so expect interface movement. The upgrade surface is small in one respect and awkward in another. Small, because the dependency list is four packages and the MLX pin is a single minor range, mlx>=0.32.2,<0.33, which means an MLX 0.33 release will require a version bump here. Awkward, because checkpoint behaviour is tied to pinned revisions and weight hashes recorded in benchmarks/results/hub-publication.json, so a checkpoint update is a behavioural change you should treat like a code change.
Editorial conclusion
Adopt laya-mlx if you need a bounded decision (a department, a rubric level, a yes/no probability) on an Apple Silicon machine and you want it local, without a PyTorch or Transformers runtime. Skip it if you need generated text, if you are not on arm64 macOS, or if you need to fine-tune: the README states that RLCD training and fine-tuning remain in the upstream project, and the port covers inference and conversion only. Before wiring it into anything, verify two things yourself: that your Mac meets the stated macOS 14+ and Python 3.11+ requirements, and that your questions fit the context limit of the checkpoint you pick, 512 tokens for convaiinnovations/laya and 1,024 for the other two.
Frequently asked questions
What does laya-mlx need to run?
An Apple Silicon Mac with Python 3.11 or newer and macOS 14 or newer. The mlx dependency is conditioned on darwin and arm64, so there is no Linux or CUDA path described. The first load downloads the checkpoint and later inference is fully local.
Does laya-mlx generate text?
No. The README describes it as answering constrained questions from one bidirectional forward pass, generating no tokens. It returns probabilities over named options for choice, over ordered rubric levels for score, and P(true) for noul.
Can I fine-tune a Laya model with laya-mlx?
No. The README states that this repository provides inference and conversion, and that RLCD training and fine-tuning remain in the upstream project. The optional reference extra pulls torch and transformers for the upstream path.
Is laya-mlx an official Convai Innovations release?
It is not. The README describes it as an independent MLX port that retains the original pretrained weights, question formatting, calibration and output schema, but it is not an official Convai Innovations release.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 0 in the last 30 days; newest first.
- Laya MLXHacker News · Sep 20, 2026 · 3 points · 1 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mizorewww-laya-mlx)Star history chart for your README
[](https://hysenlabs.com/projects/mizorewww-laya-mlx)Was this useful?