EasySpider: a visual crawler you drive by right-clicking page elements
EasySpider: a visual no-code/code-free web crawler for browser automation testing, data collection and web scraping, letting you design and run crawler tasks graphically without writing code. Also known as ServiceWrapper, an intelligent service-wrapping system for web applications.
At a glance
- What is it?
- EasySpider is an AGPL-3.0 JavaScript desktop tool that builds crawler tasks from clicks in a real browser instead of from selectors typed into code. It is a good fit for one-off or small-batch extraction by people who do not write code, and a poor fit for anyone who needs a stable, versioned pipeline.
- Who is it for?
- Adopt EasySpider if the person who needs the data is the person clicking through the page, and the job is bounded: a few hundred listings, a recurring report, a one-off export. Do not adopt it as the collection layer inside a production pipeline, because the task is built by clicking in a visual project rather than written as code you review, and AGPL-3.0 means that if you modify it and let users interact with it over a network, you must offer them the corresponding source.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
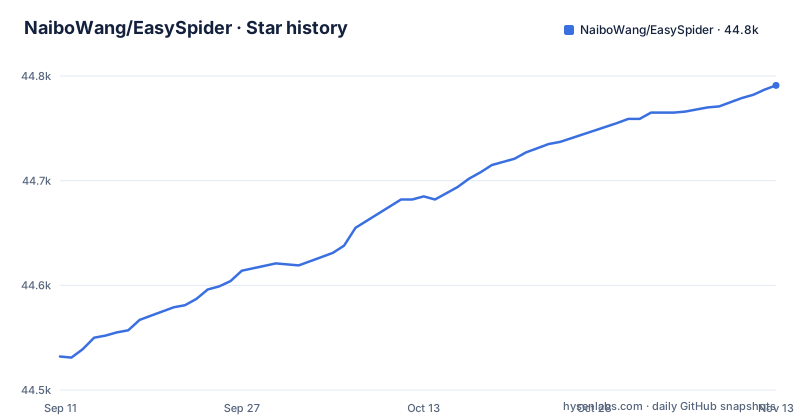
- NaiboWang/EasySpider44,791 ★ · +259
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| NaiboWang/EasySpider | 44.5k | 44.8k |
259 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem: element selection is where non-programmers give up
Most people who need data off a web page can already see the data. What stops them is the step between seeing it and getting it into a spreadsheet: writing a selector, handling pagination, opening detail pages, and repeating all of that when the page changes. EasySpider targets exactly that gap. The README describes the workflow as selecting content on the page and following prompts, with no code required, and it says the software can also be run from the command line so it can be embedded in other systems. The audience is explicit in the project's own description: a code-free crawler for designing and running tasks graphically. That is a different audience from the one served by a Python scraping library, and it changes what the tool optimises for. A library optimises for expressiveness and for being reviewable in a diff. EasySpider optimises for the first five minutes of a task, when someone who has never written a selector needs to point at a product block and have the tool infer the rest.
How a task gets built: click a block, let the tool match siblings
The mechanism is inference from one example. In the first README example, you right-click a large product block; the software detects similar blocks on the page; you click 'Select All'; then 'Select Child Elements'; then 'Collect Data'. The result is described as all products' information saved by sub-field, meaning the child elements inside each matched block become separate columns rather than one blob of text. The second example works on a single field: right-click a product title, the same type of title is matched automatically, then 'Select All' and 'Collect Data' collects only titles. There is also a 'Loop-click every element' option, which the README says opens each product's detail page in turn, after which you can configure collection on the detail page. That is the whole data flow: one labelled example, a sibling match, an optional per-element navigation step, and a field mapping. It is a reasonable design because the hard part of scraping a listing page is not the request, it is deciding which nodes belong together.
Running a task without the GUI, and what the licence requires
The README states the software can be executed separately in command-line mode and embedded into other systems, which is the part that matters if you want to schedule collection rather than sit in front of the designer. The exact command is not given in the opening of the README; the README links a wiki for documentation. Distribution is simpler than for many tools: the README calls the software completely free, including for commercial use and secondary development, and the repository licence is AGPL-3.0. Those two statements point in the same direction, and AGPL-3.0 is the operative one. The practical consequence, described in general terms rather than as legal advice, is that the copyleft reaches users who interact with a modified version over a network, so a hosted, modified EasySpider is not the same situation as an internal desktop install. If your plan is to run the stock release on your own machine to produce a CSV, the licence question is small. If your plan is to fork it behind an internal web service, read the licence text and get your own advice before you build on it.
Where the visual approach stops paying off
The failure mode is the one that affects every visual automation tool: the task is bound to the page as it looked when you recorded it. A saved project is a record of clicks against a particular DOM, not a specification of intent. When the site restructures a listing, the person who can fix it is the person who recorded it, because the knowledge lives in their memory of the clicks rather than in a file a colleague can read. The second limitation is scale. The README examples shown are about collecting items from a single page. The presence of proxy and CAPTCHA vendors as sponsors suggests that large-scale collection is a real use case for the user base, but sponsorship is not a feature list. Treat the stock tool as a single-user, browser-driven collector and verify its behaviour under sustained load yourself before you assume otherwise. The third case where it is simply the wrong tool: if the data is reachable through an API or a bulk export, a visual browser automation layer adds a rendering step and a failure surface for no benefit.
The alternative: Scrapy, and the difference is where the task lives
The obvious comparison is Scrapy, the Python framework that most engineers reach for when a crawl becomes a system. The difference is not language preference, it is where the task definition lives. In Scrapy you write a spider: a class with start URLs and parse methods, checked into version control, reviewable in a pull request, runnable headless on a server, and testable against saved HTML. In EasySpider the task is a project you assembled by clicking, and the README's framing of the tool as a way to design and execute tasks visually is the honest description of that trade. You gain a much shorter path from 'I need this table' to a populated spreadsheet, and you lose the ability to diff a change, to run the same task in CI, and to hand it to a colleague who was not present when it was built. Playwright is the other reference point, and it sits between the two: it is code, so it is reviewable, but it drives a real browser, so it handles pages that a plain HTTP spider cannot. EasySpider's advantage over both is the first hour, not the first year.
Maintenance cost and what to check before you commit
The release history shows v0.6.2 in April 2024, v0.6.3 in January 2025, and v0.6.5 in August 2026, with the repository last pushed on 2026-11-02. That is a slow but continuing cadence rather than an abandoned project, and the version numbers still sit below 1.0, which is a fair signal that interfaces and behaviour can move. The upgrade cost is the usual desktop-application cost: you download a new release from the Releases page, and the README points to a mirror at easyspider.cn for users who find the GitHub download slow. What you should verify first is narrower and more practical. Confirm the current release runs on your operating system and against the browser you intend to drive, since the whole method depends on that browser session. Re-run your element-selection step on the live sites you care about, because a task that worked when recorded is not evidence that it works today. And if you plan to embed the command-line mode in another system, check the project documentation for the actual invocation.
Editorial conclusion
Adopt EasySpider if the person who needs the data is the person clicking through the page, and the job is bounded: a few hundred listings, a recurring report, a one-off export. Do not adopt it as the collection layer inside a production pipeline, because the task is built by clicking in a visual project rather than written as code you review, and AGPL-3.0 means that if you modify it and let users interact with it over a network, you must offer them the corresponding source. Before committing, verify three things yourself: that the current release runs on your operating system and browser, that the element-selection step still matches the sites you care about, and whether your own distribution plan is compatible with the licence.
Frequently asked questions
How do web crawlers work?
In EasySpider the flow is a right click on the page element you care about, and the software detects the other elements of the same type automatically. You then choose Select All, optionally Select Child Elements or Loop-click every element to open each detail page, and finally Collect Data, which saves results split into sub-fields. A finished task is stored as a JSON document and can also be run from the command line.
What does it mean when a web search engine is crawling?
That describes a search engine building an index, which is a different job from the one this project does. EasySpider collects a defined set of fields from pages you navigate yourself, and its documentation is the GitHub wiki, with the design model described at greater length in the author's thesis, .
Is web development easy for beginners?
The repository does not address that question, and it shows the inverse case instead: a crawler configured without writing code, where both worked examples are a sequence of interface actions ending in Collect Data. The examples directory includes a task file with a JavaScript condition (JS判断条件示例.json).
Does WebCrawler still exist?
The project does not mention a product under that name, so there is nothing there to confirm. The crawler here is EasySpider, a visual no-code browser automation and data collection tool under AGPL-3.0, with a desktop application built on Electron, downloads from the GitHub releases page, and a China-domestic mirror offered for slow connections.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/naibowang-easyspider)Star history chart for your README
[](https://hysenlabs.com/projects/naibowang-easyspider)Was this useful?