FlexSearch: a full-text search library for the browser and Node.js
Next-generation full-text search library for Browser and Node.js
At a glance
- What is it?
- FlexSearch indexes text in JavaScript, with persistent indexes for Redis, SQLite, Postgres, MongoDB and Clickhouse in v0.8. Here is how it works, how to install it, and where it stops being the right tool.
- Who is it for?
- Adopt FlexSearch when search has to run inside a JavaScript process, in the browser or on a Node.js server, and when you want ranking and tokenization under your own control. Do not adopt it when you need a standalone search service with a query language, clustering, or an operational surface you can hand to a platform team; that is what Elasticsearch and similar servers are for.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 139 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
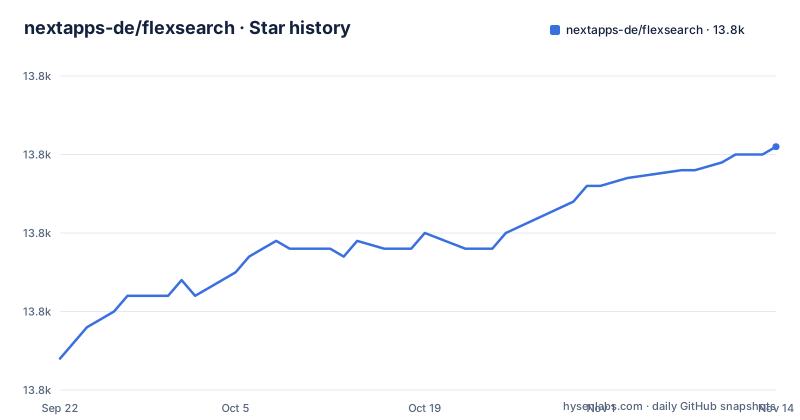
Star history
- nextapps-de/flexsearch13,821 ★ · +27
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| nextapps-de/flexsearch | 13.8k | 13.8k |
27 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What FlexSearch replaces, and for whom
The problem FlexSearch addresses is the gap between a linear scan and a search server. If you have a few thousand records in a browser tab or a Node.js process, filtering them with Array.prototype.filter on every keystroke is simple until it is not: no ranking, no partial matching, no tolerance for typos, and a cost that grows with the corpus. Standing up Elasticsearch for that job means a second process, a mapping, a client library and an index that has to be kept in sync with the source of truth.
FlexSearch sits in the middle. It is a JavaScript library, distributed on npm as flexsearch, that builds an inverted index in memory and answers queries from that index. The README describes it as a "Next-Generation full-text search library for Browser and Node.js" and lists the features that distinguish it from a plain filter: multi-field document search, phonetic transformations, partial matching, tag search, result highlighting and suggestions. The package.json keywords name the same territory: fulltext search, fuzzy search, document search, search engine.
The audience is therefore specific. Front-end engineers building auto-complete, command palettes, client-side documentation search or offline-capable apps. Node.js engineers who want search embedded in an existing service rather than deployed beside it. Teams that need CJK, Arabic, Cyrillic, Greek, Hebrew or Hindi tokenization without writing their own segmenter, since the README lists those charsets as supported alongside Latin. What it is not is a replacement for a distributed search cluster: it runs inside your process, and the persistence layer is a set of adapters onto databases you already run.
How the index and the encoders fit together
FlexSearch's core is an index object that maps tokens to document references, plus an encoder that decides what a token is. The encoder is where most of the behaviour lives. It handles the charset, the normalization (case, diacritics), and the transformation rules that make partial and phonetic matching possible. The README links a separate doc/encoder.md and lists the supported charsets, which tells you the encoder is a first-class, configurable component rather than a fixed tokenizer.
On top of the index sit two usage modes. The plain index takes a string per document. Document search takes objects and lets you declare which fields are indexed, which is what the README calls multi-field search; the doc/document-search.md page covers it along with tag search, where a document carries tags that can be used to narrow a query. Result highlighting is a separate doc page, which implies the library returns enough positional information about a match to mark it up in the original text.
Version 0.8 added persistent indexes, and this is the architectural change worth understanding. The README states that "All available features was natively ported right into the database engine of your choice," and lists InMemory (the default) plus IndexedDB in the browser, Redis, SQLite, Postgres, MongoDB and Clickhouse. The package.json exports map confirms the layout: subpaths under ./db/* resolve to dist/module/db/*/index.js for ESM and dist/db/*/index.cjs for CommonJS, and ./lang/* resolves to per-language builds. So a persistent index is not a serialized blob you rehydrate; it is an adapter that reads and writes index structures in the target database. That is what makes the parallel and large-dataset claims in the README plausible, and it is also the part most likely to vary in behaviour between backends.
The docker-compose.yml in the repository root is the development counterpart: it starts postgres on 5432, clickhouse on 8123, redis on 6379 using the redislabs/rejson image, and mongo on 27017, each with a named volume. Those are the services the persistent adapters are exercised against.
Installing FlexSearch and running a first query
The package is published on npm as flexsearch, so installation is the ordinary npm install. The repository ships four example directories: example/nodejs-esm, example/nodejs-commonjs, example/browser-module and example/browser-legacy. Pick the one matching your module system.
npm install flexsearchIn an ESM Node.js project, the exports map resolves the import to dist/flexsearch.bundle.module.min.mjs. The README's basic start section is the entry point for the API, and example/nodejs-esm is the working reference for the module form.
For browser use, the exports map has a browser condition pointing at the same ESM bundle, so a bundler resolves it without extra configuration. The legacy script build, dist/flexsearch.bundle.min.js, is the option when there is no bundler at all, and example/browser-legacy shows how it is loaded.
If you want the index to survive a page reload, the IndexedDB adapter is the browser-side persistent option and doc/persistent-indexeddb.md is its documentation. On the server side, the docker-compose.yml services give you a local Redis, Postgres, Clickhouse or MongoDB to test the corresponding adapter against before pointing it at anything shared. Start them with the compose file in the repository root; the service names are postgres, clickhouse, redis and mongo.
Where FlexSearch is the wrong choice
The honest limitation is scope. FlexSearch is a library, which means every operational concern is yours. There is no server to monitor, no query language to hand to an analyst, no cluster to scale horizontally, and no built-in replication between nodes. If your search box is really a product feature with relevance tuning, synonyms maintained by a non-engineer, and an SLA, you are building that layer yourself on top of an index object.
The persistent adapters sharpen this. Using the Postgres or Clickhouse backend means your search index now lives in the same database as your application data, with its own schema, its own write path and its own failure modes. Plan for how the index and the source records stay in sync before running this in production against a database you also use for transactional work.
Memory is the other boundary. The README's benchmark table lists an additional allocation of 16 units for flexsearch during search, against 2188 for jsii, 980 for wade, 237 for js-search, 4777 for minisearch and 5355 for orama. Those numbers come from the project's own benchmark page and measure allocation during the query, not total index size. A large corpus still has to fit somewhere: in the heap for the default InMemory backend, or in the database for a persistent one.
Finally, the release cadence is worth noting. The newest tagged release is 0.8.2 from 2025-05-21, while package.json carries version 0.8.215 and the last push to the default branch was 2026-06-28. The repository is not archived, but the tagged releases lag the package version, so pinning is advisable.
FlexSearch compared with MiniSearch and Lunr
The two libraries most often weighed against FlexSearch are MiniSearch and Lunr, and the difference is not speed so much as what each one optimizes for.
MiniSearch is also a JavaScript full-text library, and it appears in FlexSearch's own benchmark table with a memory figure of 4777 against FlexSearch's 16, and much lower query throughput across the four query categories. Those are the project's figures, not an independent measurement, and they measure a specific benchmark corpus. The more useful distinction is design: FlexSearch's surface is large, with encoders, document search, tag search, highlighting, workers and seven storage backends. Larger surface means more configuration to get right before the first query behaves the way you expect.
Lunr is the older option, best known for powering client-side documentation search. Its model is closer to a traditional search engine: build an index, serialize it, load it in the browser. FlexSearch's IndexedDB adapter takes a different route, keeping the index in a browser database rather than shipping a serialized file, which matters when the corpus is too large to embed in a bundle.
Against a real search server, the comparison is category-level. Elasticsearch indexes documents over HTTP and answers with a query DSL; FlexSearch indexes inside your process and answers with a JavaScript call. The README's own keywords include "elastic search," which is a positioning statement rather than a technical equivalence. Choose the server when search is a service with its own lifecycle; choose FlexSearch when search is a function call inside an application you already run.
Maintenance, licence and upgrade cost
FlexSearch is licensed Apache-2.0, stated in the LICENSE file and in the npm badge. Apache-2.0 is a permissive licence with an explicit patent grant and a requirement to preserve notices; it does not impose copyleft obligations on your application. That is a statement about the licence text, not legal advice, and anyone embedding the library in a distributed product should read the LICENSE file itself.
The maintenance picture is mixed in a specific way. The last push to master was 2026-06-28, and the repository is not archived, so work is ongoing. But the newest tagged release is 0.8.2 from 2025-05-21, while package.json declares 0.8.215. Anyone installing from npm without a lockfile gets whatever the registry serves for the version range they specify, which may be ahead of the last tag. Pinning an exact version and reading CHANGELOG.md before moving is the cheap precaution.
Upgrade cost concentrates in two places. The v0.8 line introduced persistent indexes, and the README's top comment links a dedicated migration guide at doc/0.8.0.md, which is where breaking changes between the 0.7 and 0.8 APIs are documented. If you use a persistent backend, an upgrade can also mean a change to the index structures stored in your database. Test the adapter against a copy of the real database, not an empty one, before rolling forward.
The project accepts donations through Open Collective, GitHub Sponsors, Liberapay, Patreon and PayPal, and lists Antithesis Operations LLC as a sponsor.
Editorial conclusion
Adopt FlexSearch when search has to run inside a JavaScript process, in the browser or on a Node.js server, and when you want ranking and tokenization under your own control. Do not adopt it when you need a standalone search service with a query language, clustering, or an operational surface you can hand to a platform team; that is what Elasticsearch and similar servers are for. Before committing, verify two things against your own data: that the exported encoders handle your charset, and that the persistent index for your chosen database behaves the way the doc/persistent-*.md pages describe on your version. The package version in package.json is 0.8.215 while the newest tagged release is 0.8.2, so pin the version you test rather than tracking the npm dist-tag.
Frequently asked questions
What is FlexSearch and what is it used for?
FlexSearch is a full-text search library for Browser and Node.js, published on npm as flexsearch. It builds an inverted index in JavaScript and answers queries from it, with document search across multiple fields, partial matching, tag search and result highlighting.
How do I install FlexSearch in a Node.js project?
Install it from npm with npm install flexsearch. The repository provides separate examples for ESM and CommonJS under example/nodejs-esm and example/nodejs-commonjs, and the exports map resolves the import or require to the matching bundle.
Can FlexSearch store its index in a database instead of memory?
Yes. Version 0.8 introduced persistent indexes, and the README lists IndexedDB for the browser plus Redis, SQLite, Postgres, MongoDB and Clickhouse on the server, with InMemory as the default. Each backend has its own documentation page under doc/.
Does FlexSearch work in the browser without a build step?
The repository includes example/browser-legacy, which uses the legacy script build at dist/flexsearch.bundle.min.js. There is also example/browser-module for ESM, and the package.json browser field points at the module bundle for bundlers.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nextapps-de-flexsearch)Star history chart for your README
[](https://hysenlabs.com/projects/nextapps-de-flexsearch)Was this useful?