PDFKit: generating PDFs in Node and the browser without a headless browser
A JavaScript PDF generation library for Node and the browser
At a glance
- What is it?
- PDFKit is a JavaScript library that writes PDF documents directly, with vector graphics, font embedding, tables, AcroForms and PDF/UA tagging. It is a good fit when you control the content and want no Chromium in the loop, and a poor fit when your source is already HTML.
- Who is it for?
- Adopt PDFKit when your document is generated from structured data, you want font subsetting and tagged PDF output, and you are willing to lay out pages yourself. Do not adopt it if your source of truth is an HTML page or a CSS stylesheet, because PDFKit has no HTML or CSS renderer and no higher level layout engine beyond the table and list helpers the README lists.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 11 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
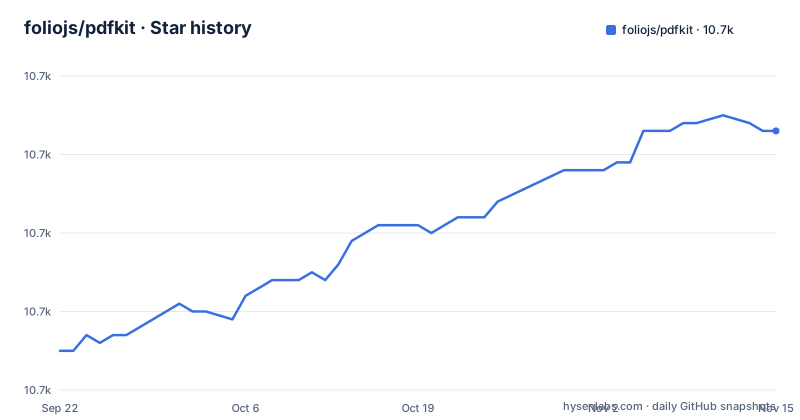
- foliojs/pdfkit10,733 ★ · +28
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| foliojs/pdfkit | 10.7k | 10.7k |
28 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What PDFKit is for, and who ends up using it
PDFKit solves one problem: turning a program's data into a PDF file without a browser, a printer driver or an external binary. The README describes it as a PDF document generation library for Node and the browser that makes creating complex, multi-page, printable documents easy. The audience is JavaScript developers writing server-side report generators, invoice and statement pipelines, ticketing or label output, and client-side export buttons where a round trip to a server is not wanted.
The library is deliberately low level. Its API is chainable, and the README says it includes both low level functions and abstractions for higher level functionality. That combination is the whole trade-off. You get direct control over coordinates, paths and page breaks, plus convenience helpers for text wrapping, bulleted lists and tables. You do not get a layout engine that decides where things go based on content flow. If you have ever wanted a PDF library that behaves like a canvas, this is the shape of it.
The feature list is broad for a library that has no rendering engine behind it: vector graphics with an HTML5 canvas-like API, linear and radial gradients, an SVG path parser, font embedding with subsetting, JPEG and PNG image embedding, tables, annotations, AcroForms, outlines, encryption with access privileges, and accessibility support covering marked content, logical structure, Tagged PDF and PDF/UA.
The mechanism: a chainable document object that writes PDF operators
A PDFKit document is an object you create, write into, and then end. The README's example shows the pattern exactly: construct a PDFDocument, pipe its output to a writable stream, call methods, then call doc.end(). Output arrives as chunks on that stream, which is why the same code works against fs.createWriteStream in Node and against a Blob in the browser.
Methods return the document, so calls chain. doc.font(...).fontSize(25).text(...) sets state and draws in one expression. The README lists an HTML5 canvas-like API, path operations, transformations and an SVG path parser for easy path creation.
Two dependencies shape the behaviour. fontkit handles font parsing, glyph layout and the subsetting that keeps embedded font data small; the README points to it for advanced glyph layout support and lists TrueType, OpenType, WOFF, WOFF2, TrueType Collections and Datafork TrueType as accepted formats. linebreak handles the text wrapping, which is why the README can advertise soft hyphen recognition as a wrapping feature. Underneath, the library emits PDF operators and objects itself.
There is no HTML parser and no CSS cascade anywhere in this path. Text is positioned by you or wrapped by the library's own line breaker; it is not styled by a stylesheet.
Installing pdfkit and producing a first document
Installation is a single package manager command. The README gives both npm and yarn forms, and there is no build step, no native compilation and no system library to install first.
npm install pdfkitThe README's own example is the shortest path to a real file. It writes to output.pdf in the working directory, embeds a TrueType font, places text at coordinates, adds an image constrained to a box and centered both ways. Note the named export: the README states that both const PDFDocument = require('pdfkit') and the default import remain supported for backward compatibility, but says new code should prefer the named PDFDocument export, because it makes a future migration to an ESM-only package more straightforward.
const { PDFDocument } = require('pdfkit');
const fs = require('fs');

const doc = new PDFDocument();
doc.pipe(fs.createWriteStream('output.pdf'));

doc.font('fonts/PalatinoBold.ttf').fontSize(25).text('Some text with an embedded font!', 100, 100);
doc.image('path/to/image.png', { fit: [250, 300], align: 'center', valign: 'center' });
doc.end();
After doc.end() runs, output.pdf exists and is a valid PDF. The image options in that call are worth reading closely: fit constrains both dimensions, and align and valign center the image inside the resulting box rather than at the page level.
For the browser, the README lists three routes: Browserify, webpack, or the prebuilt pdfkit.standalone.js distributed in the releases and in the package's js folder. It also notes that the browser build has no file system access, and that you can register a Uint8Array under a path with registerFile before passing that same path to registerFont, image or file.
Collecting output in the browser, and why those helpers are marked experimental
In Node the pipe to a stream is the whole story. In a browser you have to collect the bytes yourself. The README describes toBlob and toBytes, exported from pdfkit/output, as experimental helpers that may change before they are stabilized. Both must be called before doc.end() so they receive the complete output. Use toBlob when you are displaying, downloading or uploading in a browser, and toBytes when a binary API, worker or parser needs one contiguous Uint8Array.
import { PDFDocument, registerStdFonts } from 'pdfkit';
import Helvetica from 'pdfkit/standard-fonts/Helvetica';
import HelveticaBold from 'pdfkit/standard-fonts/HelveticaBold';
import { toBlob } from 'pdfkit/output';

registerStdFonts(Helvetica, HelveticaBold);
const doc = new PDFDocument();
const output = toBlob(doc);
doc.end();
const blob = await output;
That snippet also shows standard font registration, which is a separate concern from output collection. The README's browser example imports individual standard font modules and registers them with registerStdFonts before constructing the document. If you skip that and call font('Helvetica') in a browser build, the font data has to come from somewhere. Treat the registration step as part of the setup, not an optional extra.
One detail in the README's toBlob example is easy to miss: the comment reminding you to revoke the object URL when the iframe no longer needs the PDF. Object URLs hold their data until revoked.
Where PDFKit stops being the right tool
The clearest boundary is HTML. PDFKit has no HTML renderer and no CSS engine. If your document already exists as a styled web page, or your design team hands you a stylesheet, PDFKit makes you rebuild that layout in drawing calls. The README's own roadmap points at the gap: patterns fills, higher level APIs for laying out content and more performance optimizations are all listed under Coming soon. Until those land, anything resembling flowing content across pages is your problem, not the library's.
The second boundary is text you did not author. Wrapping is handled, and soft hyphens are recognized, but this is not a text engine that reflows around floats, avoids orphans and widows, or balances columns. Documents where the content length varies wildly and the layout must adapt are painful to build here.
The third is a practical one about fonts. Embedding and subsetting are supported for a long list of formats, but you supply the font files and you are responsible for having the right to embed them. A library that subsets a font into your output is doing you a favour and creating a licensing question at the same time.
Finally, the browser build cannot read the file system, which the README states plainly. Any asset you want to place (a font, an image, a file) has to be fetched or bundled first and registered under a path before you reference it. Server-side code that reads from disk will not port to the browser unchanged.
PDFKit against a headless browser, and against pdfmake
The comparison people actually search for is PDFKit against Puppeteer. The difference is architectural, not cosmetic. A headless browser renders your HTML and CSS with the same engine that renders a web page, then prints the result to PDF. PDFKit skips the rendering engine entirely and writes PDF operators directly. That means no Chromium process to start, no page load to wait for, and no dependency on a browser binary in your deployment image. It also means the layout you get is the layout you coded, not the layout a browser computed.
For an invoice generated from a database row, the direct approach wins on predictability and startup cost. For a report assembled from existing HTML templates with complex CSS, the headless browser wins on effort, because you already wrote the layout once.
The comparison against pdfmake is closer, since both are JavaScript libraries that write PDFs without a browser. The difference shows up in the programming model. PDFKit exposes a canvas-like API where you position content and the library gives you primitives plus some higher level helpers. pdfmake is built around a declarative document definition object that its own layout engine turns into pages. If you want to describe a document and let the library decide where the page breaks fall, that declarative model is the one to look at. If you want to decide where things go, PDFKit is the one that hands you the coordinates. Neither is a superset of the other, and the choice is really about who owns layout: you, or the library.
Maintenance, licence and upgrade cost
The repository is not archived, and the last push was on 2026-11-01. Releases in the recent series are v0.20.0 and v0.20.1, both on 2026-08-23, and v0.20.2 on 2026-08-30. That is a steady cadence rather than a burst, and the version number still sits below 1.0, which is worth reading as a statement about API stability expectations rather than as a defect.
The licence is MIT, declared in package.json and present as a LICENSE file at the repository root. MIT is permissive: it allows use, modification and redistribution, including in closed-source products, provided the copyright notice and permission notice are retained. That is a description of the licence text, not legal advice; if your product ships embedded fonts or handles regulated documents, get your own review.
The upgrade cost is dominated by two things. First, the ESM transition. The README explicitly recommends the named PDFDocument export over the default export to make a future migration to an ESM-only package more straightforward, which tells you the maintainers intend that move. Code written with the named export today will need less work later. Second, the experimental output helpers. Anything built on toBlob or toBytes from pdfkit/output is on ground the README says may change before stabilization, so pinning your dependency and reading the changelog before upgrading is the cheap insurance here.
The dependency list is small and mostly pure JavaScript: @noble/ciphers and @noble/hashes, fflate, fontkit, linebreak and png-js. There is no native module in that list, which is why installation does not need a compiler.
Editorial conclusion
Adopt PDFKit when your document is generated from structured data, you want font subsetting and tagged PDF output, and you are willing to lay out pages yourself. Do not adopt it if your source of truth is an HTML page or a CSS stylesheet, because PDFKit has no HTML or CSS renderer and no higher level layout engine beyond the table and list helpers the README lists. Before committing, verify two things in your own environment: that the standard font registration path you plan to use matches the version of the package you install, since the README marks the toBlob and toBytes helpers as experimental, and that the fonts you embed are licensed for embedding in a generated document. The repository is on the master branch, the current version in package.json is 0.20.2, and the last push was on 2026-11-01.
Frequently asked questions
Can I use PDFKit in React?
The README does not describe a React integration. It does describe three browser routes: Browserify, webpack, and the prebuilt pdfkit.standalone.js from the releases or the package's js folder, and a React app built with one of those bundlers can import the library the same way. The browser build has no file system access, so fonts and images must be registered as a Uint8Array under a path before you pass that path to registerFont, image or file.
How do I install PDFKit?
The README gives two commands, npm install pdfkit or yarn add pdfkit, and notes you can use either npm or yarn as the package manager. There is no separate build or system dependency step in the installation instructions.
How do I use PDFKit in Node.js?
Create a document with new PDFDocument(), pipe its output to a writable stream such as fs.createWriteStream, chain drawing calls, and finish with doc.end(). The README's example shows exactly this sequence, including font embedding and image placement with fit and align options.
Is PDFKit free and open source?
Yes. The licence is MIT, declared in package.json and present as a LICENSE file at the repository root. MIT permits use, modification and redistribution provided the copyright and permission notices are retained.
What is PDFKit?
It is a JavaScript PDF generation library for Node and the browser, described in the README as making creating complex, multi-page, printable documents easy. Its API is chainable and includes both low level drawing functions and higher level abstractions such as tables, bulleted lists and text alignment.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/foliojs-pdfkit)Star history chart for your README
[](https://hysenlabs.com/projects/foliojs-pdfkit)Was this useful?