NVIDIA Cloud Functions: A Self-Hosted Route for GPU Workloads
Platform for deploying and routing GPU-accelerated inference, streaming, and batch workloads at scale.
At a glance
- What is it?
- NVIDIA's NVCF monorepo is a Kubernetes-based platform for routing GPU inference, streaming, and batch tasks across clusters. It offers a full control plane, invocation plane, and CLI, but demands significant infrastructure and build tooling.
- Who is it for?
- Adopt NVCF if you operate multiple GPU clusters and need a unified control plane for routing inference, streaming, and batch tasks, and if you can commit to Bazel and Helm. Skip it if you need a lightweight, single-cluster solution or prefer Docker-based builds.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
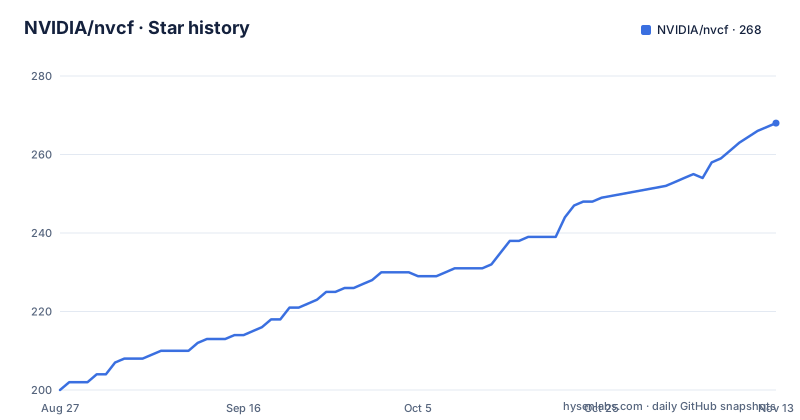
- NVIDIA/nvcf268 ★ · +68
| Repository | 2026-08-27 | 2026-11-13 |
|---|---|---|
| NVIDIA/nvcf | 200 | 268 |
68 Stars in the last 78 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What NVCF Actually Solves
NVCF is for organizations that run GPU-accelerated inference, streaming, or batch workloads across multiple Kubernetes clusters and need a single platform to manage them. The README frames it as a way to route GPU work to worker clusters, reducing the infrastructure you run yourself. It targets two workload types: functions, which are long-running endpoints for inference or streaming, and tasks, which are asynchronous run-to-completion jobs like batch inference or fine-tuning. This distinction matters because it shapes the entire API and routing design. If you only have one cluster and a simple model server, NVCF is overkill. But if you have several clusters with different GPU types and need to balance load across them, the platform provides a unified control plane to do that.
Architecture: Control, Invocation, and Compute Planes
The monorepo splits into three planes. The control plane exposes the NVCF API, manages function and deployment state, handles secrets, and coordinates operations. The invocation plane receives HTTP, streaming, and gRPC requests, applies routing and rate limiting, and sends work to running workloads. The compute plane integrates GPU clusters through the NVIDIA Cluster Agent (NVCA), which registers GPU resources and manages workload execution on nodes. This separation means you can scale each plane independently. The README notes that NVCF can span regions and GPU clusters, implying a multi-region deployment is a first-class design goal. One trade-off is complexity: running three planes as Kubernetes services requires a substantial cluster footprint and operational expertise.
Workload Packaging: Containers and Helm Charts
NVCF supports two packaging formats for both functions and tasks. You can package a workload as a container when it is a single service with health and inference endpoints. Or you can use a Helm chart when the workload needs multiple coordinated containers, services, sidecars, or other Kubernetes resources. This flexibility is useful for complex deployments like a model server with a sidecar for logging or a batch job with auxiliary workers. However, it also means you need to decide upfront which format fits your workload, and the documentation must cover both paths. The README does not detail how the platform discovers or invokes Helm chart-based workloads, so expect to read the docs/user/cli.md and quickstart.md files for specifics.
Getting Started: CLI Workflow and Configuration
The README gives a typical function workflow after installing a self-managed deployment and configuring nvcf-cli. You start with nvcf-cli init, then generate an API key with nvcf-cli api-key generate. Next, you create a function by passing an input file, for example src/clis/nvcf-cli/examples/create-function.json, with your function image. Then you deploy with nvcf-cli function deploy create and invoke with nvcf-cli function invoke --request-body '{"message": "hello world"}'. This is a clean, scriptable flow. But note that the example file must be updated with your own image before creating the function. The CLI lives in src/clis/nvcf-cli, and the README references docs/user/cli.md and docs/user/quickstart.md for full setup and cleanup, which suggests there are more steps than the snippet shows.
Building with Bazel: A Double-Edged Sword
Bazel is the build, test, and packaging tool across the monorepo. Native subtrees like the CLI and Go library build fully under Bazel. Phase B has added Bazel scaffolds to several service trees, including nvcf-grpc-proxy, nvcf-ratelimiter, and nvca. From the umbrella, you can build OCI images for any of these without leaving the monorepo. The quick start shows commands like bazel build //src/clis/nvcf-cli:nvcf-cli and bazel build //src/invocation-plane-services/grpc-proxy:image_index. The README warns that builds read from a remote cache by default and do not upload local results. If you are off the network path that can reach that cache, you may need to disable it with bazel build --remote_cache= (the README is truncated, but the intent is clear). This is a significant operational constraint. Teams not already using Bazel will face a learning curve and potential network dependency issues.
Limitations and Failure Modes
The most obvious limitation is the Bazel remote cache dependency. If your build environment cannot reach the configured cache, builds may fail before local execution starts. The README suggests disabling the remote cache, but that is a manual workaround, not a fix. Another limitation is the sheer scope of the monorepo. It includes control-plane services, invocation-plane services, compute-plane services, CLI code, libraries, deployment assets, and AI tooling. That is a lot of moving parts to operate. The README does not specify minimum Kubernetes versions, hardware requirements, or GPU driver versions, so you cannot assess compatibility without diving into the docs. Finally, the platform is designed for multi-cluster scenarios; using it for a single cluster would add unnecessary complexity. A simpler alternative is to use a direct Kubernetes deployment with an ingress controller and a custom autoscaler, which gives you control without the NVCF control plane.
Alternatives and Trade-offs
The obvious alternative is to roll your own routing layer using Kubernetes services and an ingress controller like NGINX or Traefik. That approach gives you fine-grained control but requires you to build rate limiting, multi-cluster routing, and autoscaling yourself. NVCF provides these as built-in capabilities, as listed in the README: load-balanced routing, multi-cluster autoscaling, health checks, and telemetry. Another alternative is to use a managed GPU serving platform like NVIDIA's own build.nvidia.com, which is powered by NVCF but hosted by NVIDIA. That removes the operational burden entirely but means you do not control the infrastructure. The trade-off is clear: NVCF offers a self-managed middle ground, but you pay for it with operational complexity.
Maintenance and License Considerations
The repository is under Apache-2.0, which is permissive for most use cases, but you should review the license file for any NVIDIA-specific clauses. The project is actively maintained, with recent releases in August 2026, including a UI version and a Rust library called stargate. The monorepo includes migrations/ for datastore schema changes, which means upgrades may require running database migrations. The README mentions Helm charts in deploy/ for stack installation, so upgrading likely involves updating those charts. There is a roadmap section in the README, but the content is not shown here, so you should check it to understand planned changes. The presence of a tools/ directory for license and validation utilities suggests the project takes compliance seriously, but you should still verify that your usage aligns with the license.
Editorial conclusion
Adopt NVCF if you operate multiple GPU clusters and need a unified control plane for routing inference, streaming, and batch tasks, and if you can commit to Bazel and Helm. Skip it if you need a lightweight, single-cluster solution or prefer Docker-based builds. Before adopting, verify that your Kubernetes version matches the Helm charts in deploy/, confirm your GPU cluster can run the NVIDIA Cluster Agent (NVCA), and test the CLI's function create and invoke flow against your own registry. Check the Apache-2.0 license terms for any NVIDIA-specific restrictions, and review the roadmap in the README to see if planned features cover your needs.
Frequently asked questions
what is nvidia nvcf
NVIDIA Cloud Functions, a platform for deploying, managing, and running GPU-accelerated workloads at scale. It routes inference, streaming, and other GPU work to worker clusters, and it runs as Kubernetes services covering function lifecycle, invocation routing, GPU cluster integration, artifact access, secrets, observability, and operations.
What is the difference between an NVCF function and a task?
Functions are long-running and invokable, meant for clients that need an endpoint for inference or streaming. Tasks are asynchronous and run to completion, meant for batch inference, evaluation, fine-tuning, or data preparation that should report status rather than stay online.
Where is the NVCF repository moving to?
It is transferring from NVIDIA/nvcf to dsx-ai-factory/nvcf, targeted for after September 27, 2026, with the exact date and time still pending. GitHub redirects old clone, fetch, and go get URLs, so existing links and the github.com/NVIDIA/nvcf module path keep working.
What builds NVCF?
Bazel, across the monorepo. Two native subtrees, src/clis/nvcf-cli and src/libraries/go/lib, build fully under Bazel today, and Phase B has landed Bazel scaffolds in six upstream-owned service trees including nvcf-grpc-proxy, nvcf-ratelimiter, and nvca.
What does the NVIDIA Cluster Agent do?
NVCA is how GPU clusters connect to NVCF. It registers GPU resources and manages workload execution on the GPU nodes, so nodes join by running an agent rather than by being declared in a cluster manifest.
How much of NVCF is Kubernetes?
NVCF runs as Kubernetes services, and both functions and tasks can be packaged either as a container when the workload is a single service with health and inference endpoints, or as a Helm chart when it needs multiple coordinated containers, services, sidecars, or other Kubernetes resources.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvidia-nvcf)Star history chart for your README
[](https://hysenlabs.com/projects/nvidia-nvcf)Was this useful?