datawhalechina/llm-algo-leetcode: a notebook-first lab for LLM algorithms and GPU systems
LLM algorithm practice lab with theory, solutions and test cases. A tutorial for learning LLM algorithms and systems from beginner to advanced, covering theory, worked solutions, test cases and CUDA/Triton practice.
At a glance
- What is it?
- This is a Chinese-language teaching repository that walks from PyTorch algorithm exercises down to Triton and CUDA kernels, organised as runnable notebooks with question sections, answer sections and test cases. It is a curriculum rather than a library, and its CUDA section is still under construction.
- Who is it for?
- Adopt this if you are already comfortable with Python and PyTorch and want a structured path from Transformer implementations through Triton kernels toward CUDA, or if you are assembling a study group around LLM systems work. Do not adopt it if you need an English-language reference, a maintained library you can import, or complete CUDA material today: Part 04 is marked as under construction and Part 05 is a placeholder.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
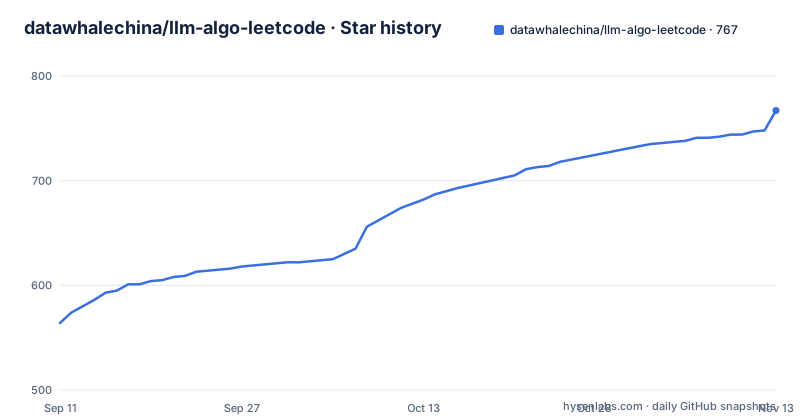
Star history
- datawhalechina/llm-algo-leetcode767 ★ · +203
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| datawhalechina/llm-algo-leetcode | 564 | 767 |
203 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The gap it fills: algorithm exercises that continue into kernels
Most LLM study material stops at the model definition. You implement attention in PyTorch, the shapes line up, and the next question is why the same computation is slow on real hardware. This repository is organised around closing that gap. Its stated path is PyTorch, then Triton, then CUDA, and the README describes the goal as connecting model implementation, operator optimisation, memory management, communication and system performance. The intended audience is named explicitly: algorithm learners who want to understand Transformers, training, fine-tuning, inference and compression; performance learners who want VRAM, profiling, communication and GPU optimisation; and practitioners who want to build reproducible comparisons through benchmarks and inference backend experiments. It is a curriculum, not a package. Nothing here is meant to be installed as a dependency.
How the parts are sequenced, and why Part 02 is the entry point
The repository is split into five parts. Part 00 covers prerequisites: Python, tensors and autograd, model construction, training intuition, and debugging. Part 01 covers hardware, maths and systems: numerical foundations, single-GPU memory access optimisation, multi-GPU communication, heterogeneous scheduling and operator programming, and compilation. Part 02 is the PyTorch algorithm track, with ten groups running from basic operators through model architecture, the training and fine-tuning loop, preference optimisation, backpropagation and memory, core and advanced inference, compression and quantization, distributed parallelism, and a project section. Part 03 is Triton kernel development across fifteen lessons. Part 04 is CUDA C++ and system optimisation, sixteen lessons, marked as under construction. Part 05, CUDA Rust, is a placeholder. The README recommends starting at Part 02 to build practical feel, backfilling Part 00 and Part 01 as needed, then moving to Parts 03 and 04. That ordering is a real editorial decision: the prerequisites are optional reference material rather than a gate, which suits readers who already write PyTorch and would stall on a twenty-lesson warm-up.
The notebook format: question area, answer area, verification
Each lesson is described as being built around runnable code, a question section, an answer section, and basic verification. That is the mechanism that distinguishes this from a prose tutorial. You read a problem statement, attempt an implementation in the notebook, and compare against the provided answer, with test cases acting as the check. The repository topics include test-driven, which matches the claim that verification is part of each lesson rather than an afterthought. The practical consequence is that the material is editable in place: you can change a block size, a dtype, or a decoding strategy and re-run the cell. The trade-off is that notebooks are awkward to diff and review, and a curriculum spread across hundreds of cells is harder to search than a documentation site. The repository does publish a documentation homepage at datawhalechina.github.io/llm-algo-leetcode, which is the better entry point for browsing structure before cloning.
Cross-cutting topic routes versus the linear part order
The README offers two ways to read the material. You can go Part 00 through Part 04 in order, or enter through a topic route. The four main routes are fine-tuning and training, inference optimisation, memory optimisation, and operators and compilers, the last of which is marked in progress. Supporting routes cover quantization and compression, communication and parallelism, profiling, and post-training and alignment. Each route has an intro page and a casebook page, and routes declare which parts they draw from. The inference route, for example, spans Parts 01 and 02 and covers FlashAttention, decoding, PagedAttention, cache behaviour and benchmarking. The quantization route spans Parts 00 to 03 and covers PTQ, QAT, GPTQ, AWQ, FP8 and deployment decisions. This is a genuine structural commitment: the same lesson can serve two routes, and the casebook pages exist to hold the cross-part narrative that a single part cannot. The cost is duplication and the risk of drift when a part is edited but the route page is not.
Getting it running: clone, open a notebook, follow the part intros
The workflow implied by the repository layout is to clone the repository, open a notebook from the relevant part directory, and run the cells. The documented entry points are the intro files: 02_PyTorch_Algorithms/intro.md for the algorithm track, 03_Triton_Kernels/intro.md for the Triton track, 04_CUDA_and_System_Optimization/intro.md for the CUDA track, and topic_discussion/intro.md for the topic index. Individual route pages sit under topic_discussion, for example topic_discussion/inference_optimization/intro.md with its casebook.md alongside. team_study/intro.md is described as a place for study-group records. Treat dependency versions as something to verify yourself before relying on any timing or memory measurement in a notebook. The README claims experiments use real GPUs and inference backends; it does not specify which GPU models or driver versions, so any number you see in a notebook is only meaningful next to the hardware it was produced on.
Where it stops short: unfinished parts and language scope
Part 04 is explicitly 建设中, under construction. The operator and compiler optimisation route is also marked in progress. Part 05 is reserved with no content. If your goal is CUDA C++ kernel work, the repository does not yet deliver it, and the README says so rather than hiding it. The second constraint is language. The project description and README are Chinese-first, with an English version section in the README but lesson content that appears to be Chinese. For an English-speaking engineer this is a reading-comprehension tax on every explanation, even though the code and kernel names are language-neutral. The third constraint is maintenance shape. The last push recorded is 2026-09-03 and the repository has no published GitHub releases, so there is no versioned snapshot to pin against. Updates arrive as commits to notebooks, which means a lesson you validated last month can change under you. That is normal for teaching material and unusual for anything you would build on.
How it differs from a kernel-focused course or a framework's own tutorials
The obvious comparison is a single-layer resource: either a PyTorch tutorial series that never leaves eager mode, or a Triton or CUDA course that assumes you already know why the kernel matters. This repository deliberately spans both ends, with Part 01 supplying the hardware and memory reasoning that motivates the kernel work in Parts 03 and 04. Compared with framework documentation, which is organised by API surface and optimised for lookup, this is organised by learning sequence and optimised for working through problems in order. Compared with a pure kernel course, it keeps the model-level context: attention variants, decoding strategies, quantization schemes and parallelism strategies all appear before their low-level implementations. The difference in approach is that the exercise is the unit of learning here, not the API reference. The weakness of that choice is discoverability. If you already know what you need, a tutorial curriculum is a slower route than reading the framework docs for the specific operator.
Licence status and what to check before reuse
The repository metadata reports NOASSERTION for the licence, which means no standard licence identifier was detected. If you intend to reuse notebook code in your own project, copy exercises into internal training material, or redistribute translated versions, resolve this first by reading the repository's licence file directly. I am not giving legal advice here; the point is that NOASSERTION is not the same as permissive, and the difference matters more for a repository whose value is its content rather than its code. For individual study the question is academic. For anything that ships, it is a blocker until you have read the actual terms. The same applies to any third-party code embedded in the notebooks.
Editorial conclusion
Adopt this if you are already comfortable with Python and PyTorch and want a structured path from Transformer implementations through Triton kernels toward CUDA, or if you are assembling a study group around LLM systems work. Do not adopt it if you need an English-language reference, a maintained library you can import, or complete CUDA material today: Part 04 is marked as under construction and Part 05 is a placeholder. Before committing, open 02_PyTorch_Algorithms/intro.md and one notebook in 03_Triton_Kernels, confirm the notebooks run against your PyTorch and Triton versions, and check the repository licence file directly, since the metadata reports NOASSERTION rather than a named licence.
Frequently asked questions
Where should a beginner start in llm-algo-leetcode?
The recommended route starts at Part 02 for PyTorch algorithm practice, then backfills Part 00 and Part 01 as needed, then moves to Part 03 for Triton kernels and Part 04 for CUDA. Part 00 and Part 01 are treated as reference material rather than a gate.
Which parts of llm-algo-leetcode are finished?
Part 00 prerequisites, Part 01 hardware and systems, Part 02 PyTorch algorithms and Part 03 Triton kernels are marked complete and still being refined, while Part 04 CUDA and system optimization and Part 05 integrated projects are marked under construction.
Which llm-algo-leetcode topic routes are still being written?
Performance optimization, operator optimization and post-training optimization are unfinished main routes, and the multimodal and deployment with heterogeneous systems topics are also unfinished, while quantization, communication and parallelism, memory optimization and performance analysis are marked complete.
How do I install the environment for llm-algo-leetcode?
Three paths exist: requirements.txt including requirements/base.txt and requirements/dev.txt, and two conda environment files, environment.yml and environment-gpu.yml. The repository root also carries verify.py, which is the file to run to check the assembled environment.
What license does llm-algo-leetcode use?
The repository ships both a LICENSE and a LICENSE-CODE file at the root, which separates content from code, while the repository metadata reports no recognised license, so tooling that reads the API will not see one.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/datawhalechina-llm-algo-leetcode)Star history chart for your README
[](https://hysenlabs.com/projects/datawhalechina-llm-algo-leetcode)Was this useful?