OKF Agent Memory keeps a 150 token codex in the prompt and everything else in a git directory
Git-native persistent memory for AI coding agents. Implements Google OKF v0.2 with sub-300µs in-memory BM25 search, embedded MCP server, and progressive disclosure. Slashes token bloat by 80% with zero external databases or dependencies. Built in pure Go.
At a glance
- What is it?
- A Go CLI plus a plain text knowledge bundle that gives agents a small always loaded rule set and a pull layer that costs nothing until it is searched. The design is well argued, and the dependency claim, the asset duplication and the self reported benchmark numbers are worth reading closely.
- Who is it for?
- Treat it as a file format with a linter attached, not as a memory service. The push layer is a conventions file you can read in one sitting, the pull layer is a directory of markdown that git already knows how to review, and the two are only as good as the bundle you put in the knowledge directory yourself.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
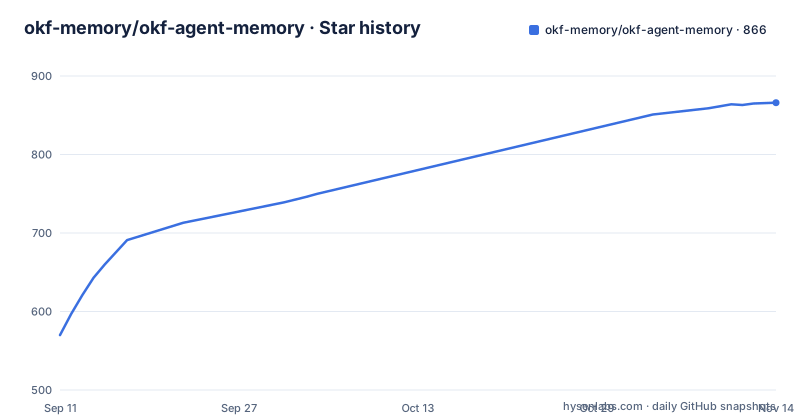
- okf-memory/okf-agent-memory866 ★ · +296
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| okf-memory/okf-agent-memory | 570 | 866 |
296 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The push layer is budgeted at about 150 tokens
Everything the agent always has to obey is meant to fit in roughly 100 to 150 tokens. That budget covers a canonical AGENTS.md holding project invariants, tone and guardrails, written in a micro-syntax called Agent Action Grammar, plus a short memory bridge whose only job is standardized triggers that force a search before a write. The grammar has its own RFC in docs/spec, and the savings claimed for using it against equivalent natural language prompt instructions are 78 to 85 percent. The architecture name for the pair is DMAA, the dual memory agent architecture, and the rule that the knowledge bundle costs zero tokens at baseline follows directly from the split: nothing from knowledge/ is loaded until a query asks for it.
The diagram that spells the two layers out is not complete. Its push subgraph names four boxes, the AGENTS.md codex, the domain codex for invariants, ethics and tone, the memory bridge with its deterministic triggers, and the AAG micro-syntax. The pull subgraph gets as far as a fourth box whose label starts with the words Persistent G and then ends, so the final element of the pull layer is a half printed caption in the file rather than a node anyone can read.
Two named failure modes justify the whole split
The argument for not just appending a memory store to an existing agent setup starts from two named problems. The first is called the prompt monolith: piling every domain rule into AGENTS.md or CLAUDE.md until the file bloats the context and the agent starts ignoring instructions that matter. Attention drift is the word used for that. The second is the RAG blindspot, and it is the more interesting of the two, because it is an argument against retrieval rather than for it. Behavioral rules pushed into a vector database fail, since an agent working on an unrelated task does not run a semantic search to discover that a formatting rule or a security rule applies to the file it is about to touch. The retrieval query never gets written.
That argument is why the project insists on deterministic triggers instead of hoping the model will decide to look something up. It is also why the repository ships AGENTS.md and CLAUDE.md at its root alongside .cursorrules and .windsurfrules, four agent configuration files in one repository, which is the arrangement the prompt monolith argument warns about in a project that has not yet solved the problem for itself.
The pull layer is markdown and an index graph
Domain knowledge lives in a knowledge/ directory holding an OKF v0.2 bundle, consumed zero tokens at baseline and queried on demand. Selection is meant to be narrow: an agent pulls the exact concept it needs through okf_search and okf_show rather than loading a summary of everything known. The mechanism named for that narrowing is progressive disclosure, built from hierarchical index.md files and link graphs, so a file can point at exactly the concepts underneath it and nothing else has to be read.
The format is the part that is not this project's invention. It builds on Google's open OKF v0.2 specification and carries three pieces of metadata that matter for trust: provenance under sources, trust tiers separating generated from verified material, and lifecycle fields status and stale_after. A concept that has gone out of date is meant to be marked rather than silently re-read, and the drift check in the validation command is what notices when the prose and the file disagree. The examples that ship with the repository span three unrelated domains, books, coaching and software, which is the concrete form of the domain neutral claim.
One command is the gate the rest of the design leans on
The entry point for checking a bundle is short:
# Validate bundle conformance, graph connectivity, and description drift
./bin/okf validate knowledge --strict --drift
Three things happen in that one invocation, and each answers a different failure. Conformance checks that the files satisfy the format. Graph connectivity checks that concepts link to each other in a way an agent can actually walk. Drift checks descriptions against the concepts they describe, which is the part that interacts with the lifecycle metadata, since a stale_after date and a description that has quietly drifted apart are the same problem seen from two directions. The strict flag is what makes this worth running in automation rather than by hand.
The search and inspection commands sit next to it:
# Search concepts via in-memory BM25 scoring
./bin/okf search "architecture layers" knowledge

# Inspect a concept and its relationships (with --json support)
./bin/okf show architecture/layers knowledge --json
The knowledge directory is a positional argument in both, not a configured path, which means a repository can carry more than one bundle and a script can point each command at whichever one it means.
Search before write turns a file path into a query
The governance mechanism is one flag:
# Discover constraints and active holds governing a specific source file before editing
./bin/okf search --for-path pkg/okf/types.go knowledge
Instead of searching for a topic, you hand it a source file and it returns the constraints and active holds that govern that file. The binding between decisions and code is done with code_refs recorded in the bundle, so a rule can name the files it applies to and be surfaced by path. The stated purpose is to be run before modifying code, not occasionally during a review.
That is a different shape from topic search and it is the piece that makes the earlier argument work. A vector store can match on meaning, but a path lookup is exact, so a rule that says a file may not be edited without updating its paired knowledge file can be attached to that file and returned every time, whether or not the agent thinks to look. The same logic runs the other way, in that the search before write principle tells an agent to query existing memory before authoring anything, which is presented as the defense against duplicated concepts and against two agents writing divergent copies of the same fact.
Zero dependencies in the description, one module requirement in go.mod
The project description says zero external databases or dependencies, and the benchmarks rest on being built in Go with no external dependencies. The module file says something narrower. It requires go 1.26.0 and pulls one module, golang.org/x/crypto at v0.57.0, with golang.org/x/sys at v0.48.0 arriving as an indirect requirement. So the no dependency claim holds in the sense that matters for the argument being made, there is no database, no service, no client library and nothing that reaches a network at query time, but it is not literally an empty require block and the wording does not draw that line.
Everything else in the module graph supports the narrower reading. The CLI is built to a single binary, the search path is an in memory index, and the whole knowledge payload is text in a directory that git already tracks. There is also no separate plugin or client package to install, the server is embedded in the same executable that does validation and search.
The skills are copied into the binary by hand, and the test suite checks
The Makefile reveals a duplication the overview does not mention. Active skill files live in .agents/skills/, and a target named sync-assets copies them into an embedded location inside the package:
@mkdir -p pkg/okf/assets/skill
@cp -R .agents/skills/okf-memory/* pkg/okf/assets/skill/
So the same skill content exists in two places, one as files an agent can read and one as assets the binary can write out on a new project. Nothing in the build runs that copy automatically, which means a change to a skill in .agents/skills does not reach an embedded copy until someone runs the target. The test target compensates: it runs the race detector across the tree and is described as including a dogfood asset drift check, so a stale embedded copy is meant to be caught by go test rather than by the compiler.
The same file stamps build metadata at link time, with LDFLAGS setting main.Version, main.Commit and main.Date, where the version defaults to the literal string dev unless a release overrides it and the commit falls back to none when git is unavailable. Release builds add -s -w. One more oddity: the phony target list carries three jules-prefixed targets, jules-list, jules-review and jules-merge, with no explanation anywhere in the file for what invokes them.
The comparison table measures something the project is not competing with
The benchmark table sets the library against two columns, Python and vector database runtimes named Mem0 and Letta, and Deno or Node.js tooling. Concept search latency reads 150 to 800 milliseconds for the first column, 40 to 120 for the second, and under 300 microseconds here, with the footnote that this is in memory BM25. Full corpus parse and graph validation is about 4 milliseconds for 50 or more concepts across a bidirectional graph. Cold start is under 4 milliseconds for a compiled single binary against 250 to 600 milliseconds of Python VM boot. Memory footprint is given as under 15 MB resident against 120 to 350 MB.
Read carefully, the column being compared is not the same kind of thing. A vector store pays its latency in an embedding call over the network on every query, and this one pays nothing, so the gap measures the cost model of local lexical retrieval against remote semantic retrieval rather than the quality of either. The self reported figures are not reproducible from the table alone, though a runner exists: make benchmark and a benchmark suite directory, targeting local models under LM Studio or Ollama with Gemma, Qwen or Llama, to check time to first token and the token reduction claim. The release history is short and recent, v0.5.0 on 2026-10-01, v0.4.4 on 2026-09-27 and v0.4.3 on 2026-09-23, with the last push on 2026-10-01.
Editorial conclusion
Treat it as a file format with a linter attached, not as a memory service. The push layer is a conventions file you can read in one sitting, the pull layer is a directory of markdown that git already knows how to review, and the two are only as good as the bundle you put in the knowledge directory yourself. Before adopting it, check three things: the go.mod requirement on golang.org/x/crypto against the zero dependency claim in the project description, whether you are willing to keep .agents/skills and pkg/okf/assets/skill in step by hand, and whether the sub 300 microsecond search figure matters to you at all, since it is measured on an in memory BM25 index rather than against the vector runtimes in the comparison table.
Frequently asked questions
How does OKF Agent Memory keep a project rule file small?
The always loaded part of AGENTS.md is budgeted at roughly 100 to 150 tokens and written in Agent Action Grammar, a micro-syntax with its own RFC under docs/spec, with claimed savings of 78 to 85 percent against equivalent natural language prompt text.
What does the okf binary do with a knowledge bundle?
The command ./bin/okf validate knowledge --strict --drift checks format conformance, graph connectivity and description drift, and other subcommands search concepts by topic or by source path and show a single concept with its relationships and JSON output.
Does okf-agent-memory need a database or an embedding API?
No database is required, retrieval is an in memory BM25 index and the cost row in the benchmark table reads 0.00 for a thousand queries, but the go.mod file does require golang.org/x/crypto v0.57.0, so the zero dependency wording is narrower than it reads.
How does the knowledge bundle record that something is out of date?
The OKF v0.2 format carries lifecycle metadata including status and stale_after, alongside sources for provenance and trust tiers that separate generated from verified, and the drift check in the validate command is what compares descriptions against the concepts they describe.
Why do the skill files exist in two places?
Active skills live in .agents/skills/ and the Makefile target sync-assets copies them into pkg/okf/assets/skill so they can ship inside the binary, with the go test target described as including a dogfood asset drift check to catch a copy that was not refreshed.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/okf-memory-okf-agent-memory)Star history chart for your README
[](https://hysenlabs.com/projects/okf-memory-okf-agent-memory)Was this useful?