google-maps-scraper's repository contains no source code at all
Google Maps Scraper & Lead Generation Tool. Extract 50+ data points including business emails, phone numbers, and social profiles. Includes enrichment features, API access, and no recurring fees
At a glance
- What is it?
- A commercial desktop app for pulling business listings off Google Maps, whose GitHub repository holds ten entries and not one of them is source code. The README is a landing page with two dead badges, a sales-funnel template marker left in the text, three authoring notes still commented in place, and three different figures for results per search.
- Who is it for?
- google-maps-scraper suits someone who wants business contact lists from Google Maps today and is willing to install a closed desktop app on a machine with Chrome, having checked that collecting and emailing those contacts is lawful where they are. It does not suit anyone who needs to audit, extend or self-host the tool, because the repository contains no source and no releases.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 7 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
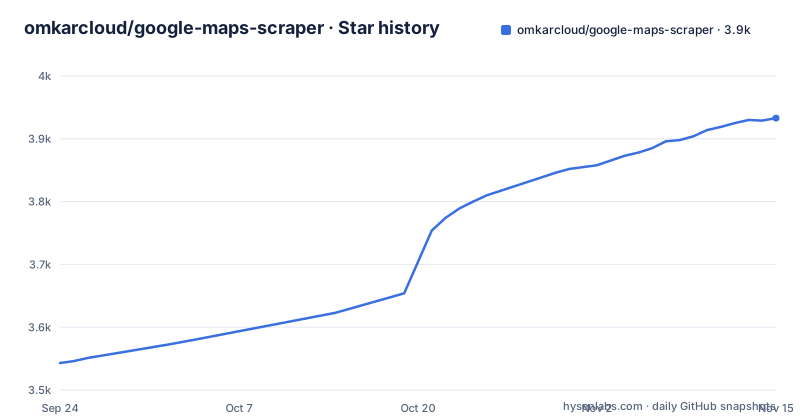
- omkarcloud/google-maps-scraper3,933 ★ · +390
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| omkarcloud/google-maps-scraper | 3.5k | 3.9k |
390 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Ten repository entries and no source code
The most important fact about this project is visible in its file listing and appears nowhere in its documentation. The repository root holds ten entries. A licence file, a README, a security policy, two documentation files, a screenshots directory, a deployment document, a video script, a gitignore, and a macOS directory-metadata file that should never have been committed. There is no source directory, no build file, no package manifest, no test directory and no release. The repository also records no primary language, which is consistent with a tree that contains nothing a language detector could classify. So the GitHub project is a landing page for a commercial desktop application that is downloaded from the vendor's own site, not the software itself. That distinction decides how you should evaluate it. You cannot read the code, you cannot check how it identifies itself to the platform it is reading from, you cannot build it yourself, and there is no version history beyond the README's own revisions. The two documentation files and the deployment note are the only substantive artefacts, and they are prose.
Two of the three badges point at nothing
The header of the README carries a row of three badges, and the first two of them are anchors whose target is the hash character, which navigates nowhere. Only the third resolves, and it points at the repository's issue tracker. So a reader arriving at the page sees three badge graphics where two are decorative and one is a dead link dressed as a link. This is the pattern the rest of the file follows. Two download buttons appear at different points in the page and both go to a vendor URL rather than to a release on the repository. The video embeds are external. The result downloads are external. And the one place the file claims the project is the most popular of its kind on GitHub is supported by no link at all, just a star count in the text. For a project whose entire public presence is this page, the broken links are not a cosmetic detail: they are the difference between a reader who can evaluate the offer and one who has to take it on trust.
The page states two different star counts
An internal inconsistency worth naming because it is the kind of number people quote. Near the top, the file describes the project as the most popular Google Maps scraper app on GitHub with 3.6K+ stars. Further down, in the benefits list, the same claim is repeated as the most popular Google Maps scraper app on GitHub with 3.5K+ stars. Both figures are in the same document, unlabelled as to when they were measured, and they disagree. The same list also carries a review-platform rating with the number of reviews that produced it, 31, which is a sample small enough that the figure moves easily. None of these numbers says anything about whether the tool works, and a page that leads with them is telling you something about its priorities. What they do tell you, reliably, is that the file is assembled from sections written at different times and assembled without a pass to reconcile them. The search-strategy section carries the same fingerprint: three different stated yields per search, which is the subject of a later section.
Three different figures for results per search
Put the numbers side by side and the page contradicts itself three times over on the one quantity it sells. The pricing comparison says the free allowance is 200 searches a month at 100 to 1,000 or more results each. The search-strategy section says the default mode returns 120 to 1,600 results per city. The results section says three searches produced 14,979 restaurants in New York City and 5,868 gyms in Delhi, which is 20,847 results from three searches, or roughly 6,949 per search. That demonstrated yield is several times the top of the range quoted in the pricing comparison, and the strategy section's figure is per city rather than per search, which may or may not be the same unit. The comparison with the named commercial service is internally consistent arithmetic: a stated free credit said to be worth about 1,250 leads, against 20,000 free leads a month, is sixteen times. But it reaches that ratio by taking the bottom of the stated range for this tool, so the honest range of the ratio runs from sixteen times to something a hundred times larger depending on where in the range a given city lands. The headline number is the conservative end of the comparison's own uncertainty.
The public API packages carry a different product's name
The README has a short paragraph aimed at developers, and it is where the identity confusion gets sharp. It says the app has a built-in API, and it names the pieces: an npm package and a Python library, both of which are called after a different product entirely, a name that has nothing to do with Google Maps or with the extractor. It also says the API can run on virtual machines on two cloud providers, linking a deployment document in the repository. That last point is the one that reconciles the repository with the product: the deployment note is the only artefact here that describes how the thing actually runs, and it is the only one a developer could act on. The practical consequence of the naming is straightforward. Someone looking for this tool's programmatic interface will search for the tool's name and find nothing, because the packages are published under the other name. A second, smaller version of the same problem appears in the data section, where the link to the full field list is labelled with a question about usage limits rather than with the name of the document it points at.
The usage-limits question is linked and never answered
The most consequential question for anyone scraping a platform at volume is how much you may do before something breaks, and the README links that question without answering it. The line offering the full list of data points points at a document in the repository, and the visible text of that link is a question about whether there are usage limits, followed by an anchor into the section that would answer it. So the field list and the rate-limit answer live in the same section of the same document, and the README declines to summarise either. What the README does give you instead is throughput, expressed per city rather than per request, with the default mode taking between one and ten minutes per city, the fastest mode about thirty seconds per city at the cost of thirty to forty fewer results, and a warning that on the detailed mode a large city can take more than two hours unless a maximum-results setting is lowered. Those are completion times, not request rates, and they tell you nothing about what happens when the platform notices. Nothing in the visible text addresses that, which for this particular class of tool is the first question to answer.
The collected data covers named individuals, not only businesses
The stated users are founders looking for customers and students gathering data for research projects, and the per-business fields are ordinary: name, main category, address, phone, website, rating and review count. The enrichment section is where the scope changes. It is described as providing verified emails, decision-makers such as a chief executive or a founder, and phone carrier information, with the stated purpose of not wasting time on landlines. Phone carrier lookup identifies the network a personal number sits on, and a decision-maker contact is a named individual rather than a company. So the deliverable is not only a list of businesses with switchboard numbers; it is a list of people with reachable personal contact details, gathered at volume. The README's own framing of the data as public sits alongside that, and public availability of a listing is not the same question as whether bulk collection and outreach to named individuals is permitted where you are. Nothing in the visible text addresses it, and since the software is closed you cannot inspect how the enrichment sources are obtained.
Five search strategies, and one of them walks map tiles
The search-strategy section is the most technically informative part of the page, and it describes five modes rather than one. Two are speed variants of the same approach, a default mode trading speed for a stated yield of 120 to 1,600 results per city in one to ten minutes, and a fastest mode at roughly thirty seconds per city for about thirty to forty fewer results. A third, detailed, returns more than the default and takes considerably longer, with an explicit recommendation against it for country-level runs and a tip to cap results per city so that a large city does not take hours. The fourth is the interesting one: by zoom level, at levels 15 through 18, which the file maps to neighbourhood, sub-neighbourhood and block level. That is not a search query at all. It is a walk of the map's own tile pyramid, collecting whatever falls inside each tile at a chosen resolution, which is why resolution and completeness trade against each other and why a zoom level is the control rather than a query. The fifth mode is by geolocation. The list of what each level yields is cut off partway through the entry for the block level, so the ladder stops before its final rung is described.
Editorial conclusion
google-maps-scraper suits someone who wants business contact lists from Google Maps today and is willing to install a closed desktop app on a machine with Chrome, having checked that collecting and emailing those contacts is lawful where they are. It does not suit anyone who needs to audit, extend or self-host the tool, because the repository contains no source and no releases. Before adopting, establish the terms under which the platform permits this kind of collection, since the README asserts the data is public and says nothing else about it, read the usage-limits answer in the linked document rather than the README, which links the question without answering it, and check whether the data you collect includes named individuals, because the enrichment described covers decision-makers and phone carriers as well as businesses. There is no GitHub release and the last push was on 2026-09-21.
Frequently asked questions
what is google maps scraper
The README describes a desktop app that finds business profiles on Google Maps for a category and location you choose, then exports names, main categories, addresses, phone numbers, websites, emails and social profiles, plus ratings and review counts. It claims 50 or more data points in total and calls the underlying data public.
how to use google maps scraper
Have Google Chrome installed, download the app from the vendor's site, enter a search query and press the Run button. There is no documented command line. Five search strategies are offered: a default Fast mode, a Fastest mode, a Detailed mode, a By Zoom Level mode at levels 15 to 18, and a By Geolocation mode.
how to install google maps scraper
Not from the repository, which holds no source code and no releases. The documented route is to install Google Chrome and then download the desktop application from the vendor's own download page. A separate npm package and Python library exist for the built-in API, but both are published under a different product name.
is google maps scraper free
There is a free allowance the README puts at 200 searches a month with no credit card, at a stated 100 to 1,000 or more results per search, which it turns into 20,000 or more free leads a month. Beyond that there is a paid tier, and the README links a question about usage limits without answering it.
what is the best google maps scraper
The README argues against two named commercial services on price and states its own comparison as sixteen times more generous free allowance than one of them, worked out from a stated free credit and a stated result count. It offers no benchmark, and its own results section shows a higher yield per search than the pricing comparison claims.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/omkarcloud-google-maps-scraper)Star history chart for your README
[](https://hysenlabs.com/projects/omkarcloud-google-maps-scraper)Was this useful?