onnxmltools: nine toolkits listed, two of them wrappers, one example from 2018
ONNXMLTools enables conversion of models to ONNX
At a glance
- What is it?
- ONNXMLTools converts models from nine machine learning toolkits into ONNX, and for two of those it is a thin wrapper around another converter. It is a small package with a precise convention for adding converters and a genuinely subtle rule about operator set versions. Its documentation has drifted in three specific places: the Python floor, the two dependency files, and a test command that ignores the test directory with a Windows path.
- Who is it for?
- Take ONNXMLTools if you are converting from one of the listed toolkits and you want a single import that routes to the right converter, especially for scikit-learn and Core ML where the underlying work is done elsewhere.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 14 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
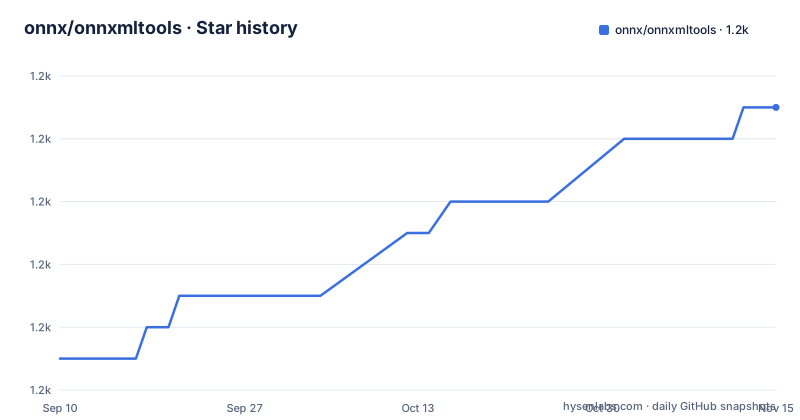
- onnx/onnxmltools1,177 ★ · +8
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| onnx/onnxmltools | 1.2k | 1.2k |
8 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Nine toolkits in the list, and two of them are wrappers around other converters
The introduction lists what the package converts, and the list is nine entries long.
TensorFlow and scikit-learn are the two that are not implemented here. Both are described as wrappers: one around the tf2onnx converter, one around the skl2onnx converter, each with a link to its own repository. Apple Core ML, Spark ML marked experimental, LightGBM, libsvm, XGBoost, H2O and CatBoost are the rest.
PyTorch is the tenth framework everyone thinks of, and it is absent on purpose. The page says PyTorch has its own built-in ONNX exporter and links to that documentation instead.
So the bullet list overstates the surface in one direction and understates it in another. Two of the nine delegate to a different project, one framework is delegated away entirely, and one of the remaining seven is marked experimental rather than supported.
What that means in practice is that a dependency question has a different answer depending on which toolkit you convert from. scikit-learn users need the scikit-learn converter's own dependency tree, Core ML users need a conversion tool with a version ceiling, and the gradient boosting frameworks are the ones this package actually implements.
The description field in the manifest is blunter than the prose: it converts machine learning models to ONNX, full stop.
The README says Python 3.7+, the manifest requires 3.9, and the classifiers stop at 3.13
Three Python stories, in three places, and they do not agree.
The README states that the package is tested with Python 3.7 or newer. The project manifest requires 3.9 or newer. The classifier list in the same manifest runs from 3.9 to 3.13.
So the prose promises a floor two minor versions below the one the packaging enforces, and the packaging claims support up to a version that a reader on the newest Python would infer from the prose but not from the metadata. The version that actually gates an install is 3.9, because that is what the manifest says and what the installer will enforce.
This is a small thing that has been small for a while, and small documentation drift of this kind is common in projects with a long history. It matters here because the whole point of a conversion package is that it runs in the same environment as the model you are converting, and the environments in question are usually somebody else's requirements file.
The development status in the manifest is Beta, which is the other version-ish signal on the page and is consistent with a package that works and is not finished.
Two dependency files, and one of them is missing two of the four declared packages
The repository carries a manifest and a requirements file, and they are not the same list.
The manifest declares four runtime dependencies: NumPy, ONNX with a floor of 1.8.1, Protobuf, and the scikit-learn converter with a floor of 1.4.9. Two of those carry a version floor and two are bare.
The requirements file contains two lines. NumPy and ONNX, both without a floor.
So Protobuf and the scikit-learn converter are absent from the requirements file entirely, and the ONNX floor is absent from both the requirements file and the prose. A source install that follows the README's install command will pull the manifest's list, because the packaging metadata drives it. A contributor who installs from the requirements file instead gets NumPy and ONNX with no floor and no scikit-learn converter, which is the dependency this package wraps for one of its two wrapper toolkits.
There is also a development requirements file and a coverage configuration in the root, neither of which the README mentions, and a package-data setting that includes everything under the package directory, which is a broad choice for a converter library that ships operator tables.
The prose dependency list adds one constraint worth noticing, because it is the only upper bound in the whole document: the Core ML conversion tool is capped at version 3.1 or lower, while the Keras requirement is a floor of 2.0.8 with the matching TensorFlow version. Everything else is unpinned in both directions.
A source install needs an environment variable set before a different package is installed
There are two install commands, and they are the only two commands on the page.
pip install onnxmltoolsfor the latest release from the package index, or a source install from the repository:
pip install git+https://github.com/onnx/onnxmltoolsAnd then one sentence that changes what the source install means. If you install this package from its source, you must set the environment variable ONNX_ML before installing the ONNX package.
That is an install-order dependency on a third-party package, stated once, in a sentence with no explanation of what the variable does. If you install the ONNX package first, which is what happens if ONNX is already in your environment, the variable has nothing left to influence, and nothing on the page tells you how to tell whether it took effect.
It is a fair criticism to say that this is the kind of instruction that belongs in the installation section as a step rather than a footnote, and that a contributor would benefit from knowing which part of ONNX's own build the flag turns on. What the page does give you is the fact, which is more than most projects bother with.
For everyone else, the index install is one command and needs nothing else.
The documented test command ignores the tests directory, using a Windows path
The section on running the converters gives one command:
python -m pytest --ignore .\tests\That is meant to exclude the tests directory, which means running the command as printed does the opposite of what the surrounding text describes. On Windows the path separator is correct and pytest is told to ignore the directory, so the run collects no converter tests. On Linux and macOS the backslashes are part of a single literal filename that does not exist, so the ignore does nothing and pytest collects everything, which is the behaviour you probably wanted in the first place.
Either reading leaves the command wrong, and neither is what the text above it describes.
The rest of the testing story is better specified. Every converter unit test generates both the original model and the converted one, and checks them automatically against a runtime, with the graphics build of that runtime named as an alternative. Extra packages are needed for the suite: one for text feature transforms, one for sparse features, one for a custom operator test, and whichever machine learning library the model came from.
The pytest configuration in the manifest is also unusual in a way worth knowing before you interpret a red build: it caps the run at ten failures and prints the ten slowest tests. A converter library that gives up after ten failures is choosing to report rather than to block, which is a defensible choice for a suite with this many optional backends.
Adding a converter has a two-file convention that is the most useful thing on the page: a unit test that must call the data and model dump function at its end, and a matching test in the backend test suite that computes the prediction with the runtime.
The operator set rule is right, and its worked example is dated December 2018
This is the part of the documentation that earns the package its keep, and it is explained properly.
If you need the converted model to work against a particular ONNX version, you pass a target opset to the convert function. The page then warns you about the thing that surprises everyone: the resulting model can come out with a lower opset than you asked for, and that is intended. The converter works by converting each operator individually and finding the opset version in which that operator was most recently updated. Once every operator is converted, the model gets the highest opset among them. The stated reason is backwards compatibility.
The illustration is a two-operator model, Abs and Add. Abs was most recently updated in opset 6, Add in opset 7, so that model is opset 7 even if you request 8. And the illustration is stamped as of December 2018, which puts the specific operator versions eight years behind a package that requires a recent ONNX and a manifest floor of 1.8.1.
The mechanism has not changed, but the numbers in the example have. A reader who takes them literally and checks them today will find that Abs and Add have been updated in later opsets, which is exactly the confusion the section is trying to prevent.
How to check what you actually got is given twice, once with a viewer and once in one line of code:
opset_version = onnx_model.opset_import[0].versionThe Keras example stops mid-comment, and the H2O example carries a Core ML comment
Two documentation defects, both small and both in the code examples.
The Keras example is the first conversion shown and it is the one that sets the target opset, using a value that the page maps to an early ONNX release. The snippet ends on a half-written comment, at the point where it was about to define the final model from its sub-models. So the flagship example on the page is truncated, and a reader has to reconstruct the last step themselves.
The H2O example is complete and correct apart from its comment. The line above the conversion call says to convert the Core ML model into ONNX, in an example that takes an H2O MOJO archive. That comment is a copy-paste leftover from the Core ML example immediately above it.
Both are the kind of thing a maintainer fixes in a minute, and both are the kind of thing a reader notices in the first five minutes, which is the expensive kind.
Around them the rest of the repository is tidy. There is a documentation directory, a tests directory, a development requirements file, a coverage configuration, a manifest file for packaging, and a changelog whose filename carries an extra letter at the end of the word.
The release history is where to look for the same kind of drift. The two older tags are prefixed with a v and the newest one is not, which is a naming change that happened between January 14 and January 30 of this year and will confuse any script that resolves tags by prefix.
Editorial conclusion
Take ONNXMLTools if you are converting from one of the listed toolkits and you want a single import that routes to the right converter, especially for scikit-learn and Core ML where the underlying work is done elsewhere. Leave it if you convert from PyTorch, because the page sends you to PyTorch's own exporter, or if you need the conversion to land on a specific operator set version, because the tool deliberately gives you the highest opset its operators support rather than the one you ask for. Three things to check before you rely on it: which Python you are on, since the manifest requires 3.9 while the README claims 3.7, whether you installed from source and therefore whether the ONNX_ML variable was set before the onnx package was installed, and whether the source install used the manifest or the two-line requirements file, since the second is missing two of the four declared dependencies.
Frequently asked questions
What does onnxmltools convert?
Models from nine toolkits into ONNX: TensorFlow and scikit-learn, both of which are wrappers around the tf2onnx and skl2onnx converters, plus Apple Core ML, Spark ML marked experimental, LightGBM, libsvm, XGBoost, H2O and CatBoost. PyTorch is not in the list because it has its own built-in ONNX exporter.
Which Python versions does onnxmltools support?
The project manifest requires Python 3.9 or newer and its classifiers cover 3.9 through 3.13. The README says the package is tested with Python 3.7 or higher, which does not match the manifest, and the manifest marks the project as Beta.
How do I install onnxmltools?
`pip install onnxmltools` for the latest release, or `pip install git+https://github.com/onnx/onnxmltools` from source. The source route also requires you to set the environment variable ONNX_ML before installing the onnx package, which the README states without further explanation.
Why is my converted model's opset lower than the target I asked for?
Each operator is converted individually and mapped to the opset in which it was most recently updated, and the resulting model takes the highest opset among its operators. The README's illustration has Abs last updated in opset 6 and Add in opset 7, so that model is opset 7 even when target_opset=8 is requested. The behaviour was defined for backwards compatibility.
How do I check which opset a converted onnxmltools model uses?
Open the model in Netron, or read it in one line of Python with `opset_version = onnx_model.opset_import[0].version`. The README also shows a Keras conversion with target_opset=7, which it maps to an early ONNX release.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/onnx-onnxmltools)Star history chart for your README
[](https://hysenlabs.com/projects/onnx-onnxmltools)Was this useful?