vLLM: a Python and CUDA LLM serving engine whose speed comes from PagedAttention, batching and a long list of kernels
A high-throughput and memory-efficient inference and serving engine for LLMs.
At a glance
- What is it?
- vllm-project/vllm is an Apache-2.0 inference and serving engine for large language models, born in UC Berkeley's Sky Computing Lab. It ships an OpenAI-compatible server, many quantization formats and parallelism modes, and releases roughly every two weeks, with a release candidate already out for v0.33.0.
- Who is it for?
- vLLM is the pick when you need to serve open-weight models to many concurrent clients behind an OpenAI-compatible endpoint, on NVIDIA, AMD or another supported accelerator. It is a heavier choice for single-user local use, and its non-NVIDIA hardware support is described partly as plugins that you must verify per device.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
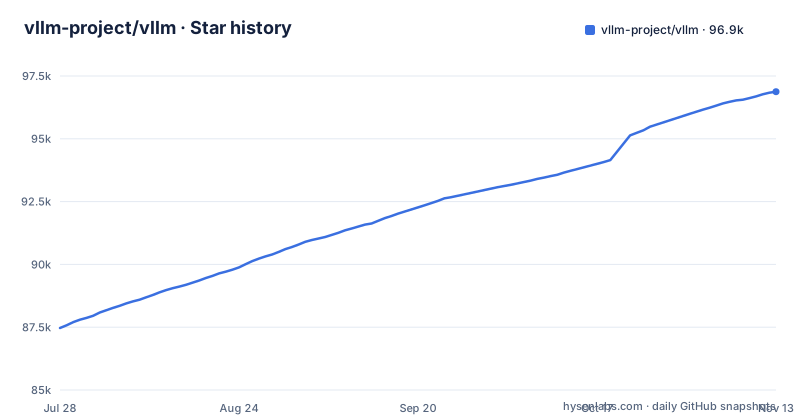
- vllm-project/vllm96,874 ★ · +9,406
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| vllm-project/vllm | 87.5k | 96.9k |
9,406 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
PagedAttention and continuous batching are the core of the throughput claim
The README lists what makes vLLM fast: state-of-the-art serving throughput, efficient management of attention key and value memory with PagedAttention, continuous batching of incoming requests, chunked prefill, and prefix caching. Fast model execution comes from piecewise and full CUDA and HIP graphs, and automatic kernel generation and graph-level transformations use torch.compile.
The design target is many concurrent requests on a shared GPU, where memory used by the key and value cache limits how many requests fit. That is why the project's founding paper is about memory management for LLM serving. The consequence is that vLLM pays off most under concurrent load. For a single user sending one prompt at a time, the batching machinery has little to batch, so the gain is smaller. The README gives no throughput figures in the text, so measure on your own workload.
Quantization and kernel support is broad, but each combination needs checking on your hardware
The quantization list covers FP8, MXFP8 and MXFP4, NVFP4, INT8, INT4, GPTQ and AWQ, GGUF, compressed-tensors, ModelOpt and TorchAO, with more in the documentation. Attention kernels include FlashAttention, FlashInfer, TRTLLM-GEN, FlashMLA and Triton, and GEMM and MoE kernels use CUTLASS, TRTLLM-GEN and CuTeDSL. Speculative decoding covers n-gram, suffix, EAGLE and DFlash, and prefill, decode and encode can be disaggregated.
These are lists of capabilities, not a compatibility matrix. A given quantization format may need a particular GPU generation or a particular kernel, and the README does not say which pairs work together. Before you plan a deployment around NVFP4 or MXFP4, confirm in the documentation that your model, quantization and accelerator are supported together.
Hardware beyond NVIDIA mixes native support and plugins
The README states support for NVIDIA GPUs, AMD GPUs, Intel GPUs, and x86, ARM and PowerPC CPUs. It then adds that diverse hardware plugins exist, naming Google TPUs, Intel Gaudi, IBM Spyre, Huawei Ascend, Rebellions NPU, Apple Silicon and MetaX GPU.
The consequence is that non-mainstream hardware is not a single install. A plugin may live in its own repository, with its own release schedule and its own list of supported models. If you target Ascend, Gaudi, TPU or Apple Silicon, read that plugin's documentation first and expect version pairings between it and vLLM itself.
The OpenAI-compatible server, tool calling and structured outputs share one endpoint
On the usability side, vLLM offers an OpenAI-compatible API server, plus Anthropic Messages API and gRPC support. It supports streaming outputs, tool calling and reasoning parsers, and generation of structured outputs using xgrammar or guidance. Decoding options include parallel sampling and beam search. Multi-LoRA is supported efficiently for dense and mixture-of-experts layers, and distributed inference can use tensor, pipeline, data, expert and context parallelism.
The practical effect is that OpenAI-client code can be pointed at a vLLM server by changing the base URL. Compatibility is described but not itemised, so test the specific features your application depends on, such as tool calling with your model's chat template. The repository's examples directory has chat templates for several models, including chatml, falcon, chatglm and alpaca styles, and folders for tool calling, reasoning, speech to text, pooling, reinforcement learning, scale-out, Ray serving, observability and disaggregated serving. Several of these folders map to features named earlier, such as the ray_serving and disaggregated folders. A recipes directory, a benchmarks directory and a docs folder complete the layout, so you can find a worked example for most deployment shapes before writing your own.
Install with uv and download kernels, and note the build-time torch pin
The README recommends uv, with pip as an alternative, followed by a command that downloads precompiled kernels:
uv pip install vllm
vllm download-kernels  # precompiled kernels for faster startup
Building from source is also documented, and the package requires Python 3.11 or newer but below 3.15. The pyproject build requirements pin torch to exactly 2.14.0 and ask for cmake 3.26.1 or newer, ninja, setuptools-rust and setuptools-scm. A Rust toolchain file and a rust directory sit in the repository, and setup.py handles a precompiled Rust frontend.
So a source build is a heavy step: a C++ and CUDA toolchain, a Rust toolchain and one specific torch. Unless you are developing vLLM itself, take the wheel and the downloaded kernels.
Releases come every two weeks, and the newest tag is a release candidate
The recent releases are v0.33.0rc3, tagged on 2026-11-02, then v0.32.0 on 2026-10-18 and v0.31.0 on 2026-10-05. The last push was on 2026-11-02 and the project is not archived. The pace is a new minor version about every two weeks, and the 0.x series means the interface can still change between them.
The release named v0.33.0rc3 is a candidate, not a final version, so a deployment that tracks the latest tag may land on a candidate. A candidate exists to be tested by users before the final version is cut, which is a useful role if you want early access and a poor one if you need stability. Pin to a final version such as 0.32.0 for production, and read the notes when you move up. The README describes a community of many dozens of academic institutions and companies and over 2000 contributors, which gives a sense of the rate of change in the repository.
Models: 200+ architectures, with the full list kept in the docs
vLLM says it supports more than 200 model architectures from Hugging Face. The categories are decoder-only LLMs such as Llama, Qwen and Gemma, mixture-of-experts models such as Mixtral, DeepSeek-V3, Qwen-MoE and GPT-OSS, hybrid attention and state-space models such as Mamba and Qwen3.5, multi-modal models such as LLaVA, Qwen-VL and Pixtral, embedding and retrieval models such as E5-Mistral, GTE and ColBERT, and reward and classification models such as Qwen-Math.
The complete list is on the supported models page, and a new architecture may need a release that adds it. If your model is brand new, check that page and the open issues before you assume it loads. Questions and feature requests go to GitHub Issues, discussion with other users goes to the user forum, development coordination goes to Slack, and security disclosures go through GitHub Security Advisories.
Editorial conclusion
vLLM is the pick when you need to serve open-weight models to many concurrent clients behind an OpenAI-compatible endpoint, on NVIDIA, AMD or another supported accelerator. It is a heavier choice for single-user local use, and its non-NVIDIA hardware support is described partly as plugins that you must verify per device. Before adopting it, check Python 3.11 to 3.14, test your exact model and quantization on your exact GPU, and pin a stable release instead of the release candidate.
Frequently asked questions
Why is vLLM so fast?
vLLM manages attention key and value memory with PagedAttention and uses continuous batching, chunked prefill and prefix caching. It also uses CUDA and HIP graphs, optimized attention and GEMM kernels, quantization and speculative decoding.
What is vLLM used for?
vLLM is used for LLM inference and serving. It offers an OpenAI-compatible API server with streaming, tool calling and structured outputs, and supports over 200 Hugging Face model architectures.
Does vLLM use PyTorch?
Yes. The pyproject build requirements pin torch to version 2.14.0, and the project uses torch.compile for automatic kernel generation and graph-level transformations.
Official sources
Where this project is recommended
- Open-source alternative to Together AI
- Open-source alternative to Replicate
- Open-source alternative to Mistral AI
- Open-source alternative to Hugging Face
- Open-source alternative to Groq
- Open-source alternative to Fireworks AI
- Comparison: llama.cpp vs vllm: single-machine inference versus data-center serving
- Comparison: sglang vs vllm: shared-prefix speed against serving breadth
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 7 in the last 30 days; newest first.
- Jensen is out. CUDA isn't. A Developer's Guide to Everything Nvidia Builtdev.to · Nov 13, 2026 · 7 points · 2 comments
- Six Serving Engines on Four Accelerators: Gemma 4 E2B on an RTX 3050, a T4, an L4 and a TPU v5edev.to · Nov 13, 2026 · 14 points · 1 comments
- Six Serving Engines on One Tesla T4: Gemma 4 E2B on a Turing GPUdev.to · Nov 11, 2026 · 4 points · 0 comments
- Six Serving Engines on One Cloud TPU v5e Chip: Gemma 4 E2Bdev.to · Nov 9, 2026 · 13 points · 2 comments
- Six Serving Engines, One 8 GB GPU: Gemma 4 E2B on an RTX 3050dev.to · Nov 8, 2026 · 20 points · 1 comments
- An 8B Agent That Thinks Without Writing Tokens Beats GPT-5.6 Luna on GAIA. Not on HLEdev.to · Oct 19, 2026 · 2 points · 1 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vllm-project-vllm)Star history chart for your README
[](https://hysenlabs.com/projects/vllm-project-vllm)Community discussions
Was this useful?