MMDetection's config system, its CPU-only build path, and the last push of 2024-08-21
GitHub describes it as OpenMMLab Detection Toolbox and Benchmark. The repository metadata lists Python as its primary language. The metadata lists the Apache-2.0 license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- MMDetection is an Apache-2.0 PyTorch detection toolbox whose four supported tasks are assembled from swappable components, not run from one model. It is a good fit for research engineers who already speak config, and a poor fit for anyone who wants a single pip install and a pretrained checkpoint with no assembly step.
- Who is it for?
- Adopt MMDetection if you are running detection experiments where swapping a component matters more than reaching a checkpoint today, and you can commit to a dependency chain that spans three repositories. Do not adopt it if you need vendor support, a maintained release train, or an install that resolves on its own.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Probably not. The repository last received commits 27 months ago, on August 21, 2024.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
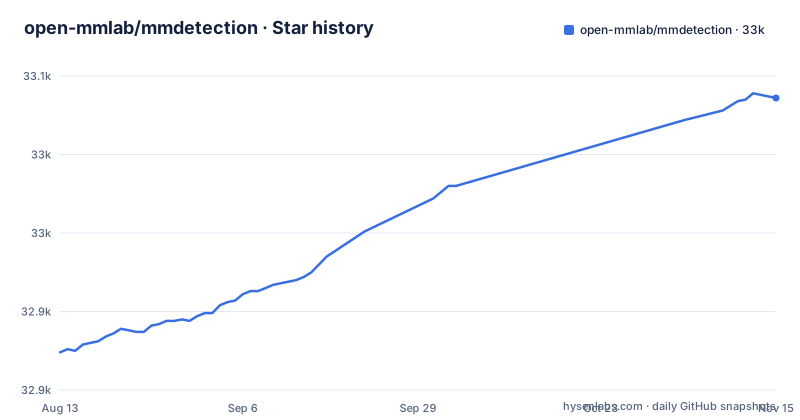
- open-mmlab/mmdetection33,036 ★ · +162
| Repository | 2026-08-13 | 2026-11-15 |
|---|---|---|
| open-mmlab/mmdetection | 32.9k | 33k |
162 Stars in the last 94 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four detection tasks sit behind one component registry
MMDetection ships object detection, instance segmentation, panoptic segmentation and semi-supervised object detection out of a single package, and the design point is that these are assembled from interchangeable pieces rather than written as four separate programs. The framework is decomposed into components, so a customised detector comes from combining modules. That targets research engineers who already know what a neck, a head and a bbox assigner are, and who want to replace one of them without forking everything downstream of it.
Two upstream packages do the underlying work. MMEngine handles model training, MMCV supplies the computer vision primitives, and neither is optional. The dependency surface is therefore three repositories wide,.
The feature list states that all basic bbox and mask operations run on GPUs.
Installation is a link, and requirements.txt names nothing
The Installation section of this repository is a URL rather than a set of commands. It points at the get_started page on mmdetection.readthedocs.io, and the Getting Started section does the same thing for the general introduction. If you came to GitHub expecting a pip line to copy, there is none to copy.
What ships in the tree is a requirements file with three includes and no package names, no version numbers, not even a mention of MMCV or MMEngine:
-r requirements/build.txt
-r requirements/optional.txt
-r requirements/runtime.txt
The version pins are not stated in requirements.txt itself. Read the Installation page before you build anything, and check what it asks the two companion repositories for. The practical consequence of this layout is that you cannot reconstruct a working environment from the repository root alone, and a colleague reproducing your setup has to be handed the same page rather than a requirements file.
setup.py quietly drops CUDA when torch.cuda.is_available() returns false
The build script settles its CUDA question before a single extension is defined, and the test is a plain runtime check with an environment variable escape hatch:
if torch.cuda.is_available() or os.getenv('FORCE_CUDA', '0') == '1':When that passes you get a CUDAExtension, the WITH_CUDA macro is defined, and the compiler receives three flags that disable half-precision operator overloads. When it fails, the script prints one line, Compiling {name} without CUDA, and falls back to a CppExtension with no CUDA sources attached.
That single print is the entire warning, and it is easy to scroll past in a long pip log. On a build machine where no GPU is visible, such as a container started without a device passed through, you get CppExtension builds with no CUDA sources attached. Set FORCE_CUDA=1 on a host that does have nvcc and torch, and the CUDA path is taken regardless of what the detection reports. Two things follow: the build host needs a working torch installed before pip reaches setup.py at all, and a green install tells you nothing about what got compiled in.
RTMDet's 322 FPS is TensorRT FP16 at batch size 1 on a 3090
One table in the README carries real numbers, and it belongs to RTMDet, a family of fully convolutional single-stage detectors. Object detection on COCO scores 52.8 AP at 322 FPS. Instance segmentation on COCO scores 44.6 AP at 188 FPS. Rotated object detection on DOTA scores 78.9 AP single-scale and 81.3 multi-scale at 121 FPS.
Read the column header before any of the figures. The header reads FPS(TRT FP16 BS1 3090). That is FP16 through TensorRT, batch size 1, one consumer GPU. It is not PyTorch eager on a workstation, and it is not a throughput number for a server chewing through batches, so if you are sizing a serving tier these numbers do not transfer without re-measuring through your own export path.
The rotated row carries two AP values because it reports single-scale and multi-scale separately, and the table does not say which of the two the 121 figure was captured with. The only speed figures in this README table are for RTMDet.
configs/ is the real interface and demo/ is where you see it run
The top level of the tree tells you how the project expects to be used. configs/ holds the per-model config files, and the README links into it for RTMDet and mm_grounding_dino. Alongside it sit model-index.yml and dataset-index.yml, which are machine-readable index files rather than prose, so downstream tooling can enumerate what is available without scraping a document.
The demo/ directory is the closest thing to a quick start that ships in the tree. demo/image_demo.py handles still images. The cases that usually break first have their own entry points: demo/large_image_demo.py for inputs too big to feed whole, demo/webcam_demo.py for live sources, and demo/mot_demo.py for multi-object tracking, which is a task the four the toolbox advertises does not include. demo/video_gpuaccel_demo.py is a separate path again, and demo/MMDet_Tutorial.ipynb with demo/MMDet_InstanceSeg_Tutorial.ipynb are the written walkthroughs.
Grounding DINO's training half was rebuilt, not ported
Version 3.3.0 shipped on 2024-01-05 with MM-Grounding-DINO as the headline, and pre-trained weights for the Swin-B and Swin-L backbones. The reason the project exists is a gap in the original work. Grounding DINO unifies 2D open vocabulary object detection with phrase grounding, but its training part was never open sourced. What MMDetection published is therefore a rebuilt pipeline rather than a port, and the recipe sits at configs/mm_grounding_dino/README.md.
Two consequences follow. Anyone hoping to reproduce the published Grounding DINO numbers by following the original procedure finds no procedure, because the data types had to be reconstructed and the results come from an open source replication that the project describes as exploring different dataset combinations and initialisation strategies. The evaluation also runs along several axes at once, OOD, REC, phrase grounding, open vocabulary detection and fine-tuning, and the write-up frames that spread as a way to expose the advantages and disadvantages of grounding pre-training.
Detectron2 appears only as a speed baseline
The training speed claim names Detectron2, maskrcnn-benchmark and SimpleDet, and says only that speed is faster than or comparable to those codebases. No table, no hardware line, no batch size accompanies it. Treat that sentence as a positioning claim rather than a measurement you can plan around.
The architectural contrast that does hold up is the one the comparison implies. MMDetection builds detectors from components described in config files, and the package needs MMEngine and MMCV sitting underneath it. A codebase you name as a speed baseline is being compared on throughput, not on how a model gets assembled, so the two axes are separate and the README only speaks to one of them.
The main branch stopped moving on 2024-08-21
The repository is not archived, and its last push was 2024-08-21. Releases came at a steady clip before that: v3.1.0 on 2023-06-30, v3.2.0 on 2023-10-12, then v3.3.0 on 2024-01-05, after which the release list stops while commits continued for another seven months. Nothing after 2024-08-21 is reflected here, which matters most for a framework whose compatibility statement is written against PyTorch 1.8+.
The main branch works with PyTorch 1.8 or later, and that line carries no upper bound. Newer PyTorch releases landed after the last push, so whether the combination still works is something you find out by building it, not by reading the repository. The release cadence you are inheriting is whatever the three upstream projects do.
Licensing is Apache-2.0, which permits commercial use and modification without a separate agreement and carries the usual notice and patent-grant terms. Any redistribution of the CUDA extensions MMCV contributes inherits that project's own licence, and nothing here is legal advice, so check the LICENSE file and MMCV's own terms before shipping a build.
Editorial conclusion
Adopt MMDetection if you are running detection experiments where swapping a component matters more than reaching a checkpoint today, and you can commit to a dependency chain that spans three repositories. Do not adopt it if you need vendor support, a maintained release train, or an install that resolves on its own. Verify first that the MMCV and MMEngine versions your environment already has match what the Installation page specifies, because requirements.txt at the repository root names none of them, and because a build that prints 'Compiling without CUDA' will still install cleanly while leaving every GPU op out of the wheel.
Frequently asked questions
How do I install MMDetection?
The repository carries no pip command. Installation is delegated to the get_started page on mmdetection.readthedocs.io, and the requirements.txt at the root only includes requirements/build.txt, requirements/optional.txt and requirements/runtime.txt, so the root file itself names no version pins.
Is MMDetection dead?
The repository is not archived and its last push was 2024-08-21, so it is not being worked on at the moment. The most recent release listed is v3.3.0 from 2024-01-05, following v3.2.0 and v3.1.0.
How do I use MMDetection?
Everything starts from a config file under configs/. For a first run, demo/image_demo.py takes still images, with video_demo.py, webcam_demo.py, large_image_demo.py and mot_demo.py covering the other input shapes, and demo/MMDet_Tutorial.ipynb walks through the steps.
What is MMDetection?
An object detection toolbox built on PyTorch and part of the OpenMMLab project. It covers object detection, instance segmentation, panoptic segmentation and semi-supervised object detection, and it depends on MMEngine for model training and MMCV for computer vision primitives.
What does COCO mean in MMDetection?
COCO is the dataset the RTMDet results are reported on. The table gives 52.8 AP at 322 FPS for object detection and 44.6 AP at 188 FPS for instance segmentation, both measured as FPS(TRT FP16 BS1 3090).
How does MMDetection compare with Detectron2?
Detectron2 is named alongside maskrcnn-benchmark and SimpleDet only as a codebase whose training speed MMDetection says it matches or beats. No figures are given for that claim, and the only speed figures in the README table are RTMDet's, on TensorRT FP16 at batch size 1 on a 3090.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/open-mmlab-mmdetection)Star history chart for your README
[](https://hysenlabs.com/projects/open-mmlab-mmdetection)Was this useful?