MMEngine: The Training Loop Behind OpenMMLab, With a BaseModel Contract and a PyTorch Support Table That Stops at 2.1
OpenMMLab Foundational Library for Training Deep Learning Models
At a glance
- What is it?
- MMEngine is the PyTorch training engine that every OpenMMLab codebase builds on, and it can be used on its own. Its contract is narrow, a model that returns a loss or predictions by mode, but its documented compatibility and its release state both need checking before you adopt it.
- Who is it for?
- MMEngine fits teams that want a configurable PyTorch training loop with DeepSpeed, FSDP or ColossalAI support, or that already work in OpenMMLab codebases. It is a weaker choice on a recent PyTorch stack, because the documented support ends at PyTorch 2.1 and Python 3.11, and the newest releases are release candidates.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 125 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
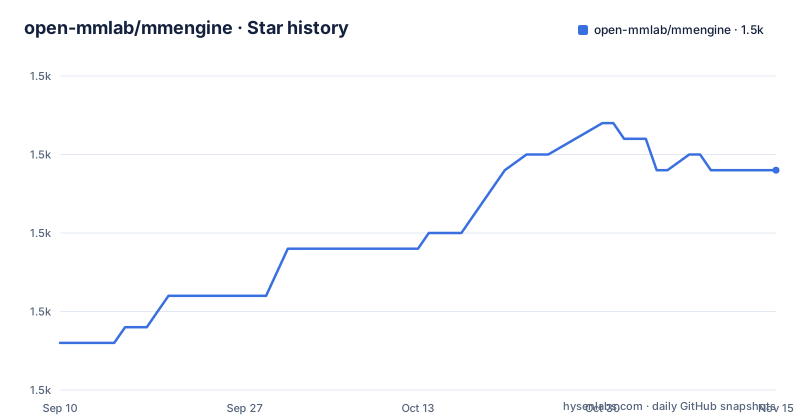
- open-mmlab/mmengine1,504 ★ · +11
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| open-mmlab/mmengine | 1.5k | 1.5k |
11 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It is the shared engine under OpenMMLab and also meant for projects outside it
MMEngine is described as a foundational library for training deep learning models based on PyTorch. It serves as the training engine of all OpenMMLab codebases, which support hundreds of algorithms in various research areas, and it is also generic enough to apply to non-OpenMMLab projects. The README organizes its highlights into four groups: large-scale model training frameworks, training strategies, a configuration system, and training monitoring platforms.
What that means in practice is that you adopt a set of conventions along with a library. The training and validation loop, hooks, config objects and logging are meant to be shared across projects, so models written against MMEngine plug into the same runner. The cost is that your code must follow its model and dataset contracts, described below, and that version changes in MMEngine reach every codebase that depends on it.
There is also a platform dimension. The README links to the OpenMMLab website and an OpenMMLab platform, and to a Documentation site on Read the Docs, so a lot of the guidance lives outside the repository. The English and Simplified Chinese READMEs sit side by side, and the docs directory holds the changelog that the What's New section points to. If you are deciding whether to adopt the library for a single project, ask whether you need the hooks, runner and registry conventions at all, or only one feature such as the DeepSpeed wrapper.
The release line is all release candidates, while the README still announces 0.10.6
The README's What's New section says v0.10.6 was released on 2025-01-13, with highlights such as support for a custom artifact_location in MLflowVisBackend and exclude_frozen_parameters for DeepSpeedEngine's zero3 consolidated 16-bit state dict. The recent releases on GitHub, however, are v0.11.0rc3 on 2026-07-13, v0.11.0rc2 on 2025-12-23 and v0.11.0rc1 on 2025-12-11.
So the newest tagged versions are all release candidates, and the stable line named in the README is the 0.10 series. If you pin to a version for a reproducible experiment, choose deliberately between the 0.10.6 stable release and the 0.11.0 candidates, and do not treat the README's What's New as current. The last push to the repository was on 2026-07-13, the same day as the third candidate, so the work is moving but toward a release that had not been finalized in the releases listed.
The documented PyTorch range ends at 2.1 and Python at 3.11
The installation section carries a compatibility table. For the main branch, and for versions from 0.9.0 to 0.10.4, it lists PyTorch at 1.6 or newer but no later than 2.1, and Python at 3.8 or newer but no later than 3.11.
The consequence is concrete for anyone on a newer stack. If you run a PyTorch release later than 2.1, or Python 3.12 or later, you are outside what the table documents, and any failure is yours to debug. The table does not say the library breaks there, only that it does not claim support. Check whether your versions work in a throwaway environment before you build a pipeline on them. The table also lists no row for 0.10.5, 0.10.6 or the 0.11 candidates, which is another reason to read the pinned requirements of the exact version you install.
The changelog link in What's New adds a small trap of its own: it points at an anchor for v0.10.4 while the text above it announces v0.10.6, so the link takes you to older notes than the announcement. For anything newer than 0.10.4, read the commit history or the release page. The practical advice is to record the PyTorch, Python and MMEngine versions in your experiment logs, since collect_env prints them and a future rerun on different versions may not match.
Install PyTorch first, then use openmim, and verify with collect_env
The README tells you to install PyTorch following its official guide before installing MMEngine. The installation itself goes through openmim:
pip install -U openmim
mim install mmengine
To verify the install, the README gives a one-line check that prints the environment details:
python -c 'from mmengine.utils.dl_utils import collect_env;print(collect_env())'The order matters because PyTorch builds are specific to your CUDA setup, and MMEngine does not choose for you. If the verification prints a PyTorch version outside the table above, that is the first thing to look at when something later fails. The repository also ships setup.py and a requirements directory, so an install from source is possible, but the README's documented route is the openmim one.
A model must inherit BaseModel and return a loss dict or predictions depending on mode
The getting-started example builds a ResNet-50 training and validation process on CIFAR-10 in fewer than 80 lines. Its core rule is that the model inherits from BaseModel and accepts an extra mode argument in forward. During training mode is loss and forward must return a dict containing the key loss. During validation mode is predict and forward returns predictions and labels.
import torch.nn.functional as F
import torchvision
from mmengine.model import BaseModel

class MMResNet50(BaseModel):
    def __init__(self):
        super().__init__()
        self.resnet = torchvision.models.resnet50()

    def forward(self, imgs, labels, mode):
        x = self.resnet(imgs)
        if mode == 'loss':
            return {'loss': F.cross_entropy(x, labels)}
        elif mode == 'predict':
            return x, labels
This contract is what lets the runner drive any model. The limit is that an existing nn.Module cannot be dropped in unchanged: its forward has to be wrapped or rewritten to branch on mode, and the loss must come back inside a dict, not as a bare tensor.
The example continues with separate steps for building datasets, metrics and the runner, and it uses the built-in TorchVision CIFAR-10 dataset with batch size 32 and shuffling on the training loader. The predict branch returns the raw outputs together with the labels, so the metric you define for validation receives both and computes accuracy from them. That arrangement keeps the model free of evaluation code, but it also means a task with a different output shape, such as segmentation or text generation, needs its own metric class, which is why the repository provides separate segmentation, text classification and text translation examples.
Configs can be pure Python or plain text, and the Python style is labeled beta
MMEngine provides a configuration system with two styles. One is pure Python-style configuration files, described as easy to navigate; the documentation link for it carries the word beta. The other is plain-text configuration files that support JSON and YAML.
The choice has consequences. Python-style files let you use imports and variables, which keeps big experiments compact, but the beta label means the interface may still change between releases, and that matters more while the newest releases are candidates. JSON and YAML files are easier to diff and to generate from tools, at the cost of expressiveness. If you want long-term reproducibility, check which style your upstream codebase uses and match it, because mixing styles in one project makes config inheritance harder to read.
Large-model and monitoring integrations are listed by name, with one marked work in progress
For large models, the README lists ColossalAI, DeepSpeed and FSDP, each with its own section in the large model training guide. For training strategies it names mixed precision training, gradient accumulation and gradient checkpointing, with links into the speed-up and GPU memory guides. For monitoring it lists TensorBoard, WandB, MLflow, ClearML, Neptune, DVCLive and Aim.
The MLflow link points to an anchor that ends in wip, which reads as a work-in-progress marker, so expect that backend to be less settled than TensorBoard. The What's New highlights include MLflow and DeepSpeed fixes, which shows these integrations still change. The examples directory contains distributed_training.py, distributed_training_with_flexible_runner.py and a llama2 folder, along with segmentation, text classification and text translation examples. Start from the one nearest your use case rather than composing the integrations from the list.
Editorial conclusion
MMEngine fits teams that want a configurable PyTorch training loop with DeepSpeed, FSDP or ColossalAI support, or that already work in OpenMMLab codebases. It is a weaker choice on a recent PyTorch stack, because the documented support ends at PyTorch 2.1 and Python 3.11, and the newest releases are release candidates. Test your exact versions before committing.
Frequently asked questions
What is MMEngine?
MMEngine is a foundational library for training deep learning models based on PyTorch. It is the training engine of all OpenMMLab codebases and can also be used in non-OpenMMLab projects.
How do I install MMEngine?
Install PyTorch first, then run pip install -U openmim and mim install mmengine. Verify with python -c 'from mmengine.utils.dl_utils import collect_env;print(collect_env())'.
Which PyTorch and Python versions does MMEngine support?
The README's table lists PyTorch 1.6 up to 2.1 and Python 3.8 up to 3.11 for the main branch and for versions 0.9.0 through 0.10.4.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/open-mmlab-mmengine)Star history chart for your README
[](https://hysenlabs.com/projects/open-mmlab-mmengine)Was this useful?