CLIP: a 77 token context, an unpinned torch, and an Approach section with nothing in it
CLIP (Contrastive Language-Image Pretraining), Predict the most relevant text snippet given an image
At a glance
- What is it?
- CLIP is OpenAI's MIT-licensed image and text encoder, used for zero-shot classification and as a feature extractor. The install line pulls torch without a version, the tokenizer works in a 77 token window, and the README has an empty Approach heading. The last push to main was on 2026-03-25 and the repository has no releases.
- Who is it for?
- CLIP is the right pick when you want image and text features in the same space, either to classify with labels you write yourself or to feed a linear probe, and the ViT-B/32 checkpoint is small enough to run on a CPU. It is the wrong pick when you need a maintained training pipeline or a versioned release to depend on.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
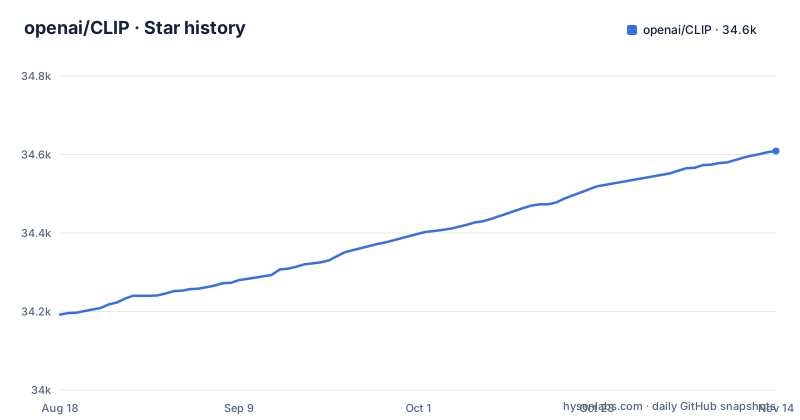
- openai/CLIP34,609 ★ · +417
| Repository | 2026-08-18 | 2026-11-14 |
|---|---|---|
| openai/CLIP | 34.2k | 34.6k |
417 Stars in the last 88 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The install line pulls torch with no version at all
The documented path is a git install, not a package index:
$ conda install --yes -c pytorch pytorch=1.7.1 torchvision cudatoolkit=11.0
$ pip install ftfy regex tqdm
$ pip install git+https://github.com/openai/CLIP.git
The first line names a specific PyTorch, 1.7.1, and CUDA 11.0, and the text below says to replace cudatoolkit with the right CUDA version for the machine or with cpuonly when there is no GPU. The second line adds the text-cleaning extras by hand. The third is the one that matters later, because it installs from the repository's current HEAD rather than from a version. Look at requirements.txt and every dependency is bare: ftfy, packaging, regex, tqdm, torch, torchvision, with no version markers. Nothing stops pip from resolving a torch that the 2021 code was never run against, and nothing in the install tells you which torch you got. setup.py compounds this by naming the distribution clip, a generic word, which is presumably why the README reaches for a git URL.
clip.load downloads the weights on the first call, and jit is off unless you ask
Two functions decide everything. clip.available_models() returns the names you can pass, and clip.load(name, device=..., jit=False) returns a pair: the model and the TorchVision transform that model needs. The download happens inside load, so the first call needs a network connection and the model is downloaded as necessary. The name argument is not only a registry key, it can also be a path to a local checkpoint, which is the route for an air-gapped machine or a vendored copy. Device selection defaults to the first CUDA device when there is one and the CPU otherwise, so the same code runs both places without a flag. When jit is False, a non-JIT version of the model is loaded.. The returned model has three methods, encode_image, encode_text and the combined call, and the module adds available_models, load and tokenize.
tokenize works in a 77 token window, and the documentation does not say what happens past it
clip.tokenize(text, context_length=77) returns a LongTensor of tokenized sequences and the default context is 77. That number is the model's context window, so it is a hard ceiling on how much text you can put in one call, and the README mentions it only as a default argument with no discussion. Nothing in the README says whether longer input is truncated, padded or rejected. A reader with a paragraph-long caption, a product description, or a translated sentence that expands in tokenized form has three possible outcomes and no documented way to find out which one happens except to call the function and look at the tensor shape. The same silence sits on the other side. The README mentions no truncation strategy, no warning, and no helper for chunking a long document into several windows, so any workflow that treats CLIP as a document retriever has to build that part on its own and accept that the embedding is not the embedding of the whole document.
The model call returns a cosine similarity times 100, and a softmax turns it into a label
model(image, text) takes a batch of images and a batch of text tokens and returns two tensors, logits_per_image and logits_per_text. Their values are the cosine similarities between the matching image and text features, multiplied by 100. Scaling by 100 is what makes the numbers behave like logits once you apply a softmax, which is exactly what the quickstart example does with logits_per_image.softmax(dim=-1).cpu().numpy(). The example labels a CIFAR-100 image against all 100 dataset class names, building each prompt as a photo of a followed by the class name, and reads the top entries off the softmax. The printed output is a ranking: snake at 65.31 percent, turtle at 12.29, sweet_pepper at 3.83, lizard at 1.88, crocodile at 1.75. That is a classifier written entirely in strings, with no training step, and it is also the moment to notice how much the prompt wording carries the result.
The linear-probe example breaks off mid-function and leaves C to a sweep
The second worked example uses scikit-learn to fit a LogisticRegression on image features, which is the standard way to ask whether CLIP's representation is useful for a task you do have labels for. The snippet imports numpy, the logistic regression, a DataLoader, CIFAR100 and tqdm, sets up train and test datasets with the model's own preprocess transform, and starts defining get_features(dataset). The text after the block says the C value should be determined via a hyperparameter sweep using a validation split, so that choice is left to you.
The Approach heading is empty, and setup.py still says version 1.0
The README has a section titled Approach with nothing under it. The method, the training data, the contrastive objective, none of it is in the repository text; the blog post, the paper at arxiv 2103.00020 and model-card.md are linked at the top of the README. setup.py has its own silence, a description field that is an empty string and a version pinned at 1.0 for a repository whose last push to main was on 2026-03-25. The repository is not archived and it has no GitHub releases, so there is no tag to install and no changelog to read. What you can do is pin the commit you tested. One more piece sits unexplained: hubconf.py at the root is a torch.hub manifest, which is the entry point that library needs to be loadable by URL, and the README never mentions it.
OpenCLIP goes to ViT-G/14, and the HF port trades the repository for the ecosystem
The README names two alternatives and says what each changes. OpenCLIP includes larger and independently trained CLIP models, up to ViT-G/14, so if your accuracy problem is a capacity problem, that is the direction to look, and the models there were trained separately rather than released by OpenAI. The Hugging Face implementation of CLIP is described as easier integration with the HF ecosystem, which is a different axis entirely: same kind of model, delivered as part of a larger stack with its own loading and serving conventions. Neither swap is free. Moving to OpenCLIP means a different model names and different checkpoints than the ViT-B/32 the quickstart loads. Staying with the upstream repository means owning the three-line install above, the 77 token window, and a code base whose last change was 2026-03-25. Which of those you can afford depends on whether you are experimenting or shipping.
Editorial conclusion
CLIP is the right pick when you want image and text features in the same space, either to classify with labels you write yourself or to feed a linear probe, and the ViT-B/32 checkpoint is small enough to run on a CPU. It is the wrong pick when you need a maintained training pipeline or a versioned release to depend on. Three things to check before you commit a product to it. First, which checkpoint name you pass to clip.load, because that call downloads weights and the README does not list the names it accepts. Second, whether your captions fit 77 tokens, since nothing in the documentation says what happens when they do not. Third, that the git URL in the install line is what you actually installed, because the distribution is named clip and the repository has no tagged release to fall back on.
Frequently asked questions
What is OpenAI's CLIP?
CLIP, Contrastive Language-Image Pre-Training, is a neural network trained on a variety of image and text pairs and described as predicting the most relevant text snippet given an image without directly optimizing for that task. The README says it matched the original ResNet50 on ImageNet zero-shot without using any of the original 1.28M labeled examples.
what is CLIP pretraining?
The pretraining is over paired image and text data, and the result is a model that can be instructed in natural language to pick the most relevant text for an image. The README compares the resulting zero-shot ability to that of GPT-2 and GPT-3. The repository has an Approach heading with no text under it, so the training details are in the paper and the model card rather than in the README.
how to install openai clip
Install PyTorch 1.7.1 or later with torchvision, then pip install ftfy regex tqdm, then pip install git+https://github.com/openai/CLIP.git. The README's conda line includes cudatoolkit=11.0, which you replace with your CUDA version or with cpuonly on a machine without a GPU. The extras are also listed unpinned in requirements.txt.
what is openai clip used for
Two documented uses. Zero-shot prediction, where an image is scored against text prompts such as a photo of a followed by each class name, and linear-probe evaluation, where scikit-learn fits a logistic regression on the image features returned by encode_image. The module also returns shared-space features through encode_image and encode_text for your own use.
is openai clip open source
Yes, the repository carries an MIT license, and setup.py records the author as OpenAI. The distribution is named clip at version 1.0, and the install instruction uses a git URL rather than a package index, so there is no tagged release to pin.
openai clip vs openclip
The README's See Also section points to OpenCLIP for larger and independently trained CLIP models up to ViT-G/14, and to the Hugging Face implementation for easier integration with the HF ecosystem. OpenCLIP changes the model scale and the training source; the HF port keeps the model family and changes how it is loaded and deployed.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openai-clip)Star history chart for your README
[](https://hysenlabs.com/projects/openai-clip)Was this useful?