MLE-bench froze its leaderboard on the same day it last pushed, and its best number is in the not-comparable table
MLE-bench is a benchmark for measuring how well AI agents perform at machine learning engineering
At a glance
- What is it?
- OpenAI's benchmark for machine learning agents, where the top score on the page uses test-set feedback, every entry above 61 percent withholds its source code, and the test suite is documented as slow because it downloads Kaggle competitions.
- Who is it for?
- The right way to use this repository right now is as a grading harness rather than as a ranking. The score columns, the padded-seed footnote and the separate table for submissions that used test-set feedback are all things to read before quoting a number, including your own.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
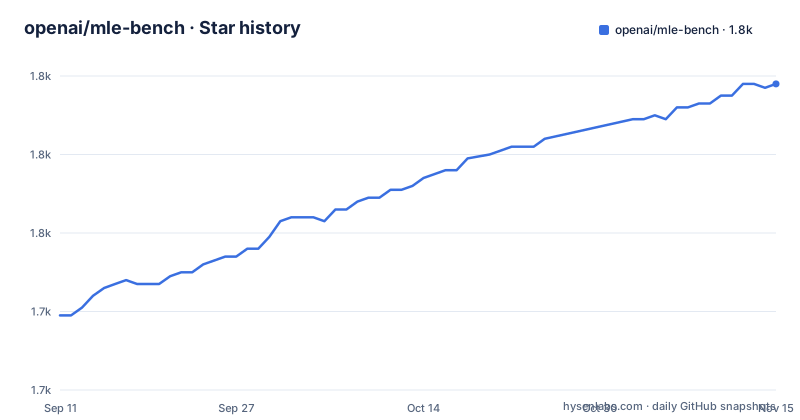
- openai/mle-bench1,798 ★ · +59
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| openai/mle-bench | 1.7k | 1.8k |
59 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The freeze notice is dated the same day as the last push
The leaderboard carries a dated update reading 04-24-2026, and it says no new submissions are being accepted while an improved process for making submissions fair and comparable is developed. Updates on that process are promised for later.
That date is also the last push to the default branch. Whatever else changed in the repository, the newest thing anyone has committed is the announcement that the scoring process is on hold.
So the practical state of the project is a snapshot. The leaderboard's newest entry is dated 2026-03-06 and the freeze was three weeks later. Nothing can be added to the table until the fairness process exists, which means anyone publishing a comparison right now is publishing against a closed board. The code is the part that remains usable: the repository says in its opening line that it released the code used to construct the dataset, the evaluation logic, and the agents it evaluated, which is a different deliverable from the ranking.
The paper is the other anchor. The repository points at an arXiv entry for MLE-Bench, evaluating machine learning agents on machine learning engineering, and at a project page on OpenAI's own site.
The highest score on the page sits in the table that is not comparable
There are two tables. The main leaderboard runs from 64.44 percent down to 1.60 percent on the All column. Below it is a second table headed Additional Leaderboard Submissions, described as submissions that are not directly comparable to the main leaderboard, with a Notes column explaining why.
The second table holds the two highest numbers on the page. Disarray scores 77.78 percent on All, well above anything in the main table, and LoongFlow scores 62.66. Both entries carry the same note, a link to a pull request against this repository about test-set feedback. Their dates are 2026-02-03 and 2026-02-09, both after several main-table entries were scored.
So the single most quotable number in this README belongs to a run that used information the benchmark is designed to withhold, and the repository says so in its own Notes column rather than leaving a reader to work it out. Any comparison that quotes 77.78 without that qualifier is quoting the wrong thing.
The separation is the right design decision, and it is worth reading the second table as a measurement of what feedback buys rather than as a score.
Every entry above 61 percent withholds its source code
The leaderboard has a column marking whether source code is available, and it runs opposite to the score column. The top entries, at 64.44, 63.11, 62.67, 61.33, 59.56, 56.44, 56.00, 52.00, 48.44, 44.00, 43.56, 39.56, 38.67, 36.44 and 34.22, all mark their source as unavailable. Every entry that marks source code available scores 61.33 or below.
The best open entry is MLEvolve at 61.33, followed by Leeroo at 50.67. Below that the open entries are the R&D-Agent runs at 35.11, 30.22 and 22.40, AIRA-dojo at 31.60, ML-Master at 29.33, four AIDE runs from 17.12 down to 3.33, OpenHands at 4.89 and MLAB at 1.60.
Two things follow for a reader. The reproducible half of the leaderboard is also the weak half, so any claim about what makes the top agents work is unverified by construction. And the grading reports column is a check on the closed half: every row, open or not, carries a grading report, which is the artifact a third party would need in order to audit a score they cannot rerun.
The model column says undisclosed once and admits ensembles in the footnotes
The table has a column for which language models were used, and it is the least reliable column on the page. One entry, Neo multi-agent, simply reads undisclosed, with a running time of 36 hours, which is the longest in the table.
Two footnotes quietly widen the other entries. One attached to the Operand row, whose model is listed as gpt-5 at low verbosity and effort, says the run had some light assistance from an ensemble including Gemini-2.5-Pro, Grok-4 and Claude 4.1 Opus, distilled by Gemini-2.5-Pro. Another, attached to two PiEvolve rows and one Leeroo row, says the architecture is primarily driven by one preview model with a subset of modules using GPT-5 and GPT-5-mini.
A third footnote explains the arithmetic rather than the models: several rows were computed by padding incomplete seeds with failing scores. That is a defensible choice, since a run that did not finish has not demonstrated anything, but it means a percentage on this table can be a mixture of measured and imputed results, and the footnote is the only place that is stated.
Read together, the model column tells you what the headline was. The footnotes tell you what actually ran. Both are needed to reproduce a row.
The running time column mixes a budget with a measurement
One column records running time in hours, and it holds almost one value. Twenty-four hours appears for most of the table. Twelve hours appears for MLEvolve, one PiEvolve row, MLE-STAR-Pro-1.0, InternAgent, the strongest R&D-Agent row and ML-Master. Thirty-six hours appears once, for Neo.
The column is labelled running time, which reads like a measurement, but the repetition of 24 across agents of very different speeds suggests it is the budget the run was given rather than the time it took. A run that finishes in two hours and a run that exhausts its budget both report 24 in that reading, and the table offers no column for the distinction.
This matters when comparing rows. A 12-hour entry scoring 61.33 and a 24-hour entry scoring 59.56 are not separated by the agent if one had twice the wall clock. And the entry that did use more, at 36 hours, is the one whose model is listed as undisclosed.
The test suite is documented as slow because it downloads competitions
The packaging file explains the test configuration in a comment. Pytest can take a long time to collect test cases when many Kaggle competitions have been downloaded, so the configuration points pytest at the tests directory ahead of time to avoid the delay. That comment is the clearest statement in the repository about what running the tests costs: competition data.
The dependency list explains the mechanism. A Docker client at version 7.1 or later is required, and Kaggle is pinned to a narrow window of 1.6.x. Each competition therefore runs somewhere isolated, with the harness talking to it, and grading reports are produced from inside that boundary. Other dependencies describe what grading means concretely: computer vision libraries for image and geometry tasks, a quaternion library for rotation-aware comparison, a fast parquet reader, a 7z reader, a MongoDB client, a disk cache, notebook conversion tools, and a Levenshtein distance library for string similarity in grading.
The package requires Python 3.11 or later, declares version 1.0.0, and installs one console script mapped to the CLI entry point. The repository has no GitHub releases, so that version number exists only inside the packaging metadata.
The competition definitions themselves ship inside the package: the setuptools package data rule bundles a competitions directory tree under the top-level module.
The platform cannot identify the license and the repository ships one anyway
The repository's license field reads NOASSERTION, which is the value used when no license could be detected, and a LICENSE file is present at the root of the tree. Those two facts do not agree on their face, and nothing visible settles which one to follow. This article does not guess at the contents of the file.
That question matters more than it usually would, because the repository is explicitly a reusable artifact. It says the code used to construct the dataset and the evaluation logic was released, and the packaging configuration is set up to distribute competition definitions as package data rather than keeping them in a data directory outside the wheel. Anyone planning to run the grading logic on their own agent runs needs to know the terms first.
The layout also tells you what the project considers its parts. There is an agents directory, an environment directory, experiments, an extras directory, a runs folder, tests, an examples tree containing a rule violation detection example, and a single `run_agent.py` at the root as the obvious entry point.
The instructions for producing a score are also in the visible page and stop mid-sentence: organize grading reports in the runs folder by run group, with one grading report per run, and the sentence ends there.
Editorial conclusion
The right way to use this repository right now is as a grading harness rather than as a ranking. The score columns, the padded-seed footnote and the separate table for submissions that used test-set feedback are all things to read before quoting a number, including your own. Two facts govern everything else: submissions are closed until a fairness process exists, and the repository's license is not identified by the platform even though a LICENSE file is present, so treat reuse as unresolved until you have read it.
Frequently asked questions
What is MLE-bench?
A benchmark for measuring how well AI agents perform machine learning engineering, published with the paper MLE-Bench: Evaluating Machine Learning Agents on Machine Learning Engineering, arXiv 2410.07095. The repository contains the code that constructs the dataset, the evaluation logic and the agents it evaluated.
Why is the MLE-bench leaderboard not taking submissions?
An update dated 04-24-2026 says new submissions are not being accepted while an improved process for ensuring submissions are fair and comparable is developed, with updates promised later. That same date is the last push to the default branch.
What do the score columns on the MLE-bench leaderboard show?
Four percentage columns, the first labelled Low == Lite, then Medium, High and All. Each value carries a plus or minus figure, and a footnote states that some rows were computed by padding incomplete seeds with failing scores rather than only measuring finished runs.
Can I submit my own agent's score to MLE-bench?
Not at the moment. Submissions are closed while a fairness and comparability process is built. The page describes producing scores by organizing grading reports in the runs folder by run group, and lists submissions that used test-set feedback in a separate table marked as not directly comparable.
How is the mlebench package installed and what does it need?
Python 3.11 or later, with a console script mapped to the CLI entry point. It depends on the Docker client and a pinned Kaggle client range, which is how competitions run in containers, and the pytest configuration notes that collecting tests is slow once many competitions have been downloaded.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openai-mle-bench)Star history chart for your README
[](https://hysenlabs.com/projects/openai-mle-bench)Was this useful?