mcp-server-airbnb: cheerio over airbnb.com, and three ways to turn robots.txt off
Search Airbnb using your AI Agent
At a glance
- What is it?
- This MCP server lets an agent search Airbnb listings and pull listing details by reading Airbnb's own web pages, not through an official API. Its robots.txt respect is a default with three separate overrides, one of which the calling model controls.
- Who is it for?
- Use this server if you want listing search and details in an MCP client and accept that every query is HTML scraped from airbnb.com, and prefer the npx route over the bundle so you can see the arguments your client passes. Settle the terms question before you point it at anything you care about, because the retrieval path is scraping a commercial site and the project's own framing of that is a compliance feature rather than a warning.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 101 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
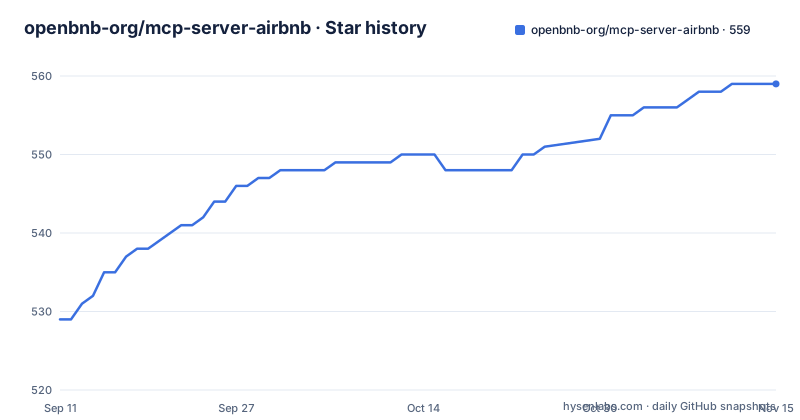
Star history
- openbnb-org/mcp-server-airbnb559 ★ · +30
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| openbnb-org/mcp-server-airbnb | 529 | 559 |
30 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three separate overrides for one robots.txt setting, and the model controls one of them
The server respects robots.txt by default, and then offers three different ways not to.
{
  "mcpServers": {
    "airbnb": {
      "command": "npx",
      "args": [
        "-y",
        "@openbnb/mcp-server-airbnb",
        "--ignore-robots-txt"
      ]
    }
  }
}
The first override is a bundle setting. In Claude Desktop you open settings, navigate to the extension, and enable an Ignore robots.txt toggle. It is a Boolean, it defaults to `false`, its stated description is bypassing robots.txt restrictions when making requests to Airbnb, and the recommendation is to keep it disabled unless needed for testing purposes.
The second is the command line flag shown above.
The third is a tool parameter. Both `airbnb_search` and `airbnb_listing_details` accept an optional `ignoreRobotsText` argument described as an override for that request.
That third one is the problem. A tool parameter is supplied by the caller, and the caller is a model. So a user who leaves the setting off and follows the recommendation still has a path to the override in every request the agent decides to make, with nothing in the configuration saying no. A robots.txt default that the agent can switch off per call is not a policy, it is a suggestion.
The `robots-parser` dependency is in the runtime list, so the parsing itself is real. Whether it is consulted is a separate question from whether the caller can insist that it is not.
The retrieval path is HTML from airbnb.com, and the page never says that in those words
The runtime dependencies are four: the Model Context Protocol SDK, `cheerio`, `node-fetch`, and `robots-parser`.
`cheerio` is an HTML parser. There is no official Airbnb API client in that list, and nothing in the visible documentation describes one. The clearest confirmation of what the server actually does is buried in a configuration description: with third-party geocoding disabled, every search goes only to `airbnb.com`, with no third-party calls. That sentence is the retrieval path stated plainly, and it appears as a side effect of explaining a privacy toggle rather than as a description of the server.
The feature list frames the same thing as compliance. Under a heading about security and compliance you get robots.txt compliance with a configurable override for testing, request timeout management to prevent hanging requests, enhanced error handling with detailed logging, and rate limiting awareness with respectful API usage.
That is a reasonable posture for reading public pages, and it is also a posture you have to accept on the project's terms rather than verify yourself. Nobody involved here has an arrangement with Airbnb. The licence is MIT and the copyright is the OpenBnB organisation, and neither of those says anything about the site being read.
So the first thing to settle is not technical. Whether scraping a marketplace's public listing pages is something you are permitted to do, and what happens to your account and your IP if you do it at volume, is a question for the site's terms and for you, not for this repository.
Geocoding is on by default, so the location string you type goes to a third party
The `airbnb_search` tool takes a required `location` string. Supply it without a `placeId` and the server geocodes the string client-side through Photon and Nominatim before it queries Airbnb.
That step is on by default. The option that turns it off is `DISABLE_GEOCODING`, a Boolean environment variable whose default is `false`, which means the geocoding step runs unless you intervene. Its description says enabling it skips the Photon and Nominatim step and lets Airbnb resolve the location string on its own, restoring the pre-pull-request behaviour where every search goes only to `airbnb.com`.
The stated cost of turning it off is accuracy. With geocoding disabled, non-US searches can return incorrect results. The feature that supports international queries is the one that requires the third-party call, and the toggle that removes the call removes the feature.
There is a third path. A `placeId` parameter takes a Google Maps Place ID, overrides `location` entirely, and skips client-side geocoding with no third-party calls at all. So you can stay off third parties if you already hold a Google-derived identifier for the place, which is a reasonable arrangement for a fixed set of destinations and a poor one for exploratory search.
The section that would document all of this properly is the one you cannot read. Both the geocoding description and the tool parameter point at an External Services section, and the visible text ends before reaching it.
One of the two configuration options has no home in the documented client setup
There are two install paths, and each exposes the settings differently.
For Claude Desktop the server ships as a bundle. You download the `.mcpb` file from the latest release, open it, Claude Desktop shows an installation dialog, and the extension's options appear as checkboxes in Claude Desktop's own settings pane, where the Ignore robots.txt toggle lives.
For Cursor and similar clients you edit a JSON file by hand, and the configuration shown contains only a command and an arguments array. There is no environment block.
That matters because the two documented options are not the same kind of thing. Ignore robots.txt is available as a checkbox in the bundle and as a command line flag in the npx form. Disable third-party geocoding is documented as a Boolean with an environment variable name, `DISABLE_GEOCODING`, and as a bundle checkbox. The hand-written JSON has nowhere to put an environment variable, so a user following that snippet exactly cannot reach the geocoding toggle without adding an env entry the documentation does not show.
Two smaller details in the same snippet. The `-y` flag in the arguments means the package installs without a confirmation prompt the first time the client starts the server, which is convenient and is one more thing happening without a prompt. And the instructions end with a single restart step, so a configuration change to the JSON file requires bouncing the client to take effect.
Type declarations for node-fetch 2 against a node-fetch 3 runtime, and no engines field
The dependency block pairs a v3 runtime with v2 typings.
The runtime entry is `node-fetch` at `^3.3.2`. The development entry is `@types/node-fetch` at `^2.6.12`. So the type declarations describe the second major version of the library while the installed code is the third.
That gap is not cosmetic. node-fetch 3 was a rewrite with ESM-first packaging and a different module shape from v2, and its published types are part of the package rather than a separate `@types` entry. A `@types/node-fetch` at v2 in a project that is itself declared as an ES module and depends on node-fetch 3 is a typing artefact left over from an earlier arrangement, and it will quietly describe an API the runtime no longer exposes.
The rest of the manifest is more disciplined. `@modelcontextprotocol/sdk` at `^1.0.1`, `cheerio` at `^1.0.0`, and `robots-parser` at `^3.0.1` all carry floors, and the package declares `"type": "module"`, a public publish config, and a bin entry pointing at `dist/index.js`.
What is missing is an `engines` field. There is no declared Node floor anywhere in the manifest, while the container image is built `FROM node:lts-alpine`, so the version you get depends on which tag the base image carries that week rather than on a constraint the package states.
Two version fields kept in sync by a script that git-adds one of them
This project publishes to npm and also ships a bundle, and the bundle carries its own manifest, so there are two version fields: `version` in `package.json` and a version inside `manifest.json`.
A script called `sync-version.js` reconciles them, and the npm lifecycle hooks wire it in at two points. The `version` script runs `node sync-version.js && git add manifest.json`, so bumping the version rewrites the manifest and stages it. The `prepare` script runs the build, and `build` itself is `node sync-version.js && tsc && shx chmod +x dist/*.js`.
So the manifest is generated, not hand-edited, and the sync runs on every build. That is a sound arrangement and it explains why the npm version and the newest release tag agree at `0.3.0`.
The container image shows the same care from the other direction. The Dockerfile is generated by a hosting service, installs dependencies with `npm install --ignore-scripts` so the `prepare` hook cannot fire a second build during install, copies the rest of the source, and then runs `npm run build` explicitly. It finishes by starting `node dist/index.js` and exposing the server on stdio.
The published file list is narrow: `dist` and `sync-version.js`, with `dist/*.mcpb` explicitly excluded. That last entry keeps the bundle out of the npm tarball, since the bundle is delivered as a release download instead.
Three TypeScript files at the root, two test scripts beside them, and a hosting config
The whole source is three TypeScript files in the repository root: `index.ts`, `util.ts`, and `types.d.ts`. Alongside them sit `sync-version.js`, `manifest.json`, `tsconfig.json`, and `package-lock.json`.
The tests are at the root too. `npm test` runs `node test-extension.js && node test-amenities.js`, with a `pretest` hook that performs the full build first, so a type error blocks the tests rather than being discovered by them. There is no test framework in the development dependencies, which means these are plain scripts asserting against the built output rather than unit tests over modules.
The names suggest the coverage is narrow by design: one script exercises the extension itself and the other exercises the amenities handling. The amenities path is the one the visible tool documentation starts to describe when it stops, describing amenities and facilities returned as `seeAllAmenitiesGroups`, an object keyed by amenity category so a category can be addressed directly.
Two deployment files round out the root. A `smithery.yaml` sits next to a Dockerfile that names its own generator, and there is a `.mcpbignore` for the bundle build alongside the ordinary `.gitignore`. So the project is set up for two different distribution channels, a hosted MCP service and the desktop bundle, from a very small source tree.
The first section of the page sells a hosted alternative it says is better
Before any feature description, the page carries a section headed with a rocket about preferring not to run a local server, pointing at `openbnb.ai` as a hosted MCP server that solves the same problem without local setup.
It then makes four claims about that hosted service: zero setup with no Node, no npx, no config files and no updates to manage; advanced filters described as richer search controls beyond the base tools here; an MCP UI with interactive components for browsing results rather than plain text; and being managed and maintained on your behalf.
That is four ways the hosted version is described as strictly better than the code in the repository, placed above the installation instructions. The project metadata names the author as the OpenBnB organisation at `openbnb.org` while the site is at `openbnb.ai`, so the hosted service appears to be run by the same people who publish the open-source server.
There is nothing wrong with that, and an open-source funnel to a hosted product is a common arrangement. It does mean the open-source server's incentive is adoption rather than parity, so the richer filters and the interactive UI are the features you should expect to stay hosted.
One more fact worth having: the newest release is `v0.3.0`, published on 2026-08-06, and the last push to the repository carries the same date.
Editorial conclusion
Use this server if you want listing search and details in an MCP client and accept that every query is HTML scraped from airbnb.com, and prefer the npx route over the bundle so you can see the arguments your client passes. Settle the terms question before you point it at anything you care about, because the retrieval path is scraping a commercial site and the project's own framing of that is a compliance feature rather than a warning. Then configure the one setting that matters, geocoding, and set it deliberately in the environment because the documented client configuration has no place to put it. If you need a stable data source rather than a demo, the hosted alternative the project recommends is the more honest dependency.
Frequently asked questions
How does mcp-server-airbnb get listing data?
It parses HTML with cheerio and fetches pages with node-fetch, querying airbnb.com rather than calling an official Airbnb API. The configuration notes state that with third-party geocoding disabled, every search goes only to airbnb.com.
Is there a way to make mcp-server-airbnb skip robots.txt?
Three ways. There is an Ignore robots.txt toggle in the Claude Desktop extension settings, an --ignore-robots-txt command line flag for the npx form, and an optional ignoreRobotsText parameter on both airbnb_search and airbnb_listing_details, which the calling agent supplies.
Why does mcp-server-airbnb call a geocoding service?
When a search supplies a location string without a placeId, the server geocodes it client-side through Photon and Nominatim so that non-US queries land in the right city. Setting DISABLE_GEOCODING to true skips that step and lets Airbnb resolve the string, at the risk of incorrect results for non-US searches.
How do I install mcp-server-airbnb in Cursor?
Install Node.js so npx works, add a server entry to your mcp.json with command npx and args -y @openbnb/mcp-server-airbnb, then restart. A second documented variant appends --ignore-robots-txt to the arguments.
What tools does mcp-server-airbnb expose?
Two. airbnb_search takes location, an optional placeId, checkin and checkout dates, guest counts, price bounds, a pagination cursor, propertyType and ignoreRobotsText. airbnb_listing_details takes a required listing id plus the same date, guest and override options.
How is the mcp-server-airbnb package versioned?
The manifest declares version 0.3.0 and the newest release is v0.3.0 from 2026-08-06. The npm version and the bundle manifest version are kept in step by a sync-version.js script that also stages manifest.json during a version bump.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openbnb-org-mcp-server-airbnb)Star history chart for your README
[](https://hysenlabs.com/projects/openbnb-org-mcp-server-airbnb)Was this useful?