OpenClaudia counts its own skills three different ways
34 open-source marketing skills for Claude Code. SEO, content, email, ads, analytics, and growth.
At a glance
- What is it?
- The MIT licensed toolkit bundles Claude Code marketing skills, and how many there are depends on where you look: 34 in the one-line repository summary, 78 in the README header, 45 rows across the tables that run out mid-word.
- Who is it for?
- OpenClaudia is best used as a directory of skill folders you read before you install, since each skill is a plain directory you can open and inspect first. Nobody needs the `--all` switch to get value, and nobody should trust the 78 figure, because the two counts inside the project's own files disagree by more than double.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 10 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
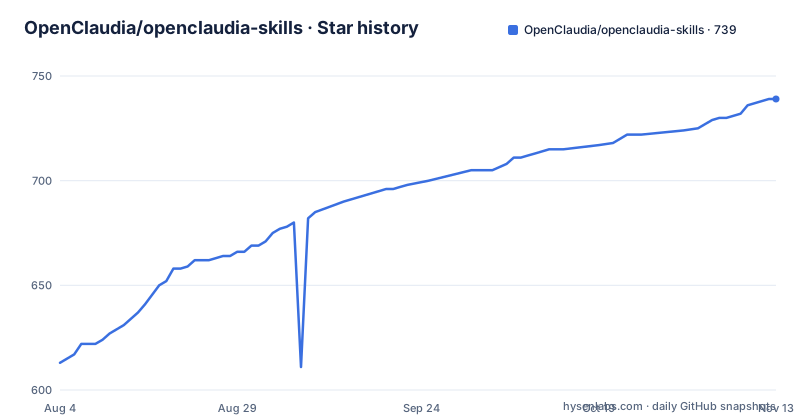
- OpenClaudia/openclaudia-skills739 ★ · +126
| Repository | 2026-08-04 | 2026-11-13 |
|---|---|---|
| OpenClaudia/openclaudia-skills | 613 | 739 |
126 Stars in the last 101 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three different skill counts, none of them reconciled
Three numbers describe the same collection. The one-line summary on the repository page reads 34 open-source marketing skills for Claude Code. The header block above the comparison table says 78 modular skills that turn your AI coding agent into a full marketing department, and the install command repeats the same figure in its own comment. The tables carry neither number. Counting the rows that are actually written out: nine under SEO and Site Audit, nine under Content Writing, two under Email Marketing, six under Social Media, six under Ads and Conversion, and thirteen under Analytics and Research, which is 45 rows before the last entry stops partway through its own description.
# Install all 78 marketing skills
npx openclaudia install --all

# Or install specific skills
npx openclaudia install seo-audit write-blog email-sequence
The smallest claim is 34, the largest is 78, and the section that would settle it ends on a partial word. The command exposes no count flag, so `--all` is the one switch that makes the disagreement matter: it hands the decision to whatever the CLI believes the inventory is, and the repo gives a reader no way to check that number before running it.
Three install routes and no version to pin them to
Three routes are offered, and every one of them resolves at the moment you run it.
# Via the skills CLI
npx skills add OpenClaudia/openclaudia-skills

# Install a single skill
npx skills add OpenClaudia/openclaudia-skills --skill seo-audit

# Manual: copy any skill directory into your skills folder
cp -r skills/seo-audit ~/.claude/skills/      # personal
cp -r skills/seo-audit .claude/skills/         # project-level
The repository publishes no GitHub releases. Its last commit is dated 2026-09-18, and none of the three commands above carries a tag or a version argument, so each run takes whatever the npm registry holds at that moment. The installer itself lives here: `cli/` sits at the root next to `skills/` and `tools/`, so the CLI and the skill folders ship together, but nothing visible ties the published package to a commit.
The manual route is the only one that lets you read a skill before running it, and it stops exactly at the copy step. The text says to copy any skill directory into your skills folder, and then says nothing about what a skill needs inside it, what the agent expects to find, or what happens when you later update and the files no longer match.
The free claim runs straight into a column of credentials
The comparison table near the top sells the toolkit on price and privacy. Price reads Free and open source, Execution reads Actually writes, publishes, sends, data privacy reads Runs locally on your machine, and setup is one command. MIT licensing and a plain directory copy do back part of that.
The Analytics and Research table then names what each of its skills needs in order to talk out to the network: `SEMRUSH_API_KEY` for `semrush-research`, a Glasser account for `glasser-research`, `BRANDDEV_API_KEY` for both `brand-monitor` and `brand-research`, Google OAuth for `google-analytics`, `search-console`, `gsc-portfolio-audit` and `google-ads-report`, `DATAFORSEO_LOGIN` for `google-reviews`, `YOUTUBE_API_KEY` for `youtube-analytics`, and the `gh` command line tool for `github-stars`. One row reads None.
Two details are worth a second look. `glasser-research` is described as live marketing data across search, keywords, ads, communities and companies through one prepaid account, and a prepaid account is the one place in the whole set where a cost is stated in words instead of implied by a variable name. Separately, `ahrefs-research` is described as the Ahrefs Python SDK while the repository's primary language is JavaScript.
Send and publish skills with no confirmation step named
Several rows are written in the present tense, which for an agent means the outbound action happens without a person in the loop. `email-sequence` creates and sends drip campaigns via the Resend API. `email-subject-lines` generates, A/B tests and sends subject lines. `social-content` creates and publishes posts to Reddit, X, LinkedIn, Instagram and Facebook. `thread-writer` writes and posts threads on X and Reddit. The Quick Start transcript ends with a Discord command posting a rich embed to an announcements channel, though no skill of that name appears in any of the six tables.
What none of those rows mentions is the same in every case: a dry run flag, a preview step, a confirmation prompt, or any ceiling on how many posts or messages leave in one invocation. The one skill that does list gates is `publish-article`, which holds an article back until the title was searched for, the author is real, the image is licensed, the sources are linked and a dofollow check passes. Those gates guard the path that publishes onto a site you control. The paths that talk to Reddit and to a mailing list are described in a single line each, with no equivalent list beside them.
That is the row to read twice in the comparison table. Actually writes, publishes, sends is an accurate description of the outbound skills rather than an exaggeration, and nothing in the visible files puts a brake on it.
The Quick Start numbers were typed by a person
The Quick Start block is a transcript, and it reads like a demo rather than a measurement. One line has the audit crawl 47 pages and return an SEO score of 72 out of 100 with 12 issues found. The next has a blog request for 10 Tips for SaaS Growth come back as a 2,400-word article with meta tags. A third has a six-email drip sequence created and sent through Resend.
Pull those figures out of the block and you are quoting whoever wrote the example. There is no crawl target, no audit method, no elapsed time, and no way to tell which parts of the output come from a tool and which from the author of the sample conversation. The one slash command that names a page, `https://mysite.com`, is the only input shown anywhere in the whole transcript, and it is the input for the run with the most specific numbers.
The command names also drift from the skill names. The transcript opens with `/audit-seo`, while the table calls that skill `seo-audit`. It also asks for `/competitor-analysis`, and the nearest name in the tables is `competitor-traffic-report`, which sits in the Analytics and Research group and takes a Google OAuth login. Two of the five sample commands do not line up with any entry in the list printed above them.
A referral link sits between the Content Writing and Email tables
One line in the middle of the reference tables is not a skill entry. Between the Content Writing table and the Email Marketing table sits a note telling anyone publishing AI-assisted copy to run it through a hosted watermark tool first, with a referral parameter already attached to the link: `?ref=openclaudia`. The note credits that service with stripping the invisible Unicode watermarks that AI writing tools embed, so your text does not carry a machine-generated fingerprint.
Two things about the placement are odd. It is a commercial referral with the referrer baked into the URL, sitting inside the reference tables rather than in a sponsors section, and it is the only sentence in the README that pushes you off the repository. At the same time, the toolkit is careful about this exact class of problem one table above: `publish-article` will not let an article ship without a licensed image, a real author and linked sources, which is provenance applied to assets. The same reasoning is not applied to the README's own outbound link.
It matters what surrounds that note. `reddit-marketing` is described as authentic Reddit marketing and community engagement, and the repository root carries a file named reddit-post-ropenclaudia.md next to a launch-card-text.png, so the project ships both the toolkit and its own promotional drafts.
One vendor, two skill names, three flat categories
Several entries describe the same paid vendor twice. `keyword-research` is keyword research using the SemRush API. `semrush-research` is SEO and competitive intelligence via SemRush, and its requirement column names `SEMRUSH_API_KEY`. Whether the first one reads the key from the same variable is not written anywhere, which makes the pair ambiguous rather than redundant.
The taxonomy itself mixes three vocabularies as peers. Editorial work sits beside distribution work and beside measurement work, with no ordering between them: `write-blog`, `copy-editing` and `content-strategy` next to `social-content`, `thread-writer` and `content-calendar` next to `gsc-portfolio-audit`, `competitor-traffic-report` and `youtube-analytics`. Nothing in that layout tells you which of the 45 written rows to install first, or which one depends on another.
The newest pair is the least connected to the rest. `geo-query-finder` finds which ChatGPT search queries mention a brand, and `geo-difficulty` scores keyword ranking difficulty for the AI-search era using a page-level UR and an AI Overview signal. Neither names a credential in the requirement column, which sets them apart from every other row in that table.
The root holds launch assets next to the license file
The top level of the repository is short, and two of its entries are promotional rather than functional:
.github/
.gitignore
CONTRIBUTING.md
LICENSE
README.md
USAGE.md
assets/
cli/
docs/
launch-card-text.png
reddit-post-ropenclaudia.md
skills/
tools/
`launch-card-text.png` and `reddit-post-ropenclaudia.md` are launch artifacts, and the second carries a stray `ro` in its name, sitting in the same directory as `LICENSE` and `CONTRIBUTING.md`. The navigation bar at the top of the README links to `USAGE.md` and to `CONTRIBUTING.md`, and to the issues page, but nothing in it points into `docs/` or `tools/` at all, so the longest guide is the one the reader has to find by hand.
Licensing is MIT and the repository is not archived, with the last commit dated 2026-09-18 and no published release. That combination means there is no tag to install by, no changelog to check a change against, and no way to reproduce the state you read about on any given day.
Editorial conclusion
OpenClaudia is best used as a directory of skill folders you read before you install, since each skill is a plain directory you can open and inspect first. Nobody needs the `--all` switch to get value, and nobody should trust the 78 figure, because the two counts inside the project's own files disagree by more than double. Check three things before pointing any of it at live accounts: whether the skill you want needs a credential you would have to buy, whether the outbound skills that post to Reddit, X and LinkedIn or send through Resend show any confirmation step you can inspect, and whether the copy you get today still matches the commit dated 2026-09-18.
Frequently asked questions
How many skills does OpenClaudia actually contain?
Three figures appear in the project's own files. The one-line repository summary says 34 open-source marketing skills for Claude Code, the README header and the install comment say 78, and the six skill tables spell out 45 rows before the final description stops mid-word.
Which OpenClaudia skills need a credential before they work?
The requirement column names SEMRUSH_API_KEY, BRANDDEV_API_KEY for two brand skills, Google OAuth for four Google skills, DATAFORSEO_LOGIN for reviews, YOUTUBE_API_KEY for video, and the gh CLI for star history. glasser-research asks for a prepaid account, and similarweb-traffic is the single row marked None.
Does OpenClaudia offer a dry run for posts and email campaigns?
No dry run is named for any skill. social-content and thread-writer are described as publishing to Reddit, X, LinkedIn, Instagram and Facebook, email-sequence creates and sends drip campaigns through the Resend API, and only publish-article lists gates, and those apply to articles published on your own site.
How do I install one OpenClaudia skill without the installer?
Copy the skill directory by hand with cp -r skills/seo-audit ~/.claude/skills/ for a personal install, or cp -r skills/seo-audit .claude/skills/ at project level. The skills CLI also takes one skill at a time via npx skills add OpenClaudia/openclaudia-skills --skill seo-audit. Claude Code must be installed and authenticated first.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openclaudia-openclaudia-skills)Star history chart for your README
[](https://hysenlabs.com/projects/openclaudia-openclaudia-skills)Was this useful?