opencv_zoo says at the top that the models moved to Hugging Face, and keeps the benchmark tables
Model Zoo For OpenCV DNN and Benchmarks.
At a glance
- What is it?
- A model zoo for the OpenCV DNN module that has become two things at once: a pointer to a new home for the weights, and the only place the cross platform latency numbers still live. Useful, specific and honest about how the numbers were taken, with one hardware row that is essentially empty and a licence line that hands the weights back to their authors.
- Who is it for?
- opencv_zoo is worth using for the benchmark tables, which are the part that stayed, and for the per model demo scripts, which is the other part. Two things to check before you depend on it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 25 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
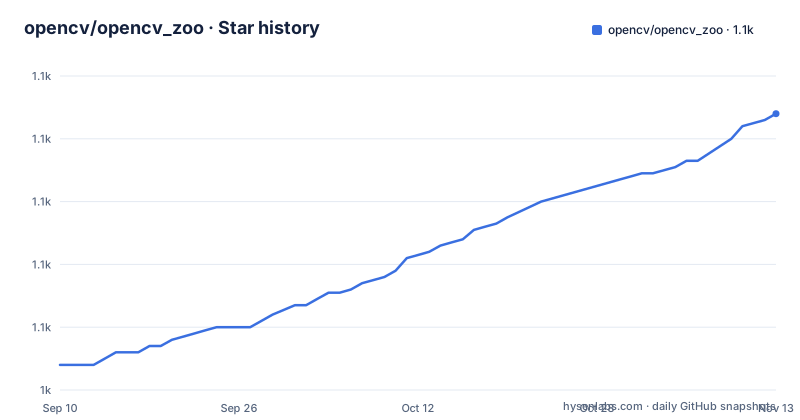
- opencv/opencv_zoo1,128 ★ · +80
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| opencv/opencv_zoo | 1k | 1.1k |
80 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The first line of the file points somewhere else
The document opens before its title with a notice that the project is now hosted on Hugging Face, with a link to the OpenCV organisation there for models and online demos. It is bolded and it comes first, which tells you how the author ranks it.
What that leaves here is a different set of things. The repository still holds a directory per model with its demo scripts, a benchmark directory with configurations and the harness, a reports directory, and a tools directory. So the split is: weights and demos moved, the measurement apparatus and the published numbers stayed.
That is a sensible division, and it also means the model list in this file is now a set of pointers rather than a set of distributions. The task is to read the tables here and fetch anything you intend to run from the other address, which is one more step than a model zoo usually asks of you.
Nothing in the body rewrites the earlier structure. The guidelines still tell you to install the latest `opencv-python` and to clone this repository to get the models and demo scripts, so a reader who starts at the guidelines and skips the notice will do exactly the thing the notice exists to prevent.
Two releases, the newest from June 2024, and commits in May 2026
The release history is two entries. Version 4.9.0 was published on 28 December 2023 and version 4.10.0 on 4 June 2024. Nothing has been released since, which is a gap of more than two years against a branch that received a push on 28 May 2026.
That combination says something specific rather than something dramatic. The release line was tied to the OpenCV release cadence, so the last tag tracks the last time the zoo was cut against a library version. Work has continued on the default branch without producing a new tag, which is the ordinary shape for a repository whose release process is inherited from its parent project rather than run on its own schedule.
It also has a practical consequence. If you pin, pin the branch or a commit rather than a release, because the two newest releases predate two years of further changes and there is no tag that tells you where the current state of the scripts came from. The archive flag is off, so the repository is not frozen, and the last push date is recent enough that nothing here should be described as abandoned.
What you cannot infer from this is whether the model files under the version tags match the weights now on the other host. The files in this repository and the artefacts being served elsewhere have no shared version marker in anything visible here.
Weights arrive through git-lfs, so a plain clone leaves pointers
The two install steps are short and both have a cost worth naming.
The library comes from pip:
python3 -m pip install opencv-python
# Or upgrade to latest version
python3 -m pip install --upgrade opencv-python
That is the prebuilt wheel, the one with the usual extras, rather than a source build and rather than the headless variant.
The models and demo scripts come from a clone that has to initialise and pull large file storage first:
# Install git-lfs from https://git-lfs.github.com/
git clone https://github.com/opencv/opencv_zoo && cd opencv_zoo
git lfs install
git lfs pull
Three consequences follow. If git-lfs is not installed, the clone succeeds and the weight files are pointers rather than weights, so a script that opens a model gets a small text file. The pull step is what actually fetches the binaries, so a clone without it is the same failure by another route. And the download is the bulk of the repository, which is worth knowing before you clone it on a metered connection.
Benchmark runs are a separate instruction: to reproduce the numbers on your own hardware, the file sends you to the readme inside the benchmark directory rather than describing a command here.
The NPU rows require an OpenCV you have to build yourself
The hardware table is the reason the repository still exists, and two of its rows cannot be reproduced with the pip install described above.
The Khadas VIM3 row, an Amlogic A311D with a five TOPS NPU, is measured with per tensor quantized models and tells you to follow a guide to build OpenCV with the TIM-VX backend enabled. The Atlas 200 DK row, an Ascend 310 with 22 TOPS at INT8, tells you to follow a different guide to build OpenCV with the CANN backend enabled. Both instructions point at the OpenCV wiki, not at anything in this repository.
So the prebuilt wheel and those two rows are mutually exclusive. To produce them you need a source build of OpenCV with a vendor backend compiled in, which is a different activity from installing a Python package and puts the result outside what the instructions above cover.
The same row also quietly changes the measurement. Quantization is called out on the VIM3 line, so those figures describe an int8 path while the desktop row describes whatever the models run as on a desktop CPU. Comparing a five TOPS NPU number with an x86 number is comparing two different things, and the table gives you the flag but not the warning.
Everything else in the ARM list, the VIM4, Edge 2, the second Atlas kit, both Jetsons, a Raspberry Pi, a Horizon board and two more, are listed without a note about needing anything extra built.
The RISC-V row has one tested model and a link to someone else's fork
Two RISC-V boards are listed, and one of the entries is a placeholder in all but name.
The StarFive VisionFive 2 has a JH7110 system on chip with a quad core RISC-V CPU that turbos to 1.5 GHz, and an Imagination IMG BXE-4-32 MC1 GPU running at up to 600 MHz. That entry is complete: chip, cores, clock, GPU, GPU clock.
The Allwinner Nezha D1 entry names a 1.0 GHz single core Xuantie C906 with the RISC-V vector extension version 0.7.1, then says that YuNet is the only model tested for now, and then points at a repository belonging to someone else for further detail. So the RISC-V row of a benchmark table is one model on one board, with the rest of the coverage living in a third party's fork.
That is stated plainly rather than hidden, which is the right way to write it, and it does mean the RISC-V section of the table cannot be used to say anything about RISC-V beyond one model. It also says the vector extension matters here: a model that assumes a scalar path and one that assumes vector instructions will not compile to the same thing on a C906.
The tree carries no code beyond the harness, scripts and configuration, so that pointer is the only route to the missing detail.
The timer includes preprocessing, batch size is one, and missing data is three hyphens
The notes under the table are short and they define the numbers, so anyone quoting them should read them first.
Each cell in the hardware columns is the elapsed time of one inference, and inference here means all three stages: preprocessing, the forward pass and postprocessing. So a row is not a model forward pass in isolation, it is the whole round trip, which is the number most people actually care about when they ask how fast a board is.
The time is the mean of ten runs taken after some warmup runs. Different metrics may be applied to some specific models, which is the one sentence in the notes that gives no specifics, so a handful of rows have an unstated measurement basis. Batch size is one for every result on show, which rules out any throughput claim: these are latency numbers for a single item, and the fast rows are fast because the image is small.
The sentinel is three hyphens, defined as meaning the model cannot be run on that device, and the definition is written in a line that also misspells available. Encoding absence as a string inside a numeric table is a small choice, and it is the right one for a table that mixes supported and unsupported across twelve boards.
Per model and per device configuration lives in the benchmark config directory, which is where you go to reproduce rather than guess.
PP-OCR is listed twice, and both entries point at one directory
The examples section runs through the model set, and one entry appears under two headings.
There is a heading for Chinese text detection with PP-OCR detection, and a separate heading for English text detection with the same model, and both link to `./models/text_detection_ppocr/`. So the same directory is presented twice as two capabilities, with the language difference carried entirely by the heading text.
The naming across the rest of the set is inconsistent in a way that reflects where the models came from. Some are named after a compact model identifier, as in face detection with YuNet, face recognition with SFace, licence plate detection with LPD_YuNet, object detection with YOLOX, and text recognition with CRNN. Others carry the name of a paper method, as with Progressive Teacher for facial expression recognition, PP-HumanSeg for human segmentation and EfficientSAM for image segmentation. Four are MediaPipe models with an abbreviated prefix, covering palm detection, hand pose, person detection and pose estimation.
So the list mixes vendor families, paper names and one consistent prefix from a single framework. Fine for browsing, awkward for scripting, because there is no naming convention to key off when you want to enumerate everything from one vendor.
Every model also has its own directory with more examples than the file shows, which is the part that stays useful when the weights live elsewhere.
Apache-2.0 covers the repository, and the weights keep their own terms
The licence section is two sentences and the second one is the important one. The repository is under the Apache 2.0 licence, and readers are referred to the licences of the different models.
That delegation matters more here than it would in a code repository. Apache-2.0 covers the harness, the scripts and the configuration, and it says nothing about a face detection network trained by someone else. Each model carries the licence of whoever trained or distributed it, and the file does not enumerate them, does not name a licence for any individual entry, and does not say where to look beyond the instruction to check.
So the practical sequence is: the repository licence tells you what you may do with the tooling, and every model you copy out of it needs its own check. For a zoo that hosts third party networks trained on third party datasets, that is the licence question that actually matters, and the file is honest about delegating it rather than pretending one licence covers everything.
The repository root is small and consistent with that split: attributes, ignore rules, the licence, the readme, and four directories, with the model directories holding both the weights and the per model demo code.
Editorial conclusion
opencv_zoo is worth using for the benchmark tables, which are the part that stayed, and for the per model demo scripts, which is the other part. Two things to check before you depend on it. If you need a model, follow the pointer at the top of the file to the Hugging Face organisation rather than cloning this repository, and remember that the weights arrive through git-lfs, so a plain clone leaves pointer files behind. If you need the numbers, read the measurement notes before quoting them: batch size is one, the timer includes preprocessing and postprocessing, and on the Khadas row the models are quantized, so those figures do not compare against the desktop row. And read the licence line last, since it covers the repository and tells you to check the licences of the individual models yourself.
Frequently asked questions
Where do I download models from opencv_zoo?
The file points to the OpenCV organisation on Hugging Face for models and online demos, and says the project is now hosted there. What remains in this repository is the per model demo scripts, the benchmark harness with its configurations, the reports and the tools.
How do I get the model weights in opencv_zoo?
Through git-lfs. The documented sequence is to install git-lfs, clone the repository, then run git lfs install followed by git lfs pull. Without that pull step the weight files are pointers rather than the actual files.
What do the opencv_zoo benchmark numbers measure?
The elapsed time of a single inference covering preprocessing, the forward pass and postprocessing, at batch size one. Each figure is the mean of ten runs after warmup runs, and a cell containing three hyphens means the model cannot be run on that device.
Can I reproduce the NPU benchmarks in opencv_zoo with pip?
Not for the rows that need a vendor backend. The Khadas VIM3 row requires OpenCV built with the TIM-VX backend and the Atlas 200 DK row requires the CANN backend, each with a separate build guide in the OpenCV wiki. The VIM3 row is also measured with per tensor quantized models.
What licence applies to the opencv_zoo models?
The repository is licensed under Apache 2.0, and the file says to refer to the licences of the different models. Individual model directories therefore carry whatever terms their authors set, and those terms are not enumerated in the repository.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Lens It: Find Yourself in Every Event Photo With One Selfie, Without a Face Ever Leaving the Roomdev.to · Oct 18, 2026 · 2 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/opencv-opencv-zoo)Star history chart for your README
[](https://hysenlabs.com/projects/opencv-opencv-zoo)Was this useful?