NASA-CMR-STAC ships two files and calls one of them a CSV
A list of geospatial datasets on NASA's Common Metadata Repository (CMR)
At a glance
- What is it?
- A daily regeneration of every geospatial dataset on NASA's Common Metadata Repository into a tab separated file and a JSON file, small enough that the whole dependency surface is one line in requirements.txt and honest enough to be checked in a minute.
- Who is it for?
- NASA-CMR-STAC is worth pinning if you need a plain file listing rather than a live API call, since the daily regeneration means you can cache a snapshot and diff it against the previous day. Check the file dates before you trust it, because the freshness guarantee is a sentence in the README rather than a version number, and the repository publishes no releases.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
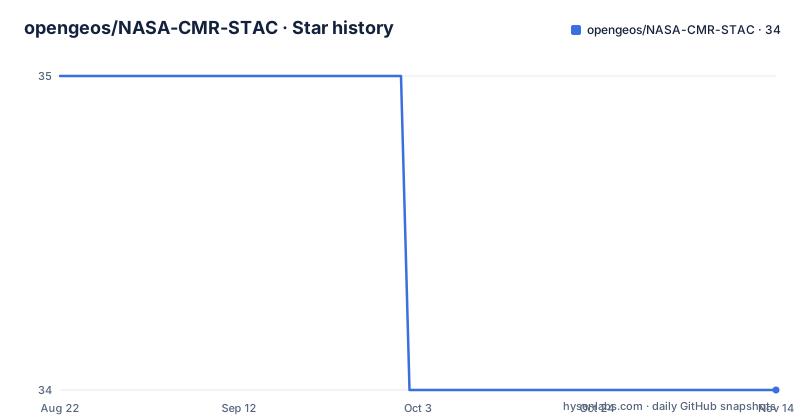
- opengeos/NASA-CMR-STAC34 ★ · -1
| Repository | 2026-08-22 | 2026-11-14 |
|---|---|---|
| opengeos/NASA-CMR-STAC | 35 | 34 |
-1 Stars in the last 84 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two files, regenerated daily out of a metadata catalog
NASA's Common Metadata Repository is a metadata catalog of NASA Earth Science data, and this repository compiles the list of all geospatial datasets available through CMR-STAC, the spatio-temporal asset catalog form of it. The output is deliberately plain: one tab separated file and one JSON file, with the stated purpose of making the catalogue easier to find and use programmatically rather than forcing every consumer to query the service. The list is updated daily, which is the whole contract. In the tree those two artefacts are `nasa_cmr_catalog.tsv` and `nasa_cmr_catalog.json`, sitting next to the notebook and script that generate them. There is no API wrapper, no rate limit to design around and no authentication, which is both the appeal and the limit of the approach.
The introduction says CSV and the usage section says TSV
The document describes the output twice and does not agree with itself. The introduction says the list is compiled as a CSV file and as a JSON file, while the usage section calls the first artefact a tab separated values file and links it with a `.tsv` extension. The example settles it in favour of TSV, because the read call passes a tab separator explicitly:
import pandas as pd

url = 'https://github.com/giswqs/NASA-CMR-STAC/raw/master/nasa_cmr_catalog.tsv'
df = pd.read_csv(url, sep='\t')
df.head()
That distinction is not cosmetic. A reader who follows the introduction and lets pandas sniff the separator will land in the wrong parsing mode, because `read_csv` defaults to a comma and a comma-separated guess on a tab-separated file produces one very wide column rather than an error. Anyone writing their own loader should copy the separator from the example rather than the wording from the introduction.
GitHub calls it a notebook, and the tree holds both a notebook and a script
The repository's primary language is recorded as Jupyter Notebook, which points at how the catalogue is actually built. The tree contains `nasa_cmr_catalog.ipynb`, which is also what both the Colab and Binder badges point at, and next to it a plain `nasa_cmr_catalog.py`. That is two copies of the same generation logic in the same directory, which is the usual trade for a notebook-first repository: the notebook is the readable version and the script is the one a scheduler can run without a Jupyter kernel. The daily update implies something outside this repository runs one of them on a timer. There is no `tests/` directory and no CI configuration beyond `.github/`, so nothing in the repository checks that the generated files match the script, which is also why the freshness claim has to be taken on trust.
The entire dependency surface is one unpinned line
`requirements.txt` contains exactly one package:
leafmapNo version constraint, no lock file, no second entry. That is worth pausing on, because the repository description says it is a list of geospatial datasets and the primary language suggests plotting and mapping work, yet nothing in the declared dependencies covers HTTP requests or JSON parsing beyond what leafmap pulls in itself. For a file this simple that may be sufficient, since the pipeline is read a catalogue and write two files, but it also means there is no pinned environment to reproduce the daily run in. If you depend on the output, copy the file rather than the script, or pin `leafmap` yourself, because an unpinned single dependency is the kind of thing that changes under you between one regeneration and the next.
Every link in the document points at a different organisation
The repository is hosted under `opengeos`, and every URL inside the README points at `giswqs`. That includes the Colab badge, the Binder badge, the raw TSV URL in the pandas example, and all eight entries in the related projects list. The likely explanation is an account rename or a fork, but the practical effect stands either way: running the example exactly as printed fetches the catalogue from another account, and if that account stops publishing or drifts, your copy of the notebook keeps working against stale data while this repository looks fine. Two things follow. If you copy the snippet, rewrite the URL to this repository. And if you rely on daily freshness, check the file's own date rather than the repository's last commit, since the two can diverge.
One cell in a grid of catalogues built the same way
The related projects section lists eight repositories from the same author, and the pattern is consistent: take one place geospatial data is catalogued, flatten it into a file, publish it. `aws-open-data` and `aws-open-data-geo` cover open datasets on AWS, and `aws-open-data-stac` is the same list with a STAC endpoint attached. `stac-index-catalogs` collects STAC endpoints from stacindex.org, `Planetary-Computer-Catalog` covers Microsoft Planetary Computer, and `Earth-Engine-Catalog` covers Google Earth Engine. `geospatial-data-catalogs` is an index of these catalogues rather than a catalogue itself. Read as a group, they are a reasonable substitute for querying each provider's API: a flat file you can diff, cache and grep, refreshed on the maintainer's schedule rather than the provider's.
A datasets/ directory the README never mentions
The tree holds one directory that the document does not describe at all:
datasets/Everything else at the root is accounted for: the two catalogue files, the notebook, the script, `requirements.txt`, `LICENSE`, `README.md`, `.gitignore`, `.vscode/` and `.github/`. `datasets/` is either where intermediate output lands or a placeholder, and either way it is the thing to look at first if you want to know what else the pipeline produces. The project metadata is quiet: MIT licensed, 35 stars, 5 forks, no open issues, no GitHub releases, and a default branch called `master`. The last push landed on 30 September 2026, so the files are being regenerated, but with no releases there is no way to pin a specific snapshot of the catalogue by version.
Editorial conclusion
NASA-CMR-STAC is worth pinning if you need a plain file listing rather than a live API call, since the daily regeneration means you can cache a snapshot and diff it against the previous day. Check the file dates before you trust it, because the freshness guarantee is a sentence in the README rather than a version number, and the repository publishes no releases. When you run the example, note that the URL points at the giswqs organisation rather than opengeos, so the snippet as written fetches from a different account than the one hosting it.
Frequently asked questions
What is NASA's Common Metadata Repository (CMR)?
It is a metadata catalog of NASA Earth Science data. This repository compiles the list of all geospatial datasets available through CMR-STAC, the spatio-temporal asset catalog form of that service.
What format is the NASA-CMR-STAC dataset in?
Two formats: a tab separated values file at nasa_cmr_catalog.tsv and a JSON file at nasa_cmr_catalog.json. The introduction calls them a CSV file and a JSON file, but the shipped file is tab separated and the example reads it with sep='\t'.
How often is the NASA-CMR-STAC list updated?
Daily. The repository compiles the list from NASA's Common Metadata Repository and regenerates the files, and there are no GitHub releases to pin a specific snapshot by.
How do I load the NASA-CMR-STAC catalogue into pandas?
Read nasa_cmr_catalog.tsv with pandas and an explicit sep='\t'. The example in the README fetches the raw file over HTTP and calls df.head(), and the URL it prints points at the giswqs organisation rather than opengeos.
What dependencies does NASA-CMR-STAC need?
requirements.txt lists a single package, leafmap, with no version pin and no lock file. The generated catalogue is the portable artefact, so copying the file is safer than reproducing the pipeline.
Are there other catalogue projects like NASA-CMR-STAC?
Seven are listed: aws-open-data, aws-open-data-geo, aws-open-data-stac, stac-index-catalogs, Planetary-Computer-Catalog, Earth-Engine-Catalog and geospatial-data-catalogs, which indexes the others.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/opengeos-nasa-cmr-stac)Star history chart for your README
[](https://hysenlabs.com/projects/opengeos-nasa-cmr-stac)Was this useful?