Memind's default stack pairs SQLite with a JSON vector store and a reranker that does nothing
Self-evolving cognitive memory and context engine for AI agents in Java. Empowering 24/7 proactive agents like OpenClaw with understanding and SOTA performance.
At a glance
- What is it?
- Memind is a Java memory and context engine for AI agents, built as a multi-module Maven project with a Docker Compose path as its recommended entry. Its shipped defaults are the interesting part: a placeholder API key that still boots the server, a JSON file standing in as the vector store, and a blank reranker key that leaves deep retrieval unranked.
- Who is it for?
- Read Memind as an architecture reference rather than something to drop into production unchanged. The layer design is more instructive than the ranking headline suggests, and the defaults are unusually candid about their own limits.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 94 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
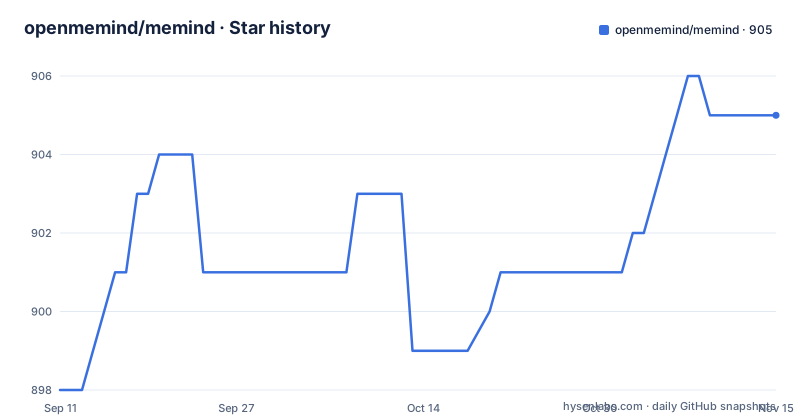
- openmemind/memind905 ★ · +7
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| openmemind/memind | 898 | 905 |
7 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Docker Compose boots the server with a placeholder API key
Copying the example environment file is the entire setup step on the recommended path:
cp .env.example .envFour values decide what the container talks to, and the defaults point at a router rather than a vendor:
OPENAI_API_KEY=your-api-key
OPENAI_BASE_URL=https://openrouter.ai/api
OPENAI_CHAT_MODEL=openai/gpt-4o-mini
OPENAI_EMBEDDING_MODEL=openai/text-embedding-3-small
The compose file fills each of those from your shell environment with the same fallback, and in two cases nests one default inside another so the embedding key inherits the chat key and the embedding base URL inherits the chat base URL. The service itself is built from context . with dockerfile memind-server/Dockerfile and tagged memind-server:local, so a rebuild is a local image rather than a pull. That placeholder key is not a guard. The comment sitting above those values spells out the behaviour: the default placeholder starts the service, but real memory extraction, retrieval, and embedding calls require valid provider credentials. So a fresh clone reaches a listening server on port 8366 carrying a key that cannot bill anything, and the first extraction request is where the mismatch surfaces.
The vector store is a JSON file next to the SQLite database
Two variables decide where state lives, both under the data directory. MEMIND_DATASOURCE_URL resolves to jdbc:sqlite:/app/data/memind-server.db and MEMIND_VECTOR_STORE_PATH resolves to /app/data/vector-store.json. Read the second one literally: similarity search, one of the layers the retrieval story rests on, is backed by a JSON document on disk rather than a separate vector database service. The payoff is that there is no second process to provision, no connection string to keep alive, and nothing extra to back up. The cost is that this whole tier is a file, so whatever your load volume is, that file is where it lands. The project is explicit that it is not a vector store wrapper, and the graph, thread, and insight layers sit above that file rather than beside it. The repository is laid out to match that separation: memind-core, memind-server, memind-ui, memind-plugins, memind-integrations, memind-clients, memind-dependencies, memind-examples, and two evaluation directories sit alongside a pom.xml, plus a .claude-plugin directory at the root.
Deep retrieval's reranker is a no-op until you supply a key
Deep retrieval is described as query expansion, sufficiency checking, and reranking. Two of those three run locally. The third is a remote HTTP call, and it ships switched off. Three variables control it: MEMIND_RERANK_BASE_URL, MEMIND_RERANK_API_KEY, and MEMIND_RERANK_MODEL. The example environment sets the base URL to https://aihubmix.com and the model to jina-reranker-v3 while leaving the key blank, and the comment attached to that blank line states that it keeps the default no-op reranker. Two consequences follow. The reranking half of the deep retrieval path is a pass-through in an out-of-the-box install, so a quality comparison run without adding credentials is not measuring the documented pipeline. And the gateway host is a specific third-party service baked into the default rather than a neutral placeholder, which is one more endpoint to review before a deployment.
Five provider keys ship empty and only matter if you write the beans
The example environment reserves keys for DeepSeek, GLM, Anthropic, Gemini, and SiliconFlow, and the compose file carries all five with empty defaults. The comment above them is precise about their role: they exist for additional Spring AI beans that you define for advanced model routing. Nothing in the shipped server consumes them on its own, so setting a key is half the work and declaring the bean yourself is the other half. The route named for that wiring is Spring AI's OpenAI provider path, which is also the path described as the way OpenRouter, DeepSeek, GLM, and SiliconFlow can be used when they expose an OpenAI-compatible API. The only other value the example file sets beyond those keys is a chat temperature of 0.2.
The ranking claim is bounded to a baseline list the overview never shows
Every highlight leads with state of the art results across LoCoMo, LongMemEval, and PersonaMem. The second bullet narrows that to a protocol and a scope: under aligned MemOS / EverMemOS-style evaluation, memind ranks number one among the listed baselines, surpassing EverMemOS on LoCoMo and LongMemEval and exceeding MemOS on PersonaMem. Both qualifiers carry weight. The comparison is described as style-aligned rather than run on an identical harness, and the ranking is scoped to baselines the project chooses to list rather than to the field. The sections above the benchmark contain no scores from any of those baselines, and no benchmark table of its own, so the numbers that back the headline live entirely in the Benchmark section that the navigation links to by anchor.
The quick start stops mid-sentence on model names
Configuration guidance ends abruptly. The text explains that the default Spring AI OpenAI configuration can point at OpenAI or any OpenAI-compatible endpoint by changing the base URL and the model names, names OpenRouter, DeepSeek, GLM, and SiliconFlow as providers reachable through that shape, and then breaks off partway through a line: If you use OpenAI directly, use OpenAI model names. Nothing completes it. The values that ship in the example environment are router-style model names paired with a router base URL, so they agree with each other and with nothing else. A reader who swaps the base URL to OpenAI is told to change the model names without being told which names to use, which is the one gap a reader of the quick start is most likely to hit. The Benchmark section that the page navigation links to sits past this point as well. A Chinese edition of the same file sits next to it as README_zh.md, and the same break appears in the Compose file, where MEMIND_RERANK_MODEL is cut off partway through its default value.
One engine, two memory audiences, and three structures above them
The design keeps USER memory and AGENT memory apart inside one system. User profiles, preferences, relationships, and life events sit beside agent directives, tool experience, playbooks, and resolved-task knowledge, and the same engine is aimed at coding agents, local personal agents, chatbots, workflow agents, and copilots at once. Above both audiences sit three structures doing work a flat store cannot. Insight Trees distil raw memories into leaf, branch, and root levels so patterns and preferences surface instead of isolated facts. Memory Graphs materialise entities, mentions, semantic, temporal, and causal links, aliases, and co-occurrence signals, then expand from them to recover context that similarity alone misses. Memory Threads group related items into durable episodes with timeline events, memberships, and lifecycle state so unfinished work can be resumed. Retrieval reads across all of these plus BM25 keyword search and temporal signals.
Editorial conclusion
Read Memind as an architecture reference rather than something to drop into production unchanged. The layer design is more instructive than the ranking headline suggests, and the defaults are unusually candid about their own limits. Before adopting it, verify three things: that your provider keys and model names line up with the router-style defaults the example environment ships, that a JSON file on disk is the vector store your data volume actually needs, and that an empty reranker key has not been quietly returning unranked results in your own evaluations. There is one published release, 0.2.0, and the project is Apache-2.0, so reading the source carries no licensing friction.
Frequently asked questions
What does Memind store, and how is it different from a plain vector database?
It captures raw context from conversations, documents, images, audio, tool calls, agent timelines, and resolved tasks, then turns that into user memory, agent experience, insight trees, memory graphs, and memory threads. In the shipped Compose configuration the storage is one SQLite file plus a JSON file used as the vector store.
Do I need a real model provider key before the Docker Compose server starts?
No. The example environment ships a placeholder key, and the service starts on port 8366 with it. Memory extraction, retrieval, and embedding calls need valid provider credentials, so the failure shows up on the first real request rather than at boot.
Is the reranker active in Memind's default configuration?
No. The example environment leaves MEMIND_RERANK_API_KEY blank, which keeps the default no-op reranker, so the reranking step of deep retrieval passes results through until you add a key for the configured gateway at https://aihubmix.com.
How many Memind releases are published?
One: version 0.2.0, published on 2026-08-13, the same day as the most recent push to the main branch.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openmemind-memind)Star history chart for your README
[](https://hysenlabs.com/projects/openmemind-memind)Was this useful?