OpenVINO notebooks keeps branches per release, and calls the wrong one main
📚 Jupyter notebook tutorials for OpenVINO™
At a glance
- What is it?
- A collection of runnable tutorials for an inference toolkit, versioned by branch so that the current release, the previous release and the previous long term support release are all reachable. Its upgrade instruction points at a requirements file containing nothing but Jupyter packages, its system requirements table sends two cells to the same wiki page, and its container installs two packages by direct URL.
- Who is it for?
- This suits a developer who wants to run an example before installing an inference toolkit on their machine, and who can pick the branch matching the toolkit version they already have. It does not suit someone who wants one supported path, because the repository is three releases deep in branches and the guidance for moving between them is one sentence each.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
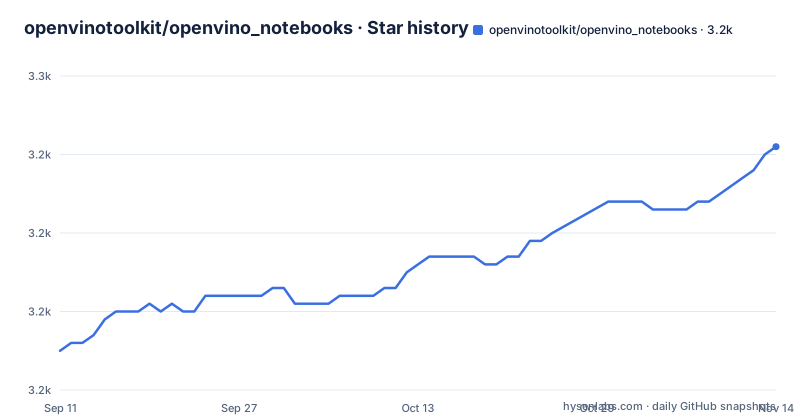
- openvinotoolkit/openvino_notebooks3,241 ★ · +26
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| openvinotoolkit/openvino_notebooks | 3.2k | 3.2k |
26 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The upgrade instruction points at a file that lists only Jupyter
There is one upgrade instruction in this readme and it is worth reading closely.
It says the main branch was updated to support the current toolkit release, and that to move to the new release you should run a package upgrade against the requirements file, inside your named virtual environment.
That requirements file has four entries, and all four are Jupyter: the notebook lab itself, the widget library, a kernel package pinned to one exact version, and the interactive shell with a floor.
The toolkit itself is not in it. Neither is the model compression library that the build file installs. So the file a user is told to run when upgrading a toolkit release is a file that contains no toolkit.
That is not necessarily wrong. The toolkit comes from the platform guides in the wiki, one per operating system, and the requirements file is there so that the notebook environment exists at all. But it means the sentence reads as though upgrading the toolkit is a matter of upgrading four Jupyter packages, and a user who follows it will get a working notebook environment with the old toolkit still in it.
The other requirement file in the repository, in the continuous integration directory, is a different set again and is what the build actually installs.
The default branch is named latest, and the documentation calls it main
This repository does not use the usual branch names, and it does not use them consistently.
The default branch is named latest, not main. Three separate places say otherwise. The upgrade note calls it the main branch. The container's metadata records a build source reference of main. And the readme offers a fallback: if you want the previous release, check out the branch named after that release, and if you want the previous long term support release, check out the branch named after it.
So the branches in use are: latest for the current release, one named for the release immediately before it, and one named for the last long term support release. That is three releases of notebooks kept alive as parallel branches, which is a heavier commitment than it looks and explains why the upgrade note exists.
The naming is also why the mismatch survived. Nothing points at a branch called main, so an instruction referring to main cannot be checked by following it, and a build metadata field recording main cannot be validated against the repository. Both are one word that should have been the default branch name.
For a user, the practical effect is that the branch name in the note is wrong and the branch names in the fallbacks are right.
Two cells of the requirements table point at the same page
The installation section is a single row of eight links, one per environment, and two of them are the same destination.
There are separate cells for a Red Hat distribution and for CentOS, and both open the same wiki page, whose address contains both distribution names. So the table presents a choice where there is one guide.
The other six cells do point at distinct guides: Windows, Ubuntu, macOS, a hosted machine learning service, a container route, and a managed notebook service. That is a sensible spread, covering the local platforms plus the two ways people actually try things without installing anything.
The requirements table below it is a separate thing and does not overlap. It lists seven operating systems with a Python version range, and the range is identical for every row: 3.10 to 3.13, on 64-bit builds only.
So there are two coverage tables a few paragraphs apart. One is eight links for installation, with a duplicate. The other is seven platforms with versions, with no duplicates. Neither cross-references the other, and the Python range is stated once and then repeated seven times rather than being named once for the whole table.
The image installs two packages by direct URL from third-party mirrors
The container file is long and careful in most places, with two details that would make a reviewer stop.
First, it installs two packages by fetching them straight from a mirror URL rather than from a configured repository. One comes from a package mirror for the Fedora ecosystem's extra packages, the other from a CentOS Stream mirror. Both are pinned to exact package filenames including the distribution version in the path.
The surrounding installs are all done properly through the system package manager with a repository added for the vendor's GPU stack. So the two direct downloads stand out: they are the only artefacts in the image that depend on a mirror somebody else controls remaining at that path.
Second, there is a comment in the build file marking a version declaration as temporary, saying it should be removed once the information is available in a later version of the distribution. That is a known-fragile spot left in place with a note, which is better than leaving it undocumented.
Two more details are ordinary: the build runs once as root to install system packages and then drops to an unprivileged user for the rest of the image, and the Python packages come from a lock file copied in from a subdirectory and deleted immediately after installation.
The build downloads the toolkit wheels and then uninstalls them
The build file has a step that looks wrong until you read it as a whole, and it is the most interesting thing in the repository.
The step creates a package cache directory, upgrades the installer, and then installs two packages into the virtual environment with caching enabled and dependency resolution disabled. It then copies the cache directory to a second location beside it, and finally uninstalls both packages from the environment.
So the toolkit and the model compression library are downloaded, stashed, and removed. The packages end up in a directory in the repository rather than in the environment that built the notebooks.
That makes sense for a conversion pipeline whose job is to turn notebooks into a published form: the packages have to be available at run time for the reader, and keeping them out of the build environment keeps the environment small and reproducible. It also means the published notebooks depend on a cache directory rather than on a declaration.
The rest of the build is ordinary and well ordered: create the environment, install the development requirements from a file in the continuous integration directory, register the environment as a notebook kernel under a fixed name, print the frozen package list for the record, and run a script that checks the installation. Only then does it convert the notebooks, through a shell script in the same directory.
Two CI systems, and a workflow file with a typo in its name
There are two continuous integration systems configured in this repository, and one of them has a misspelled name.
The GitHub side has a workflow whose file name appears to be a transposition of the words for the tool it runs, followed by the word for commit. Whatever it was meant to be called, it is the link the readme's badge points at, so the typo is the one everybody sees.
The second workflow builds the container image, which matches the Dockerfile discussed above.
And then there is a build file at the root in the older pipeline style, alongside a make file. So a notebook in this repository can be produced by either of two systems, and the readme's badge links only to the newer one.
That is a maintenance cost rather than a defect. Two pipelines is common in repositories that predate hosted runners, and the older one is often kept precisely for the tasks hosted runners cannot do.
What is worth noticing is the naming. A repository this size, with three release branches to keep in step, has one CI badge, two pipelines, and a workflow file whose name nobody corrected, which suggests the continuous integration configuration is maintained by the same small group as the notebooks rather than by a dedicated owner.
The free hosted notebook services are documented as slower
There is one recommendation in the readme about where to run the notebooks, and it is unusually blunt for a tutorial collection. Launching one notebook is a single command naming its path from the repository root, and browsing all of them is the same tool pointed at the notebooks index file:
jupyter lab notebooks/README.mdNotebooks carrying a button for one free hosted notebook service, or for a hosted service that runs in a browser, can be executed with nothing installed. And those services are described as free with limited resources. The readme then tells you that for the best performance you should follow the installation guide and run the notebooks locally.
So the project positions itself in two places at once: a zero-install path for trying something, and a locally installed path for actually measuring anything.
That is the correct framing for a set of notebooks about inference, where the whole point of many of the examples is speed, and a shared hosted machine cannot tell you anything about performance. It is also why the interactive site and the binder configuration both exist, and why the readme repeats the advice in the same paragraph as the zero-install option rather than burying it.
One related detail: the repository carries a directory whose only purpose is holding the model files the notebooks fetch, and a selector directory that drives the interactive notebook browser on the project's published site.
Editorial conclusion
This suits a developer who wants to run an example before installing an inference toolkit on their machine, and who can pick the branch matching the toolkit version they already have. It does not suit someone who wants one supported path, because the repository is three releases deep in branches and the guidance for moving between them is one sentence each. Before you start, check three things: which toolkit release you need and therefore which branch you should read, since the previous release and the previous long term support release live on their own branches; whether you will run locally or on one of the two free hosted notebook services, which the documentation says are slower; and what the two thin requirements files actually install, because neither is where the toolkit comes from.
Frequently asked questions
What is the purpose of OpenVINO?
In this repository's terms, the toolkit exists for optimized deep learning inference, and these notebooks exist to teach its API. The collection describes itself as introducing the basics and showing developers how to use that API, with the material organised as ready-to-run notebooks per task, browsable through an interactive site or launched one at a time from a notebook lab.
Is OpenVINO only for Intel?
The repository does not answer that. What it documents is a system requirements table covering two Linux distributions, a third-party Linux distribution, macOS, two Windows editions and Windows Server, plus eight installation guides that include a container route and two hosted machine learning services. The container image is Intel-branded and installs that vendor's GPU runtime, but the repository makes no claim about hardware support.
How do I run the OpenVINO notebooks?
Two documented ways. To launch one notebook, run the notebook lab against that notebook's path from the repository root. To browse everything, run the notebook lab against the notebooks index file so the directory listing opens first. Both need the notebook environment installed, whose requirements file contains only Jupyter packages. Alternatively, notebooks carrying a hosted-service button can be run with nothing installed at all, at the cost of limited resources.
How do I get the OpenVINO notebooks for an older toolkit release?
By choosing a different branch. The current release is on the branch named latest, the previous release on a branch named after it, and the previous long term support release on its own branch. The readme's upgrade note describes the current one as the main branch, which is a naming error, so follow the branch names given for the older releases rather than that sentence.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openvinotoolkit-openvino-notebooks)Star history chart for your README
[](https://hysenlabs.com/projects/openvinotoolkit-openvino-notebooks)Was this useful?