Fifty half-hour sessions that converge on one artifact, and three unpinned installs
A 10-week, 30-minutes-a-day roadmap for LLM inference serving and optimization. vLLM, SGLang, quantization, speculative decoding, benchmarking.
At a glance
- What is it?
- A reading-and-building curriculum for LLM inference serving, ordered around the roofline model rather than around tools. It schedules its measurements before its optimizations, tells you which parts not to rebuild, and ends by asking you to publish a benchmark with pinned versions.
- Who is it for?
- Follow this roadmap if you are an engineer who knows the transformer architecture and the command line but has never run a serving stack, and you can rent a GPU by the hour for a couple of months. Three things to weigh first.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 93 days ago.
- What is it written in?
- Mainly HTML, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
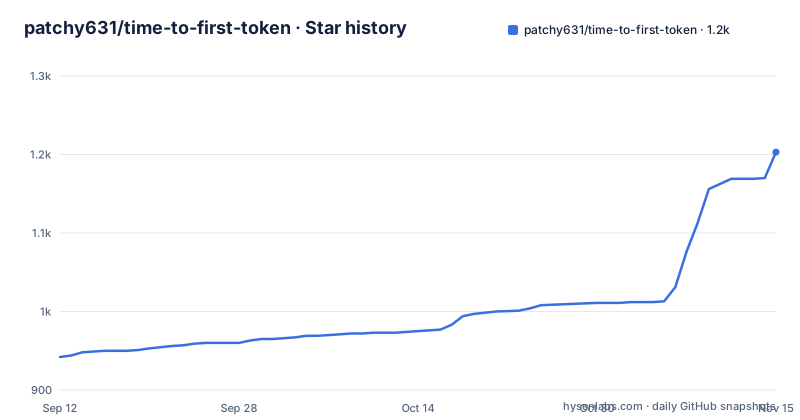
- patchy631/time-to-first-token1,203 ★ · +261
| Repository | 2026-09-12 | 2026-11-15 |
|---|---|---|
| patchy631/time-to-first-token | 942 | 1.2k |
261 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Every session feeds the same service
The plan's structure is unusual and deliberate. All fifty sessions feed a single artifact: an OpenAI-compatible inference service, deployed on a rented GPU, instrumented, load tested past a thousand concurrent requests, optimized with quantization and speculative decoding, put behind a cost-aware router, and finally published as a reproducible benchmark. The argument against it is stated in the same breath as the alternative: seventeen disconnected experiments, which spend most of their time on setup and leave you with nothing to show. The seventeen is asserted rather than evidenced, but the shape of the claim is the interesting part. The argument is not that one project covers more ground, it is that a growing service gives you somewhere to put every measurement you take, which is the difference between an experiment and a system.
Fifty sessions of thirty minutes, and the arithmetic holds
The time budget is stated as a table and it adds up. Sessions are thirty minutes, there are five a week plus two buffer days, and the total is ten weeks, fifty sessions and twenty-five hours. Twenty-five hours is the whole commitment, and the plan is explicit that it is small: thirty minutes a day, with the buffer days existing so that missing a Tuesday does not collapse the schedule, and specifically not for new material. The hardware line is roughly one twenty-four gigabyte card rented by the half hour, plus two sessions on a much larger card. The plan also has a filter for people who already know some of it: sessions marked skim are the ones to compress, and the instruction for the build sessions is that they are the point and should not be compressed.
Measurement is scheduled in week three and load testing in week five
The ordering decision that matters most is that instrumentation lands in week three and load testing in week five, well before any tuning knobs are turned. The stated reason is that nothing after those two sessions is verifiable without them, and the second sentence is the one worth remembering: a public benchmark is mostly a credible measurement harness with a model attached. So the plan is not really about serving, it is about building the thing that makes a claim checkable, and doing it early enough that every later optimization lands inside a harness rather than inside a notebook. The deliverable list follows the same logic. The dashboards are named explicitly: time to first token, inter-token latency, throughput, queue depth and cost per request, which is five numbers rather than a single latency figure, and the load test harness is required to be reproducible at a thousand concurrent requests.
Two topics are declared not-build-exercises
The plan rules out two assignments on purpose. Paged attention and continuous batching are implemented in the serving engine the plan already uses, and chunked prefill is named as the default scheduling strategy in both that engine and the other one it uses. The argument is that reimplementing them teaches less than reading them, and it names what reading them should produce: being able to explain, from the code rather than from a diagram, why memory waste drops below four percent and why the GPU stops idling between requests. That is a much sharper definition of done than a working implementation, and it is a useful reminder for anyone who arrives at week two planning to rebuild the scheduler in a weekend.
The roofline plot is the index for four later topics
The first week is the roofline model, and four later topics are then positioned on it. Quantization attacks the bandwidth-bound side of decode. Continuous batching raises arithmetic intensity toward the compute roof. Speculative decoding spends arithmetic operations, which the plan describes as cheap in the memory-bound regime, in order to cut sequential memory loads. Disaggregation exists because prefill is compute-bound and decode is bandwidth-bound, so the two phases fight over one GPU. Once that plot is in your head, each of those four is a move on a chart rather than a technique to memorise, which is the stated purpose and, more importantly, the reason for putting the model first rather than the tooling. The plan's own summary of what happens without it is that the rest becomes a bag of tricks.
The GPU calendar is a scheduling document
Which sessions need hardware is worked out in detail, which is unusual for a reading list and makes it possible to do this without a cluster. A model in the seven to eight billion range needs roughly one twenty-four gigabyte card, and the instruction is to rent by the half hour and shut the instance down between sessions. The provider table distinguishes them by use: one for per-second billing and quick machines, one serverless option described as best for benchmark sweep scripts, one pair for cheap on-demand and marketplace cards, and a notebook environment for pure sessions where no serving happens. All of week one, most of week three, the lecture days of week six and all the reading in week nine need no card at all. One large card is needed for exactly two sessions: the thousand-concurrent test in week five, and the disaggregation work in week eight if you run it for real.
Edge deployment is week ten and shares nothing with the other nine
The last topic is optional and the reason given is structural rather than practical. Client-side and embedded runtimes, with three named, share almost no operational surface with the datacenter stack the other nine weeks build. That is the argument: you would be learning a second discipline, not a second deployment of the first, and the operational vocabulary, the failure modes and the measurement you have built do not carry over. It is also the only week where the plan tells you it is fine to read rather than build, so someone on a budget can skip it entirely without breaking the artifact that the other forty-nine sessions feed.
The three installs are unpinned and the final deliverable demands pins
The setup section is three lines long:
pip install vllm
pip install guidellm
pip install sglang
No versions, no constraints file, no lock. The plan also assumes Docker for the metrics stack and either a local cluster tool or a small managed cluster for week eight. Now put that next to the last item in the deliverable list, a published benchmark writeup with pinned versions and reproducible commands, and the tension is the whole curriculum in miniature. You are told to spend fifty sessions learning to make an optimization claim credible, and then handed an unpinned starting point that means your week one and your week ten may not be running the same engine. The progress tracker at the repository root, a plain markdown file, suggests the plan is meant to be worked through rather than merely read.
Editorial conclusion
Follow this roadmap if you are an engineer who knows the transformer architecture and the command line but has never run a serving stack, and you can rent a GPU by the hour for a couple of months. Three things to weigh first. It is a document, not software: there is nothing to install from this repository except three unpinned pip packages, which sits awkwardly beside a plan whose final deliverable is a benchmark with pinned versions. It spends ten of fifty sessions on topics it tells you to read rather than build, so the value depends on whether you actually open the block manager. And it spends real money: fifty sessions of hardware rental plus two sessions on the fastest card in the list.
Frequently asked questions
How long does the time-to-first-token roadmap take?
Ten weeks, fifty sessions of thirty minutes each, five sessions a week plus two buffer days, twenty-five hours in total. Buffer days are for catching up rather than new material, and the build sessions are explicitly not to be compressed.
What do I end up with after the ten weeks?
A serving stack you configured and instrumented, dashboards for time to first token, inter-token latency, throughput, queue depth and cost per request, a reproducible load test harness at a thousand concurrent requests, benchmarked variants, a cost and latency router, and a published writeup with pinned versions.
Do I need a big GPU for this roadmap?
Not for most of it. A seven to eight billion parameter model needs roughly one twenty-four gigabyte card, and the plan says which weeks need none at all. One much larger card is needed for exactly two sessions, the thousand-concurrent test and the disaggregation session.
Why does the roadmap tell me not to reimplement paged attention?
Because the serving engine already implements it, along with continuous batching, and chunked prefill is the default scheduling strategy in both engines the plan uses. The stated goal is reading the block manager and scheduler until you can explain from the code why memory waste falls below four percent.
What tools does the roadmap ask me to install?
Three pip packages named in the setup section with no version pins, plus Docker for the metrics and dashboard stack, and either a local cluster tool or a small managed cluster for week eight.
Is edge deployment part of the ten weeks?
It is the last week and it is optional. The three named runtimes are client-side and embedded, and the stated reason is that they share almost no operational surface with the datacenter stack built in the other nine weeks.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/patchy631-time-to-first-token)Star history chart for your README
[](https://hysenlabs.com/projects/patchy631-time-to-first-token)Was this useful?