Every Tribuo model and evaluation ships a provenance record, and three of its interfaces need native code
Tribuo - A Java machine learning library
At a glance
- What is it?
- Tribuo is Oracle's Java prediction library covering classification, regression, clustering, anomaly detection and multi-label tasks. What sets it apart from a plain algorithm collection is the provenance object attached to every artefact and the OLCUT configuration system, and what constrains it is platform reach on the native interfaces.
- Who is it for?
- Tribuo suits Java teams that need reproducible model builds from checked-in configuration files and an audit trail on every artefact. Verify before you commit that the machine learning interface you need is one of the three with native code, because support there is limited to the tested x86_64 platforms, and confirm your build runs Java 17 if you want the model card and reproducibility packages, which are outside the tribuo-all deployment.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 12 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
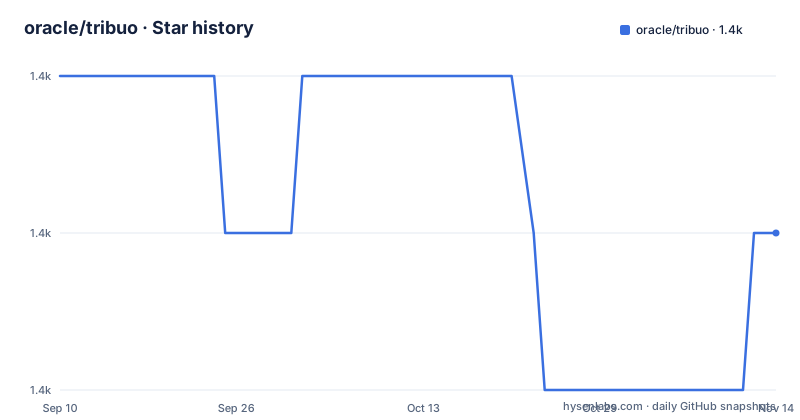
- oracle/tribuo1,417 ★ · -1
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| oracle/tribuo | 1.4k | 1.4k |
-1 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Provenance travels with the model and can be replaced by a hash
Every model and every evaluation produced by Tribuo carries a serializable provenance object, and the contents are specific. For a model it records the creation time, the identity of the data and any transformations applied to that data, plus the hyperparameters of the trainer that produced it. For an evaluation it also names the specific model that was evaluated. That record can be pulled out as JSON or serialized directly through Java serialization, so it can sit next to the model in a store or be shipped to a tracking system on its own. For production the text describes a redaction step: the provenance information can be stripped and replaced with a hash, which gives you model tracking through an external system without the original contents. That is the practical difference between this and a bare toString on a model, and it is why the feature is called out before the export formats are.
OLCUT moves the trainer out of Java code and into a repeatable config file
All trainers are configurable through the OLCUT configuration system, which is a separate Oracle project. The point is repeatability: a trainer can be defined in an xml or json file and then built again the same way, so the configuration becomes the artefact you version rather than the Java class that assembles it. Example configurations for each supplied trainer sit in the config folder of the package that contains it, which means the reference is per-algorithm and local rather than centralised in one place in the tree. The same configurations can also be written in json or edn, provided the matching OLCUT configuration dependency is added, so the file format is a dependency decision rather than a hardcoded constraint. Models and datasets are themselves serializable using Java serialization, so a trained artefact and the configuration that produced it can both be persisted without a separate format.
Three interfaces need native libraries, and two packages need Java 17
Tribuo runs on Java 8 and later and the library itself is pure Java, supported on all Java platforms, with testing on LTS versions and the latest release. That statement has two carve-outs sitting next to it. The first is native code. The interfaces to ONNX Runtime, TensorFlow and XGBoost require it, so those are supported only where native library support exists. Testing covers x86_64 on Windows 10, macOS and Linux on RHEL, OL or CentOS 7 and later, and for another platform the recommendation is to reach out to the developers of ONNX Runtime, TensorFlow or XGBoost. The second carve-out is packaging. The model card and reproducibility packages require Java 17, and for exactly that reason they are not part of the tribuo-all Maven Central deployment. A Java 8 project depending on tribuo-all therefore gets neither feature, silently, rather than through a compile error.
Regression output is multidimensional even when the model is not
Tribuo's regression algorithms are multidimensional by default, which is a different default from most libraries that return a single predicted number. Single dimensional implementations are wrapped in order to produce multidimensional output, so the wrapping layer, not the algorithm, is what fixes the output rank. The algorithm list follows the same shape as the classification one. Linear models and Factorization Machines are trained with SGD and accept any gradient optimizer, CART is implemented in Tribuo itself, Lasso uses the LARS algorithm, and Elastic Net uses co-ordinate descent. The remaining rows are wrappers around outside libraries: regularised linear models through LibLinear, SVM through LibSVM or LibLinear where LibLinear only supports linear SVMs, and gradient boosted decision trees through XGBoost. Only Linear models, Factorization Machines and CART are marked as Tribuo implementations in that table.
LIME explanations mix text and tables but stop short of images
For explaining classifier predictions, Tribuo implements LIME, and the implementation draws its boundary in three places. It allows mixing of text and tabular data in a single explanation, which is not something you get from a tabular-only explainer. It accepts any sparse model as the explainer, with regression trees and lasso named as examples, so the surrogate is not fixed to one family. What it does not support is images, and that exclusion is stated rather than left to be discovered. The surrogate choice interacts with the mixing capability: because the explainer can be a sparse model over the same feature space, a mixed text and numeric explanation is built from the same underlying model that made the prediction, rather than from a separate image pipeline that does not exist here. Explanations therefore cover the two data types Tribuo's loaders handle best and stop at the third.
Feature selection discretises your inputs into equal-width bins first
Tribuo carries a set of information theoretic feature selection algorithms for classification tasks, and the mechanism is worth stating before the names. Feature inputs are automatically discretised into equal width bins, so the algorithms score binned representations rather than the raw values. Equal width means the bin edges follow the numeric range of a feature, and a feature with a long tail spends most of its bins on values few rows ever take. That preprocessing is applied by the selection step itself rather than being something you configure. Four implementations are named: mutual information maximisation, abbreviated MIM, conditional mutual information maximisation, CMIM, minimum redundancy maximum relevancy, mRMR, and joint mutual information, JMI. They are applied to classification tasks specifically; the same table does not appear under regression, where the selection story is not described.
Ensembles and K-NN are task-agnostic, but their combiners are not
The ensemble and K-NN implementations in Tribuo are task agnostic: the same code handles classification, regression and the other prediction types. The output is not produced by that code directly. A combination function does it, and the combiners are prediction task specific, which splits the design in two places and is easy to misread from the outside. Tribuo ships voting and averaging combiners, and they are provided for multi-class classification, multi-label classification and regression tasks. The general predictor table shows what plugs into that arrangement. Bagging can use any Tribuo trainer as its base learner, Adaboost.SAMME can use any Tribuo classification trainer, K-NN includes options for several parallel backends as well as a single threaded backend, and neural networks come through the TensorFlow wrapper and can be deployed over either the ONNX interface or the TF interface. Random Forest and Extra Trees cover both classification and regression.
One Maven module per prediction task, and a release gap after 4.3.2
The repository layout mirrors the API. AnomalyDetection/, Classification/, Clustering/, MultiLabel/, Regression/, Reproducibility/, Data/, Interop/, Json/, Math/, Util/, Common/ and Core/ are separate top-level entries beside pom.xml, so a consumer can see from the tree which prediction types exist and pick modules rather than depend on everything. Around them sit distribution/, docs/, tests/, tutorials/, spotbugs-exclude.xml, sbom_generation.yaml, rebuild_protos.sh, SECURITY.md, CODE_OF_CONDUCT.md, CONTRIBUTORS.md and THIRD_PARTY_LICENSES.txt. The docs folder points at Architecture.md, PackageOverview.md, HelperPrograms.md, Internals.md, Roadmap.md and FAQs.md, and published Javadoc is kept for versions 4.3, 4.2, 4.1 and 4.0. Release timing is uneven: v4.3.2 shipped on 2025-04-04, more than two years after v4.3.1 on 2022-12-23 and v4.2.2 on 2022-10-25, while the last push to main is dated 2026-05-07.
Editorial conclusion
Tribuo suits Java teams that need reproducible model builds from checked-in configuration files and an audit trail on every artefact. Verify before you commit that the machine learning interface you need is one of the three with native code, because support there is limited to the tested x86_64 platforms, and confirm your build runs Java 17 if you want the model card and reproducibility packages, which are outside the tribuo-all deployment. Pass on it if you would rather ship a model to another runtime and have nothing to say about how it was produced.
Frequently asked questions
How do you configure a Tribuo trainer without writing Java?
Through the OLCUT configuration system, which lets a trainer be defined in an xml or json file and built the same way each time. Example configurations for each supplied trainer live in the config folder of the package that provides it, and json or edn can be used with the matching OLCUT dependency.
Which platforms can Tribuo run on?
Tribuo runs on Java 8 and later and the library itself is pure Java, supported on all Java platforms. The ONNX Runtime, TensorFlow and XGBoost interfaces need native libraries and are tested on x86_64 with Windows 10, macOS, and Linux on RHEL, OL or CentOS 7 and later.
Can a Tribuo model be exported for another language or platform?
Many Tribuo models export in ONNX format for deployment in other languages, platforms or cloud services. Neural networks trained through the TensorFlow wrapper can additionally be deployed over the TF interface, so there is a second route for that family.
Why do the Tribuo model card and reproducibility features not appear in a Maven build?
Both require Java 17, so neither is part of the tribuo-all Maven Central deployment. A project on Java 8 that depends on tribuo-all gets the rest of the library without those two packages.
How recently has Tribuo been updated?
The newest release listed is v4.3.2 from 2025-04-04, which came more than two years after v4.3.1 on 2022-12-23. The last push to the main branch is dated 2026-05-07, and published Javadoc exists for 4.3, 4.2, 4.1 and 4.0.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/oracle-tribuo)Star history chart for your README
[](https://hysenlabs.com/projects/oracle-tribuo)Was this useful?