Oxylabs Agent Skills: five product skills and two disagreeing env schemas
Official Agent skills of Oxylabs products
At a glance
- What is it?
- A repository of markdown that teaches an agent how to call a commercial proxy, unblocking, scraping, browser and video service. The routing guidance is sensible and the licensing question is yours. The credential names in the readme and the example environment file are not the same, which is the practical trap.
- Who is it for?
- These skills are worth reading if you already pay for one of the Oxylabs products and want an agent to drive it correctly, since the routing table and the small-request-first instruction are the useful parts. Skip them if you are looking for a free scraping tool, because every one of them needs a vendor account.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
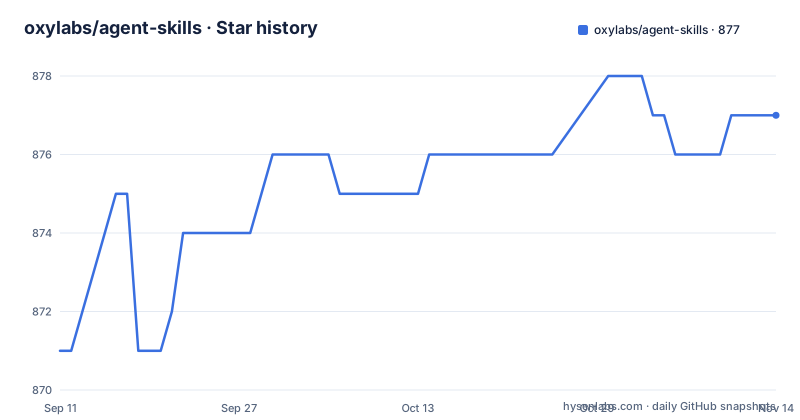
Star history
- oxylabs/agent-skills877 ★ · +6
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| oxylabs/agent-skills | 871 | 877 |
6 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Five skills, and a routing table that tells you not to overreach
The repository is five skills, each one a directory with a markdown instruction file, and the readme's most useful content is the routing table that sits between the catalogue and the install instructions.
The routing advice is short and correct: start with the most specific product that fits the task, validate one small request first, confirm the authentication, the status and the expected output, then scale with explicit limits. That is close to the opposite of how most agent instructions are written, and it is the right instinct for a paid API where a mistake costs money.
The five products cover distinct jobs. Raw proxy traffic with your own HTTP client, authentication, IP rotation and sticky sessions is one. Fetching a protected page without driving a browser is another. Structured JSON from supported targets, search results and commerce pages is a third. Clicks, forms, screenshots and browser automation belong to the fourth. Video metadata, subtitles, search and downloads belong to the fifth.
The split matters because the products bill and fail differently. A proxy session that retries indefinitely costs more than a scraper call that returns an error, and the routing table is implicitly about keeping an agent inside the cheapest product that can do the job.
Install as one Claude Code plugin, or with the skills CLI
There are two supported installation paths and they differ in what you get.
Inside Claude Code, the repository is exposed as a plugin marketplace, and the commands are slash commands rather than shell commands. You add the marketplace, then install the plugin by its marketplace-qualified name:
/plugin marketplace add oxylabs/agent-skills
/plugin install oxylabs@oxylabs-agent-skills
That installs all five skills as a single plugin rather than one at a time, and updating later is a third slash command against the marketplace name. A plugin manifest directory at the repository root is what makes this work.
For every other agent, the generic path is a single command that takes a git URL:
npx skills add https://github.com/oxylabs/agent-skills.gitSo a team on Claude Code gets one bundled unit, and a team on anything else gets the same five directories through a generic installer. Nothing in the repository is code, so the platform does not matter much beyond whether your agent supports the skills format at all.
One detail worth noting for anyone browsing the repository: the promotional banner image is committed with spaces in its filename, which is unusual enough to be visible in any file listing.
The readme and the example environment file name variables differently
This is the practical trap in the repository, and it is worth resolving before you configure anything.
The readme publishes a table of environment variables keyed by product: a residential and mobile pair, a datacenter and ISP pair, a pair for the unblocker, a pair for the scraper API and video data, a pair for the agent browser, and a high-bandwidth endpoint for video downloads.
The example environment file in the repository root does not match it. It ships a residential pair named differently from the one in the readme, plus a separate mobile pair, which suggests the residential variable was renamed to something shorter and a mobile variable was added without the readme being updated. It also ships a dedicated unblocker pair that the readme never mentions, and it labels the browser pair as a compatibility fallback rather than as the primary name. Two datacenter-specific variables appear only in the example file, and a second endpoint variable appears only there as well.
The pattern is clear: the environment file is ahead of the documentation, and the readme table is a snapshot of an older naming scheme. Whether a given name works depends on which service version your account is on, which is exactly the kind of ambiguity that produces an authentication failure with no useful error.
So read the example file, copy from it, and treat the readme table as a guide to which variable belongs to which product rather than as the source of truth for spelling.
The proxy skill is the widest and the least structured
The first skill covers the largest product line in the catalogue, and it is the one with the least shape.
It covers residential, mobile, datacenter, dedicated datacenter, ISP and dedicated ISP proxies, and it is the only entry that mentions geo-targeting, IP rotation and session persistence as first-class capabilities. Sticky sessions in particular are the reason an agent cannot treat a proxy as a simple string prefix: a session that persists is a different object with a different lifetime, and getting it wrong means either losing the reputation you built or reusing one you should not.
The routing table places this skill first for anything involving your own HTTP client, proxy authentication, rotation, sticky sessions or raw geo-targeted traffic. That is the right default, because it is the lowest layer: the other products are built on it, and if you need control over egress, you should not be routing through a higher-level product that hides it.
The documentation link at the bottom of the readme points at the vendor's agent skills page under the residential proxies product, which is a hint that the proxy skill is treated as the primary entry point and the others as specialisations.
The unblocker is the skill that advertises CAPTCHA handling
One entry deserves to be read carefully rather than skimmed.
The web unblocker skill is described as an AI-powered proxy that handles fingerprinting, JavaScript rendering and CAPTCHAs, and that improves access reliability automatically. The routing table places it for fetching protected pages without browser interactions, which is the honest distinction between it and the browser skill: no clicks, no forms, just a response.
Every one of those capabilities exists to defeat a site's defences against automated clients. That does not make the skill illegitimate, because these are commercial products sold openly and used for legitimate purposes including price monitoring, market research and testing your own sites. It does mean the responsibility sits with the user: what you may point a scraping tool at is determined by the target and its terms, not by the fact that a vendor sells a tool that can reach it.
Two practical notes follow from the description. Because it handles fingerprinting and rendering on the server side, it is the right choice when you need a response rather than a browser, and the wrong choice when you need session state across requests. And since it is billed per request, an agent that retries on failure will spend money quietly, which is why the routing table's instruction to confirm status before scaling matters more here than anywhere else in the catalogue.
Agent Browser and Video Data split two unrelated jobs
The last two skills are unrelated to each other, which is worth noting because they share credentials.
Agent Browser gives you remote browsers driven over the Chrome DevTools Protocol with Playwright or Puppeteer, with request handling built in and residential proxies behind them. Its routing entry is the one with clicks, forms, screenshots, browser state and full automation. That is a genuinely different cost profile from the unblocker: you are renting compute and a browser session rather than buying a response.
Video Data covers video metadata, subtitles, search and channel data, plus high-bandwidth proxy downloads of video and audio. Its routing entry is specific to that. The interesting engineering detail is the separate high-bandwidth endpoint variable, which exists because ordinary proxy bandwidth is not appropriate for media transfer.
Both skills list the scraper API credentials, so if you are using both you set one pair and get two products.
That sharing is the one thing in the credential scheme that reduces friction, and it also means an error in one place looks like a failure of the other. If video metadata fails while scraping works, the endpoint variable is the first thing to check.
A repository of markdown, with no releases at all
The state of the repository is worth one short paragraph, because it shapes how you should treat it.
There are no GitHub releases, and the last push to the default branch was 2026-09-30, so the skills are only available from the branch. There is no tag to pin and no changelog to diff, which means if the vendor changes a variable name, you find out from a failing request rather than from a release note.
The repository itself is minimal by design: a plugin manifest directory, the example environment file, a licence, the readme with its Chinese and other-language counterparts linked elsewhere, the five skill directories, and a banner image. The repository metadata does not even report a primary language, which is accurate, since the content is instruction text rather than code.
The licence is MIT, which is worth noting because these are official vendor skills: the instructions are permissively licensed while the services they call are commercial and separately billed.
That combination, an open instruction set in front of a paid API, is the shape of most vendor-published agent integrations. It works, and it means the failure modes are documentation failures rather than software failures.
Editorial conclusion
These skills are worth reading if you already pay for one of the Oxylabs products and want an agent to drive it correctly, since the routing table and the small-request-first instruction are the useful parts. Skip them if you are looking for a free scraping tool, because every one of them needs a vendor account. Before you configure anything, copy the variable names from the example environment file rather than the readme table, and make sure you are authorised to send traffic to the targets you point these skills at.
Frequently asked questions
how to install agent skills in claude code
Add the repository as a plugin marketplace with /plugin marketplace add oxylabs/agent-skills, then install it with /plugin install oxylabs@oxylabs-agent-skills, which brings in all five skills as one plugin. Update later with /plugin marketplace update oxylabs-agent-skills.
What skills does the Oxylabs agent-skills repository contain?
Five: Proxies for raw proxy traffic with geo-targeting, rotation and sticky sessions; Web Unblocker for protected pages; Web Scraper API for structured JSON across more than 40 targets; Agent Browser for remote browsers over the DevTools Protocol; and Video Data for metadata, subtitles, search and downloads.
Do the Oxylabs agent skills need an account?
Yes. Every skill authenticates through environment variables read from a .env file, and each of the five products needs its own credentials, with the unblocker pair and a high-bandwidth endpoint appearing only in the example environment file.
Which environment variables do the Oxylabs skills use?
Residential and mobile proxy credentials, datacenter and ISP credentials, unblocker credentials, scraper API credentials shared by the scraper and video skills, agent browser credentials, and a high-bandwidth endpoint for video downloads. The readme table and the example environment file use different names for some of these.
Is it legal to use the Oxylabs agent skills?
The skills are a client for a commercial service and are MIT licensed, but what you may scrape is decided by each target and its terms. Use them against sites you own or have permission to test, and keep requests small and bounded as the readme advises.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/oxylabs-agent-skills)Star history chart for your README
[](https://hysenlabs.com/projects/oxylabs-agent-skills)Was this useful?