Scraping Amazon product data: a 503, a user-agent, and a repository with no code in it
The process of extracting product data from Amazon using Python, including titles, ratings, prices, images, and descriptions.
At a glance
- What is it?
- A Python walkthrough for pulling product name, rating, price, images and description out of Amazon pages, published by the vendor of a commercial scraping API. The repository holds a README and an images folder and nothing else, so every script lives in a fence you copy by hand, and the text stops part way through explaining the first selector.
- Who is it for?
- Read this as a document about one vendor's tutorial rather than as a scraper you can adopt. It teaches the shape of the problem honestly, the block message, the 503 status, the two page types and the selectors, and it hands you a working requests plus BeautifulSoup recipe for the parts of a product page that are plain HTML.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
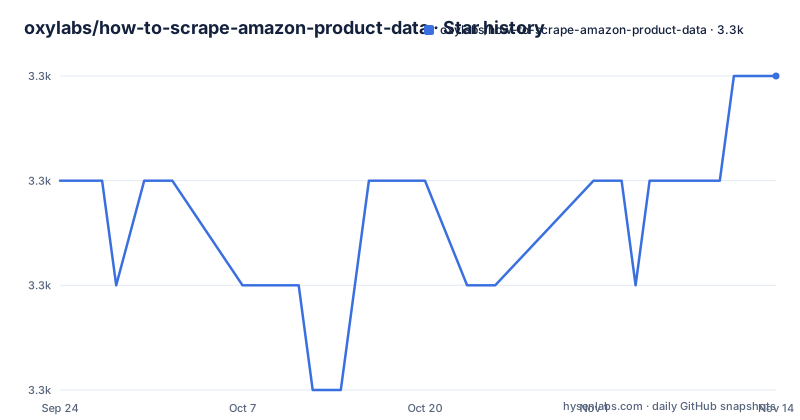
- oxylabs/how-to-scrape-amazon-product-data3,259 ★ · +1
| Repository | 2026-09-24 | 2026-11-14 |
|---|---|---|
| oxylabs/how-to-scrape-amazon-product-data | 3.3k | 3.3k |
1 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository is one README and an images folder
The top-level entries are README.md and images/. There is no source directory, no package manifest, no requirements file, no tests and no release history. The declared primary language and license are both unrecorded.
So there is nothing to clone and run. Every script in the guide exists as a fenced block that you retype into a file you create yourself, starting with amazon.py. The data points the walkthrough targets are five: product name, product rating, product price, product images and product description.
The page under discussion is a specific product, a Bose QuietComfort 45 headphone listing, and the same URL is reused through the setup section, which means the selectors discussed later are the ones that fit that page. The last push on the default branch is dated 2026-06-08.
A bare request returns 503 and a message naming an address for automated access
The first script fetches the product URL with requests and prints response.text:
import requests
url = 'https://www.amazon.com/Bose-QuietComfort-45-Bluetooth-Canceling-Headphones/dp/B098FKXT8L'

response = requests.get(url)

print(response.text)
What comes back is not the page. It is this:
To discuss automated access to Amazon data, please contact [email protected].Printing response.status_code gives 503 rather than 200, and the guide notes that such responses begin with 500 and sometimes with 400. The stated reason is that the request was not using a browser.
That sentence is the site's own position, and it is worth reading twice: the block is not an accident of markup, and the address it prints is where the site says questions about automated access belong.
The documented workaround escalates from one header to five
The response to a 503 in this guide is to send headers the way a browser does. Sometimes one is enough, and the guide names the user-agent first, with accept-language as the second thing to reach for. To find your own string you press F12, open the Network tab, reload, pick the first request and read its Request Headers.
The first dictionary shown holds two entries:
custom_headers = {
    'user-agent': 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/108.0.0.0 Safari/537.36',
    'accept-language': 'en-GB,en;q=0.9',
}
and it is passed straight to the get method as headers=custom_headers.
If those two still return 503, the guide escalates to a five-entry dictionary that adds Accept-Encoding, Accept and a Referer pointing at google.com, and it then suggests rotating User-Agent strings between attempts. Rendering is the alternative it names for pages that need it, with Playwright or Selenium.
Both hardcoded user-agent strings name browser versions from years ago
Neither string is a placeholder. The first names Chrome/108.0.0.0 on macOS 10_15_7. The fallback names Version/16.1 Safari/605.1.15 on macOS 13_1, and pairs it with an Accept-Language of da, en-gb, en.
Those are pinned versions, not current ones, which matters because the guide's own instruction for finding a user-agent is to copy the one your own browser sends. Read that way, the two dictionaries are examples to be replaced rather than configuration to be kept, and the Accept-Language value in the fallback is set to Danish first, which is a choice with no stated reason behind it.
The guide also draws a line it does not fully justify, saying you will not need Javascript rendering if you send as many headers as possible, and that rendering requires tools like Playwright or Selenium.
The title is an id, the price is two spans, and the description is on another page
Two page types are separated before any selector is discussed. The category page is the search results listing, and it shows title, image, rating, price and the product URLs. Anything more detailed, the description among it, comes only from the product details page.
The picking method is the browser's own Inspect command. The title is a span whose id attribute is productTitle. The price is split: the dollar component sits in a span with the class a-price-whole, and the cents sit in another with the class a-price-fraction, so a price is two elements that have to be joined. Rating, image and description are located the same way.
The parsing code that consumes this uses CSS selectors and one parser:
from bs4 import BeautifulSoup

response = requests.get(url, headers=custom_headers)
soup = BeautifulSoup(response.text, 'lxml')
None of these names is presented as an interface Amazon commits to. They are the class names in the markup on the day the guide was written.
The contents promises eight steps and the text stops inside the first one
The contents lists setting up with a virtual environment and package installation, then eight numbered steps: sending a GET request with custom headers, then locating and scraping product name, rating, price, image and description, then handling product listing, then exporting the scraped data to a CSV file. A final section, described as an easier solution to extract Amazon data, adds three more: scraping products from search results, extracting product details, and scraping products by ASIN.
The visible text reaches the first numbered step in full, then opens the second and stops inside it, at a sentence about the product name or title being located in a span element. So the request step, the parsing setup and the first selector are all there, and the seven steps after that are named in the contents without their text.
The same gap applies to the three subsections of the easier solution, which are the parts that would show how the vendor's own API is called.
The banner link carries affiliate tracking parameters
The first line of the file is a link to the vendor's Amazon page for its Scraper API, and the URL is not clean. It carries utm_source=877, utm_medium=affiliate, groupid=877, a utm_content value naming this repository, and a transaction_id.
Above the title sit two more links, a Discord invite and the vendor's YouTube channel. Below the title, the guide points to an extended version of itself on the vendor's blog.
The arrangement is consistent throughout: the walkthrough teaches the manual method with requests, BeautifulSoup, lxml and pandas, and the last section of the contents offers the easier route, whose three subsections are search results, product details and scraping by ASIN. The tutorial is the free part of a product whose homepage is the paid endpoint.
Editorial conclusion
Read this as a document about one vendor's tutorial rather than as a scraper you can adopt. It teaches the shape of the problem honestly, the block message, the 503 status, the two page types and the selectors, and it hands you a working requests plus BeautifulSoup recipe for the parts of a product page that are plain HTML. What it cannot give you is a maintained tool: there are no code files in the repository, no license, no tests, and the walkthrough ends mid-sentence on the first selector. Before running any of it against a real site, note that Amazon's own blocked response directs automated access questions to [email protected], that the header strings in the guide name browser versions several years old, and that Amazon's class names are not an interface the site promises to keep. For volume, the guide's own answer is to buy the API it is selling.
Frequently asked questions
How can I scrape product data from Amazon?
The walkthrough creates a virtual environment, installs requests beautifulsoup4 lxml pandas, sends a GET request for a product URL with browser-like headers, parses the response with BeautifulSoup using the lxml parser, and reads the fields with CSS selectors: an id of productTitle for the name and the classes a-price-whole and a-price-fraction for the price.
Is it legal to scrape data from Amazon?
This repository does not address legality. What it shows is Amazon's own response to a blocked request, a 503 carrying the text To discuss automated access to Amazon data, please contact [email protected].
Is web scraping legal or illegal?
That question is outside what this guide covers. It is a how-to for reading product name, rating, price, images and description from two kinds of Amazon page, and it says nothing about the legal status of scraping in general.
Is AI scraping illegal?
Nothing in this repository addresses AI scraping or its legality. The guide is a Python walkthrough for product pages, using requests, BeautifulSoup, lxml and pandas, with no mention of model training or of automated access terms.
What does the guide do when Amazon returns 503?
It sends browser-like headers. It starts with user-agent and accept-language, shows a second dictionary adding Accept-Encoding, Accept and a Referer if those are not enough, suggests rotating User-Agent strings between attempts, and names Playwright or Selenium when rendering is needed.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/oxylabs-how-to-scrape-amazon-product-data)Star history chart for your README
[](https://hysenlabs.com/projects/oxylabs-how-to-scrape-amazon-product-data)Was this useful?