pifs stores no data, only the offsets of your bytes in pi
πfs - the data-free filesystem!
At a glance
- What is it?
- A GPL licensed C filesystem that mounts and, instead of writing file contents to disk, looks each byte up in the hexadecimal digits of a mathematical constant, keeping a metadata directory of offsets. The readme is written as a series of objections answered in turn, and it answers the performance objection by pointing at Moore's law.
- Who is it for?
- pifs is a novelty project rather than something to deploy, and it says so. It is interesting to read as a thought experiment about what a filesystem would look like if storage were free, and the metadata design is the one idea with a practical edge.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
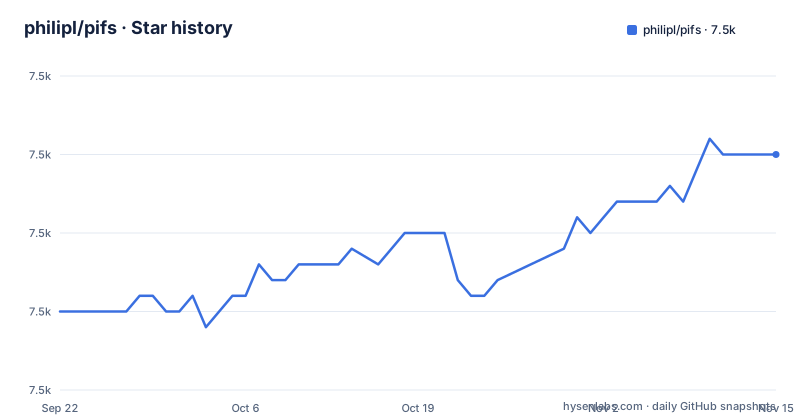
Star history
- philipl/pifs7,540 ★ · +10
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| philipl/pifs | 7.5k | 7.5k |
10 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Each byte is looked up separately, deliberately
The design decision that makes the whole thing work is a granularity choice, and the readme is explicit that it is a performance decision.
Finding a long run of digits in a constant takes a while, so files are broken into smaller chunks that can be found more readily. And in this implementation, to maximise performance, every individual byte of a file is considered separately and looked up on its own.
That is the opposite of how a real block layer works, and it is what makes the storage claim work at all: a byte has a fixed length, so a one-byte search is bounded, and the price is one search per byte.
Which is also why the project is a filesystem rather than a compression tool. Nothing is compressed, because nothing is stored. The readme answers the compression objection directly, pointing out that full compression was said to be impossible and then presenting this as the answer.
Metadata is the only thing stored, and it is not optional
The readme handles the obvious objection in its own heading, and the answer is that the locations are metadata, which by its own argument is fine because metadata keeps becoming more important.
So the filesystem stores two things: the name of a file, and where its bytes live inside the constant. The mount command makes this visible, taking an option that names a metadata directory and a mountpoint, and the readme explains that the directory holds the filenames and the locations.
Then the follow-up question, which is the one that matters: what happens if the locations are lost? The answer is that the files are still there in the constant, because they were never moved out of it.
That is the joke and also the honest limitation. Losing the metadata loses the files, in exactly the same way that losing a database loses a database, and the readme's framing does not change that.
Five minutes for four hundred lines, acknowledged
There is a heading that asks why the thing is slow, and the specific number in it is worth quoting.
It took five minutes to store a four hundred line text file.
And the answer, in full: this is just an initial prototype, and do not worry, there is always Moore's law.
So the performance claim is a joke with a real number in it. The number is the honest measurement, and the answer is the refusal to treat it as a blocker.
What that combination tells you about the project is useful: the author knew the throughput was unacceptable, wrote down the measurement anyway, and pointed at hardware rather than at an optimisation. Which is consistent with everything else in the readme, including the closing list of things that could make it faster.
The normality conjecture carries the whole argument
The argument rests on an unproved property of a constant, and the readme is careful to say so.
It is conjectured that the digits are normal, meaning they are distributed evenly, which implies the digits form a disjunctive sequence, meaning all possible finite sequences of digits appear somewhere within them. The readme then makes the step that makes the filesystem work: considering the constant in base sixteen, it is trivial to see that if the conjecture holds, then all possible finite files exist within it.
Two things are being noted at once. The conjecture is unproved, so the guarantee is conditional. And the base sixteen step is the actual trick, because a file is a byte sequence, and a byte is two hexadecimal digits.
The readme also dates the observation, noting that the first record of it goes back to 2001, with a link. This is a two-decade-old joke, and the repository is a good example of one.
The successor is announced in the first line
The readme opens by pointing somewhere else.
The very first line directs the reader to a different repository for the latest in data-free filesystems, separated by a horizontal rule from everything that follows.
So this repository is the previous version, superseded by a separate project with a different name, and the author says so before anything else.
That single decision tells you most of what you need to know about the state of the work. It is not abandoned, because the commits are recent and the code is still in the tree, and it is not maintained as the current line either.
If you are evaluating the idea rather than the code, the newer repository is where the evaluation belongs.
The future list ends with Hadoop
The readme closes with a short list of things that could be done next, and it is worth reading as a set because the items are not the same kind of thing.
Two are about lookup: variable run length search and lookup, and parallelisable lookup. One is about compression: arithmetic coding, which is what you would reach for if you were storing data rather than addressing it.
Two are about deployment. One is a cloud-based lookup service, and the last is a version for a specific distributed data system.
So the trajectory the author imagines is a lookup service, parallelised, reachable over a network, integrated with a cluster filesystem. Which is an odd thing to want from a joke, and probably the most honest section in the readme, because it says what would actually be required to make the premise usable.
Autotools, no tests, and a release history that does not exist
The repository layout is a snapshot of a particular decade of Unix tooling.
There is an autotools skeleton: a bootstrap script, a configuration source, a makefile template, and the usual accompanying files for installation, changes, news and authors. The source is a single directory.
./autogen.sh
./configure
make
make install
There is no test directory, no continuous integration configuration, and no releases. The build instructions are four commands after installing an autotools package, a build tool, and the FUSE development headers.
So the project is installable in the conventional way for a FUSE filesystem, which is a real and rather pleasant thing about it, and it carries none of the machinery a maintained project would have. Both facts are consistent with the readme's own framing of the work as a prototype.
Editorial conclusion
pifs is a novelty project rather than something to deploy, and it says so. It is interesting to read as a thought experiment about what a filesystem would look like if storage were free, and the metadata design is the one idea with a practical edge. Read the successor repository instead if you want the current version of the idea, and do not treat the performance section as a benchmark: the only figure given is the author's own five minutes for a four hundred line file, offered as a joke.
Frequently asked questions
What is pifs?
It is a FUSE filesystem written in C that does not store file contents. Instead of writing your data to disk it looks up each byte in the digits of a mathematical constant and keeps only the file names and the offsets, which it calls metadata, in a directory you supply at mount time.
How do I build and mount pifs?
Install an autotools package, the build tool, and the FUSE development headers, then run the bootstrap script, configure, make and make install. Mount it by passing a metadata directory and a mountpoint, for example with the mount command shown in the readme.
Why does pifs store metadata instead of files?
Because the readme's argument is that the constant already contains every file that could exist, so storing bytes is wasted space. What remains is the mapping from file name to offset, and the readme argues that is metadata, which it treats as cheaper and increasingly important.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/philipl-pifs)Star history chart for your README
[](https://hysenlabs.com/projects/philipl-pifs)Was this useful?