Effective HTML: six markdown files, four plugin manifests, and no releases
Agent skills for useful HTML artifacts, wireframes, interactive prototypes, plans, and diagrams.
At a glance
- What is it?
- plannotator/effective-html is a collection of six agent skill files for producing HTML artifacts, where the repository ships four separate plugin manifests for the same six markdown files, demonstrates installing three of them, publishes no releases at all, and names a documentation domain it shares with a different product's namespace.
- Who is it for?
- Read it before you install it, because that is what the project asks for and it happens to be the better order: six markdown files is a small enough body of guidance to judge on its own, and the argument about how complete an artefact should be is the part worth the read. Three things to decide before adopting it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 15 days ago.
- What is it written in?
- Mainly HTML, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
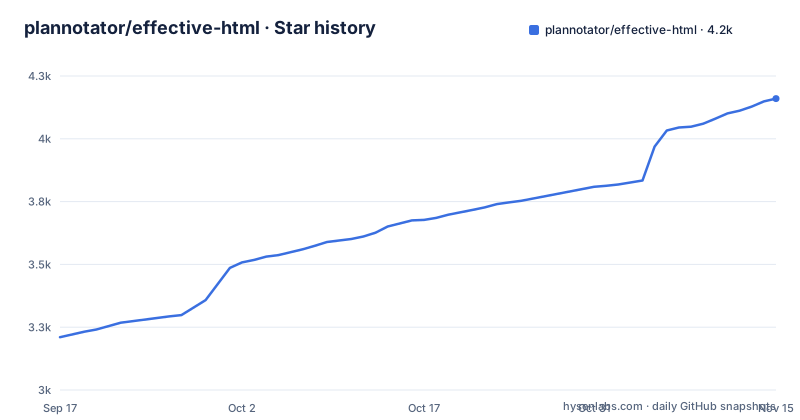
Star history
- plannotator/effective-html4,160 ★ · +950
| Repository | 2026-09-17 | 2026-11-15 |
|---|---|---|
| plannotator/effective-html | 3.2k | 4.2k |
950 Stars in the last 59 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The project is named after a domain it does not own, inside another organisation's namespace
Three domains appear in one README. The note that tells you how to use this repository points at effectivehtml.com for the guide. The practical guide link, sitting directly under the skill table, points at docs.plannotator.ai. The repository's own homepage field points at plannotator.ai, the parent project's site rather than this one's.
The repository is named effective-html and the guide it points to is on effectivehtml.com, so the name and the documentation site line up. The namespace does not: the repository lives under the plannotator organisation, which also publishes Plannotator itself, described in the README as the tool for rendering and annotating local HTML, and tot, described as the tool for creating a shareable link for an HTML file.
So this is a documentation site with its own name, hosted as a subpath of a different product's documentation, inside the namespace of a product with a third purpose. Both sibling tools get a block in the README: Plannotator gets one in the upper third, immediately after the demo link, and tot gets one at the very end.
Nothing here is hidden or dishonest. A reader who wants the guide goes to the domain named in the note, and a reader who wants to annotate an HTML file finds Plannotator where the README says it is. It is simply a repository whose name, whose documentation domain, and whose namespace all point at different things, which is the kind of arrangement that costs a new user one extra search.
The deliverable is six markdown files and the rest is distribution scaffolding
The skill table links six paths, and every one of them is a SKILL.md inside a directory named after the skill. That is the whole product: six markdown instruction files.
Around them the top level listing holds four manifest surfaces for the same six files. There is a .agents directory, a .claude-plugin directory, a .codex-plugin directory, and a skills.sh.json file. Then there are the things that are not the product at all: a site directory, an assets directory, a single examples directory, two SVG badges for the sibling tools, and a Chinese translation of the README.
The repository's primary language is recorded as HTML, which is not the language the skills are written in. It is a consequence of the site directory and the assets directory being the bulk of the repository's bytes.
That ratio is worth stating plainly for anyone deciding whether to vendor this. If you want the six instruction files, they are six markdown files and the rest of the repository is distribution machinery for four different agent ecosystems plus a marketing site. If you want the site, the skills are the small part.
There is also one example directory in the whole repository, and it is named release-readiness. Six skills covering wireframes, prototypes, plans and diagrams ship exactly one worked example, and its name does not obviously correspond to any of the six skill names.
Four manifest surfaces describe the same six files, and the per-skill examples name three of them
The install section has one command for the whole collection and then a flag for taking one skill:
npx skills add plannotator/effective-htmlThree skills are demonstrated with the per-skill flag: design-artifact, html-wireframe and html-prototype. The other three, html, html-plan and html-diagram, are not.
The omission that matters is html, because the README's own description of how the skills work says the broad html skill routes the work, that design-artifact supplies optional creative direction, and that specialist skills own fidelity and behaviour. It is the entry point. Its table row is the longest one in the table, covering broad HTML requests, mixed artifacts, reports, explainers, presentations, landing pages, tools, and routing to a specialist, and yet it is the one skill with no install example.
html-plan and html-diagram are easier to excuse, since the three demonstrated skills cover the two that need the most explanation, wireframes and prototypes. But the pattern across three install routes is the thing to notice: a skill you did not see in an example is a skill whose name you have to copy from a table rather than from a command line.
For a collection whose stated purpose is to be read and reused, that is a small but real friction. Three lines would fix it.
Claude Code installs with a slash command and Codex installs with a shell command
The same operation is presented two different ways, and the difference is not cosmetic.
For Claude Code it is a pair of slash commands typed into the session, fenced as plain text rather than as a shell block:
/plugin marketplace add plannotator/effective-html
/plugin install plannotator-effective-html@effective-html
For Codex it is a pair of commands you would run in a terminal:
codex plugin marketplace add plannotator/effective-html
codex plugin add plannotator-effective-html@effective-html
The fencing is right in both cases. A slash command is not shell input, and tagging it as a shell block would invite someone to paste it into a terminal. What the difference reveals is that the three install paths are not one abstraction with three front ends. Each ecosystem has its own identifier scheme: the npx path names the repository, the Claude Code path names a plugin as a hyphenated repository name at an at-sign and a short name, and the Codex path uses the same plugin name at an at-sign and the same short name.
Three routes, two identifier conventions, and no single line in the README that says which one to prefer or what happens if you have used more than one. A user who installs the collection through npx and then adds the Claude Code plugin has two copies of the same six markdown files in their agent configuration, and nothing in the document says whether the second one overrides the first.
Verified in a browser is asserted in one line with no mechanism named
One bullet states the standard the whole collection holds itself to: every artifact is responsive, accessible, self-contained, and verified in a browser.
Three of those four are properties you can check by looking. Responsive is a viewport. Self-contained means the file works on its own, which is checkable by opening it. Accessibility is checkable with a checker, though the README does not name one.
The fourth is different, because verification is a process rather than a property. Something has to open the artifact in a browser and look at it, and nothing in the README says what does that, when, or how the result is recorded. There is no test directory in the listing, no build step, no check command, and the language is written as a standing property of the artifacts rather than as a step the skills ask an agent to take.
The other five bullets are the ones that carry the actual design argument, and they are more interesting than the standard. Visual direction comes from the conversation, project, audience and subject. design-artifact provides a reusable design process without prescribing a reusable look. Wireframes stay intentionally unfinished so reviewers focus on structure. Prototypes implement one credible flow and its relevant states. Plans preserve source commitments. Diagrams choose a visual model and rendering method that fit the relationship being explained.
That last cluster is the actual contribution: a decision about how complete an artifact should be, per artefact type. It is more useful than the verification claim, and it is the part you would have to read carefully to adopt.
A bare attachment URL and two empty badge blocks sit inside the README
Partway down the page, between the note about the guide and the block about Plannotator, there is a line that is a bare URL. No markdown, no alt text, no angle brackets. It points at github.com/user-attachments with a UUID path and nothing after it.
That host is where GitHub stores attachments that have no repository of their own. Written as plain text it renders as a long unclickable-looking string in the middle of the prose, and the reader has no idea whether it is a video, a screenshot, or a broken link. Whichever it was meant to be, it needed markup that markdown or HTML would recognise.
The two badge blocks have the opposite problem: they are markup that renders as nothing. Each is a paragraph containing a single anchor tag with a URL and no text between the opening and closing tags. One wraps the Plannotator repository, the other wraps tot. Both render as empty lines, and in each case the sentence below it repeats the same link with visible text.
So there are three sibling-project references in the README and all three are malformed in some way: one bare URL, two anchors with no content. The tool names and destinations are still recoverable from the sentences underneath, so nothing is lost except the badges, which would normally be the compact version of exactly the same information.
It is worth noting because it is the pattern that shows up in every README in this family. An author who starts with shields.io badges and then strips image sources, for size or for a renderer that will not fetch them, is left with the anchor shells.
No releases exist, so nothing records which version of the skills you installed
The repository publishes no GitHub releases. There is no tag to install from and no version to record.
Every install path in the README resolves to a branch. npx skills add takes a repository reference. The Claude Code and Codex plugin commands add a marketplace named for the repository. There is no version argument anywhere in the six install commands.
That is the normal shape for a collection of prose instructions, and it carries less risk here than it would in a code dependency: a stale markdown file degrades an agent's behaviour rather than breaking a build. But it is not nothing.
What these files do is change how a model behaves. A skill that tells an agent how to build a wireframe, which states a prototype must implement, what a plan must preserve, is a behavioural contract with the agent. Six such files changing silently between one session and the next is a difference in output that has no version attached to it and nothing to diff against.
The repository does carry the tools to do better. There is a CHANGELOG-shaped artefact in the wider project family and the other tools in the namespace do tag releases; this one does not. Vendoring the six markdown files, or pinning the marketplace reference to a commit, would give you the record that the release system is currently not providing.
Two of the six skills break the naming convention the other four follow
Six skills, and six directories under skills. Four of them are prefixed with html-: html-wireframe, html-prototype, html-plan, html-diagram. The other two are not: html and design-artifact.
The html one is defensible, since html is the family name and prefixing the parent with its own name reads badly. design-artifact is the interesting case, because it is the only skill in the collection whose name does not contain the word html at all, and it is not one of the four fidelity or behaviour specialists either.
Its row in the table says it is for subject-specific creative direction for any HTML artifact without imposing a reusable house style. And the bullets say it provides a reusable design process without prescribing a reusable look. So it is the one skill that is deliberately about method rather than output type, which is consistent with it sitting outside the html- prefix. Whether that was intended or is a leftover is not something the document says.
The naming does have one practical consequence, which is the per-skill install flag. Choosing between the collection and a single skill means typing --skill followed by a directory name, and the four html-prefixed names are guessable from the table's left column while design-artifact is not. It is a small thing, and it is the kind of small thing a collection of six instructions is allowed.
Editorial conclusion
Read it before you install it, because that is what the project asks for and it happens to be the better order: six markdown files is a small enough body of guidance to judge on its own, and the argument about how complete an artefact should be is the part worth the read. Three things to decide before adopting it. There are no releases, so nothing records which version of the behavioural instructions you are running, which means pinning or vendoring the six files is worth doing. The install examples cover three of the six skills and skip html, which is the router the whole design depends on. And if you install through more than one of the three routes, you will have two copies of the same files with nothing in the document saying which wins.
Frequently asked questions
What does the effective-html skill collection contain?
Six optional skills, each a SKILL.md file under skills/. They are html for broad requests and routing to a specialist, design-artifact for creative direction, and four specialists: html-wireframe, html-prototype, html-plan and html-diagram.
How do I install the effective-html skills?
npx skills add plannotator/effective-html installs the collection, with --list to see the skills and --skill to take one. There is also a Claude Code plugin installed with the /plugin marketplace add and /plugin install slash commands, and a Codex plugin installed with codex plugin marketplace add followed by codex plugin add.
Do I have to install anything to use effective-html?
No. The note under the introduction says you can use the repository without installing anything and to treat it as a reference first and an installable skill collection second. The install section repeats the same framing.
What standard does effective-html hold its artifacts to?
One line says every artifact is responsive, accessible, self-contained and verified in a browser. The design bullets add that wireframes stay intentionally unfinished so reviewers focus on structure, prototypes implement one credible flow and its relevant states, plans preserve source commitments, and diagrams pick a visual model that fits the relationship being explained.
Which other plannotator tools does effective-html point at?
Plannotator, for rendering and annotating local HTML, and tot, for creating a shareable link for an HTML file. Each gets its own block in the README, Plannotator near the top and tot at the end, and the guide link goes to effectivehtml.com while the practical guide goes to docs.plannotator.ai.
What is effective-html based on?
The README says the project was inspired by Thariq Shihipar's The unreasonable effectiveness of HTML. Its own framing is a set of focused agent skills for creating self-contained HTML artifacts, from low-fidelity wireframes through to working interactive prototypes.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/plannotator-effective-html)Star history chart for your README
[](https://hysenlabs.com/projects/plannotator-effective-html)Was this useful?