Honcho: peer memory that reasons in the background
Memory library for building stateful agents
At a glance
- What is it?
- Honcho is an AGPL licensed memory layer for stateful agents, built as a FastAPI server with Python and TypeScript SDKs, peer representations, and background reasoning. Read it for the data model and the packaging; its frontier claim points to linked evals for detail.
- Who is it for?
- Honcho fits teams that want memory shaped around peers, sessions and background reasoning rather than around vector similarity, and that can run Postgres with pgvector plus Redis, or use api.honcho.dev. Skip it if your agent needs read your write semantics, or if AGPL-3.0 rules out your deployment.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
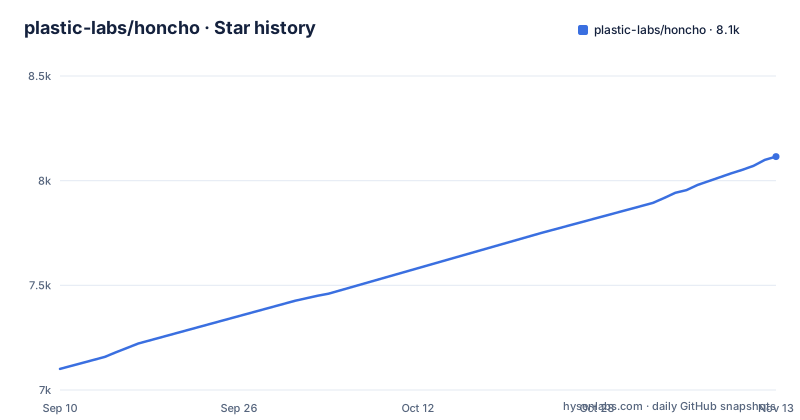
- plastic-labs/honcho8,115 ★ · +1,014
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| plastic-labs/honcho | 7.1k | 8.1k |
1,014 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Store returns before reason has finished
Honcho describes its own cycle in four steps. You store conversations, events, documents or tool traces as messages on a session. The service then reasons, processing a queue in the background and updating peer representations. You query for context, search results, peer representations or a natural language answer, then inject that result into any LLM call or agent framework.
The practical asymmetry is that the store step returns before the understanding step completes, so a successful write says nothing about whether the system has absorbed what you sent. The note in the documentation is blunt about the consequence: newly added messages may take a moment to show up in chat and representation responses. If you write a fact and immediately ask a question about it, the answer can miss it, and retrying the write is the wrong fix. The documented answer is to read from the representation endpoint when latency matters.
Workspaces hold peers, peers hold sessions, sessions hold messages
The model is four nouns that nest: workspaces hold peers, peers take part in sessions, messages live on sessions, and Honcho maintains a representation per peer that you query through the Chat Endpoint or directly. A peer is not a user row. Users, agents, groups, projects and ideas are all peers in the capability table, because the point is that each of them changes over time rather than sitting still between requests.
Multi peer perspective is listed as modelling what one peer knows about another when configured, which is what separates this from storing a transcript and grepping it. Queries come in three shapes: session.add_messages(...) writes history, peer.chat(...) asks about one peer, and honcho.chat(...) or honcho.chat_stream(...) asks across a workspace. The trade is that retrieval reads like a conversation rather than a ranked list.
Two client packages, three targets, one base_url switch
The Python client comes from PyPI as honcho-ai. The TypeScript client is @honcho-ai/sdk.
pip install honcho-ai
# or: uv add honcho-ai
# or: poetry add honcho-ainpm install @honcho-ai/sdk
# or: bun add @honcho-ai/sdkThe same code then points at one of three targets: the managed service at api.honcho.dev is the default, a local stack starts with `honcho start --setup` from the honcho-cli package, and self hosting means running the FastAPI server yourself. Signup at app.honcho.dev prompts you to join an organization, which gets its own dedicated Honcho instance.
import os
from honcho import Honcho

# Managed service uses api.honcho.dev by default. For self-hosted, pass
# base_url="http://localhost:8000" or set HONCHO_URL.
honcho = Honcho(
    workspace_id="my-app-testing",
    api_key=os.environ["HONCHO_API_KEY"],
)

# 1. Store: peers and messages on a session
alice = honcho.peer("alice")
tutor = honcho.peer("tutor")
session = honcho.session("session-1")
So the only thing that changes between a laptop and production is the base_url value and where HONCHO_API_KEY comes from.
Python 3.13, Postgres with pgvector, and a Redis that is not optional
The floor is stated twice: requires-python = ">=3.13" in pyproject.toml and a python:3.13-slim-bookworm base image. Anything older will not install.
The dependency list is where the shape of a deployment shows up. psycopg[binary]>=3.1.19 is the Postgres driver and pgvector>=0.2.5 is the vector extension binding for that database, with sqlalchemy>=2.0.30 above them and alembic>=1.16.0 alongside an alembic.ini and a migrations/ directory for schema changes. redis>=8.0.1,<9.0.0 plus cashews[redis]==7.5.0 covers caching and queues. Around those sit pyjwt>=2.10.0 for tokens, tenacity>=9.1.2 for retries, cloudevents, prometheus_client, sentry-sdk wired to anthropic and sqlalchemy, langfuse, tiktoken>=0.9.0 for token counting and nanoid for identifiers.
A self hosted install is therefore not a lone Python process. The repository ships docker-compose.yml.example next to config.toml.example and .env.template for wiring the services, and the README has Self-hosting and Configuration sections to read before the first run.
Vector backends are install time extras, and surprisal ships switched off
Four extras decide what Honcho can search. The surprisal extra pulls in scikit-learn>=1.6.0 and drives surprisal based dream prioritisation behind DREAM.SURPRISAL.ENABLED, which is off by default. The comment in pyproject.toml gives the reason: scikit-learn drags in scipy, about 199MB installed on Linux, so it stays out of the base dependencies.
The lancedb extra adds lancedb>=0.25.3 and pyarrow>=19.0.0, and its environment marker, sys_platform != "darwin" or platform_machine != "x86_64", leaves Intel Macs without that backend. qdrant adds qdrant-client>=1.18.0 and chromadb adds chromadb>=1.5.2. turbopuffer>=1.8.1, unlike the rest, sits in the base dependency list.
Two consequences. Any behaviour that depends on surprisal maths does not exist until you install an extra and set an environment variable, so a feature you read about may be dormant in your deployment. And the backend libraries are install-time extras, so switching to one that is not installed means rebuilding the environment.
The Docker build pins uv 0.9.24 and rejects a bad build arg
The Dockerfile is written for an image that gets remounted, and the comments spell out the choices. The builder copies uv from ghcr.io/astral-sh/uv:0.13.5, sets UV_COMPILE_BYTECODE=1, and switches to UV_LINK_MODE=copy because the cache is a mounted volume where linking misbehaves.
There are two build options, INSTALL_LANCEDB and INSTALL_SURPRISAL, and both are validated rather than guessed.
# Optionall include lancedb with:
#   docker build --build-arg INSTALL_LANCEDB=true .
True selects uv sync --frozen --no-install-project --no-group dev --extra lancedb, false selects the same sync without the extra, and any other value prints INSTALL_LANCEDB must be 'true' or 'false' to stderr and exits with code 2. So a typo fails the build instead of quietly producing an image without the vector store. In the runtime stage a system user called app is created before the virtualenv is copied, because a recursive chown in a later layer would copy the whole virtualenv and nearly double the image size, and /app/lancedb_data is created up front so a named volume mounted there inherits app ownership rather than root.
One repository holding the server, the CLI, the SDKs and the plugins
This repository hosts the core service logic, implemented as a FastAPI server, the Python and TypeScript client SDKs under sdks/, and the honcho-cli package. Alongside them sit mcp/ for Model Context Protocol support, harness-plugin-core/ and hermes-plugin-honcho/ for agent integrations, skills/, sandbox/, .claude/ and .agents/ for tooling, typings/, tests/, and examples/ with crewai, gmail, granola, langgraph, n8n and zo directories. fly.toml, database/ and migrations/ cover deployment and schema.
pyproject.toml reads version = 3.5.0, matching the v3.5.0 release from 2026-10-30, and v3.4.1 came out on 2026-10-27. The last commits landed on 2026-11-02 and the repository is not archived, so this is active work rather than a frozen sample.
The trade is navigation. A failure in an agent example under examples/ and a failure inside the server live in different directories.
The frontier claim ships without a single number
Two checks are worth doing before you build on this. First the licensing. The repository is AGPL-3.0, so read the terms yourself before embedding the server in a product you distribute.
Second, the evidence. The README states that Honcho has defined the Pareto Frontier of Agent Memory, and it links a video, an evals page and a benchmarking blog post for detail. The README also has a Benchmarks & Evals section; read it and the linked evals page before relying on the claim.
Add the asynchronous background reasoning on top of that, and the picture for an integrator is a service with an active release cadence and a real data model, whose performance claim is worth checking against the linked evals.
Editorial conclusion
Honcho fits teams that want memory shaped around peers, sessions and background reasoning rather than around vector similarity, and that can run Postgres with pgvector plus Redis, or use api.honcho.dev. Skip it if your agent needs read your write semantics, or if AGPL-3.0 rules out your deployment. Before committing, fetch the linked evals page yourself, because the README's frontier claim points there for detail.
Frequently asked questions
what is honcho ai
Honcho is a memory library for building stateful agents. It stores messages and events, reasons about them in the background, and serves peer representations, session context, search results or natural language answers to any model or framework.
how to install honcho
For Python, use pip install honcho-ai, or uv add honcho-ai, or poetry add honcho-ai. For TypeScript, use npm install @honcho-ai/sdk, or bun add @honcho-ai/sdk.
how to install honcho locally
Install the CLI, which is published as honcho-cli on PyPI, then run honcho start --setup. Point the SDK at http://localhost:8000 by passing base_url or by setting HONCHO_URL.
how to use honcho with hermes
Hermes is listed among the coding agents that can use Honcho as persistent memory through the integrations path, alongside Claude Code, OpenCode and OpenClaw, since Honcho speaks MCP. The repository also ships a hermes-plugin-honcho/ directory at the top level.
how to setup honcho
For a local stack, install the CLI and run honcho start --setup. For an existing deployment, the CLI offers honcho workspace inspect and honcho doctor. Self hosting from source is done with Docker Compose or local development.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/plastic-labs-honcho)Star history chart for your README
[](https://hysenlabs.com/projects/plastic-labs-honcho)Was this useful?