pulldown-cmark: one flag drops the binary and std at the same time
An efficient, reliable parser for CommonMark, a standard dialect of Markdown
At a glance
- What is it?
- pulldown-cmark is a Rust pull parser for CommonMark that also ships a small rendering command. Its build switches are entangled, the HTML renderer insists on a buffered target, and consecutive text events are normal enough that a helper type exists for them. The crate is still published as 0.13.4.
- Who is it for?
- pulldown-cmark is a good fit when you want to walk a Markdown document as events, need byte offsets back for highlighting or reporting, and do not want a document tree in memory, because the parser implements Iterator directly and into_offset_iter hands you a range with every event.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 22, 2026, and from our analysis. They are not legal advice.
Star history
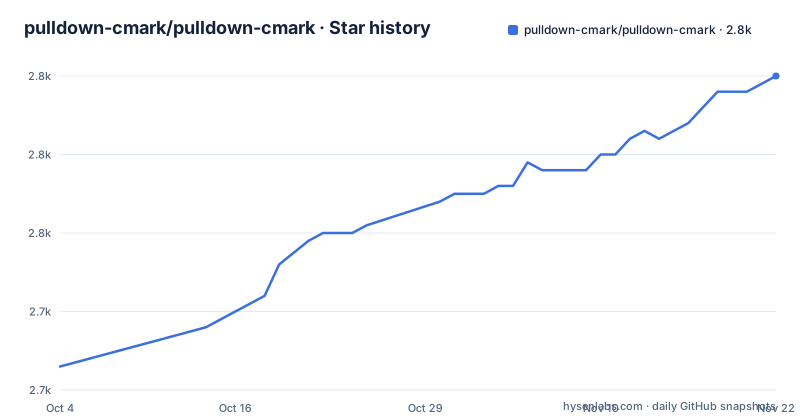
- pulldown-cmark/pulldown-cmark2,770 ★ · +37
| Repository | 2026-10-04 | 2026-11-22 |
|---|---|---|
| pulldown-cmark/pulldown-cmark | 2.7k | 2.8k |
37 Stars in the last 49 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The example that does not compile, and why it is written that way
Start with the five claims the README makes about the design, because they are the reason to pick this crate and each one carries a caveat. Fast is qualified as a bare minimum of allocation and copying. Safe is qualified as pure Rust with no unsafe blocks, except in the opt-in SIMD feature. Versatile means source maps are supported. Correct is stated as a goal of 100% compliance with the CommonMark spec, which is a target rather than a certificate. The smallest program is four lines and asserts on the output:
// Create parser with example Markdown text.
let markdown_input = "hello world";
let parser = pulldown_cmark::Parser::new(markdown_input);

// Write to a new String buffer.
let mut html_output = String::new();
pulldown_cmark::html::push_html(&mut html_output, parser);
assert_eq!(&html_output, "<p>hello world</p>\n");
Note that the output is asserted to a String rather than printed, and the reason why is the subject of the next section. The examples directory of the repository is pointed at as holding basic but functional usage examples, and the internal scanning code is described as low level, scanning byte patterns, while the interface is idiomatic Rust.
The renderer does many small writes, so the target has to be buffered
The advice is explicit and it is about where the bytes go. When using pulldown-cmark's own HTML renderer, write to a buffered target like a Vec<u8> or a String. Because it performs many very small writes, writing directly to stdout, files or sockets is detrimental to performance, and such writers can be wrapped in a BufWriter. That is why the example above builds a String and asserts against it instead of printing. The reason is structural rather than incidental. Event::Text, which represents text, is a small copy-on-write string, and the vast majority of text fragments are slices of the source document, so copy-on-write gives a representation that requires no allocation or copying while still allowing allocated strings when they are needed. The result is that most text is copied exactly once, from the source document to the HTML buffer. Copy once is cheap. Thousands of tiny writes to an unbuffered handle are what the guidance is steering you away from, and it applies to any renderer you write on top of the events as well.
Consecutive text events are normal, so TextMergeStream exists
The parser evaluates the source in a manner that can produce consecutive text events, and the README says so plainly before introducing a helper type whose only job is to make iteration comfortable. The helper is constructed from a parser:
use pulldown_cmark::{Event, Parser, Options};

let markdown_input = "Hello world, this is a ~~complicated~~ *very simple* example.";

let iterator = TextMergeStream::new(Parser::new(markdown_input));

for event in iterator {
    match event {
        Event::Text(text) => println!("{}", text),
        _ => {}
    }
}
Worth noticing is that the import line brings in Event, Parser and Options while the code below constructs TextMergeStream, which is not in that list, so the snippet as printed does not compile until you add it. Beyond the missing import there is a design point for anyone transforming text. A replacement written as a match on Event::Text works on one event at a time:
let parser = parser.map(|event| match event {
	Event::Text(text) => Event::Text(text.replace("abbr", "abbreviation").into()),
	_ => event
});
If a phrase is split across two events, a substitution like that one misses the seam, and the merge helper is the answer the crate offers to that problem.
Compliance is a stated goal and the workspace carries two fuzzers
The README claims 100% compliance with the CommonMark spec as a goal, and the repository's own layout shows how that goal is pursued. The root holds fourteen entries, and four of them are not documentation: bench/, fuzz/ and dos-fuzzer/ are all named as workspace members alongside the two published crates and guide/demo. A denial-of-service fuzzer is a separate target from the general one, which tells you that adversarial input handling is treated as its own problem rather than a variation on parsing. None of the three is mentioned anywhere in the README, which describes benchmarks and fuzzing only by pointing at the examples directory. The published version is 0.13.4, tagged v0.13.4 and titled 0.13.4, and the two releases before it are v0.13.3 on 2026-03-22 and v0.13.2 on 2026-03-21, one day apart. So the crate is well past its first release and still carrying a 0.x version, with patch releases arriving on consecutive days in the same week.
Four of the five extensions are GitHub's and the fifth is markdown-it's
CommonMark is the base, and the extensions are optional on top of it. Four of the five are GitHub's: tables, task lists and strikethrough, each linked to the corresponding GitHub flavoured Markdown extension, plus footnotes. The fifth is different in origin. The highlight extension handles ==marked== and renders it as a mark element, and the link for it points at markdown-it-mark rather than at a specification. So enabling everything gives you a document that mixes two dialects, and a document that renders the same way on GitHub and through this parser will still differ wherever the two sets of extensions disagree. The Options type is what turns these on, which is also why the TextMergeStream snippet imports Options without using it: the extension flags and the merge helper travel through the same constructor path, and examples in the file are not always kept in step with each other. All of this is opt-in, so the default output is CommonMark and nothing else.
SIMD is x64 only and it is the one place unsafe code is allowed
The safety claim has exactly one exception and it is a feature you open yourself. The README says the crate is written in pure Rust with no unsafe blocks, except in the opt-in SIMD feature, and that SIMD accelerated scanners are available for the x64 platform from version 0.5 onwards. Two things follow. On any non-x64 target, enabling the feature buys nothing, so the same flag is meaningful on a desktop x64 machine and inert on ARM hardware, which covers a large share of what the rest of the crate's users run. And an audit that stops at the default feature set will not see the unsafe code, because it is not compiled in unless asked for. Turning it on is a build flag rather than a runtime setting:
> cargo add pulldown-cmark --no-default-features --features=simdThe default build is the plain one, so the safe-by-default property holds for anyone who does not read past the first paragraph of the design goals.
One flag drops the binary and switches off std at the same time
The build options are where the switches pile up. By default the binary is built as well, and if you do not want or need it you build with no default features:
> cargo add pulldown-cmark --no-default-featuresThe same flag has a second documented job. no_std support is enabled by compiling with --no-default-features to disable std support and --features hashbrown for the Hash collections that are only defined in std for internal usage in the crate. So one switch means two different things depending on which page of the README you read it from: trim the packaged binary, or build without the standard library. Adding the hashbrown feature on top is only necessary in the second case, since the collections are an internal dependency of the crate rather than part of its interface. The dependency snippet that demonstrates the no_std configuration asks for version = "*", a wildcard, and the snippet itself stops partway through the word false, so the example is the least finished part of an otherwise specific file.
The root profile repeats the advice the README gives you for your own
The workspace file is short and does three things. It sets default-members to the two published crates, pulldown-cmark and pulldown-cmark-escape, while the members list is longer and adds bench, dos-fuzzer, fuzz and guide/demo, so a bare cargo build at the root builds the two default members rather than everything in the tree. It sets resolver = "2", which is the edition-2021 dependency resolution behaviour. And it carries a release profile of three lines:
lto = true
codegen-units = 1
panic = "abort"
Those are exactly the three settings the README tells you to put in your own release profile for higher release performance, which is the useful detail here: the crate's own profile section only applies when it is the root package being built, which is why the advice is to copy them rather than rely on them. Two smaller things sit alongside. Cargo.lock is committed at the root of a library, and the tree carries a second published crate, pulldown-cmark-escape, for HTML escaping, plus guide/ which holds the demo that matches the project's homepage. The toolchain floor is Rustc 1.71.1 or newer, stated to the patch level.
Editorial conclusion
pulldown-cmark is a good fit when you want to walk a Markdown document as events, need byte offsets back for highlighting or reporting, and do not want a document tree in memory, because the parser implements Iterator directly and into_offset_iter hands you a range with every event. It is a poor fit if you need a stable API to design against, since the published version is 0.13.4 and two patch releases landed on consecutive days in March 2026, or if you want CommonMark output without reading about which options you have to turn on. Three things to check first. That you are writing to a buffered target, because the HTML renderer performs many very small writes and writing straight to stdout, files or sockets is described as detrimental to performance. That your transform survives split text events, since the parser can emit consecutive text events and TextMergeStream exists for exactly that reason. And that you build with the features you actually mean, because --no-default-features does two jobs at once, dropping the command-line binary and disabling std, and the SIMD scanners behind it exist for x64 only.
Frequently asked questions
What is pulldown-cmark and when would I reach for it?
It is a pull parser for CommonMark written in Rust, so you iterate events instead of implementing callbacks or building a document tree, and it also ships a small command-line tool for rendering to HTML. Rustc 1.71.1 or newer is required to build the crate.
Which Markdown extensions does pulldown-cmark support?
Footnotes, GitHub flavoured tables, GitHub flavoured task lists and strikethrough, all optional, plus a highlight extension where ==marked== renders as a mark element, which follows markdown-it rather than the GitHub set of extensions.
Does pulldown-cmark use unsafe code?
The README states it is written in pure Rust with no unsafe blocks, except in the opt-in SIMD feature. Those accelerated scanners are available for the x64 platform from version 0.5 onwards, so the exception is compiled in only when you ask for it.
How do I get source offsets while parsing with pulldown-cmark?
Call into_offset_iter(), which yields pairs of an event and a Range, where the range is the event's corresponding range in the source document. Text events are small copy-on-write strings, and the vast majority of text fragments are slices of the source document.
Why is my pulldown-cmark HTML output slow when written straight to a file?
The renderer performs many very small writes, so the README says to write to a buffered target such as a Vec<u8> or a String, and to wrap other writers in a BufWriter. Writing directly to stdout, files or sockets is described as detrimental to performance.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pulldown-cmark-pulldown-cmark)Star history chart for your README
[](https://hysenlabs.com/projects/pulldown-cmark-pulldown-cmark)Was this useful?