Puppeteer downloads Chrome from an install script your package manager may block
JavaScript API for Chrome and Firefox
At a glance
- What is it?
- A JavaScript library with a high-level API over two browser protocols, shipped as two npm packages that differ in whether they fetch a browser at install time. The awkward part is that the download runs as an install script, and several package managers now block those by default.
- Who is it for?
- Take Puppeteer when you need to script a real Chrome or Firefox instance and you are willing to own the browser binary. Two decisions settle most of it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
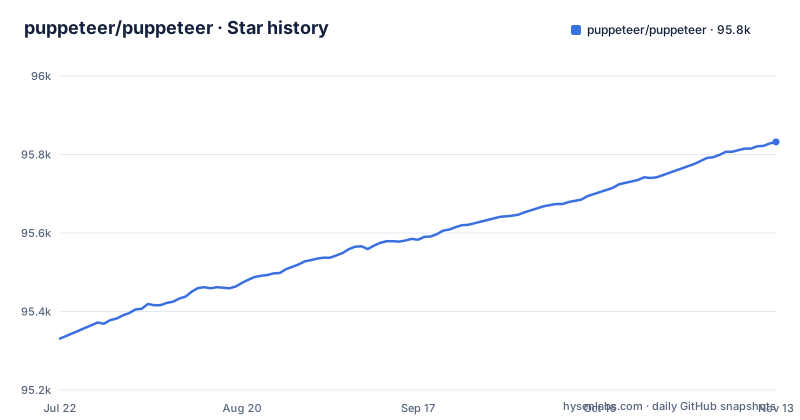
- puppeteer/puppeteer95,832 ★ · +501
| Repository | 2026-07-22 | 2026-11-13 |
|---|---|---|
| puppeteer/puppeteer | 95.3k | 95.8k |
501 Stars in the last 114 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Headless is the default, and the test matrix treats visibility and transport separately
The README states one default outright: Puppeteer runs in the headless mode, with no visible UI, by default.
The scripts in package.json split Chrome coverage along two independent axes. Visibility gives you test:chrome:headless, test:chrome:headful and test:chrome:shell. Transport gives you test:chrome:pipe, test:chrome:bidi and test:chrome:bidi-only. Firefox gets its own three, test:firefox, test:firefox:headful and test:firefox:headless, which matches the repository description of a JavaScript API for Chrome and Firefox.
The consequence for a reader is that a headless default is not the same as a headless-only library, and it is not the same as one protocol. A bug that only appears over WebDriver BiDi is caught by a different script than a bug that only appears with a visible window. If you are reproducing a report, the transport name in the script is the first thing to match, because it names the layer where the failure lives.
The install script that fetches Chrome is blocked by default, and the error arrives later
This is the sharpest edge in the project, and the README states it as a note rather than a warning. Modern package managers, including npm under its own RFC, plus pnpm, Yarn, Bun and Deno, block dependency install scripts by default. If the install script is blocked, Puppeteer will not download the browser during installation, leading to runtime errors.
Read that last clause carefully. The failure is not at install time. The README says the missing browser leads to runtime errors, so the problem shows up when your script launches one. That gap between cause and symptom is what makes this expensive to diagnose, because the stack trace points at your code and not at a package manager policy.
There are two documented ways out. Download the browser yourself afterwards:
npx puppeteer browsers installOr let the script run by configuring the package manager, which for npm means adding "puppeteer" to "allowScripts" in your package.json. Pick one deliberately and record it in the repository, because a fresh clone on a different machine or a CI image with a different package manager will silently take the other path.
puppeteer or puppeteer-core is a cache decision, not an API decision
Two lines in the README cover the whole packaging question:
npm i puppeteer # Downloads compatible Chrome during installation.
npm i puppeteer-core # Alternatively, install as a library, without downloading Chrome.
The difference is the download, nothing else. The README's own example says so in a comment: import puppeteer from 'puppeteer', or import puppeteer from 'puppeteer-core'. Same launch call, same page object, same selectors.
So the choice is about who owns the browser binary. With puppeteer, the install step is responsible for placing a compatible Chrome on disk, which is convenient locally and expensive in CI, where the download either hits a cache or does not happen at all. With puppeteer-core, nothing is downloaded, which is what you want when a base image already ships a browser or when your pipeline builds one deliberately.
The trap is that the two feel identical in code and behave differently in a pipeline. A script that works on a laptop because the install fetched Chrome will fail on a runner that skipped the script, and the switch to puppeteer-core is invisible in the source. Decide from the CI cache policy, not from the import line.
Three tags in the same second, and two independent version lines
The three most recent releases were all published on 2026-10-22, seconds apart: puppeteer-v25.16.0, puppeteer-core-v25.16.0 and browsers-v3.2.6. Read the numbers rather than the timestamps. The first two sit on the 25.x line together, so the API package and the core package move in step. The third is on 3.x, so the browser management layer is on its own cadence, and it is a separate package in packages/, referenced in the build graph as ./packages/browsers:build.
That is a deliberate arrangement, and the release tooling shows how it is produced. The repository has release-please configuration files, and package.json has a release-please-dry-run script that runs release-please release-pr with the repository URL and a --dry-run flag.
For a reader this means two things worth internalising. Upgrading Puppeteer and upgrading the code that downloads browsers are separate version decisions that happen to coincide on release day, so a lockfile pinning puppeteer 25.16.0 says nothing about which browsers version you are on unless you look. And the fact that a dry-run script exists tells you the publish path is meant to be rehearsed before it runs.
page.locator addresses elements by accessible name, so renaming a button breaks the test
The README's example ends on a line worth reading twice:
import puppeteer from 'puppeteer';
const browser = await puppeteer.launch();
const page = await browser.newPage();
await page.goto('https://developer.chrome.com/');
await page.setViewport({width: 1080, height: 1024});
await page.keyboard.press('/');
await page.locator('::-p-aria(Search)').fill('automate beyond recorder');
The selector is the ::-p-aria pseudo-element applied to a visible name, Search. The element is found through its accessible name, not through a CSS class or an id, which means the test is coupled to the wording a screen reader would announce.
That coupling is the point and the cost. It catches a button that has lost its label, which a class-based selector would sail past. It also fails when someone improves the copy, or when the localised build announces a different name, and it fails in a way that looks like a Puppeteer failure rather than a content change. Two protocols are in play underneath, the DevTools Protocol and WebDriver BiDi, with a worked example at examples/webdriver-bidi.mjs, and neither changes this: the name is what you are pointing at.
examples/ includes running inside a browser and inside an extension
The examples directory is small and pointed. Ten single files: block-images.js, cross-browser.js, custom-event.js, detect-sniff.js, pdf.js, proxy.js, screenshot.js, screenshot-fullpage.js, search.js and webdriver-bidi.mjs, plus a README.md.
Two of the entries are directories, and they are the interesting ones. examples/puppeteer-in-browser/ and examples/puppeteer-in-extension/ describe deployments where Puppeteer runs somewhere other than a normal Node process. A library that is expected to work inside a page and inside a browser extension has different constraints from one that only runs in a server process, and the fact that both are maintained here is the clearest statement of the intended surface.
The module detail is small but real. The root package.json sets type to module, and the file list mixes extensions: webdriver-bidi.mjs alongside plain .js files. Nothing here documents why, so if you are copying an example into a CommonJS project, check the import form yourself rather than assuming the directory listing transfers.
puppeteer-repo is private, and --if-present hides a workspace that lost its script
The root manifest is not the published library. It is named puppeteer-repo, marked private, and it carries package-lock.json plus a wireit configuration driving the build. The package you install from npm is a different artifact, built out of packages/.
The workspace plumbing is where a contributor can lose time. Several scripts fan out with the same shape, check, clean, unit, postinstall and prepare all run npm run with --workspaces --if-present. That flag is the quiet part: a workspace that is missing the script is skipped without complaint, so a rename or a broken manifest produces a green run that covered less than you think.
Two more scripts check dependencies and licences. validate-deps calls node tools/validate-deps.mjs, and validate-licenses runs a TypeScript file through node --experimental-strip-types. If a build fails on a machine that otherwise works, check those two, and check whether the workspace you expected to run actually had the script.
Editorial conclusion
Take Puppeteer when you need to script a real Chrome or Firefox instance and you are willing to own the browser binary. Two decisions settle most of it. Choose puppeteer-core when your CI already caches a browser or supplies one, because npm i puppeteer downloads compatible Chrome during installation and that download is the fragile part. Then confirm your package manager actually runs install scripts, since npm, pnpm, Yarn, Bun and Deno block them by default and the missing browser only shows up as a runtime error. Before writing selectors, read page.locator('::-p-aria(Search)') in the README example again: elements are addressed by accessible name, so renaming a button breaks the test that clicks it.
Frequently asked questions
What is a puppeteer?
In this repository, Puppeteer is a JavaScript library that provides a high-level API to control Chrome or Firefox over the DevTools Protocol or WebDriver BiDi. It runs in the headless mode, with no visible UI, by default.
how to install puppeteer
There are two packages. npm i puppeteer downloads compatible Chrome during installation, while npm i puppeteer-core installs as a library without downloading Chrome. If your package manager blocks install scripts, run npx puppeteer browsers install afterwards.
how to use puppeteer
The README example imports puppeteer from 'puppeteer' or from 'puppeteer-core', calls puppeteer.launch(), opens a page with browser.newPage(), navigates with page.goto(), sets a viewport with page.setViewport(), then locates an element with page.locator() and fills it.
how to use puppeteer mcp
The README points to chrome-devtools-mcp, a Puppeteer-based MCP server for browser automation and debugging. Puppeteer also supports the experimental WebMCP API.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/puppeteer-puppeteer)Star history chart for your README
[](https://hysenlabs.com/projects/puppeteer-puppeteer)Was this useful?