Pyro's dev branch, its master checkout, and the extras bracket that decides whether the examples run
Deep universal probabilistic programming with Python and PyTorch
At a glance
- What is it?
- Pyro is a probabilistic programming library on PyTorch, and its install instructions split into a stable path and a dev path that do not clone the same tree. The dependency metadata also draws a line the docs do not draw.
- Who is it for?
- Pyro suits a team that already lives in PyTorch and wants a probabilistic layer without leaving the ecosystem, provided you read the install section closely enough to notice which tree you cloned. Anyone who needs a documented throughput baseline, or who runs on a Python version past the one the classifiers name, should check the pyproject metadata before committing.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 41 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
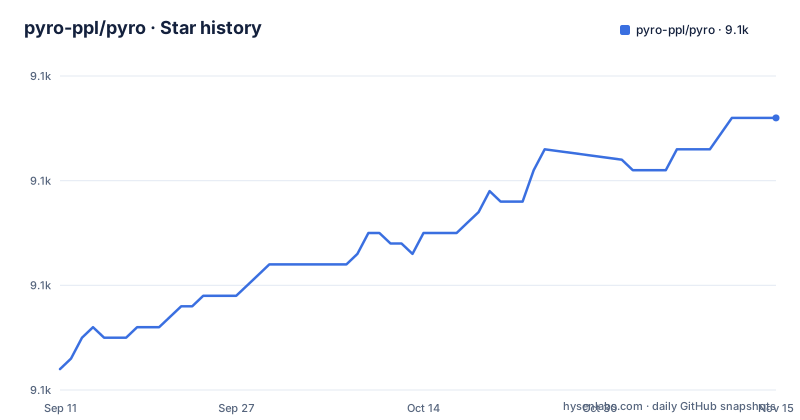
- pyro-ppl/pyro9,076 ★ · +24
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| pyro-ppl/pyro | 9.1k | 9.1k |
24 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Pyro's flexibility principle splits into two paths into the same model
The design principles name four properties, and the fourth is the one that shapes day-to-day use. The stated goal is automation when you want it and control when you need it, achieved through high-level abstractions for expressing generative and inference models while letting experts reach in and customize inference. So a model gets written once against the abstractions, and the inference side is where the two audiences diverge. For the application of the library, that means the abstraction layer is enough. For the person writing the inference algorithm, it means reaching past it. Nothing in that paragraph names a specific customization entry point, so a reader planning to write a custom inference algorithm should confirm in the API docs which hook is available before designing around one.
Universal is a claim about expressivity, and scalability comes with no published number
The universality claim is stated in one line: Pyro is a universal probabilistic programming language, meaning it can represent any computable probability distribution. That is a statement about what can be written, not about how fast it runs or how large a model can be. The scalability claim is separate and compares against a baseline rather than an absolute: it scales to large data sets with little overhead compared to hand-written code. There is no figure attached to that comparison, and no benchmark table in the README. The repository does carry a performance entry point, so the comparison is something you would have to run yourself rather than read:
bash scripts/perf_test.sh ${ref}That is the Makefile's perf-test target, and it takes a reference argument. The consequence for a reader is concrete: there is no published baseline in the project text to size your expectations against, and the sibling target for profiling takes a reference and a model list:
bash scripts/profile_model.sh ${ref} ${models}The dev branch is the default, but the stable recipe checks out master
The two from-source installs in the README differ in more than a comment. The stable path uses SSH and then pins the tree:
git clone [email protected]:pyro-ppl/pyro.git
cd pyro
git checkout master  # master is pinned to the latest release
pip install .
The dev path uses an HTTPS URL and never checks anything out, which leaves you on whatever the repository's default branch is:
git clone https://github.com/pyro-ppl/pyro
cd pyro
pip install .
The project metadata records that default branch as dev, and the coverage badge in the README tracks the dev branch too. So the checkout line is doing real work in the stable path, and skipping it in the dev path is the documented behavior rather than an omission. A reader who clones the stable way but forgets the checkout line ends up installing from the development tree while believing they installed a release, which is exactly the confusion the comment on that line warns against.
extras is one bracket away, and the example models must match your release
Running the models under examples/ and tutorials/ needs a second install:
pip install pyro-ppl[extras]The contents are declared as the extras group and cover the plotting and notebook side of those models: notebook, ipywidgets, graphviz, matplotlib, torchvision, pandas, pillow, scikit-learn, seaborn, wget, and scipy. Three more optional groups sit alongside it and are not part of extras: horovod, pulling horovod with the pytorch extra, lightning, and funsor. The funsor entry is pinned to an exact version and gated on the interpreter:
funsor = [
    "funsor[torch]==0.4.8; python_version >= '3.10'",
]
That marker means the pin applies only from 3.10 upward, and the version is exact rather than a floor, so it will not float. The other documented failure mode is version drift between code and models: the instruction says to make sure the models come from the same release version of the source as the one you installed. Running a tutorial model against a mismatched install is a mismatch the project asks you to rule out yourself.
requires-python opens at 3.8 while the classifiers stop at 3.11
The packaging metadata draws a boundary the prose does not discuss. The interpreter floor is declared broadly:
requires-python = ">=3.8"The classifier list, however, names only Python 3.8, 3.9, 3.10, and 3.11. There is no entry for anything newer, which means the declared support and the enumerated support are not the same set. Since the floor is an open inequality, pip will resolve and install the package on a newer interpreter without complaint, because nothing in requires-python excludes it. The consequence is that a reader on a Python release past 3.11 gets no signal from the metadata that the combination is unclassified, and has to find out from the issue tracker or the CI matrix instead. The operating system classifiers are narrower still, listing only POSIX Linux and MacOS X, so Windows is likewise undeclared rather than excluded.
The build side is unremarkable but worth recording: the backend is setuptools with a floor of version 77.
The doctest run deliberately skips the torch wrapper distributions
The Makefile carries a doctest target with a comment explaining an omission, and the omission is the interesting part. The wrapper classes under pyro.distributions.torch are excluded because they include torch docstrings, which are tested upstream rather than here:
python -m pytest -p tests.doctest_fixtures --doctest-modules -o filterwarnings=ignore pyro --ignore=pyro/distributions/torch.pyTwo settings travel with that run beyond the ignore path: warnings are filtered rather than promoted, and a project-specific plugin supplies the fixtures. So this target cannot catch a documentation regression inside the torch wrappers, by design, and the correctness of those docstrings rests on the upstream PyTorch suite instead. A reader who edits a docstring under pyro/distributions/torch.py and sees the doctest target pass should not read that green as coverage. The filterwarnings=ignore setting also means a warning introduced by a change in this project will not surface as a failure here. The lint target is the one that runs type checking, with mypy invoked against the pyro, scripts, and tests directories alongside ruff.
Tests run in stages, and the tutorial check only sees notebooks marked smoke_test
The test target is a chain, not a single command: it depends on lint, docs, and doctest, then runs the unit stage. Each stage is selectable on its own, which is how a contributor narrows a run:
pytest -vx -n auto --stage unitThe integration stage uses the same invocation with a different stage name, and the examples have their own stage, test_examples. The notebook check is the one with a real limitation, and it is visible in how it selects files. It greps the tutorial notebooks for the string smoke_test, filters out any notebook that carries a smoke_test = False line, and passes the rest to pytest with --nbval-lax and --current-env. A tutorial notebook that never mentions smoke_test is therefore never executed by this target at all. That is a reasonable way to keep documentation notebooks from breaking a test run, but it means coverage of the tutorials depends on the notebooks opting in, and a reader should not assume every tutorial under tutorial/source has been run.
There is also a scrub target that runs nbstripout over the tutorial notebooks with --keep-output and --keep-count, then runs a cleaning script over the same files.
Version 1.9.2 landed more than two years after 1.9.1
The release stream is irregular, and that has consequences for how you pin. The three most recent tags are 1.9.2, 1.9.1, and 1.9.0. Version 1.9.0 was tagged in February 2024, 1.9.1 followed in June of that year, and 1.9.2 came in October 2026. The gap between the two latest is therefore more than two years, during which the repository itself kept moving: the last recorded push is 2026-10-05, two days after the 1.9.2 tag. The project is not archived, and a RELEASE-MANAGEMENT.md sits at the top level of the tree alongside the contribution and code of conduct files. What the irregular spacing changes is the upgrade question. Someone who installed 1.9.1 and asks for the current release is not taking a patch or a minor step, and there is no release-by-release changelog in the README to size that jump against. Go by the version notes rather than by the version number's shape.
Editorial conclusion
Pyro suits a team that already lives in PyTorch and wants a probabilistic layer without leaving the ecosystem, provided you read the install section closely enough to notice which tree you cloned. Anyone who needs a documented throughput baseline, or who runs on a Python version past the one the classifiers name, should check the pyproject metadata before committing. For a production dependency, pin the release deliberately: the gap between 1.9.1 and 1.9.2 spans more than two years, so a fresh install is a large jump.
Frequently asked questions
What is Pyro used for?
Pyro is a probabilistic programming library built on PyTorch, for expressing generative models and running inference over them. It offers high-level abstractions for both, while letting experts customize the inference side.
What are Pyro objects?
Pyro describes itself as implemented with a small core of powerful, composable abstractions, which are the objects you build against. The declared intent is a core small enough to stay agile and maintainable while covering generative and inference modeling.
What is meant by the prefix pyro?
The project text does not explain the origin of the name. What it does record is the naming of the artifacts: the PyPI distribution is pyro-ppl, the repository is pyro-ppl/pyro, and the homepage is pyro.ai.
Does Pyro mean fire?
Nothing in the project's own text defines the word as a common noun or explains a derivation, so there is no basis in the repository for reading it that way. Pyro is used throughout as the library's name only.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pyro-ppl-pyro)Star history chart for your README
[](https://hysenlabs.com/projects/pyro-ppl-pyro)Was this useful?