ratel puts a search index in front of your tool schemas
Context engineering for AI agents. ~80% fewer tokens. Fix tool overload. Skills and memory with in-process BM25 and semantic retrieval. Progressive Disclosure. No vector DB.
At a glance
- What is it?
- A context engineering layer that indexes tools and skills so an agent looks up what a turn needs instead of being handed everything. BM25 by default, dense retrieval only when you ask for it, a Rust core with NAPI and PyO3 bindings, and no vector database.
- Who is it for?
- Adopt ratel if your agent has accumulated more tools than it can hold in context, and you want selection to be deterministic and inspectable rather than model-guessed. Do not adopt it expecting the token saving to transfer to a different workload without measuring, since the headline figure is a claim from the project and the full results live on a separate benchmark site.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
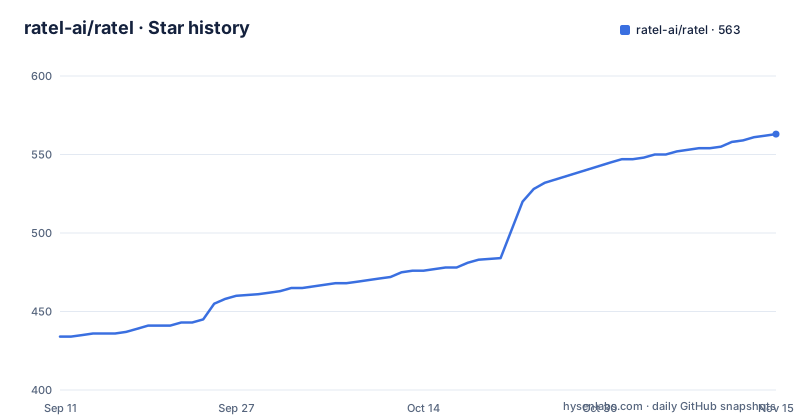
- ratel-ai/ratel563 ★ · +129
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| ratel-ai/ratel | 434 | 563 |
129 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Progressive disclosure instead of a bigger system prompt
The problem is stated as two costs rather than one. The cost is that every tool schema, every skill, and a growing list of instructions in the system prompt are tokens you pay for on every single call. Send them all up front and you pay for them all, every turn.
The second cost is accuracy. Models get worse as that context grows. Crowd them with tools, skills and instructions a turn does not need and the model picks the wrong option and drifts off task. A tool the model should never have considered is still competing for its attention.
What ratel does about it is index the tools and skills into a catalog that the agent progressively discloses. On each turn it searches for what is needed and injects only the matching capabilities. Tools are invoked by id, and skill instructions stay out of context entirely until the agent loads a relevant playbook with `get_skill_content`.
That shape matters more than the specific algorithm. A system prompt listing forty tools is a fixed tax with a fixed accuracy cost. A catalog turns the same forty tools into something looked up, which is the difference between a toolbelt and a toolbox.
The repository description claims around 80 percent fewer tokens, and the README points to a separate benchmark site for the full results rather than restating them.
BM25 unless you ask for anything else
The default retrieval is lexical, and the choice is described in terms of what it costs.
The indexes use BM25 by default, the same algorithm behind most search engines, applied to each tool's name, description and argument names, and to skill names, descriptions and tags. The stated properties are that retrieval is fast and deterministic.
Deterministic is the word that carries the argument. A model deciding which tools to load produces a different answer each run; a ranking function produces the same one. For an agent that must justify why it called a tool, or must behave the same way in a test, that is worth more than semantic nuance.
Semantic and hybrid ranking are opt-in, per catalog or per call. When you do turn them on, SDK callers register capabilities, which is when the embedding happens, and search dense indexes asynchronously. Embeddings come either from an in-process model or from an OpenAI-compatible endpoint.
So the cost ladder is real. The default needs nothing: no model, no endpoint, no index server. Dense retrieval is a decision you make per catalog, and it is paid for at registration time rather than at query time, which is the right place for that cost.
That is also why the project can say no vector database with a straight face. There is no server component in this design at all.
Facts get re-injected only when they go stale
There is a second category alongside tools and skills, and it handles a different problem.
Search-based selection is the wrong mechanism for constant grounding: a shop's address, a brand's voice, the details of a product line. Those are not things a turn should have to look up, and they are not things a turn should pay to re-read either.
So they are registered as facts and pushed into context directly. The condition attached is the interesting part: they are re-injected only when they are not already fresh in the transcript. If the address is still in context from two turns ago, nothing is added. When the transcript has moved past it, it goes back in.
That is a small rule with a large effect on cost, because grounding facts are exactly the kind of content that tends to be duplicated defensively by a prompt author. One copy, refreshed when it expires, rather than one copy per turn or one copy per agent.
The tools that do the looking up have short names in both SDKs. `search_capabilities` returns focused results from separate tool and skill indexes, and the TypeScript surface also exposes `getSkillContentTool` and `invokeToolTool` as tools in their own right, so search itself can be handed to a model that has no other way to ask.
One Rust engine, three language bindings
The repository layout explains the shape of the project better than the feature list does.
`src/core` is a Rust retrieval engine published as `ratel-ai-core`. `src/sdk/ts` is the TypeScript SDK, published as `@ratel-ai/sdk` and NAPI-bound, meaning it loads as a native addon rather than through a pure-JavaScript port. `src/sdk/python` is the PyPI package `ratel-ai`, PyO3-bound. Alongside them sit adapters for the Vercel AI SDK and for Mastra, a `telemetry/` directory holding OpenTelemetry conventions and helper packages, and a `protocol/` directory holding the catalog-source wire contract.
That wire contract is the piece that matters for anyone building on top. It is the format a catalog source has to speak, which is what makes it possible for the MCP distribution to sit in front of an existing setup rather than requiring a rewrite.
The examples directory shows the matrix of choices the SDKs are meant to cover: the Vercel AI SDK, Pydantic AI, Mastra, an MCP chat example, telemetry examples in both languages, adaptive ranking examples, and a pair of S3-backed ranking examples, which is how a dense index gets persisted rather than rebuilt.
Prerequisites for building are Rust stable, Node 24 or newer and pnpm 10.28 or newer, with Python 3.9 and uv for the Python side. The build itself is three lines per language:
cargo build --workspace && cargo test --workspace   # Rust
pnpm install && pnpm -r build && pnpm -r test       # TypeScript
Versions are per package, tagged independently
The three most recent tags are `vercel-ai-sdk-v0.6.0-rc.1`, `sdk-ts-v0.13.0-rc.9` and `sdk-ts-v0.13.0-rc.8`, all created on 2026-10-01.
That is not untidy tagging, it is a recorded decision. The workspace manifest carries a comment referencing an architecture decision record, ADR-0008, stating that versions are per-package: each release unit carries its own version in its own manifest and is tagged independently, with tag prefixes for the core, the TypeScript SDK and the Python SDK. Only non-version metadata is shared at the workspace level.
The consequence is that a user installing the Python SDK is not pulled into a version bump of a TypeScript adapter they do not use. For a project with a Rust core, two SDKs and two framework adapters, that is the difference between an upgrade and a rebuild.
The cost is that there is no single version number to quote, and a bug report has to say which package it is about.
The workspace itself is small by contrast. Four members: the core, the telemetry core, and the native halves of the TypeScript and Python SDKs, on cargo resolver 3 and edition 2024.
Apache for the engine, MIT for the SDKs
The licensing is split on purpose, and the README links the reasoning.
The `ratel-ai-core` engine is under Apache-2.0, described as an explicit patent grant for the engine that others embed. Everything else, meaning the SDKs, the telemetry helpers and the examples, is MIT. The rationale is written up in ADR-0009 in the documentation directory.
That is a defensible split. A retrieval engine that companies embed into their own products carries a different risk profile from the thin binding layer around it, and Apache-2.0's patent clause is the part that matters for an embedded component. MIT for the SDKs keeps adoption friction low.
The repository backs the split with the matching files at the root: an Apache licence file, an MIT licence file, and a NOTICE file.
If you are embedding the engine in something you distribute, this is the line to check rather than the repository's overall label.
Two other governance artefacts sit alongside them: an ADR directory configured in the repository root, and a release document describing how the independent tagging works.
The release profile is tuned for download size
One block in the Cargo manifest is commented at length, and the reasoning is about what the user downloads rather than about what the compiler produces.
Release builds ship as native addons, the SDK shared libraries, where binary size is user-facing install weight. Three settings follow from that. Symbols and debug tables are stripped, since they serve no runtime purpose. Thin link-time optimisation is enabled. And codegen units are set to one, so dead-code elimination can cross crate boundaries.
That last one is the interesting constraint. The comment names what gets eliminated: unused candle-transformers models and gemm kernels. Both are large, both are pulled in by the dense-index path, and neither is needed by a user who stays on BM25.
The comment also explains why the profile has to live in the workspace root, since cargo ignores a profile section declared in a member manifest. That is the kind of detail that saves an afternoon for anyone who tries to tune a single crate and finds the setting ignored.
The practical effect is that the default configuration is the small one. A user who never enables semantic ranking does not download the model weights for a ranking mode they are not using, which is the same argument the BM25 default makes one level up.
Editorial conclusion
Adopt ratel if your agent has accumulated more tools than it can hold in context, and you want selection to be deterministic and inspectable rather than model-guessed. Do not adopt it expecting the token saving to transfer to a different workload without measuring, since the headline figure is a claim from the project and the full results live on a separate benchmark site. Verify two things first. Read the benchmark site rather than the summary, because the number that matters is your own accuracy under tool overload. Then check the licence split, since the Rust engine is Apache-2.0 while the SDKs and examples are MIT, which matters if you embed the engine in something you distribute.
Frequently asked questions
What does Ratel do for an AI agent?
It indexes your tools and skills into a catalog the agent searches each turn, injecting only the capabilities that turn needs. Constant grounding such as an address or a brand voice is registered separately as facts and re-injected only when it is no longer fresh in the transcript.
Does Ratel need a vector database?
No. The default retrieval is BM25 over tool names, descriptions and argument names, and over skill names, descriptions and tags. Semantic and hybrid ranking are opt-in per catalog or per call, and when enabled the embeddings are produced by an in-process model or an OpenAI-compatible endpoint.
How do I install Ratel?
With pnpm add @ratel-ai/sdk for TypeScript, or pip install ratel-ai for Python. The retrieval engine itself is published to crates.io as ratel-ai-core. You then register tools and skills on a ToolCatalog and a SkillCatalog and call search_capabilities when the agent needs to act.
What is the Ratel licence?
The ratel-ai-core engine is Apache-2.0, described as an explicit patent grant for the engine others embed. The SDKs, telemetry helpers and examples are MIT. The README links ADR-0009 for the reasoning behind the split.
Are Ratel versions released together?
No. Versions are per package, each release unit carrying its own version in its own manifest and tagged independently with prefixes for the core, the TypeScript SDK and the Python SDK, as recorded in ADR-0008. The three most recent tags were all created on 2026-10-01.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ratel-ai-ratel)Star history chart for your README
[](https://hysenlabs.com/projects/ratel-ai-ratel)Was this useful?