swarmvault: graph edges tagged extracted, inferred, or ambiguous
The local-first LLM Wiki: open-source knowledge graph builder, RAG knowledge base, and agent memory store. Built on Andrej Karpathy's pattern. An Obsidian alternative for personal knowledge management, AI second brain, and durable Claude Code / Codex / OpenClaw memory.
At a glance
- What is it?
- swarmclawai/swarmvault implements Karpathy's three-layer LLM wiki pattern as a local Node CLI that turns documents, code, transcripts, notes, and URLs into markdown plus a typed knowledge graph, tags every edge with its provenance so hallucinations are visible rather than compounding, and ships a container whose stated purpose is satisfying an MCP registry's introspection check.
- Who is it for?
- swarmvault is worth a look if you already keep a pile of source material and want an agent to be able to read across it, because the design decisions are pointed. Raw sources stay immutable, the wiki is the artifact that compounds, and the schema is a file you and the model revise together.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 137 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
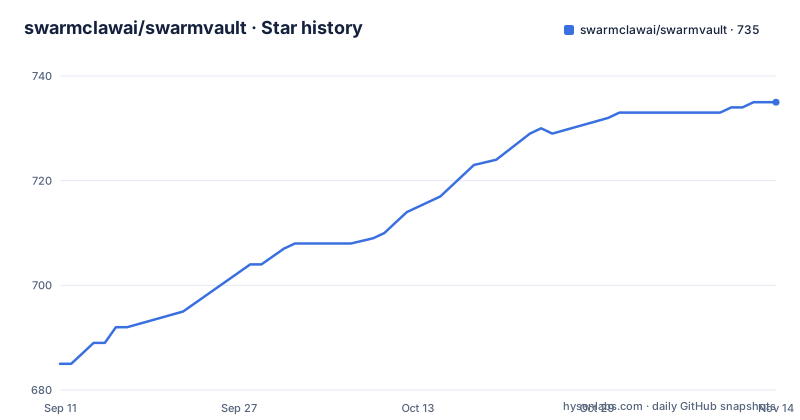
- swarmclawai/swarmvault735 ★ · +50
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| swarmclawai/swarmvault | 685 | 735 |
50 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Every edge is labelled with where it came from
The documentation opens its argument with the objection everyone raises about generated wikis, which is that hallucinations compound because each generation reads the previous one. The answer is provenance on every edge in the graph. Each one is tagged `extracted`, `inferred`, or `ambiguous`, so a reader can tell a claim the model lifted from a source from one it reasoned to, and from one it is not sure about. On top of that sits contradiction detection, which flags conflicting claims rather than silently preferring one. Changes are not written straight into the wiki either: `compile --approve` stages everything into reviewable approval bundles, and new concepts land in `wiki/candidates/` before anyone promotes them. `lint --conflicts` audits for contradictions whenever you ask. That is a workflow answer, not a technical one, and it is the difference between a generated corpus and a reviewable one.
raw/ is immutable and the schema is a file you revise with the model
The three-layer structure is the part taken from the pattern this project credits to Andrej Karpathy, and SwarmVault implements it rather than describing it. The first layer is `raw/`, your curated source documents, described as immutable: the tool reads from them and never modifies them. The second is `wiki/`, which holds LLM-generated and human-authored markdown, source summaries, entity pages, concept pages, cross-references, dashboards, and outputs, and which the documentation calls the persistent, compounding artifact. The third is `swarmvault.schema.md`, a file that defines how the wiki is structured, what conventions to follow, and what matters in your domain, and that you and the model revise together over time. The historical framing is Vannevar Bush's Memex from 1945, and the observation attached to it is pointed: Bush solved associative trails between documents but not the question of who does the maintenance. The model is the answer to that.
The first run needs no key because the provider is heuristic
The documentation states it plainly: no API keys are required for the first run, because the built-in heuristic provider runs locally and offline. That is a deliberate design choice, and it has a visible consequence. The first compile tells you how the tool structures things, and the quality of extraction is bounded by a heuristic until you point it at something better. The suggested upgrade is a free local model through Ollama, and cloud providers are described as optional rather than as the default path. What makes this testable rather than aspirational is the release tooling. The root manifest defines separate smoke lanes for the heuristic provider, the heuristic provider with a browser check, Neo4j, Ollama, OpenAI, and Anthropic, plus a corpus run and a CLI surface check. Six backends exercised by named scripts is a different claim from saying the tool supports them.
Hybrid search is SQLite full-text plus embeddings
The scaling question is answered with a specific pair of mechanisms rather than a reassurance. Search merges SQLite full-text with semantic embeddings, which is what lets a query work without fitting every page into context, and the local index lives at `state/retrieval/`. Generation is bounded separately, with `compile --max-tokens` trimming output to fit a window you choose. Alongside search there is traversal, and the graph commands are worth knowing by name: `graph query` to find, `graph path` to walk between nodes, `graph explain` to see why an edge exists, and `graph callers` to work backwards. The comparison table in the documentation frames the whole tool against the original gist on eighteen axes, and the two rows that name a technology are the hybrid search row, where the gist is described as indexing a single markdown file and SwarmVault as using SQLite full-text plus embeddings. `SCALE.md` at the repository root is where the detail sits.
quickstart is an alias for scan, and next tells you where you are
The entry path is two commands:
npm install -g @swarmvaultai/cli
swarmvault quickstart ./your-repo
`quickstart` initialises a vault in the current directory, ingests a local file, a directory, or a public GitHub repository, compiles the wiki and the graph, writes the share artifacts, and opens the local graph viewer. It is described as the beginner-friendly alias for `swarmvault scan`, which tells you what the command underneath actually does. If you have no repository to hand, `swarmvault demo` does the same thing with material provided. After the first compile the documentation suggests five more:
swarmvault next
swarmvault query "What are the key concepts?"
swarmvault graph serve
swarmvault doctor
swarmvault candidate list
`next` is the one that matters for a tool with this many layers, because it is read-only and tells you whether to initialise, ingest, compile, query, review, or refresh.
Five directories and a share kit end up on disk
What a run leaves behind is worth knowing before you point it at a directory you care about. `raw/` holds immutable copies of everything ingested. `wiki/` holds the generated markdown pages, saved outputs, graph reports, context packs, and task notes. `state/graph.json` is the machine-readable knowledge graph, which is the file to back up if you want to rebuild anything else. `state/retrieval/` is the local search index, which is the part you can afford to lose. And a first run also produces `wiki/graph/share-card.md`, a matching `share-card.svg`, and a `share-kit/` directory described as copyable and visual first-run summaries. That last group exists so the first result is something you can show someone, which is a small design decision with a large effect on whether a tool gets used at all.
The container exists to answer an MCP registry's introspection check
The Dockerfile says so at the top. It builds the CLI from the workspace and exposes the MCP server over stdio, the same transport Claude Code, Codex, OpenCode, and other MCP clients use, and the stated purpose is that the Glama MCP registry uses it to verify the server starts and responds to MCP introspection. So this is not a deployment image in the usual sense; it is a conformance image. The build is disciplined about it. It starts from `node:24-alpine`, enables corepack and activates pnpm at the version named in the workspace's own `packageManager` field, copies the four workspace manifests before the source so dependency layers cache, installs with `--frozen-lockfile`, builds the viewer, the engine, and the CLI in that order, then runs `pnpm prune --prod` before copying the result into a clean runtime stage. The entrypoint is the built CLI with the `mcp` subcommand, which is the one command that has to work for the check to pass.
The root manifest is private and one minor ahead of the tags
Two details in `package.json` explain most of what the release tooling is for. The package is named `swarmvault-opensource` and is marked `private: true`, so it is not what consumers install; the published artifact is `@swarmvaultai/cli`. And its version is `3.21.0` while the newest release tag is `v3.20.0`, which means the branch sits a minor ahead of anything on npm. That gap is what the `check` script guards. Alongside Biome and a recursive typecheck it runs `check-release-sync.mjs`, `check-published-manifests.mjs`, `check-readme-parity.mjs`, and `check-clawhub-skill.mjs`, and there is a separate `check:perf` budget. Readme parity matters because the repository ships English, Simplified Chinese, and Japanese READMEs with an explicit statement that the English one is canonical, and the script keeps the translations honest. The release history itself is fast: v3.18.0, v3.19.0, and v3.20.0 were all published on 2026-06-12 within about two and a half hours of each other.
Editorial conclusion
swarmvault is worth a look if you already keep a pile of source material and want an agent to be able to read across it, because the design decisions are pointed. Raw sources stay immutable, the wiki is the artifact that compounds, and the schema is a file you and the model revise together. Provenance on every edge is the part to borrow even if you never install it. Two things to weigh. The heuristic provider is local and offline by default, which means the first compile works but the quality ceiling is yours to raise, and the project's own suggestion is to point it at a local model through Ollama when you need better extraction. And the root manifest is a private monorepo named `swarmvault-opensource` at 3.21.0 while the newest release tag is 3.20.0, so read `SCALE.md` and `STABILITY.md` before you decide how much this is expected to carry.
Frequently asked questions
What does SwarmVault actually do?
It turns docs, code, transcripts, notes, and URLs into a durable markdown wiki plus a local knowledge graph you can inspect, query, and hand to agents. It is positioned as an Obsidian alternative for personal knowledge management and as a memory store for Claude Code, Codex, and OpenClaw.
Do I need API keys to use SwarmVault?
No. The built-in `heuristic` provider runs locally and offline, and the quickstart states that no API keys are required for the first run. For sharper extraction the project suggests pairing it with a free local model through Ollama, and cloud providers are optional.
How does SwarmVault stop generated claims from compounding?
Every graph edge is tagged `extracted`, `inferred`, or `ambiguous`, contradiction detection flags conflicting claims, and new concepts land in `wiki/candidates/` before promotion. `compile --approve` stages changes into reviewable bundles, and `lint --conflicts` audits contradictions on demand.
How do I install SwarmVault?
Either download the desktop app for macOS, Windows, or Linux, which bundles its own runtime, or install the CLI with `npm install -g @swarmvaultai/cli` on Node `>=24`. Then run `swarmvault quickstart ./your-repo`, or `swarmvault demo` when you have no repository to hand.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/swarmclawai-swarmvault)Star history chart for your README
[](https://hysenlabs.com/projects/swarmclawai-swarmvault)Was this useful?