BiliBiliToolPro: twelve task codes, and the maintainers account ships as a default
An automated task tool for Bilibili, supporting Docker, QingLong panel, Kubernetes and other deployment methods, fully embracing AI and easy enough for anyone to use.
At a glance
- What is it?
- An automation tool that runs recurring Bilibili activities through the platforms APIs from a web panel or a console host, where cookies land in three different places depending on the deployment, the main branch publishes preview images rather than stable releases, one advertised deployment route is an archived recipe, and the maintainers own creator identifier is the shipped default.
- Who is it for?
- BiliBiliToolPro suits someone who runs their own container or automation panel and wants recurring Bilibili tasks on a schedule rather than by hand, and who reads the configuration before switching anything on. It does not suit you if you want a guaranteed set of rewards, because eligibility, rewards and timing are controlled by the platform and may change under you.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C#, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
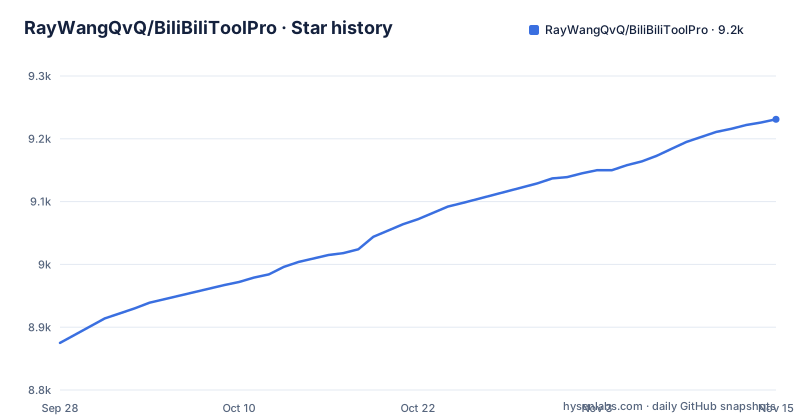
- RayWangQvQ/BiliBiliToolPro9,231 ★ · +356
| Repository | 2026-09-28 | 2026-11-15 |
|---|---|---|
| RayWangQvQ/BiliBiliToolPro | 8.9k | 9.2k |
356 Stars in the last 48 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The maintainers account identifier is the shipped default
One line in the support section is the most important thing to read before your first run. It states that some creator-identifier settings use the maintainers own Bilibili ID as a default configuration value, and that you can change those settings through the configuration file, through secrets, or through environment variables in order to support a different creator. The default is not incidental: the project ships with somebody elses account pre-filled into the settings that decide who gets supported. Since one of the twelve tasks spends a voucher to back a creator, an unconfigured install points that task at the maintainer rather than at anyone you chose. So the first thing to do after your first login is find those settings and set them, rather than enabling everything and watching what happens.
Cookies are stored in three different shapes depending on the host
The documentation explains that where a cookie is stored depends on which host you deployed, and the three cases are not variations of one format but three different mechanisms. With the web panel, accounts are managed inside the panel and persisted into a database file under a config directory. With the panel host, cookies are written as numbered environment variables with a prefixed name and an index. With the console host and other non-web hosts, the default local account file is a JSON document holding an array of cookie strings:
{
  "BiliBiliCookies": [
    "cookie1",
    "cookie2"
  ]
}
The consequence is that credentials do not move between deployments on their own. The README describes no step that migrates a cookie from a database row into an environment variable, so plan on re-adding accounts with the Login task when you move from a container to a panel or from a panel to a local run.
There are two kinds of secret, and the docs repeat the rule three times
The page distinguishes a panel administrator login from the Bilibili accounts used for tasks, and then tells you to treat both the administrator credentials and the Bilibili cookies as secrets. That separation matters operationally, because rotating one does nothing for the other: a leaked panel password is your own deployments problem, while a leaked cookie is the accounts problem. The warning appears in more than one form across the documentation, including an important notice that this project is intended for learning and testing, that you should review the tasks and configuration before running them and comply with the platforms terms, and that you should not expose account cookies or other secrets in issues or public configuration. The reporting guidance repeats it once more, telling you never to post cookies, tokens or passwords when opening an issue. Repetition like that usually means the mistake actually happens.
Task eligibility belongs to the platform, not to the tool
The task table lists twelve runnable units with a console code, a description and a suggested frequency, and a note above it defines the unit clearly: a task is a runnable unit of work, some tasks contain several individual activities, and you should enable only the ones you need. The codes are explicit, covering login, the daily experience bundle, live-room lottery entries up to four times a day, batch unfollowing, several VIP activity groups, fan medals, manga check-ins, a silver-to-coin exchange, charging a creator with a voucher, and a cookie usability check. What the page is careful about is what that list means. Eligibility, rewards and timing are controlled by the platform and may change. So the twelve rows are a snapshot of what was available when the documentation was written, and a scheduled job that quietly stops earning anything is the expected behaviour rather than a defect. Notifications are optional and separate again, with delivery offered through Telegram, PushPlus, WeCom, DingTalk, Microsoft Teams, ServerChan and CoolPush, plus custom API endpoints. Delivery depends on the provider and your own configuration, which means the notification path is another thing that can be silently broken without affecting the task itself.
Merging to the main branch publishes a preview image, not a release
The release guidance contains a distinction that catches people deploying from source. It states that merges to the main branch produce preview Docker images, while stable releases are published separately, and it asks you to update to the latest release and search the documentation and issue tracker before reporting a problem. So the branch and the release are two different channels, and the branch is the one that moves constantly. The recent tags underline the point, with three releases in six days in mid-October 2026 (4.2.1 on 2026-10-12, 4.2.2 on 2026-10-15 and 4.2.3 on 2026-10-17), which is fast enough that a tag you recorded last month is several changes behind. The practical consequence is that a guide telling you to pull the branch gets you a preview build, and a reproducible deployment needs a tag pinned in the image reference rather than a branch name.
One advertised deployment route is an archived recipe
The getting-started table lists ten ways to deploy this tool across containers, automation panels, a local machine and other platforms. The other-platforms row includes a cloud function service, a cluster plugin manager, and a hosted automation service, and that last one is labelled as an archived recipe in the link text itself. The page then spells out what that means: those task workflows are stored in a backup directory rather than in the active repository workflows, and the guide describes an archived recipe rather than a ready-to-enable deployment. So one row of the deployment matrix documents something that has been moved aside and is not ready to enable as described. Worth knowing before you pick a deployment target from the table.
The build stage runs on the host architecture on purpose
The container file carries two numbered decisions in comments, and both are about not being surprised by a build. The first explains that the compile stage is deliberately forced onto the build platform instead of emulating the other architecture. The reasoning is that a publish without a runtime identifier produces architecture-neutral intermediate code with the native libraries for every platform included, for example a SQLite library under a per-architecture runtime path, so a build produced on one machine architecture and one produced on the other contain the same content, while the speed difference measured was about ten times. The second decision says the version is always injected by the build system and baked in, and that a local manual build without it falls back to a development placeholder version from the shared properties file. The rest of the tree matches that picture: a solution file over a layered set of projects for the web host, its client, the application layer, its contracts, the domain, a domain service, configuration, an agent component and two infrastructure projects including one for the ORM that backs the panel database. There is also a pinned SDK file, a central package version manifest, a directory of API client definitions, git hooks wired up on install, and agent context files. The contributing flow asks you to search existing issues first, to open an issue before any substantial or uncertain change, to branch from main, and to target main with a pull request that maintainers squash-merge.
Editorial conclusion
BiliBiliToolPro suits someone who runs their own container or automation panel and wants recurring Bilibili tasks on a schedule rather than by hand, and who reads the configuration before switching anything on. It does not suit you if you want a guaranteed set of rewards, because eligibility, rewards and timing are controlled by the platform and may change under you. Before the first run, override the default creator identifier so the coin-charging task does not point at the maintainers account, decide where your cookies will be stored, and pin a tagged release rather than tracking the main branch.
Frequently asked questions
How do I deploy BiliBiliToolPro?
Pick one of the documented routes: containers through Docker, Podman or Helm on Kubernetes; one of the automation panels; a download and run on a local machine or server; or an alternative platform such as a cloud function service or a cluster plugin manager. The GitHub Actions route is listed but its workflows live in a backup directory and the guide describes an archived recipe rather than a working deployment.
How do I add my Bilibili account to BiliBiliToolPro?
Start the application and run the login task, which adds an account or refreshes an expired cookie by scanning its QR code. Where the cookie is then stored depends on the host: a database file for the web panel, numbered environment variables for panel hosts, or a local JSON account file for the console host. Run the task again to add further accounts.
Is it safe to run BiliBiliToolPro with my own account?
The project states it is intended for learning and testing, asks you to review the tasks and configuration before running them and to comply with the platforms terms. Treat both the panel administrator credentials and the Bilibili cookies as secrets, never post them in issues, and note that some creator-identifier settings default to the maintainers own account, which you should override before enabling the coin-charging task.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/raywangqvq-bilibilitoolpro)Star history chart for your README
[](https://hysenlabs.com/projects/raywangqvq-bilibilitoolpro)Was this useful?