Qwerty Learner's rule is simple: a wrong keystroke means retype the word
Words learning and English muscle memory training software designed for keyboard workers.
At a glance
- What is it?
- Qwerty Learner combines vocabulary memorisation with typing muscle memory for people whose native language they type faster than English. The mechanism is one rule: a mistyped word has to be typed again, which is why the speed figure on screen is a consequence of accuracy rather than a goal. The project is a private, unreleased React app maintained by three people in their spare time.
- Who is it for?
- Qwerty Learner fits a keyboard worker who already feels the gap between typing their own language and typing English, and who wants vocabulary and typing drilled together rather than separately. It does not fit a native English speaker with no such gap, and it does not fit a team that needs cloud sync or a pinned release, because the package is marked private, carries no GitHub releases and reads 0.1.0.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 68 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
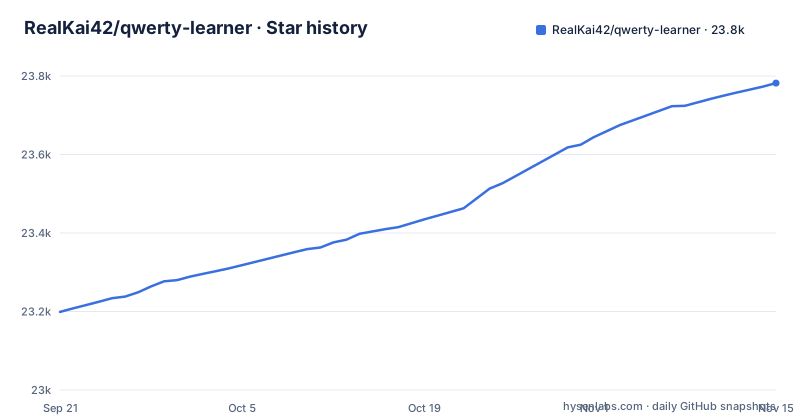
- RealKai42/qwerty-learner23,782 ★ · +583
| Repository | 2026-09-21 | 2026-11-15 |
|---|---|---|
| RealKai42/qwerty-learner | 23.2k | 23.8k |
583 Stars in the last 55 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A mistyped word has to be typed again, and that is the design
Strip away the word banks and the feature list and one rule is left. To avoid creating incorrect muscle memory, the design requires that when a user types a word incorrectly they have to enter it again, in order to make sure correct muscle memory is maintained.
That single rule explains the rest of the product. It explains why speed and accuracy are displayed together, since the point of the exercise is to make accuracy the constraint and let speed follow. It explains why the dictation mode is offered after a chapter is finished, adding a recall step on top of the typing. And it explains why the project does not compete on words per minute, because any keystroke you are allowed to skip is a keystroke that trains the wrong thing.
The consequence for a user is that practice is deliberately slower than a speed drill. The number on screen is a by-product of not making mistakes, not something you push, and there is no way to skip a word you got wrong except by typing it correctly.
The target user is someone who types their own language faster than English
The design rationale is stated at length in the README, and it starts from a specific person. The intended group is keyboard workers whose main working language is English. Some of them type their native language faster than English, because years of native language typing built very solid muscle memory while English typing memory stayed comparatively weak, so they forget how to spell a word while typing it.
Memorising vocabulary is the other half of the problem, and the project combines the two: learn the word while reinforcing the typing, so neither is practised alone.
The same section notes it helps people who have to take a computer-based English test, which is a different user with a different deadline rather than a daily practice habit.
That assumption also explains the project's lineage. The author credits Keybr, which generates pseudo-English from per-letter accuracy and speed, as the core inspiration, and says explicitly that Keybr targets native English speakers and did not improve word mastery for a non-native user. Keybr drills letters, this drills words, and the second is the case the first leaves unsolved.
docker-compose maps 8990 to 5173 while the Dockerfile ends in nginx
Two files describe how to self host the app, and they do not obviously agree.
The Dockerfile builds in node:20 and serves the result from nginx:alpine.
FROM node:20 AS build

# 设置工作目录
WORKDIR /app

COPY . .
RUN npm config set registry  https://registry.npmmirror.com
RUN npm install
RUN npm run build

# 将构建好的 React 应用复制到 Nginx 容器的默认站点目录
FROM nginx:alpine
COPY ./public/default.conf /etc/nginx/conf.d/default.conf
COPY --from=build /app/build /app
The compose file maps a single host port to container port 5173.
    ports:
      - '8990:5173'
Port 5173 is the address the README gives for local development, which is the dev server. The published image is nginx serving static files through a config copied from public/default.conf, so the port it actually listens on is whatever that file says, and 80 is nginx's default. A reader following the compose file has to reconcile those two numbers before the mapping means anything.
There is a second mismatch in the same pair. The Dockerfile uses npm and rewrites the registry to registry.npmmirror.com, a mirror, while the README's local setup uses yarn throughout.
Three maintainers, Vercel hosting, and cloud sync as a goal
The funding section is the most revealing paragraph in the README. The website is maintained by three people in their spare time, and they want in future to buy an independent domain, since it is currently deployed on Vercel, and to buy a server so that users in China can reach it and so that data can be stored for cloud sync.
Read that as a statement of what does not exist yet. Cloud sync is described as something the server purchase would enable, not as a running feature, and the hosting is a shared platform deployment rather than infrastructure the project owns.
The dependency list explains where your progress goes in the meantime. Dexie is the storage layer, dexie-react-hooks binds it to the interface, and dexie-export-import is there to move data in and out, which is the shape of a local-first application with manual backup rather than an account-backed service.
So there is no service level to depend on, no sync across devices, and no guarantee that the domain you visit today is the one you visit next year. For a flashcard trainer that is a low bar. For anything you intend to build a habit around, it is the thing to think about first.
Dictionary data is scraped, pronunciation comes from an API, API banks are pull requests
Content provenance is uneven, and the README is candid about the sources. Dictionary data was scraped from a dictionary repository named kajweb. Pronunciation comes from the open API of a commercial Chinese dictionary service, Youdao, which the author credits for making professional pronunciation available to a small project. The JavaScript API word list came from react-code-game.
The API dictionaries are the weakest link and the project says so: they depend mainly on community contributions. The named ones are JavaScript API, Node.js API, Java API, Linux Command and a C# List API, each credited to an individual contributor. More languages are described as being added gradually.
The examination word banks are the stable part, running from CET-4 and CET-6 through GMAT, GRE, IELTS, SAT, TOEFL and the Chinese postgraduate and professional level exams, plus a coder dictionary and school textbooks for grades three to nine. Japanese common words from N1 to N5 and a Kazakh beginner set of three thousand words are listed too.
The import guide for adding a dictionary lives in docs/toBuildDict.md, and the README asks for requests in an issue, which tells you coverage grows by pull request rather than by design.
yarn start on port 5173, and two one-click scripts with their own prerequisites
The manual path is four steps and nothing clever.
git clone https://github.com/RealKai42/qwerty-learner.gitcd qwerty-learneryarn installyarn startThe project then serves at http://localhost:5173/, and the README warns that skipping the git step can leave you with missing dependencies. The environment needs NodeJS, Git and Yarn, which you can check with node --version, git --version and yarn --version.
The one-click scripts carry their own conditions, and those are the interesting part. The Windows script at scripts/install.ps1 depends on winget to install node and is only supported on Windows 10 version 1709, build 16299, or higher. The macOS script at scripts/install.sh depends on homebrew and expects brew to be on the machine. Both, and the matching pre-check scripts, install missing dependencies rather than only checking for them.
So the convenience path can modify your machine, and it has OS floors the manual path does not.
No releases, version 0.1.0, private true, and three delivery surfaces
package.json is short and decisive. The version is 0.1.0, private is true, and homepage is a dot. Nothing is published to a registry, which is why you will not find this project as an npm package, and the repository has no GitHub releases either. There is no version to pin beyond cloning a commit.
The stack behind it is React 18 with TypeScript declared at ^4.0.3, Vite as the bundler given vite.config.ts and index.html, Tailwind for styling, Radix components with a components.json file, and Jotai for state. Prettier and ESLint are configured, Husky is present for hooks, and Playwright has its own config plus a tests directory.
Then there are three delivery surfaces in three places. The web app is this repository. A VSCode plugin is published on the marketplace and lives in a separate repository. A src-tauri directory sits in this tree, which is the Tauri desktop shell.
The README also describes the project as being at an early stage of development with new features being added, and progress plus future plans live in Issue #42. That is consistent with the version number and with a last push on 2026-09-08.
Editorial conclusion
Qwerty Learner fits a keyboard worker who already feels the gap between typing their own language and typing English, and who wants vocabulary and typing drilled together rather than separately. It does not fit a native English speaker with no such gap, and it does not fit a team that needs cloud sync or a pinned release, because the package is marked private, carries no GitHub releases and reads 0.1.0. Verify first which delivery surface you actually want: the web app, the VSCode plugin and the src-tauri directory are three separate update paths.
Frequently asked questions
What is Qwerty Learner?
It is a word memorisation and English typing muscle memory app for keyboard workers, written in React with TypeScript. A word typed incorrectly has to be typed again by design, so that incorrect muscle memory is not reinforced, and the app shows typing speed and accuracy together.
How do you run Qwerty Learner locally?
Clone the repository, change into the project root, run yarn install and then yarn start, which serves the app at http://localhost:5173/. A one-click script exists for Windows at scripts/install.ps1, which depends on winget and needs Windows 10 build 16299 or higher, and one for macOS at scripts/install.sh, which depends on homebrew.
Which word banks does Qwerty Learner include?
CET-4, CET-6, GMAT, GRE, IELTS, SAT, TOEFL, Chinese postgraduate entrance exam English, professional level four and eight English, a coder dictionary, and API dictionaries for JavaScript, Node.js, Java, Linux commands and C#. Japanese common words from N1 to N5 and a Kazakh beginner set are also listed.
Does Qwerty Learner sync my progress between devices?
Not as a shipped feature. The README describes cloud sync as something the maintainers want to enable after buying a server. Progress is stored locally, and the dependency list includes Dexie with dexie-export-import, which is how data is kept and moved in and out of the browser.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/realkai42-qwerty-learner)Star history chart for your README
[](https://hysenlabs.com/projects/realkai42-qwerty-learner)Was this useful?