XXL-JOB: distributed scheduling with clustered executors
A distributed task scheduling framework (XXL-JOB).
At a glance
- What is it?
- XXL-JOB is a Java distributed task scheduler built as a central admin plus clusterable executors, with sharding, a web IDE and per-executor permissions. The README points to two documentation sites, a Docker Hub image and Maven Central.
- Who is it for?
- Adopt XXL-JOB when your jobs are Java handlers you want a web console, sharding and retry policy around, and when a single database can serve as the coordination point, with a database lock coordinating scheduler instances; retries and shard broadcasts can result in multiple executions, so job effects may need to be idempotent.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 35 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
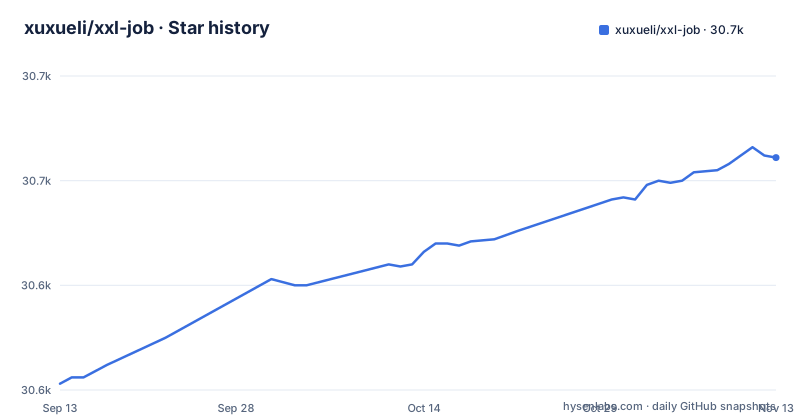
- xuxueli/xxl-job30,661 ★ · +108
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| xuxueli/xxl-job | 30.6k | 30.7k |
108 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two processes and a database lock do the coordination work
The architecture is small enough to hold in your head, which is the point the project makes about its own design goal. There is a scheduler centre, called the admin, which uses a central design and supports cluster deployment so the centre itself is highly available. There are executors, which run the jobs, and those also deploy as a cluster so execution is highly available.
Executors register themselves on a periodic cycle and the scheduler centre discovers and triggers them; entering executor addresses by hand is supported as well. When a machine joins or leaves the cluster, task allocation is recomputed at the next scheduling round rather than being fixed at registration time, which is what makes scaling in and out cheap.
The consistency mechanism is the part worth knowing. The scheduler centre uses a database lock to coordinate scheduling across a cluster. This is not an end-to-end exactly-once guarantee: retries and shard broadcasts can produce multiple executions, so job effects may need to be idempotent. That is a deliberately modest design: no consensus service, no leader election to operate, and the database you already run becomes the coordination point. The cost is that the admin and its lock share a failure domain.
Integrators are not limited to Java. The scheduler and executor expose a language-agnostic OpenAPI in RESTful form, so a third party can integrate with the centre or implement an executor in any language, with a multi-task mode and an `httpJobHandler` offered as further cross-language routes.
Shard broadcast turns the executor cluster into a parallel worker pool
Most schedulers route a job to one executor. XXL-JOB has a mode that does the opposite, and it is the reason to pick it for batch work. Under shard broadcast, one scheduling round triggers every executor in the cluster to run the job once. Combined with dynamic sharding, where sharding is done by executor, the shard count rises automatically as you add machines, and the shards cooperate on the same business workload. The stated effect is a significant improvement in throughput and speed on large-volume operations, without anyone rewriting the job when capacity changes.
The other side of that is retry granularity. Failure retry is configurable per job, and for sharded tasks it works at shard granularity, so one failed shard is retried rather than the whole broadcast.
For everything that is not sharded, routing decides where a job lands, and the list is long: first, last, round-robin, random, consistent HASH, least frequently used, least recently used, failover, and busy transfer. Failover is the one with an explicit behaviour: if a machine in the cluster fails, the scheduler automatically switches to a healthy executor and sends the request there. Busy transfer covers the different case of an executor that is alive but saturated. Consistent HASH is the option that keeps a given job landing on a predictable subset, which matters when the job holds local state.
Every one of these strategies is chosen per job, so a broadcast batch and a singleton maintenance job can share a scheduler.
GLUE is a web IDE with thirty versions of history behind it
The most unusual feature for a Java scheduler is a code editor in the browser. GLUE provides a web IDE where job logic is developed online, published dynamically and compiled into effect immediately, which removes the deploy step from the edit-run loop. It keeps thirty versions of history for rollback, so a change that breaks a production job is not a one-way door.
The same mechanism covers scripts. Script tasks are developed and run in GLUE mode, and the supported types are Shell, Python, NodeJS, PHP and PowerShell. That list matters if your operations team writes shell and the scheduling platform lives in a Java shop, because a scheduled shell script no longer needs a wrapper class.
There is a third path for anything that is a plain command. A generic command line task handler is provided as a Bean task called `CommandJobHandler`, and the stated requirement is that you supply only the command line. Task parameters can be configured online and take effect immediately, so the same handler serves a family of jobs that differ only by arguments.
Task dependencies are also configurable: a job can name child jobs, and when the parent finishes successfully the children are triggered once, with several children separated by commas. The trigger is a consequence of success, not a dependency graph, and that distinction is what keeps the model small.
Three separate policies decide what happens when schedules collide
Dense scheduling produces three distinct questions, and the project answers each with its own policy rather than one global setting.
The first is what may start a job. Trigger policies cover cron, fixed interval, fixed delay, API or event triggering, manual triggering, and parent-child triggering. A job scheduled every second and a job fired by an external event are the same object with a different trigger.
The second is what to do about a trigger the scheduler centre missed, for instance because the centre was down. The overdue policy is either ignore it, or compensate by triggering once immediately.
The third is what happens when the centre schedules faster than an executor can cope. The block handling strategy is single-machine serial, which is the default, discard later schedules, or overwrite the earlier schedule.
Timeouts and shutdown are handled in the same spirit. A job can declare its own timeout, and a job that exceeds it is actively interrupted rather than left running. Shutdown is graceful on both sides: when the scheduler centre stops, it detects a non-empty time wheel and waits for in-flight scheduling to finish, and when an executor stops it stops accepting new tasks and waits for running ones to complete. That is the difference between a rolling deploy and a pile of interrupted jobs, and it is the kind of behaviour that is either present or absent rather than configurable.
Scheduling traffic protection and isolated thread pools
The project describes encryption for scheduler-to-executor traffic. Verify authentication, encryption configuration and protection of other links in your deployment.
Scheduling itself is fully asynchronous by design: asynchronous scheduling, asynchronous execution and asynchronous callbacks, with the stated purpose of smoothing bursts of dense scheduling. The claim that comes with it is that tasks of arbitrary duration are theoretically supported.
That design has one visible safeguard. The scheduling thread pool is isolated and split, and a slow job is automatically degraded into a separate pool named `Slow` so that it cannot exhaust the threads that dispatch work. Without that split, one expensive job is enough to stop the scheduler from triggering anything else on that instance.
Observability is arranged in two layers. Task progress can be monitored in real time, and scheduling results can be viewed online with the executor's complete execution log read in a Rolling fashion rather than fetched at the end. Reports cover run data such as task counts, schedule counts and executor counts, plus scheduling reports as distribution charts.
A native AI executor is also shipped, with built-in AI task handlers and integrations for spring-ai, ollama, openclaw and dify, so an AI task is scheduled through the same console as a batch job.
Permissions are granted per executor, and the audit log records the sensitive parts
Access control is not a role-only model, which is the detail that matters when more than one team shares a scheduler. There are two roles, administrator and normal user. An administrator holds full permissions. A normal user is allowed to operate only on executors that have been assigned to them, and the control is at the executor dimension rather than at the job or the screen. So revoking someone's access means reassigning executors, not rewriting a role table.
Alongside that, an audit log records sensitive task operation information for system monitoring, audit and security analysis, with the stated purpose of tracing abnormal behaviour quickly and locating problems. Review the audit log, access controls and configured transport protections together against your operational requirements.
Failure notification defaults to email, supports configuring multiple addresses for broadcast, and leaves extension interfaces so SMS or DingTalk can be added. Custom task parameters are configured online and take effect immediately.
The admin interface is bilingual, offering Chinese and English with Chinese as the default, which is worth knowing before you hand the console to an international team. The project is funded through sponsorship, with Aliyun providing a cloud-hosted deployment, and the licence is GPL-3.0 with a separate NOTICE file at the root.
The repository ships modules and a Docker image, and no install command
The README points to the following places for getting started. Chinese documentation is at www.xuxueli.com/xxl-job/ and English documentation at www.xuxueli.com/xxl-job/en/. A container image is published as `xxl-job-admin` on Docker Hub, the shared library is pushed to Maven Central as `com.xuxueli/xxl-job-core` whenever a stable version is released, and tagged builds are on the GitHub releases page. Start from the documentation site.
The repository layout tells you what you are assembling. A parent `pom.xml` sits above three modules: `xxl-job-admin` for the scheduler console, `xxl-job-core` for the shared client and model library, and `xxl-job-executor-samples` for sample executors. Alongside them are `docker/` for image definitions, `doc/` for documentation sources, and `LICENSE` and `NOTICE` at the root.
Versions move regularly. Release 3.5.0 was published on 2026-10-09, following 3.4.2 on 2026-06-19 and 3.4.1 on 2026-06-14, and the last push to the default branch `master` was on 2026-10-09. The repository is not archived. For history, the project was created in mid-2015 and the first major version shipped in November 2015, and the README notes that an internal deployment at Dianping was built on version 1.1 under the alias Ferrari, which it recommends upgrading from.
Editorial conclusion
Adopt XXL-JOB when your jobs are Java handlers you want a web console, sharding and retry policy around, and when a single database can serve as the coordination point, with a database lock coordinating scheduler instances; retries and shard broadcasts can result in multiple executions, so job effects may need to be idempotent. Do not adopt it if you need DAG-style data dependencies, since parent-child triggering runs a child after a parent succeeds rather than modelling dependencies between tasks, and read the documentation sites for installation steps. Three things to verify in your own environment: that the admin and executor communication works through whatever sits between them, and verify authentication, encryption configuration and network reachability for the deployment; that the executor thread pool isolation behaves for your slowest job, since slow tasks are pushed into a separate pool to protect scheduling; and that the shard count your batch job assumes still holds after you add executors, because sharding is by executor and grows with the cluster. Last push was 2026-10-09 and the project is not archived.
Frequently asked questions
What is XXL-JOB?
A distributed task scheduling framework written in Java, built as a central scheduler admin plus executors that run the jobs. Both sides deploy as clusters, executors register themselves periodically, and the scheduler centre uses a database lock to coordinate clustered scheduling; retries and shard broadcasts can lead to multiple executions. Tasks can be developed in a web IDE called GLUE and published without a redeploy.
How does XXL-JOB compare with Quartz?
Quartz is an in-process Java scheduling library, so the jobs share the memory and deployment of your own application and there is no separate console. XXL-JOB splits the work: the admin schedules, executors run, and a database provides the lock that keeps a clustered scheduler centre from triggering the same round twice.
How does XXL-JOB compare with Airflow?
Airflow models work as a DAG of operators with data dependencies between them, and its unit is a task inside a graph. XXL-JOB's unit is a job handler triggered by cron, interval, delay, API or manual means, with parent-child triggering that runs a child once after its parent succeeds. Shard broadcast and executor-dimension dynamic sharding are the mechanism it offers for large batch workloads instead of graph scheduling.
What alternatives exist to XXL-JOB?
The comparison is yours to make. The structural question is whether you want an in-process library such as Quartz, a DAG orchestrator such as Airflow, or a separate scheduler console with clusterable executors and shard broadcast, which is the shape XXL-JOB takes. XXL-JOB also exposes a language-agnostic RESTful OpenAPI so an executor can be written outside Java.
How does XXL-JOB compare with PowerJob?
XXL-JOB's own shape is: a central admin with cluster deployment, distributed executors that register periodically, a database lock for single-trigger consistency, shard broadcast with executor-dimension dynamic sharding, and routing strategies including failover and busy transfer.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/xuxueli-xxl-job)Star history chart for your README
[](https://hysenlabs.com/projects/xuxueli-xxl-job)Was this useful?