bear records real compiler invocations, or reconstructs them from a log
Generate compile_commands.json for any C or C++ build
At a glance
- What is it?
- bear produces compile_commands.json for C and C++ projects whose build system cannot export one, either by wrapping the build command or by parsing text you already have. It is written in Rust as a Cargo workspace, and it names CMake, Meson, and Bazel as the cases where you should not reach for it at all.
- Who is it for?
- bear is the right tool when your build system cannot emit a compilation database and you cannot or will not modify it, which covers make, autotools, custom scripts, embedded and HPC toolchains, and anything sitting behind a compiler launcher. It is the wrong tool when CMake, Meson, or Bazel is already in the project, since those export the database directly.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
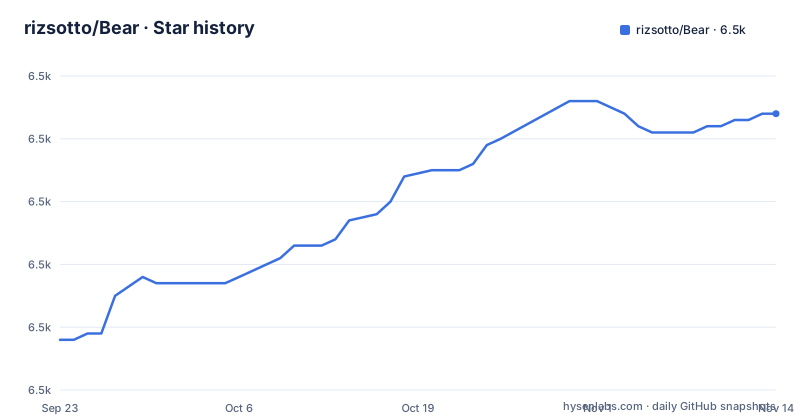
- rizsotto/Bear6,534 ★ · +36
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| rizsotto/Bear | 6.5k | 6.5k |
36 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The output goes to the current working directory, not your build root
The whole interface is one wrapper. After installation you run:
bear -- <your-build-command>and bear writes compile_commands.json into the current working directory. The double dash is the contract: everything before it is an option belonging to bear, everything after it is treated as part of the build command and passed along. More detail lives behind `bear --help` or the man page. The file describes how each translation unit is compiled, which is what Clang tooling such as clangd, clang-tidy, and friends need in order to give you code navigation, autocomplete, and diagnostics. Because bear captures the invocations as the build runs, it records what the compiler was actually called with, and it needs no changes to your build system. The placement rule is worth remembering, since editing a database in one directory while the editor looks in another produces a database that appears to be ignored.
bear names its own alternatives and tells you when to skip it
The case for bear starts with the build systems that cannot help. That list covers make, autotools, or custom script builds, described as most of the C world. It also covers a build you cannot or do not want to modify, naming a third-party project, a codebase you are just exploring, and a CI job. The unusual toolchains get their own category: embedded targets such as ARM, TI, Microchip, and QNX, HPC toolchains including Cray, Intel, NVIDIA, and MPI wrappers, CUDA, cross-compilers, and compiler launchers such as ccache, distcc, and icecc. Against that, there is one sentence that should stop you before you install anything. If your project uses CMake, Meson, or Bazel, those tools can export a compilation database directly, and you should use that when it is available. bear is the fallback, not the default.
parse-sh builds the database from text when the build cannot run
There is a second mode for the case where running the build is impossible and all you have is a CI log or the dry-run output of the build system:
make -n | bear parse-shThis is a different mechanism from interception. bear interprets the commands a build system plans to run and formats those into a compilation database as if they had executed, which means the quality of the result is bounded by what the text actually contains. A dry run omits anything the build system decides at execution time, so conditional compilation paths, generated sources resolved on the fly, and anything a wrapper computes can be missing. That is the trade: a database reconstructed from text is better than none for tooling, and worse than one captured from a real run. The documentation site is where the difference between the two is written down.
Interception is the whole value, and wrappers are where it shows
The reason to prefer a captured database over a parsed one is visible in what capture can see. bear records what the compiler was actually invoked with, including flags injected by wrappers and entries for generated sources. A wrapper such as ccache, distcc, or icecc sits between your build system and the compiler, so the flags your source files are actually compiled with are not the flags your build script wrote down. Generated sources have the same problem from the other direction, since a file that does not exist until the build runs cannot appear in a dry-run listing. This is also why the tool is positioned for HPC and CUDA builds, where the interesting compiler invocations come from wrapper scripts rather than from the build system itself.
Seven operating systems are supported, each with its own interception limits
The stated platform list is Linux, Android, macOS, FreeBSD, OpenBSD, NetBSD, DragonFly BSD, and Windows. Read the next sentence before planning around that. Each operating system and build system imposes constraints on how bear can run and which interception method is available, and those constraints affect the final output. In other words, being on the supported list tells you the binary will run, not that the database will be equivalent across those systems. The documentation site is where the available options are enumerated along with the limitations of each one, and it also covers known issues and platform- and toolchain-specific usage.
It is a Rust workspace with a shell harness deliberately left out of it
The repository root shows the shape: crates/, build-support/, tests/, docs/, man/, scripts/, site/, plus INSTALL.md, Cargo.toml, Cargo.lock, and a COPYING file. The workspace definition is explicit about one exclusion:
[workspace]
members = ["crates/*", "build-support/*", "tests/*"]
# tests/dogfooding is a POSIX-sh release-time harness, not a Rust crate, so it
# has no Cargo.toml; exclude it from the tests/* glob.
exclude = ["tests/dogfooding"]
resolver = "3"
So the release-time dogfooding run is a POSIX shell script that the Cargo glob would otherwise pick up, and it is excluded by name with a comment saying why. The workspace pins itself at version 4.2.4, edition 2024, under GPL-3.0-or-later, and the release profile is tuned hard:
[profile.release]
strip = true
lto = true
opt-level = 3
codegen-units = 1
Single codegen unit and full link-time optimization on a tool whose whole job is to sit in front of a build.
The dependency list tells you what the tool has to parse and intercept
The workspace dependency table is a readable summary of the problems this tool solves. Command-line parsing is clap 4.6 with the cargo, help, usage, and suggestions features enabled, and shell-words sits alongside it because bear has to take apart a shell command line it did not build itself. serde and serde_json write the database, with default features off and only derive and std turned back on. libc and errno handle the low-level interception, while ctor registers handlers before main runs and signal-hook manages process signals. which locates a compiler, cc builds native helpers, and encoding_rs deals with output that is not UTF-8. The test side is unusually heavy: mockall, proptest, insta for snapshots, plus assert_cmd, assert_fs, and predicates. This is a program whose hard part is being correct about other people's command lines.
Three patch releases in five weeks, and two funders
The release record shows 4.2.2 on September 5, 2026, 4.2.3 on October 14, and 4.2.4 on November 2. The repository is not archived and its last push is dated November 2, 2026, the same day as the 4.2.4 release, so the current version and the current branch are close together. The acknowledgments are short and specific: regular sponsorship from one person, and a free Claude subscription that supported development work. Neither the README nor the release notes state a minimum compiler, build system, or operating system version per release, so a version floor has to be read out of the documentation site rather than the release notes. Problem reports are asked to check the documentation for a known issue with a documented workaround and to look at older, possibly closed, issues before filing a new one.
Editorial conclusion
bear is the right tool when your build system cannot emit a compilation database and you cannot or will not modify it, which covers make, autotools, custom scripts, embedded and HPC toolchains, and anything sitting behind a compiler launcher. It is the wrong tool when CMake, Meson, or Bazel is already in the project, since those export the database directly. Before adopting, check whether your distribution packages it, then read the documentation site for the interception method that applies on your operating system, because that choice changes the output.
Frequently asked questions
What does bear do and who needs it?
It wraps your build command, records the compiler invocations, and writes compile_commands.json for clangd and clang-tidy. It is for make, autotools, custom script, embedded, HPC, and CUDA builds that cannot export a database themselves.
How do I run bear for the first time?
Run bear -- <your-build-command>, then read compile_commands.json from the current working directory. Options for bear itself go before the double dash, and everything after it belongs to your build.
Do I need bear if my project uses CMake, Meson, or Bazel?
No. Those tools can export a compilation database directly, and you should use that when it is available. bear is positioned for build systems that cannot produce one.
Can bear work when I cannot run the build at all?
Yes, from text. Piping the build system's dry-run output into bear parse-sh, for example make -n | bear parse-sh, formats the planned commands into a database as if they had executed.
Which operating systems does bear support?
Linux, Android, macOS, FreeBSD, OpenBSD, NetBSD, DragonFly BSD, and Windows. Each one constrains which interception method is available, and that choice affects the output.
How is bear installed?
It is packaged for many distributions, so checking your distribution's package manager is the first step. Alternatively you can build it from source, following INSTALL.md in the repository.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rizsotto-bear)Star history chart for your README
[](https://hysenlabs.com/projects/rizsotto-bear)Was this useful?