agentmemory: a local memory server for coding agents that works keyless but recalls best with embeddings
#1 Persistent memory for AI coding agents based on real-world benchmarks.
At a glance
- What is it?
- rohitg00/agentmemory records coding-agent sessions through hooks and serves them back over an API, MCP and a live viewer. Its keyless default runs on BM25 only, so semantic recall and LLM summaries are opt-in decisions you make during setup.
- Who is it for?
- agentmemory suits developers who switch between coding agents such as Claude Code, Codex CLI, Cursor or OpenCode and want one local store of decisions and fixes they can inspect and edit. It is a weaker fit if you will not configure an embedding provider, because keyless mode only does BM25 keyword recall, or if you need a 1.0 API, since the package is at 0.9.31.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
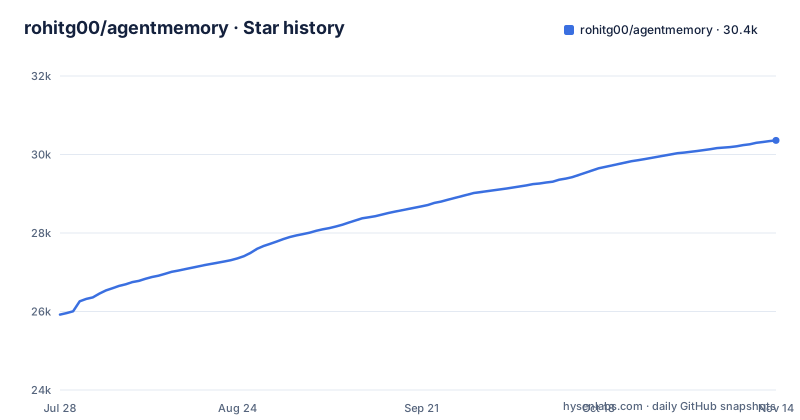
- rohitg00/agentmemory30,360 ★ · +4,438
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| rohitg00/agentmemory | 25.9k | 30.4k |
4,438 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One memory store shared by Claude Code, Codex CLI, Cursor and any MCP client
agentmemory is a TypeScript server, published on npm as @agentmemory/agentmemory under Apache-2.0, that records what coding agents do and lets them recall it in later sessions. Supported agents named on the project front page are Claude Code, GitHub Copilot CLI, Cursor, Gemini CLI, Codex CLI, Hermes, OpenClaw, pi, Oh My Pi, OpenCode, DeepSeek Harness, and any MCP client. The point is that one store sits behind all of them, so a fix found in one tool can be retrieved from another, together with project history, lessons and session handoffs. Capture runs through native hooks and plugins that record supported session events, with secret scrubbing and offline replay. The repository carries .claude-plugin/, .codex-plugin/ and .cursor-plugin/ directories for those integrations, and further agents are wired up with agentmemory connect <agent>. Saved memories can be browsed, edited, exported and forgotten in a live viewer.
Keyless mode answers keyword queries through BM25 and misses semantic ones
The default setup can run without any API key, and that mode disables vector embeddings. memory_recall, which follows the mem::search path, uses BM25 keyword ranking. memory_smart_search can also fuse structural graph matches, but only when graph data already exists. The project is direct about the consequence: its own demo includes the query database performance optimization, which is intentionally semantic and can return zero results until an embedding provider is configured. If your agents phrase recall requests differently from how the original session was worded, keyless mode will not connect the two. Anyone evaluating agentmemory on its keyless default is evaluating a keyword index, not the hybrid search the project's linked gist describes as an extension of Karpathy's LLM Wiki pattern with confidence scoring, lifecycle, knowledge graphs and hybrid search.
Local embeddings fetch Xenova/all-MiniLM-L6-v2 on the first request
Semantic recall without a paid key comes from setting EMBEDDING_PROVIDER=local in ~/.agentmemory/.env and restarting the server. The first embedding request then downloads the Xenova/all-MiniLM-L6-v2 model, and inference runs on the machine after that initial download. Plan for that first request to need network access even though everything afterwards is local. Remote embeddings are the other route: the Docker configuration exposes OPENAI_EMBEDDING_API_KEY, OPENAI_EMBEDDING_BASE_URL, OPENAI_EMBEDDING_MODEL and OPENAI_EMBEDDING_DIMENSIONS, separate from the OPENAI_API_KEY used for language model calls, so embeddings and summarisation can point at different endpoints. Configuration normally lives in ~/.agentmemory/.env, though the example file notes it can also be placed in a project root for scoped config. Running npx -y @agentmemory/agentmemory@latest doctor checks that the daemon reads the env file you expect.
Without a provider key, summarisation, reflection and consolidation stay off
With no LLM provider key, agentmemory runs in what .env.example calls noop mode. Observations are still indexed through zero-LLM synthetic compression and BM25 recall still works, but LLM-backed summarisation, reflection and consolidation are disabled. Adding a key is not enough on its own to get LLM-written observation compression either: that path also requires AGENTMEMORY_AUTO_COMPRESS=true. Provider detection walks the keys in a fixed priority order and the first key present wins, as implemented in src/config.ts::detectProvider. The practical result is that a machine with both an OpenAI and an Anthropic key in its environment will use whichever comes first in that order, not the one you might expect, so set only the provider you mean to use. Local API authentication uses a generated secret unless AGENTMEMORY_SECRET is set explicitly.
Capture filters decide which tool calls become memories
Not every tool call is stored. AGENTMEMORY_CAPTURE_ALLOW takes a comma or space separated list of tool names or globs; when it is set, only those tools are captured. AGENTMEMORY_CAPTURE_DENY adds extra names or globs to skip on top of the defaults, which are memory_*, toolsearch, listmcpresources and fetchmcpresource, so the memory tools do not record their own calls. AGENTMEMORY_CAPTURE_OUTPUT_MAX defaults to 8000 and caps how many characters of tool output are kept. That cap has a cost: a long test log or stack trace beyond 8000 characters is cut, and whatever sat past the limit cannot be recalled later. Raise it if your agents rely on long outputs, and set an allow list if you only want a few tools in the store.
Setup through npx @latest, with a global install as the fallback
Requirements are Node.js 20 or newer with npm and npx. macOS and Linux also need curl, a POSIX sh and tar for automatic runtime setup; on Windows the options are WSL2 or a separate native Windows setup. The canonical path is a single npx call:
npx -y @agentmemory/agentmemory@latestSetup asks you to choose agents and a provider or keyless mode, writes the configuration, starts the memory server and offers a global install of the agentmemory command. The -y flag accepts the npm package prompt and @latest picks the current release, which means two machines set up a week apart can run different versions. Seeding sample data and installing the skills follows:
npx -y @agentmemory/agentmemory@latest demo  # seed sample sessions + exercise recall
npx skills add rohitg00/agentmemory -y   # 17 native skills so your agent knows when to reach for memory
If a global install is wanted and npx is not, this is the alternative, though the project keeps npx as the path that avoids global-prefix permission errors such as EACCES:
npm install -g @agentmemory/agentmemory@latestThe Docker build binds the viewer to 0.0.0.0 and pins iii-engine versions
Run directly, the API listens on http://localhost:3111 and the live viewer on http://localhost:3113, both bound to loopback. The docker-compose.yml changes that: it sets AGENTMEMORY_VIEWER_HOST to 0.0.0.0 inside the container, maps III_REST_PORT to 3111, III_VIEWER_PORT to 3113 and III_ENGINE_PORT to 49134, and keeps data under /data. Access is then governed by REST_ALLOWED_ORIGINS, VIEWER_ALLOWED_HOSTS and VIEWER_ALLOWED_ORIGINS, which default to localhost, 127.0.0.1 and [::1] on those ports. If you publish the container ports on a shared host, those lists are what stands between your stored sessions and the network, so review them before exposing anything. The build arguments pin III_VERSION 0.25.0, STATE_VERSION 0.22.20 and HTTP_VERSION 0.22.7, matching the package description of being powered by iii-engine's three primitives, and III_TELEMETRY_ENABLED is set to false.
A 0.9.x package whose release gate tests recovery paths
The package version is 0.9.31, released on 2026-10-26, after v0.9.30 on 2026-10-06 and v0.9.29 on 2026-08-16. The main branch was pushed on 2026-11-02 and the repository is not archived. Being below 1.0 means configuration names and tool behaviour can still change between releases, which matters more because setup pulls @latest by default. The package.json shows what the maintainers check before shipping: release-gate scripts for vector recovery, startup, summary recovery, CLI diagnostics, the graph index, skills and OpenClaw, run together through npm run release:gate. The default test script excludes test/integration.test.ts, which runs separately under test:integration. The repository tagline calls agentmemory number one based on real-world benchmarks; the benchmark/ and eval/ directories are where to check that claim against your own workload before trusting it.
Editorial conclusion
agentmemory suits developers who switch between coding agents such as Claude Code, Codex CLI, Cursor or OpenCode and want one local store of decisions and fixes they can inspect and edit. It is a weaker fit if you will not configure an embedding provider, because keyless mode only does BM25 keyword recall, or if you need a 1.0 API, since the package is at 0.9.31. Before relying on it, run the demo, confirm a semantic query returns results, and check the bind address if you use the Docker setup.
Frequently asked questions
What is agentmemory?
agentmemory is an Apache-2.0 TypeScript server that captures coding-agent sessions and makes decisions and fixes searchable later. It works with Claude Code, GitHub Copilot CLI, Cursor, Gemini CLI, Codex CLI, OpenCode and any MCP client.
How does agentmemory work?
Hooks and plugins record supported session events with secret scrubbing, and a local server indexes them. Recall uses BM25 keyword search without a key, and adds semantic search when local or remote embeddings are configured.
How do I start using agentmemory?
With Node.js 20 or newer, run npx -y @agentmemory/agentmemory@latest, pick your agents and a provider or keyless mode, then run the demo command to check recall. The API listens on localhost:3111 and the viewer on localhost:3113.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rohitg00-agentmemory)Star history chart for your README
[](https://hysenlabs.com/projects/rohitg00-agentmemory)Was this useful?