Best of Agent Harnesses ranks 100+ projects on a hand-written axis next to star counts, and ships the same list as prose, JSON, and an MCP server
🏆 Curated, ranked list of AI agent harnesses (100+) — plus an MCP server, llms.txt & JSON so agents can recommend them too. Rescored weekly.
At a glance
- What is it?
- Best of Agent Harnesses is a curated catalog of agent runtimes, orchestration frameworks, and harness techniques, published as a browsable site and as machine-readable surfaces so an agent can query the list itself. Its strongest asset is that it cites its sources and separates measurement from interpretation. Its structure is unusual in one respect worth knowing before you reuse it: the ranking combines a qualitative axis with popularity, and the repository commits its own curation queue and traffic history.
- Who is it for?
- Use this list if you are deciding which agent runtime to adopt and want the shortlist narrowed before you build anything, and use its MCP server if you would rather ask an agent than read tables.
- Can I use it commercially?
- Yes, with credit. CC-BY-SA-4.0 allows commercial use as long as you credit the authors and indicate what you changed. It is written for creative content, so check how it applies to any code.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
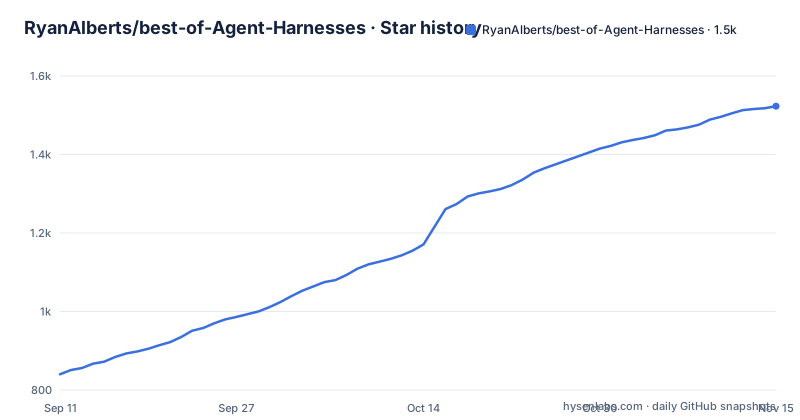
Star history
- RyanAlberts/best-of-Agent-Harnesses1,523 ★ · +683
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| RyanAlberts/best-of-Agent-Harnesses | 840 | 1.5k |
683 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The ranking puts a hand-assigned axis next to star counts
The stated method is a blend, and the blend is worth quoting in full. Projects are ranked by relevance to harness concerns, which are given as environment, orchestration, lifecycle, and guardrails, and by stars and activity. Those are two different kinds of quantity placed on one axis, so a project with a large community can outrank a project that fits your situation better. The landscape views make that visible rather than hiding it. One chart plots every project by adoption surface area, described as the axis running from simplicity to capability, against GitHub stars, with colors for categories and the largest projects in each tier labelled. A second chart places the same projects by how much unsupervised latitude the design gives and by what happens when a run dies, autonomy against recovery. Two markers appear in the tables below the charts: a star marks headless-ready projects and a cross marks durable ones. Both charts regenerate from the list data on every refresh, so the plot is a rendering of the catalog rather than a separate claim. The site adds a third surface, one page per harness with filtering by capability, autonomy, and recovery, and the catalog is described as holding 100 or more entries.
Releases are named by month rather than by version number
The release tags here are dates, not versions. Two are visible: list-2026-09-2, whose description names the mid-September 2026 catalog with the harness-matters-more material, QM, Prime Agent, and OpenJarvis, and list-2026-09, the September 2026 update. So the sequence number is the part that increments within a month and the year-month is the identity, which is a sensible scheme for a catalog where the useful question is when a snapshot was taken rather than which version is newer. What ships alongside each refresh is as interesting as the prose. The repository root holds harnesses.json as the machine-readable list, harnesses.jsonld carrying the same content in linked-data form, projects.yaml as a human-editable source, server.json for the MCP server's registration, feed.json, contributors.json, TAGS.md, landscape.md as the chart source, and latest-changes.md as a running log. The primary language is Python and the root has both a scripts directory and a tests directory, so the site, the charts, and the JSON are generated rather than hand-maintained. The project description says the list is rescored weekly; nothing in the repository states where that schedule is configured, so the cadence is a claim you can verify by watching the tags.
The evidence gets its own page, including what the claim does not mean
This is the part of the catalog that distinguishes it from a link dump, and it is built on cited measurements with the caveats kept in the same document as the numbers. The framing rests on named sources rather than on assertion. Simon Willison's definition of an agent is quoted as an LLM agent running tools in a loop to achieve a goal, with the harness described as everything around that loop. Andrej Karpathy named the architecture in 2023 with the model as the kernel process of a new operating system and the harness as the rest of that operating system. The SWE-agent paper is credited with coining the agent-computer interface, the claim being that how tools and feedback are presented changes what a model can do independently of the model itself. The numbers then follow with attribution. On SWE-bench Pro, a report from AINews dated Aug 8, 2026, citing analysis by a specific researcher, says swapping the harness changed pass@1 more than many model upgrades do, with the same model moving from 23% to 52% pass@1 on one model and 15% to 36% on another, and a rank correlation of -0.05 across models. On long-horizon work, a bare frontier model was verified at about 30% on ARC-AGI-3 while a harness described in a cited paper took a different model to 95.5%. A dedicated page then covers who says so, what they measured, and what the claim does not mean.
The same list is published four times, and agents are meant to query it
Four publication surfaces describe the same catalog, and the fourth is the unusual one. The browsable site gives one page per harness with filtering. llms.txt is the plain-text convention for machine consumption. harnesses.json is the structured list, with harnesses.jsonld as its linked-data form. And an MCP server in the repository exposes tools named recommend and pick_harness, so the stated purpose is that an agent can call the list and choose a harness matched to a given model and task rather than inheriting whichever harness somebody else benchmarked. There is also a section of templates and playbooks, directories at the repository root holding copy-paste setup files and step-by-step guides for the harnesses in the list, which is a different commitment from a ranking: it is opinionated configuration that has to be read and adapted rather than data that can be consumed. attributes/ holds the attribute definitions the filters and charts are built on. For anyone building on this, the practical split is that the JSON, the YAML, and the attributes are the reusable substrate, while the rankings carry the judgment and the licence.
A curated list repository that commits its own queue and traffic history
The root listing shows what accumulates when a list project is maintained over time, and several entries are not content at all. curation-queue.json is a queue file, so the editorial to-do list lives in the repository rather than in an issue tracker. traffic-history.jsonl is a JSON Lines file of traffic data committed alongside the catalog, which means the project's own audience numbers are versioned artifacts that can be diffed over time rather than a dashboard that changes invisibly. contributors.json and feed.json serve the same role for attribution and syndication. CITATION.cff sits at the root, so the catalog is citable as a scholarly artifact. TAGS.md and latest-changes.md handle taxonomy and the running log. There is also a CLAUDE.md at the root of a project whose entire subject is agent harnesses, so the repository dogfoods one of the things it ranks. Nothing in the root listing suggests a build pipeline definition beyond the scripts and tests directories, and nothing describes where the weekly rescoring job runs, which is the one piece of infrastructure a reader would want to see before trusting the freshness claim.
Six questions, seven measurements, and a two-week trial
The decision material is organised as head-to-head pages rather than as a single ranked table, and the structure is consistent. A how-to-pick page poses six questions that turn the list into a decision, and names one chart to internalise first. A test-drive page sets out what is called a two-week trial protocol, built on a fair setup, tasks drawn from your own repositories, seven measurements, and a walk-away test. The comparison pages are explicit about which projects they put against each other: an always-on personal agent debate framed as presence against discipline, a page on managed against self-hosted always-on agents that names five options including a hosted bot product, a managed agents offering, and three open harnesses, a terminal coding agents page comparing five command line harnesses, a multi-agent orchestration page comparing four frameworks, and a memory layers page comparing three projects. A separate page ranks the best harnesses in 2026 by category with the top three per category, regenerated on every refresh. The pattern is consistent throughout: a small set of named contenders, a stated basis for comparison, and a page per argument rather than one document trying to hold all of them.
The definition section is an argument, and the licence reaches the data files
Two things about the project are worth stating plainly. First, the opening section on what an agent harness is does not report a measurement. It argues for a category of investment, citing named guidance on building effective agents and an interview in which a framework executive says the framework era is over and the layers that matter are skills, tools, and context quality. It states the position that harness quality rather than model quality determines whether agents ship, and that the gains come from a new class of self-improving harnesses that stay thin and expose only what the model cannot do for itself. Whether you accept that is a judgement call the document invites rather than settles, and the measurement pages are where the evidence lives. Second, the licence is CC-BY-SA-4.0, a share-alike terms licence, on a repository whose most reusable parts are not the prose but harnesses.json, harnesses.jsonld, projects.yaml, attributes/, and llms.txt. Anyone who forks the data and republishes it inherits those terms, which is the one piece of legal mechanics a reader of this project will care about and which the data files themselves say nothing about.
Editorial conclusion
Use this list if you are deciding which agent runtime to adopt and want the shortlist narrowed before you build anything, and use its MCP server if you would rather ask an agent than read tables. Do not use it as a leaderboard you can cite, because the ordering is a stated blend of a hand-assigned axis and star counts, the star component moves for reasons unrelated to harness quality, and the project's own comparison page is explicit about what its headline numbers do and do not mean. Before you commit to anything it recommends, check three things. The category the project was filed under, since environment, orchestration, lifecycle, and guardrails are not interchangeable concerns. The two-week test-drive protocol, which asks for a fair setup, tasks from your own repositories, seven measurements, and a walk-away test, and which is a better use of your time than any ranking. And whether you want the machine-readable surface at all, because harnesses.json, llms.txt, and the MCP tools are the part of this repository most likely to be reused, and they carry the share-alike licence the prose does.
Frequently asked questions
Which is the best agent harness?
The catalog does not name a single winner, because its rankings mix relevance to harness concerns such as environment, orchestration, lifecycle, and guardrails with GitHub stars and activity, and its own evidence pages note that harness rankings barely transfer across models with a rank correlation of -0.05. Its answer is to use the MCP server's recommend or pick_harness tool so the choice is matched to your model and task.
What are examples of agent harnesses?
The catalog holds 100 or more entries and its comparison pages place named sets against each other, including five terminal coding agents, four multi-agent orchestration frameworks, three memory layers, and five managed or self-hosted always-on agent options. An agent harness is defined there as the runtime that turns a model into an agent, the model thinking while the harness decides what that thinking is allowed to touch.
What is the difference between an agent and a harness?
The project puts it as: a model answers, an agent acts, and the agent harness is the runtime that turns one into the other. Simon Willison's definition of the agent is quoted as an LLM agent running tools in a loop to achieve a goal, and the harness is everything around that loop, meaning which tools exist, what needs approval, what the model sees each turn, and what survives a crash.
Which open source AI agent harness is considered the best?
Nothing is treated as best in general here, since the ordering is a blend of a qualitative axis running from simplicity to capability against GitHub stars, and the charts are regenerated from the list data on every refresh. The catalog instead offers a two-week test-drive protocol with a fair setup, tasks from your own repositories, seven measurements, and a walk-away test.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 0 in the last 30 days; newest first.
- Best-of-Agent-Harnesses – Ranked list of 167 AI agent harnesses, rescored weeklyHacker News · Oct 2, 2026 · 7 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ryanalberts-best-of-agent-harnesses)Star history chart for your README
[](https://hysenlabs.com/projects/ryanalberts-best-of-agent-harnesses)Was this useful?